
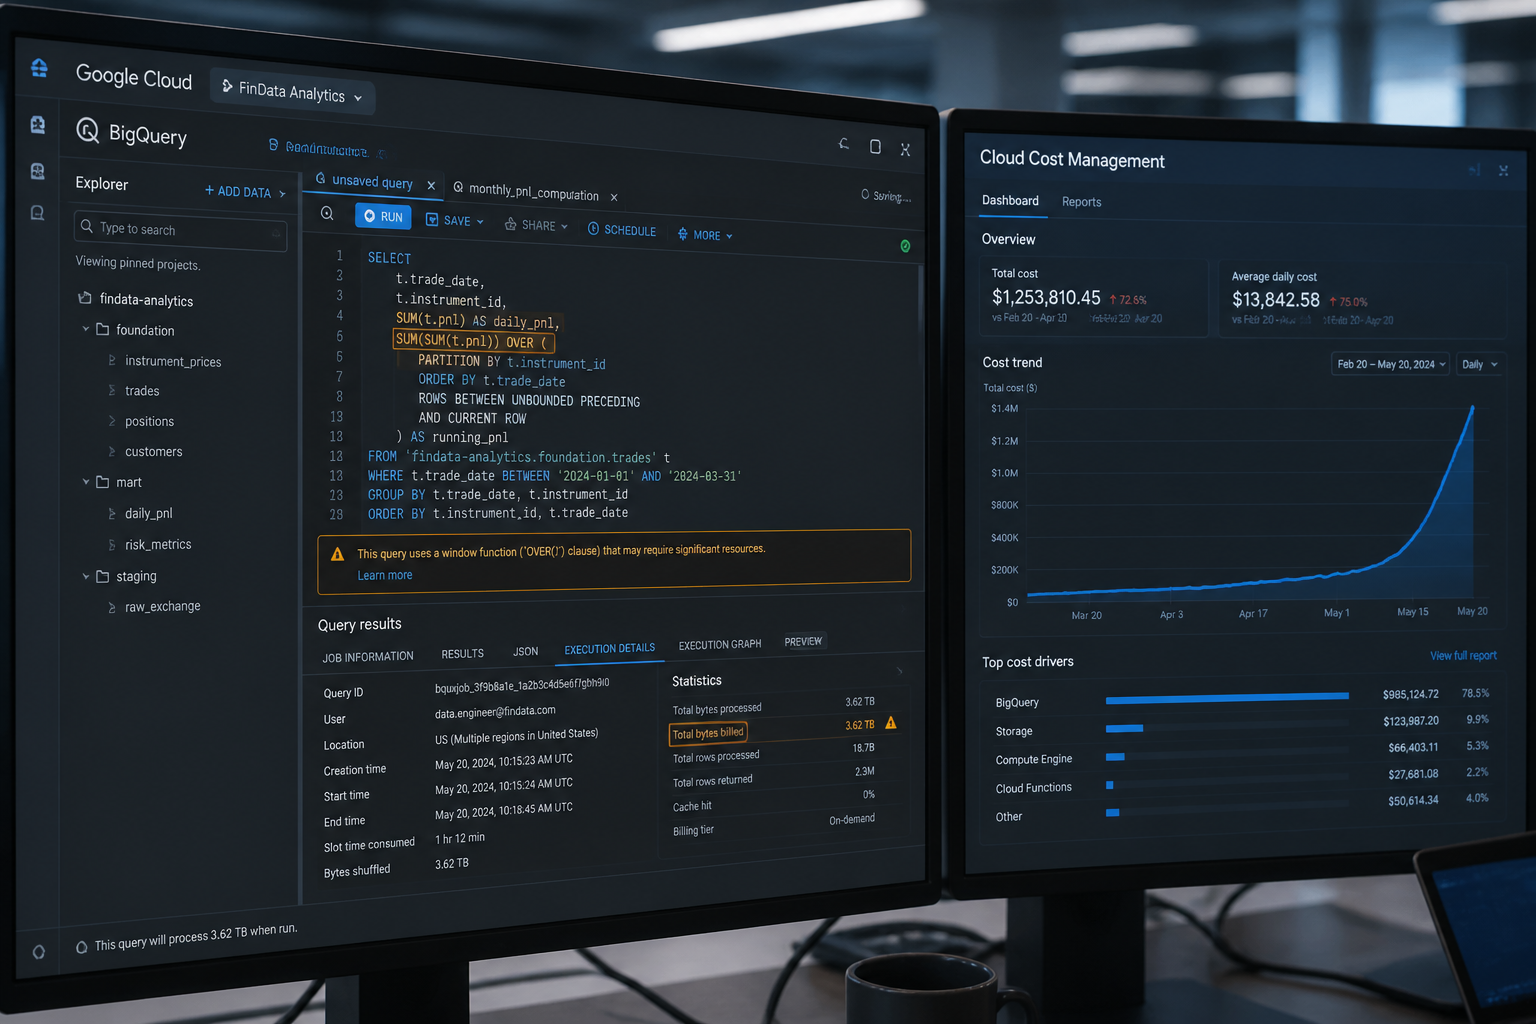
Unpartitioned window functions in BigQuery are one of the most common — and least diagnosed — causes of runaway query costs at growth-stage companies. A single OVER() clause without a PARTITION BY definition forces BigQuery to treat your entire dataset as one giant window, scanning every row in the table regardless of how narrow your WHERE filter is. The result: bills that double quarter-on-quarter with no obvious culprit, and a data team that has no idea where to look.
If you are running analytical SQL on BigQuery — particularly inside dbt models — and you have not audited your window function usage recently, there is a meaningful chance this problem exists in your pipeline right now.
Why Unpartitioned Window Functions Are So Expensive in BigQuery
To understand the cost impact, you need to understand what BigQuery actually does when it evaluates a window function.
Window functions are one of the most useful features in SQL. They let you perform calculations across a set of rows that are related to the current row, without collapsing the result into a single row like GROUP BY does. That power comes with a cost: BigQuery needs to sort and group data across the defined window before it can evaluate the function. Poorly written window functions can consume massive compute resources, while optimised implementations deliver sophisticated analytics efficiently.
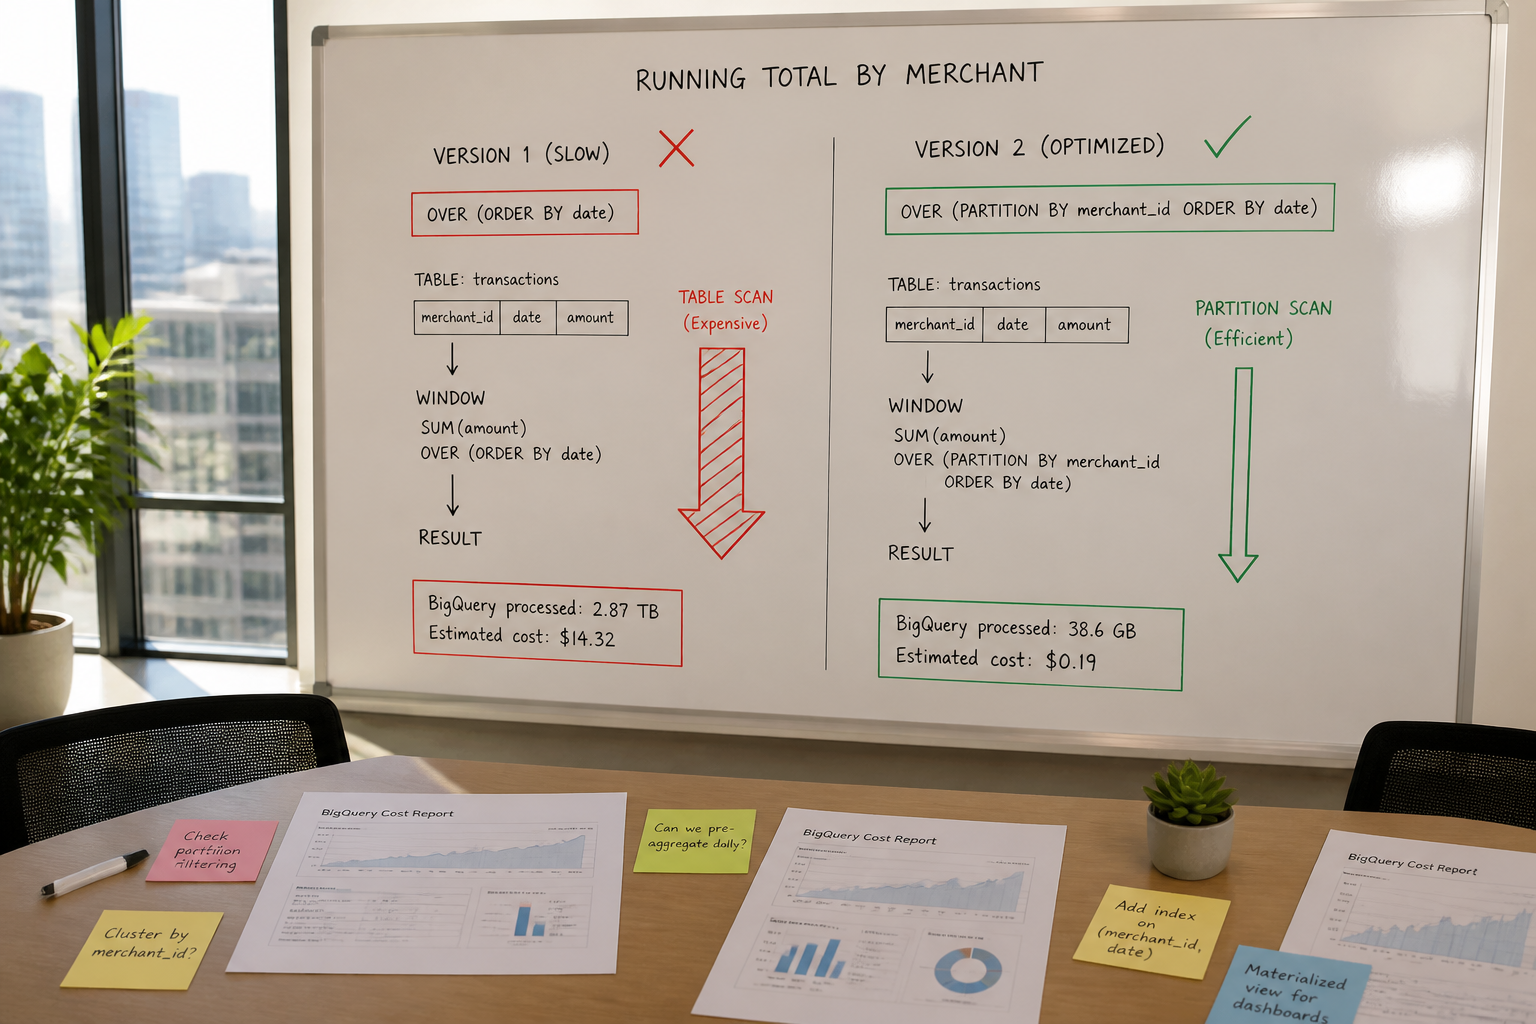
Here is the problem in concrete terms. Suppose you have a transactions table with 500 million rows, partitioned by transaction_date. You write a model that calculates a running total of amount for each merchant:
SELECT
  merchant_id,
  transaction_date,
  amount,
  SUM(amount) OVER (ORDER BY transaction_date) AS running_total
FROM transactions
WHERE transaction_date >= '2025-01-01'
Your WHERE clause looks reassuring — you are only asking for data from 2025 onwards. But the OVER (ORDER BY transaction_date) clause has no PARTITION BY. BigQuery interprets this as a single global window across every row that passes the filter — potentially hundreds of millions of rows that all need to be sorted together before the sum can be computed. In BigQuery, cost and runtime are strongly tied to how much data a query scans and outputs. And a global sort across a massive result set is one of the most slot-intensive operations in the query engine.
The corrected version is almost identical:
SELECT
  merchant_id,
  transaction_date,
  amount,
  SUM(amount) OVER (
    PARTITION BY merchant_id
    ORDER BY transaction_date
  ) AS running_total
FROM transactions
WHERE transaction_date >= '2025-01-01'
Now BigQuery evaluates the window independently per merchant_id. When you align window partitions with your analytical dimensions — customer cohorts, product categories, time periods — BigQuery can process these functions much more efficiently. Each merchant's running total is computed in isolation, the sort is scoped to that partition, and slot consumption drops dramatically.
📺 Watch: BigQuery WindowFunctions
The Four Failure Patterns We See in Real dbt Projects
In our work with early-stage fintech and e-commerce companies, window function misuse almost always falls into one of four patterns. None of them are obvious until you go looking.
Pattern 1: The global OVER() with no clause at all.
The most dangerous variant. OVER() with an empty clause is syntactically valid and produces a result — it just applies the function across every single row in the output without any partitioning or ordering constraint. We have seen this used (incorrectly) to calculate percentage-of-total metrics: SUM(revenue) OVER() AS total_revenue. At small data volumes it looks fine. At 200 million rows it is catastrophic.
Pattern 2: ROW_NUMBER() without a meaningful partition.
Deduplication is one of the most common uses of window functions inside dbt staging models. The typical pattern is ROW_NUMBER() OVER (PARTITION BY id ORDER BY updated_at DESC) — perfectly safe. But we regularly encounter models where a developer has written ROW_NUMBER() OVER (ORDER BY updated_at DESC) without the partition, either by omission or because they were working with a source that did not have a clean natural key yet. The dedup logic silently breaks and the bytes billed spike.
Pattern 3: Multiple incompatible window definitions in the same SELECT.
Using multiple window functions with different PARTITION BY or ORDER BY clauses forces BigQuery to re-sort data, which adds cost. A model that calculates five different window metrics — each with a slightly different frame definition — may be triggering five separate sort passes across the same dataset. The fix is to consolidate compatible windows using BigQuery's named WINDOW clause.
Pattern 4: Window functions layered on top of unfiltered CTEs.
A window function that would be cheap on filtered data becomes expensive when the CTE it references does not push the filter down. If your CTE selects FROM raw_events without a date filter, and the window function sits in the next CTE, BigQuery scans the full raw table before evaluating the window — even if your final WHERE clause would have excluded most of it. This is a data shuffle problem, not strictly a window problem, but window functions amplify it.
How to Find Unpartitioned Window Functions Across Your dbt Project
The fastest way to audit your project is with a combination of BigQuery's INFORMATION_SCHEMA and a quick grep of your dbt model SQL.
Start with cost: query INFORMATION_SCHEMA.JOBS to find your most expensive queries in the last 30 days, sorted by total_bytes_billed. Cross-reference those job IDs with the model names in your dbt manifest. This gives you a ranked list of models to audit — do not try to review everything at once.
SELECT
  job_id,
  query,
  total_bytes_billed,
  total_slot_ms,
  creation_time
FROM `region-eu.INFORMATION_SCHEMA.JOBS`
WHERE creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND job_type = 'QUERY'
  AND statement_type = 'SELECT'
ORDER BY total_bytes_billed DESC
LIMIT 50
Once you have your expensive queries, look for the pattern OVER (ORDER BY without a preceding PARTITION BY. That is your primary signal. In a dbt project, you can also run a simple grep from the command line:
grep -rn "OVER (ORDER BY" models/
This will surface every window function ordered without an explicit partition. Not all of them will be wrong — some analytical patterns genuinely require a global window — but each one needs a deliberate human decision, not a default.
If you want to go deeper on the cost side, the total_slot_ms column in INFORMATION_SCHEMA.JOBS is often more revealing than bytes billed for window function issues, because the slot consumption reflects the sort cost even when the byte scan looks modest. A query that processes 10 GB but runs for 45 seconds consuming 200,000 slot milliseconds is a window function problem, not a scan problem.
For teams using the dbt project governance patterns we have written about in dbt Project Governance for Startups: Stop Model Sprawl, this audit fits naturally into a quarterly model review cycle — not a one-time fix.
If you want Fintel Analytics to run this audit for you and prioritise the fixes by cost impact, explore our services — we work with growth-stage businesses globally to find and resolve exactly these kinds of hidden cost leaks in their BigQuery and dbt setups.
What This Actually Costs: Real Numbers From the Field
Abstract warnings about efficiency are easy to ignore. Concrete numbers are harder to dismiss.
A pattern we see repeatedly: a Series A payments company running a dbt project with approximately 80 models. Six of those models contained window functions — three of them were using global OVER() clauses to compute percentage-of-total metrics across their transaction ledger. The ledger table had grown to roughly 400 million rows over 18 months of operation. Those three models were responsible for 61% of total bytes billed across the entire project. Fixing the partition definitions — a two-hour code change — reduced monthly BigQuery spend on those models by over 70%.
This is not an unusual finding. Proper BigQuery SQL optimisation can reduce query costs by up to 90% while dramatically improving performance through strategic use of partitioning, clustering, and efficient query patterns. Window function correction is one of the highest-leverage places to start because the changes are surgical — you are not restructuring your pipeline, you are correcting a handful of OVER() clauses.
Advanced analytical queries — cohort analysis, time-series comparisons, running totals, rank calculations — rely heavily on window functions. The challenge in BigQuery is that poorly written window functions can consume massive compute resources, while optimised implementations deliver sophisticated analytics efficiently.
The other cost dimension is correctness. An unpartitioned ROW_NUMBER() used for deduplication does not just cost more — it produces wrong results. If you are using that model downstream to feed a revenue metric or a reconciliation process, you are reporting on bad data. We have seen this produce material discrepancies in financial reporting that took days to trace back to a single missing PARTITION BY. A reconciliation process rebuilt correctly as a clean SQL pipeline — where deduplication logic is explicit and tested — eliminates that entire class of error. The cost is not just the BigQuery bill; it is the analyst time spent firefighting incorrect numbers.
For further context on the related pattern of silent data quality failures in dbt, our post on dbt Lineage Blind Spots: Why Downstream Models Break Silently covers how upstream model changes propagate undetected downstream — a close cousin of the silent correctness failure described here.
How to Fix It: The Named WINDOW Clause Pattern
Once you have identified the offending models, the fix is usually straightforward. The key principle: every window function in a production dbt model should have an explicit PARTITION BY clause unless a global window is a deliberate, documented analytical choice.
For models with multiple window functions, use BigQuery's named WINDOW clause to avoid repetition and guarantee consistency:
SELECT
  merchant_id,
  transaction_date,
  amount,
  SUM(amount) OVER merchant_window AS cumulative_amount,
  AVG(amount) OVER merchant_window AS avg_to_date,
  ROW_NUMBER() OVER merchant_window AS rn
FROM transactions
WHERE transaction_date >= '2025-01-01'
WINDOW merchant_window AS (
  PARTITION BY merchant_id
  ORDER BY transaction_date
)
This demonstrates how to use named windows in BigQuery to efficiently perform multiple window function calculations. Defining and reusing named windows allows you to streamline your queries and maintain consistent analysis across different metrics.
For deduplication patterns specifically, make the partition explicit and add a dbt test to assert that the deduplicated model contains no duplicate keys. This is the single most effective safeguard — if the partition logic ever breaks, the test catches it before the model reaches production. If you have not yet implemented systematic test coverage across your dbt project, start with dbt Models With No Tests: Find Them in BigQuery Now.
For the "window function on an unfiltered CTE" problem, the fix is to push your date filters as far upstream as possible — ideally into your staging models — so that every downstream transformation operates on an already-filtered dataset. Repeated full-table scans and inefficient result caching are among the primary cost drivers in BigQuery analytical workloads. Keeping filters high in the CTE chain prevents window functions from amplifying those scan costs.
Finally, set a query cost limit at the project or user level using BigQuery's custom quotas. Most BigQuery cost problems show up the wrong way: a surprise line item in last month's invoice, a data team lead forwarding a screenshot of a spike. By the time the conversation starts, the query that caused it ran two weeks ago. A per-query byte limit catches runaway window functions before they complete — not after you get the invoice.
Frequently Asked Questions
Q: What happens if I use OVER() with no PARTITION BY in BigQuery?
A: BigQuery treats your entire result set as a single window, meaning every row must be processed together before the function can evaluate. This forces a global sort and dramatically increases slot consumption and bytes billed. For large tables, this can turn a cheap query into an expensive one with no warning.
Q: Does a WHERE clause prevent BigQuery from scanning extra rows in a window function?
A: Partially. The WHERE clause filters which rows are passed to the window function, but it does not reduce the cost of the window operation itself if the window spans all remaining rows without a PARTITION BY. You still pay for the full sort and aggregation across every row that survives the filter.
Q: How do I find expensive window functions in my BigQuery project?
A: Query INFORMATION_SCHEMA.JOBS in your BigQuery region, sorted by total_bytes_billed or total_slot_ms, and inspect the SQL of your most expensive queries for OVER (ORDER BY patterns without a preceding PARTITION BY. Cross-reference with your dbt model names from the manifest to prioritise fixes.
Q: Can I use the named WINDOW clause in dbt models?
A: Yes. BigQuery's named WINDOW clause is fully supported in dbt SQL models. It is particularly useful when a single model computes multiple window metrics with the same partition and ordering logic — it reduces repetition and guarantees consistency across all window definitions in the query.
Q: How much can fixing unpartitioned window functions reduce my BigQuery costs?
A: The impact varies by table size and query frequency, but in our experience with growth-stage companies, correcting window function partition definitions in the worst-offending models can reduce their individual query costs by 50–90%. For organisations where analytical models are the primary cost driver, this often translates to a meaningful reduction in total monthly BigQuery spend.
Unpartitioned window functions are a quiet tax on every analytical team running BigQuery at scale — they produce inflated bills, slow dashboards, and in the worst cases, silently incorrect numbers flowing into financial and operational reports. At Fintel Analytics, we have helped fintech, payments, and e-commerce companies find and fix these exact patterns as part of data stack audits and ongoing engineering engagements — often recovering significant monthly cloud spend within the first two weeks. If your BigQuery bill has been climbing faster than your data volume and you do not have a clear explanation for why, this is one of the first places we would look.