
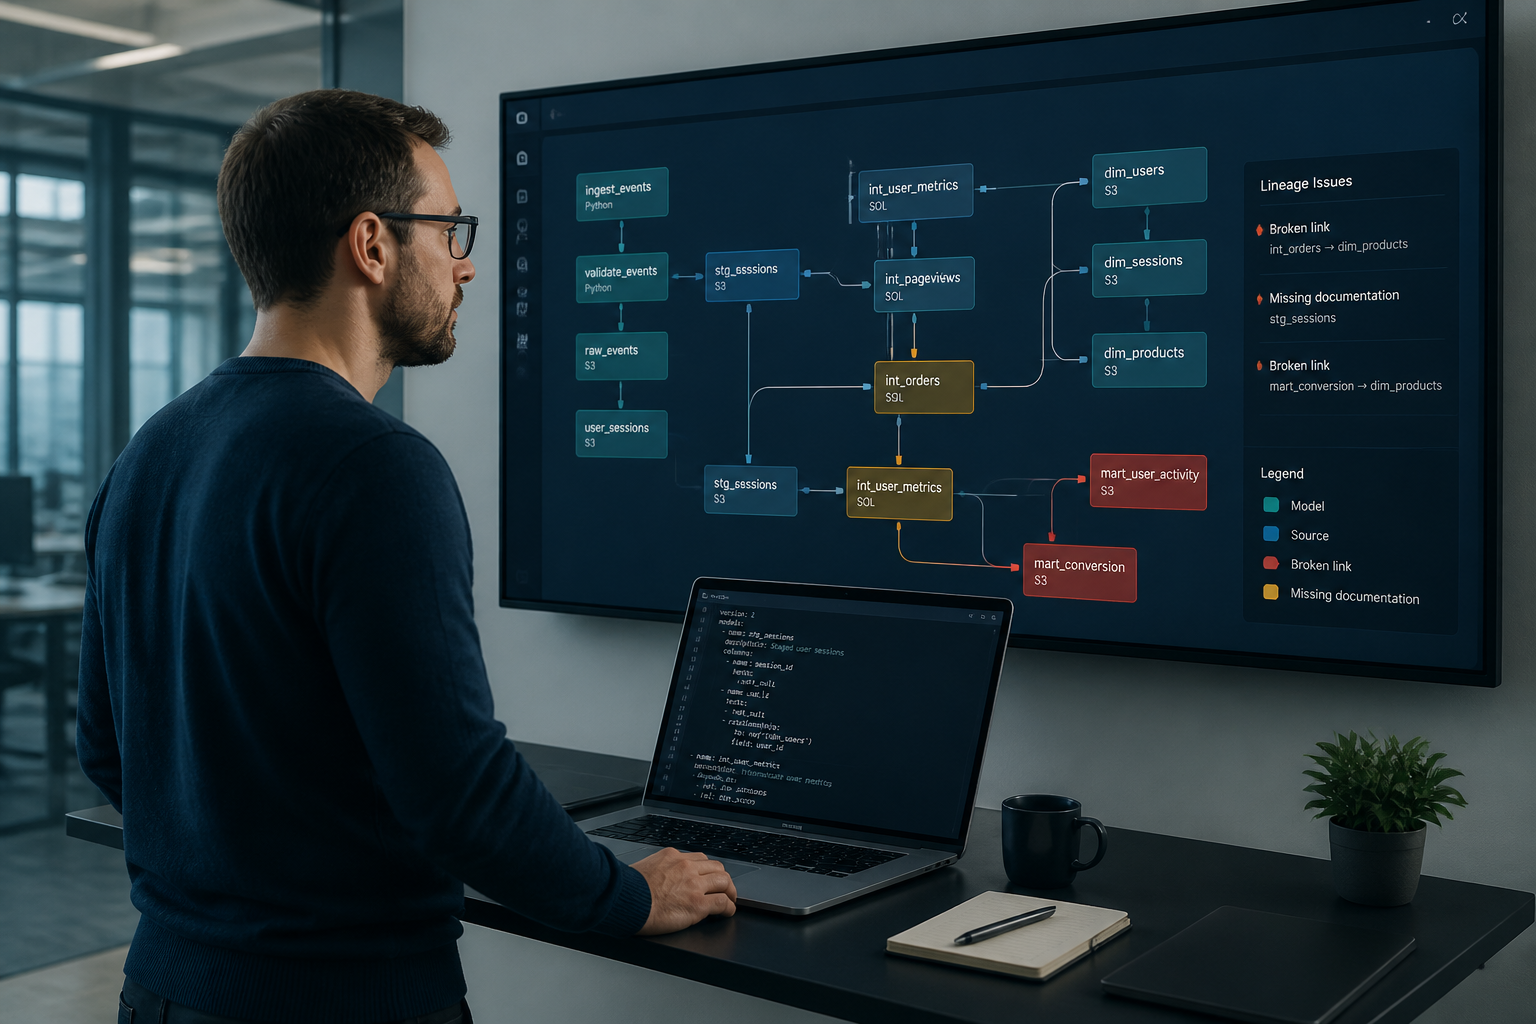
Broken downstream dbt models rarely announce themselves loudly. A source schema changes, an upstream model is quietly refactored, and three dashboards start showing wrong numbers — usually discovered by a finance lead asking why last month's revenue looks different today. Effective dbt model lineage management means knowing exactly what depends on what, enforcing that knowledge in code, and making upstream changes safe before they reach production. Without it, your DAG is a dependency graph that only the person who built it fully understands — and even they forget after six months.
This is one of the most common failure modes we see in growth-stage companies that have been using dbt for twelve to eighteen months. The project started clean. Models were few, the DAG was readable, and everyone knew where everything lived. Then the business scaled, the team grew, and the project accumulated models faster than it accumulated discipline. Now nobody is entirely sure which downstream marts will break if they rename a column in a staging model — so they either don't make the change, or they make it and find out the hard way.
Why dbt Lineage Becomes a Liability as Projects Grow
dbt's core proposition is powerful: version-controlled, modular, testable SQL transformations with a built-in dependency graph. The DAG is one of dbt's most valuable features. But the DAG only tells you what depends on what — it does not tell you whether those dependencies are intentional, documented, tested, or safe to modify.
As dbt projects grow, they introduce complexity that small-team usage doesn't expose. The most common failure mode is not a technical one — it is model proliferation without governance. Models accumulate faster than ownership is assigned, testing coverage degrades under delivery pressure, and the DAG becomes an undocumented dependency graph that nobody fully understands.
The practical consequence is a project where:
- Staging models are referenced directly by mart models and by ad-hoc intermediate models built months later by a different analyst
- Columns in widely-used staging models carry no descriptions, so downstream consumers make assumptions about nullability, grain, and transformation logic that may be wrong
- A model that was built as a one-off exploratory query has quietly become a dependency of three production dashboards
- Nobody has mapped which BI reports break if a given model is deprecated or restructured
A pattern we see repeatedly in our work with early-stage companies: a data engineer refactors a staging model to fix a date-handling bug. The change is correct. It passes the two tests that exist on that model. It deploys without error. Two days later, a finance analyst notices that a month-to-date revenue figure in their Holistics dashboard no longer matches the number in their reconciliation sheet. The intermediate model sitting between the staging layer and the mart layer had an implicit dependency on the old date logic — but it had no tests, no documentation, and no owner. The pipeline ran clean. The numbers were wrong.
📺 Watch: A simple 4-step process for creating dbt models

What "Lineage Hygiene" Actually Means in Practice
Lineage hygiene is not about making your DAG look pretty in dbt's documentation site. It is about enforcing three properties across every model in your project:
1. Documented intent — every model, especially in the staging and intermediate layers, should have a description that explains what it represents, its grain, and any transformation decisions that are not self-evident from the SQL. Every mart layer model should have a description. Every column in every mart model should have a description. Undocumented columns in production models are a technical debt indicator.
dbt's project recommendations surface model documentation coverage — the percentage of models with a description — alongside model test coverage, the percentage of models with at least one test configured. In most projects we audit, these numbers are lower than the team expects. Documentation coverage tends to cluster in the mart layer, which gets the most stakeholder attention, while staging and intermediate models — the ones most likely to be refactored — go undocumented.
2. Declared ownership — every model should have a declared owner in its .yml metadata. Every model needs a defined owner — the team responsible for accuracy, freshness, and test coverage. Use dbt's meta property to declare ownership in every model's yml file. Undocumented ownership means undocumented accountability. When a model has no owner, refactors happen without stakeholder review, and nobody is responsible for the downstream consequences.
3. Tested contracts at layer boundaries — the boundary between your staging and intermediate layers, and between your intermediate and mart layers, should be treated like a contract. Any column that flows across a layer boundary should have a not-null test and, where appropriate, an accepted-values or relationships test. This is not about testing everything — it is about making the implicit contract explicit and machine-verifiable.
Start with critical paths: focus testing efforts on models that directly impact business decisions. In a typical growth-stage dbt project, that means prioritising the mart models that feed executive dashboards, finance reports, and operational tooling — and then tracing back to every upstream dependency of those models.
How to Audit Your DAG for Hidden Lineage Risks
If you are not sure how exposed your project is, here is the audit we run with clients. It takes a half-day and reveals more than most teams expect.
Step 1 — Generate and review documentation coverage.
Run dbt docs generate and open your project's documentation site. Look at the model graph and filter for models with no description. Pay particular attention to intermediate models (int_ prefix or equivalent) — these are the most commonly undocumented and the most dangerous to refactor blindly.
Alternatively, the dbt-coverage package computes documentation and test coverage as quantified metrics:
dbt-coverage compute documentation --cov-report coverage-doc.json
dbt-coverage compute test --cov-report coverage-test.json
Aim for comprehensive coverage on critical business metrics and primary keys. We treat anything below 80% documentation coverage on mart-layer models as a red flag that warrants immediate remediation.
Step 2 — Map BI exposure to model dependencies. For every model in your mart layer, document which dashboards, reports, or downstream tools consume it. Downstream exposures in dbt help users understand how their models are used in downstream analytics tools, informing investment decisions and reducing incidents. If you are on dbt Cloud and using Tableau, this can be partially automated — but for most growth-stage companies using Holistics, Looker, or similar tools, this mapping needs to be done manually the first time.
Once you have it, you can assess blast radius: if a given model breaks or changes behaviour, how many dashboards are affected, and who relies on them? A model consumed by the CFO's weekly revenue report has a very different blast radius than a model used only in an internal analytics exploration.
Step 3 — Identify undeclared cross-layer references.
Search your project for any model that references a staging model (ref('stg_...')) from within the mart layer, skipping the intermediate layer entirely. This is a common lineage smell — it means transformation logic that should live in an intermediate model has been embedded directly in a mart, creating a tight coupling that is hard to test and easy to break.
Similarly, flag any model that references more than four or five upstream models via ref() without having tests on its output columns. The more upstream sources, the more vectors for silent data quality degradation.
Step 4 — Review deprecation candidates.
Run a query against your data warehouse's INFORMATION_SCHEMA to identify dbt-generated tables or views that have not been queried in the last 30 days. Cross-reference against your DAG to find any downstream dependencies on those models. Stale models that are still in the dependency chain are lineage debt — they continue to be built, consume compute, and carry risk, without delivering value.
If you want to go deeper on the related cost dimension, our post on BigQuery scheduled query costs walks through how to identify which models are running unnecessarily and what they are costing you.
The Real Cost of Ignoring Lineage Hygiene
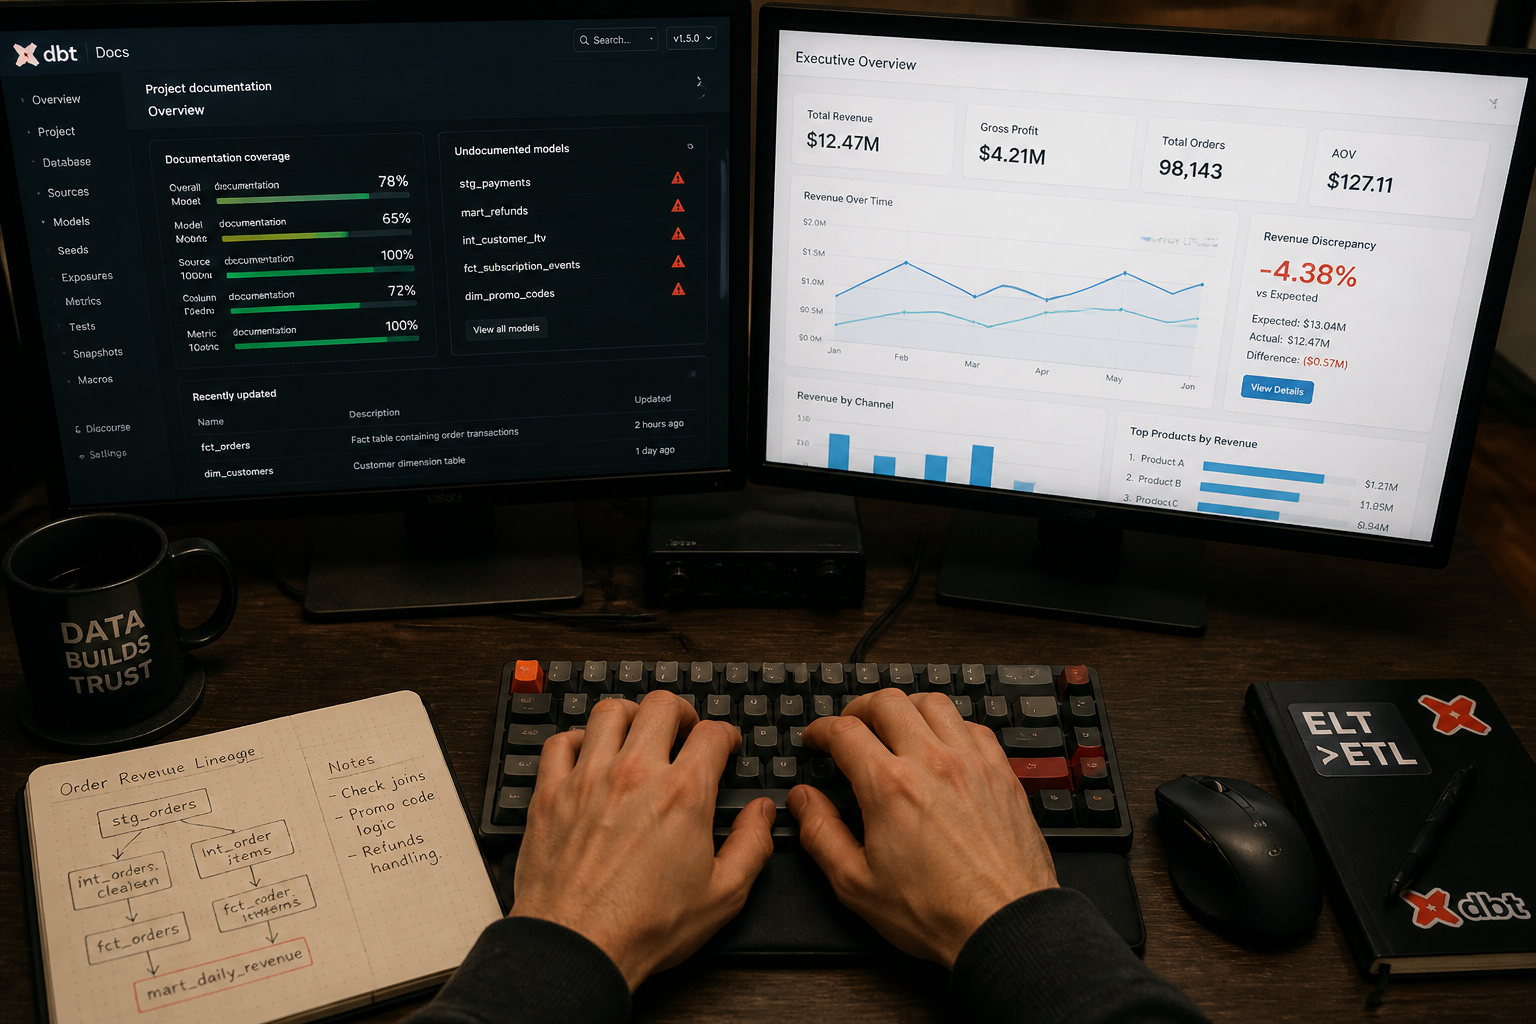
The cost of a lineage failure is rarely captured in a single incident report, which is why it tends to be underinvested in. It shows up as:
- Analyst time lost to investigation — when a dashboard shows unexpected numbers, the default response is a manual investigation. A pattern we see repeatedly: what looks like a data question turns out to be a pipeline question, and resolving it takes hours of debugging across the DAG.
- Decisions made on stale or incorrect data — the most dangerous version of a lineage failure is one that produces plausible-looking wrong numbers. Metrics that are slightly off but not obviously broken get used in planning, hiring, and investment decisions.
- Deployment paralysis — teams that have been burned by silent downstream failures become reluctant to refactor or improve their models. The technical debt accumulates, the DAG becomes increasingly rigid, and the cost of any future change grows.
A 2025 report by the IBM Institute for Business Value found that 43% of chief operations officers identify data quality issues as their most significant data priority — and over a quarter of organisations estimate they lose more than USD 5 million annually due to poor data quality.
For a growth-stage company, the numbers are smaller in absolute terms, but the proportional impact is often greater. When we rebuilt a reconciliation process for a global fintech — migrating the logic out of a tangle of undocumented intermediate models and into a properly tested, documented SQL pipeline — the process went from 30–50 minutes of fragile, manual-dependent execution to completing in under 3 seconds. The lineage problem was not just a code quality issue; it was an operational bottleneck that had been normalised.
The 2024 State of Analytics Engineering survey highlights that poor data quality emerged as a predominant issue for the majority of respondents — and lineage failures are one of the primary mechanisms through which poor data quality propagates in dbt-based projects.
If your team is spending meaningful time each sprint investigating "why the numbers changed," that is a lineage problem, not a data problem. And it is solvable. If you want to understand how Fintel Analytics approaches this kind of project, explore our services — we work with growth-stage companies globally to design, audit, and remediate dbt projects so that refactoring is safe and pipelines are trustworthy.
How to Build Lineage Safety Into Your dbt Workflow Going Forward
Auditing your current project is a one-time exercise. Keeping it clean is a process. These are the practices we embed into every dbt engagement we deliver:
Enforce documentation coverage in CI. Add a step to your CI pipeline that fails the run if a new model is merged without a description. This can be done with a simple dbt pre-commit hook or a custom check in your CI configuration. Making documentation a merge requirement turns it from an aspirational standard into an enforced one.
Require a meta.owner tag on every model.
Add a project-level check that fails if any model is missing its meta.owner property. This single change makes accountability explicit and ensures that when a model is about to be changed, there is a named team or person to notify.
Treat intermediate-to-mart boundaries as contracts. Any column exposed from the intermediate layer into a mart model should have a corresponding test. Not-null tests on join keys. Relationships tests where foreign keys reference other models. Accepted-values tests on status or type columns. This is the minimum viable contract that makes downstream refactoring safe.
Document breaking change intent before merging. For any PR that modifies a model which has downstream dependencies, require the author to list the affected downstream models and confirm that each has been reviewed. This is a lightweight process change that prevents the most common class of silent lineage failure — the refactor that nobody realised was breaking.
For teams that are also dealing with out-of-control model growth alongside lineage problems, our post on dbt project governance for startups covers the structural decisions that prevent these problems from recurring.
Frequently Asked Questions
Q: What is dbt model lineage and why does it matter?
A: dbt model lineage refers to the dependency graph between your transformation models — which models reference which, and how data flows from raw sources through to mart-layer tables consumed by dashboards and reports. It matters because any change to an upstream model can silently break every downstream model that depends on it, producing wrong numbers in production without triggering a pipeline error.
Q: How do I check lineage in a dbt project?
A: Run dbt docs generate and open the documentation site to view the DAG visually. You can also use dbt ls --select +model_name to list all ancestors of a given model, or dbt ls --select model_name+ to list all descendants. For quantified coverage metrics, the dbt-coverage package computes documentation and test coverage scores across your entire project.
Q: What causes silent downstream failures in dbt pipelines?
A: The most common causes are: renaming or removing a column in an upstream staging model without checking what references it; changing the grain of an intermediate model without updating downstream aggregation logic; and deploying a model that passes its own tests but whose output breaks assumptions in an undocumented downstream model. Weak test coverage at layer boundaries is the root enabler.
Q: How much documentation coverage should a dbt project have?
A: At minimum, every mart-layer model and every column in every mart-layer model should be documented. For intermediate models, every model should have a description, and any column that flows into a mart-layer join key or aggregation should be described. Staging models should document non-obvious transformations and grain decisions. Aim for 100% on mart models and 80%+ on intermediate models as a production standard.
Q: How do I prevent upstream dbt model changes from breaking production?
A: The most effective approach combines three things: enforced documentation and ownership (so every model has a declared owner who is consulted before changes); contract tests at layer boundaries (not-null, relationships, and accepted-values tests on columns that cross layer boundaries); and a CI step that lists affected downstream models for any PR that modifies a model with dependents. Together, these make breaking changes visible before they reach production.
Undocumented dbt dependencies are one of those problems that feels manageable right up until the moment it isn't — and by then, a finance lead has spent an afternoon investigating a discrepancy that should never have existed. At Fintel Analytics, we have audited and remediated dbt projects for growth-stage companies across fintech, payments, and e-commerce, and we know exactly where the lineage debt hides and what it takes to clear it safely. If your team is losing time to unexplained number changes, deployment anxiety, or a DAG that only one person truly understands, that is a fixable problem — and fixing it makes every future sprint faster and every refactor safer.