
dbt project governance for startups means defining ownership, documentation, and testing standards before your model count outpaces your team's ability to understand the DAG. Without it, models accumulate faster than trust, and a change to one upstream model can silently break the metrics your leadership team relies on every week.
If you have been running dbt for more than six months at a growing company, there is a reasonable chance your project already has a governance problem — you just haven't felt the full pain of it yet. This post covers what model sprawl actually looks like in practice, where the real risk sits, and exactly how to structure governance controls before they become urgent.
Why Does dbt Model Sprawl Happen to Fast-Growing Companies?
Every dbt project starts clean. You have a handful of staging models, a few mart models, and a DAG you could draw from memory. Then the company grows. A new data source gets added. Someone needs a one-off model to answer an investor question. A contractor builds a transformation layer that uses slightly different logic from the one that already exists. Nobody deletes anything — deletion feels dangerous — so the project accumulates.
This is not a discipline failure. It is a structural one. Fast-moving teams are rewarded for shipping, not for refactoring. In the absence of enforced governance, the rational individual behaviour is to add a new model rather than modify a shared one, to skip documentation under deadline pressure, and to copy-paste logic rather than abstract it cleanly.
The consequence is predictable. The most common dbt failure mode is not a technical one — it is model proliferation without governance. Models accumulate faster than ownership is assigned, testing coverage degrades under delivery pressure, and the DAG becomes an undocumented dependency graph that nobody fully understands.
We see this pattern repeatedly in early and growth-stage companies that have been running dbt for twelve to eighteen months. The first sign is usually not a broken pipeline — it is a metrics trust problem. Finance quotes a number that doesn't match what the product dashboard shows. Someone asks "which model should I be using?" and nobody can answer confidently. At that point, the governance debt has already compounded.
📺 Watch: Scaling dbt from startup to scale up with Gopuff (Mike Angelo & Hassan Al Rabea)
What Are the Real Risks of an Ungoverned dbt Project?
The risks are not abstract. Let's be specific about where ungoverned dbt projects actually hurt you.
Broken downstream metrics from upstream changes. When a source schema changes — a field is renamed, a column is dropped, a data type shifts — a governed project detects this at the source layer and fails loudly. An ungoverned project propagates the change silently downstream. If nobody has defined a contract on the model feeding your revenue dashboard, you may not notice the problem until a board meeting. We have written before about dbt source schema drift and how to detect it before it breaks production — the same failure mode applies equally to internal model-to-model dependencies in sprawling projects.
Compute cost from redundant and inefficient models. Every materialised model that runs on a schedule costs money. Ungoverned projects accumulate models that were built for a specific analysis, materialised as tables for performance, and then forgotten — continuing to scan your data warehouse on every pipeline run. Without a structured framework, the proliferation of undocumented models and lack of testing lead to errors, high compute costs, and loss of confidence in KPIs. One case study from 2026 found that introducing naming standards, mandatory tests, and a biannual cleanup of unused models in a disorganised dbt project stabilised warehouse performance and reduced annual compute costs by 30%.
Logic duplication producing divergent metrics. In a sprawling project, the same concept gets defined multiple times, differently. "Active customer" means one thing in the CRM mart and something subtly different in the payments mart. When two dashboards consume different models, they produce different numbers — and leadership loses trust in both. This is the same single source of truth problem that shows up when critical logic lives in spreadsheets, except now it is hidden inside a version-controlled project that looks governed from the outside.
Onboarding failure. A new analytics engineer joins, looks at a 200-model DAG with no descriptions and no ownership assignments, and either asks the wrong person or guesses. Either way, institutional knowledge that should be encoded in the project instead lives in the heads of the people who built it. When those people leave — and they do — the knowledge goes with them.
Test coverage rot. dbt's built-in tests — not_null, unique, accepted_values, relationships — are the minimum, not the complete testing strategy. Under delivery pressure, teams stop adding tests to new models, and test failures start getting suppressed rather than fixed. Over time, the test suite becomes a formality rather than a safeguard.
What Does Good dbt Project Governance Actually Look Like?
Governance does not mean bureaucracy. It means a small number of enforced standards that prevent the most expensive failure modes. Here is what that looks like in practice at a startup running dbt in production.
1. Folder structure as enforced architecture.
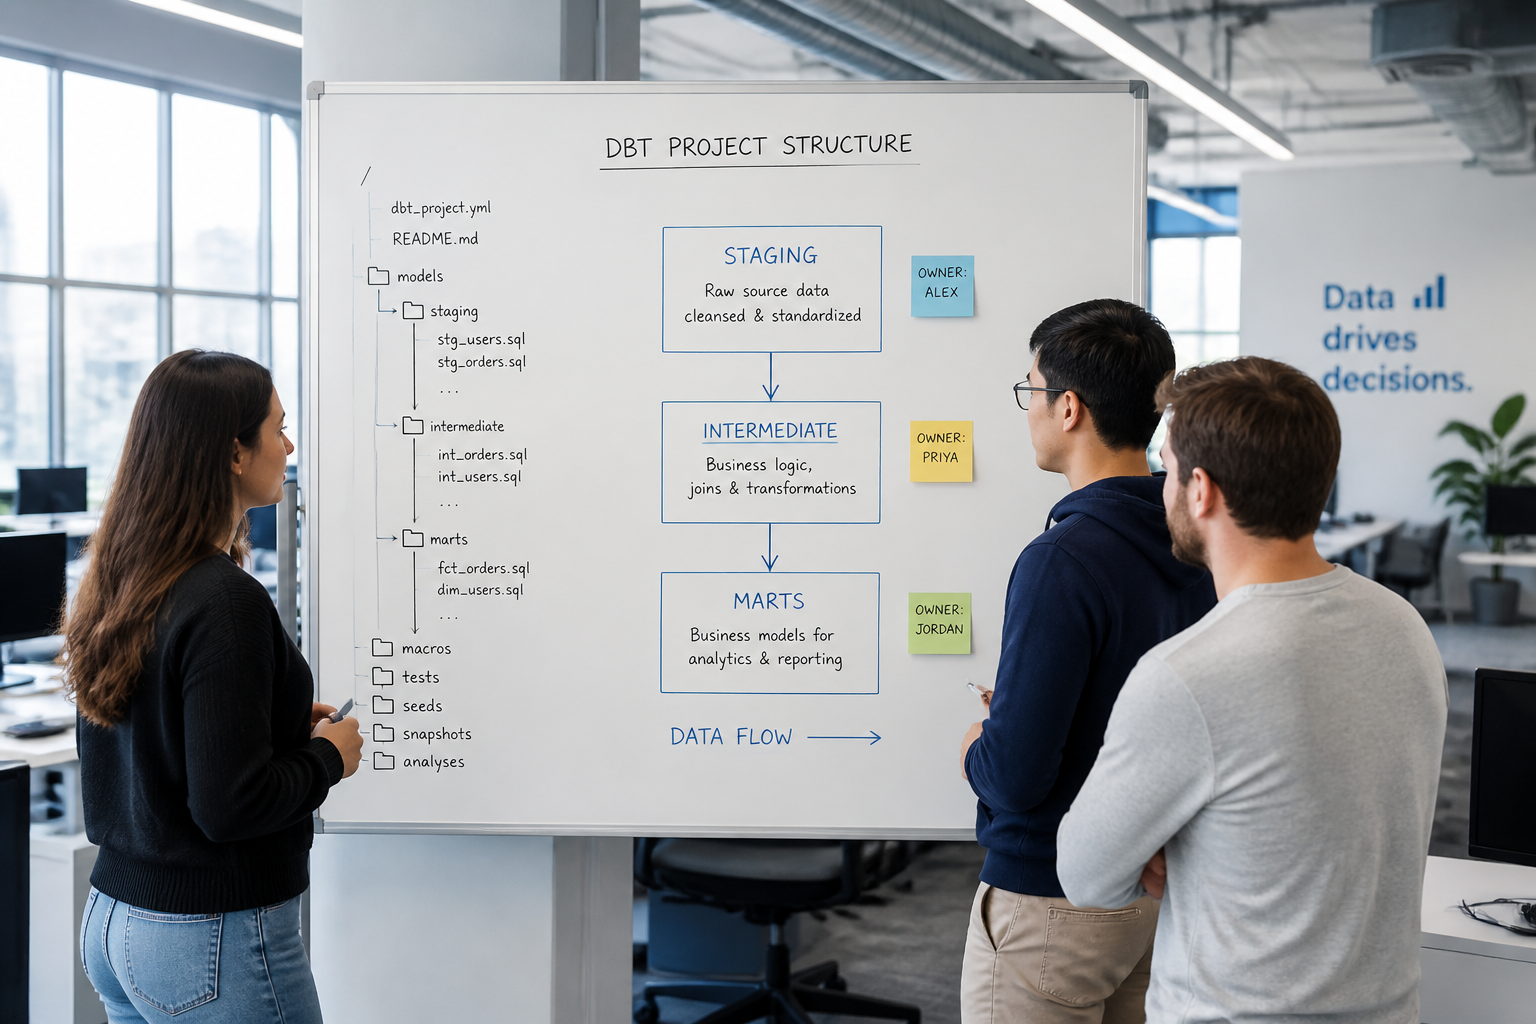
The single most effective governance decision you can make early is enforcing a three-layer folder convention: staging/, intermediate/, and marts/. Staging models do one thing — they clean and rename raw source data, one model per source table. Intermediate models join and aggregate staging models. Marts are the final, business-facing outputs that consumers — dashboards, reverse ETL, downstream applications — should reference.
This convention is not just aesthetic. It enforces a rule that prevents the most common structural failure in growing dbt projects: lateral dependencies. A mart model should never reference another mart model. If it does, you have a dependency that is invisible from the DAG and will break in unpredictable ways as the project evolves. These constraints prevent the dependency tangles that make large dbt projects fragile. The failure mode appears gradually — the first lateral dependency is a pragmatic shortcut, the fifth is a pattern, the fifteenth is an architectural problem requiring significant refactoring to untangle.
2. Mandatory ownership in model YAML.
Every model in the marts/ layer should have a meta.owner field in its YAML definition. This is not about blame — it is about routing. When a test fails at 3am, someone needs to be paged. When a downstream consumer asks why a metric changed, someone needs to be accountable for the model's definition. Ownership also drives documentation quality: people document models they own.
3. Documentation coverage as a CI gate.
The dbt_project_evaluator package from dbt Labs surfaces models that are missing descriptions at the model and column level. The fct_undocumented_public_models check highlights any public model that does not have a model-level description as well as descriptions on each of its columns — a stricter check than basic undocumented model detection. Run this as part of your CI pipeline. Merge requests that introduce undocumented public models should not pass. This sounds draconian; in practice it takes three minutes to write a model-level description and thirty seconds per column. The cost of enforcement is low; the cost of not enforcing it compounds every month.
dbt's documentation serves as a single source of truth for data teams — it allows users to define descriptions for models, columns, and sources, reducing confusion and improving collaboration. By providing clear context around data assets, dbt documentation ensures everyone works with accurate and up-to-date information.
4. Test coverage tiers, not blanket testing.
Not every model needs every test. A sensible tiered approach for startup teams:
- Staging models:
not_nullanduniqueon primary keys. That is the floor. - Intermediate models:
relationshipstests where foreign keys exist. Addaccepted_valueswhere business logic constrains a column. - Mart models: Full coverage — primary key integrity, business logic assertions (refund amount never exceeds order amount, LTV is always positive), and freshness checks.
Pairing dbt's built-in tests with a dedicated data observability integration such as Elementary extends coverage to freshness and anomaly detection that dbt tests alone don't catch.
If you are building custom test logic for business assertions, write it once as a generic test macro and apply it across the relevant models. You can create your own generic tests using macros — write a test once and apply it to multiple models throughout your project, enforcing consistency and saving time.
5. Model contracts on mart-layer outputs.
Once a mart model is being consumed by a dashboard, a reverse ETL pipeline, or an external application, it should have a dbt model contract. A contract declares the expected column names and data types and enforces them at run time — if an upstream change would break the contract, the run fails before the consumer sees bad data. Imagine a pipeline loading customer data where the marketing team expects a field called customer_name, but an upstream change renames it to customer_full_name — the marketing team's process consumes the break without anyone immediately noticing. A model contract makes this impossible. It is the programmatic equivalent of a formal interface agreement between data producers and data consumers.
If you want to explore how Fintel Analytics structures dbt governance — from folder conventions and CI gates through to mart-layer contracts and ownership models — explore our services to see how we approach this with early-stage and growth-stage clients.
How Do You Recover a dbt Project That Already Has Governance Debt?
This is the question that most teams actually need answered. The theoretical governance framework is useful for greenfield projects. But the majority of teams reading this already have a project that has accumulated some degree of sprawl. Here is a pragmatic recovery path.
Step 1: Audit what you actually have.
Run dbt_project_evaluator against your project and export the results. You will get a list of undocumented models, models without tests, models without owners, and models with no downstream consumers (i.e., orphaned models that are running and costing money but serving nothing).
Step 2: Classify by exposure.
Not all technical debt is equally urgent. Prioritise models that are:
- Directly consumed by dashboards or downstream systems (highest risk)
- Referenced by many other models (high blast radius if changed)
- Used in financial or compliance reporting (highest consequence of error)
Models that have no downstream consumers, no recent query history, and no owner should be candidates for deprecation. Mark them with a deprecated: true tag in YAML, suppress their tests, and schedule deletion after a defined period. This alone will reduce your compute bill and clean your DAG.
Step 3: Enforce the new standard at the PR level.
Do not try to retroactively document 200 models in a sprint — that is a motivation-destroying project that will be abandoned. Instead, set a policy: any model touched in a PR must meet the new documentation and test standard before merge. Over six months, the most actively maintained models — which are also the most important ones — will be compliant. The long tail of stale models will be visible by contrast.
Step 4: Add model contracts to your most critical mart models first.
Start with the five models that, if broken, would cause the most damage. Apply contracts, assign owners, and write the descriptions. These become your reference implementations — the standard that new models are compared against during review.
A pattern we see repeatedly is that teams are reluctant to invest in this recovery work because it feels like maintenance rather than feature development. The reframing that lands with founders and CTOs is this: model sprawl is not a technical debt problem, it is a business risk problem. The $25M reconciliation discrepancy that went undetected in one client's financial data — a gap that was costing over $6,000 per day at market borrowing rates before we found it — was invisible precisely because the transformation layer had no governance, no contracts, and no test coverage on the models feeding the reconciliation.
What Should a Startup dbt Project Look Like at 50, 100, and 200 Models?
A useful governance benchmark by project size:
Under 50 models: Enforce folder structure and primary key tests universally. Write model-level descriptions for every mart. Do not add governance overhead beyond this — before adding governance features, consider whether your dbt project is ready to benefit from them. Introducing governance while models are still changing can complicate future changes. At this stage, keep it simple.
50–100 models: Add ownership metadata to all mart models. Introduce dbt_project_evaluator to CI. Start enforcing column-level documentation on public models. Apply model contracts to your two or three most business-critical outputs.
Over 100 models: You need a formal model tier policy (staging / intermediate / marts), a deprecation process, a quarterly DAG audit, and model contracts on all consumer-facing outputs. dbt at scale introduces complexity that small-team usage doesn't expose. At this point the project is large enough that a new team member cannot hold the full DAG in their head — documentation is no longer optional, it is the only way the system remains navigable.
For context on the scale of adoption driving these patterns: the 2025 dbt State of Analytics Engineering survey found over 30,000 organisations using dbt in production. The tooling has matured; the governance practices have not kept pace in the majority of fast-growth teams.
Frequently Asked Questions
Q: How do I detect undocumented and orphaned models in my dbt project?
A: Install the dbt_project_evaluator package and run it against your project. It surfaces undocumented models, models without tests, models without owners, and models with no downstream consumers. Run it as part of your CI pipeline so new violations are caught at merge time rather than after the fact.
Q: What is the difference between a dbt model contract and a dbt test?
A: A dbt test validates data values at run time — checking that a column is not null, that values are unique, or that a business logic assertion holds. A dbt model contract validates the structure of the model — it enforces that expected column names and data types are present and will cause the run to fail if an upstream change would alter the model's interface. Tests catch bad data; contracts catch breaking schema changes.
Q: When should a startup introduce dbt model contracts?
A: Introduce model contracts on any mart model that is being consumed by a downstream system — a dashboard, a reverse ETL pipeline, an external API, or a financial report. Once a model has a consumer that depends on its structure, that structure should be formally declared. Typically this becomes relevant when your project reaches 30–50 models and you have stable, business-facing outputs.
Q: How do I stop my dbt project's compute costs from growing as we add more models?
A: Three levers: first, audit for orphaned models with no downstream consumers and deprecate them — they are running on a schedule and scanning data for no purpose. Second, review materialisation strategies — not every model needs to be a table; views add no compute cost until queried. Third, check your incremental model configurations for full-refresh footguns. See our post on dbt incremental models strategy for a detailed breakdown.
Q: What is the minimum viable governance setup for a dbt project at a 20-person startup?
A: Four things: enforce the staging / intermediate / marts folder convention; add not_null and unique tests to all primary keys; write a model-level description for every mart model; and assign a meta.owner to every mart model. This takes a day to implement on an existing project and prevents 80% of the most common failure modes. Everything beyond this is incremental improvement.
Ungoverned dbt projects do not break all at once — they degrade gradually, and by the time the pain becomes undeniable, the cleanup effort is an order of magnitude larger than early prevention would have been. At Fintel Analytics, we work with pre-seed through Series B companies to audit, restructure, and govern their dbt projects — building the ownership models, CI gates, contract layers, and documentation standards that let fast-moving teams ship confidently without accumulating trust-destroying technical debt. If your data team is spending time firefighting metrics discrepancies instead of building new capability, that is a structural problem with a structural fix.