
dbt's Default Behaviour Will Silently Drop Your Columns
dbt incremental models default to on_schema_change='ignore', which means when a source table gains a new column, that column is never picked up — your model runs green, your tests pass, and the data simply disappears into the floor. The failure is invisible until a downstream analyst or dashboard consumer notices a blank field and starts asking questions nobody can immediately answer.
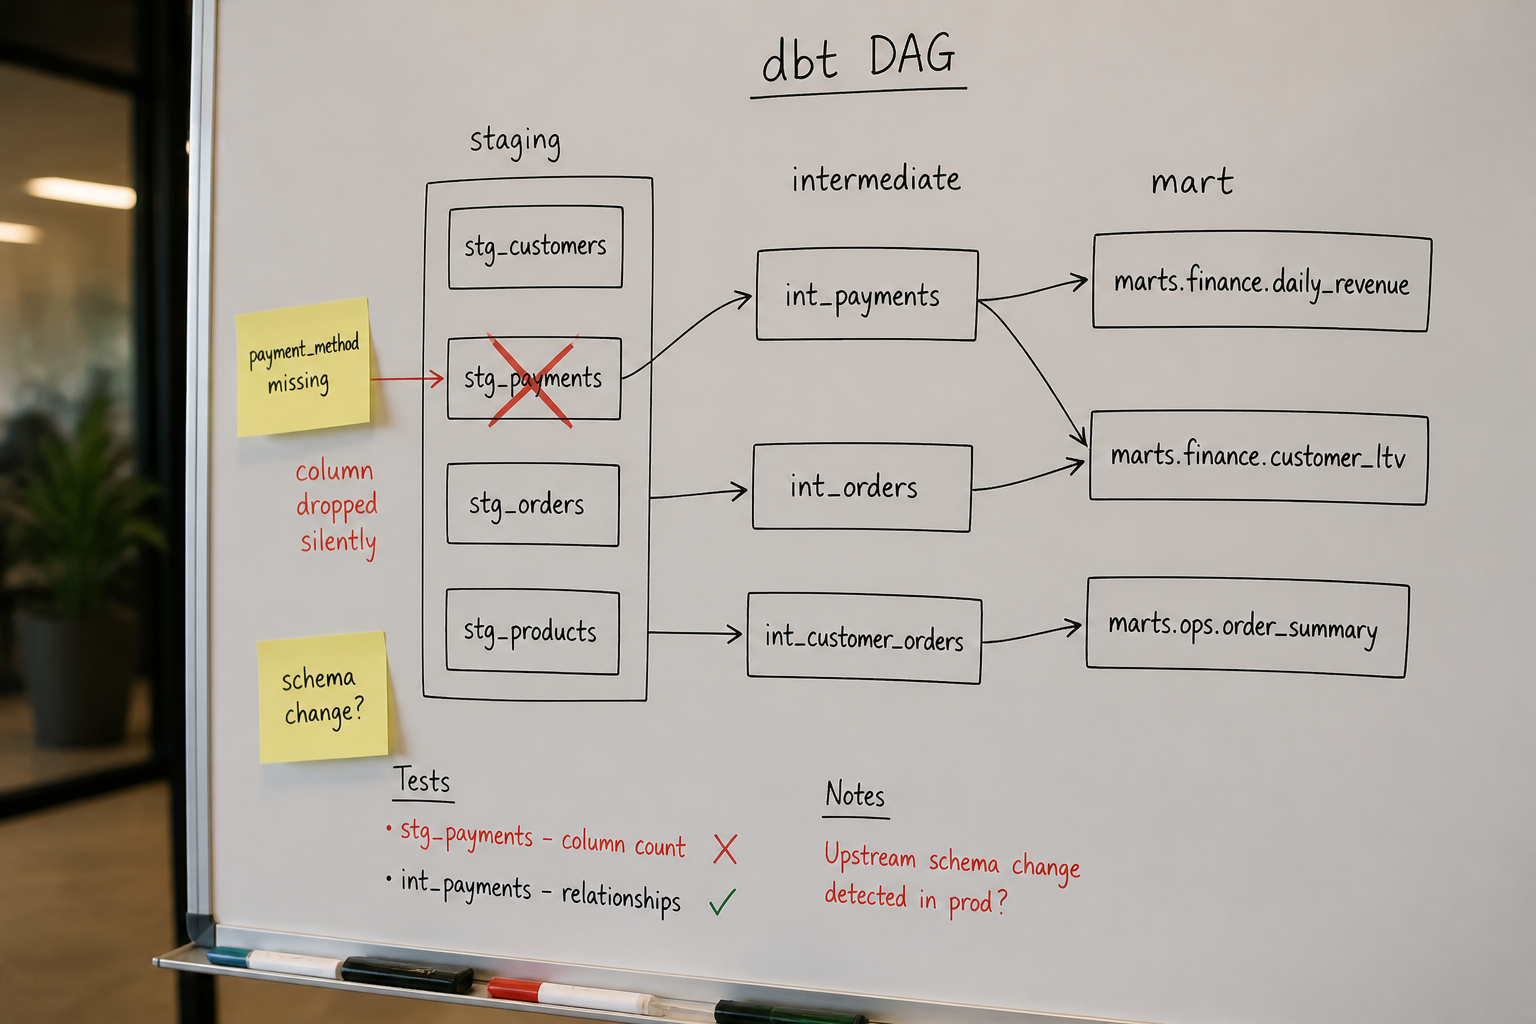
This is one of the most reliably misunderstood behaviours in dbt. It is not a bug — it is documented default behaviour. But in fast-moving organisations where upstream application teams push schema changes without notifying data engineering, it becomes a recurring production incident. A pattern we see repeatedly when onboarding clients: the dbt run history is clean, the tests are all green, and yet a critical field — payment_method, risk_score, account_tier — has been silently absent from the mart layer for weeks.
This post shows you how to detect it in BigQuery in under five minutes, how to fix it without a full refresh, and how to stop it recurring.
Why Schema Drift Kills dbt Pipelines Silently
Schema drift encompasses the unexpected, often undocumented structural changes originating from upstream source systems — the uncoordinated mutation of data structures that catches downstream consumers completely off-guard.
In practice it shows up in three ways inside a dbt project:
-
A new column appears upstream. The default behaviour of incremental models in dbt is
on_schema_change='ignore'. When the raw table has columns that your SELECT statement doesn't include, dbt ignores them — no error, no warning, just silent omission. The column never reaches your marts, your BI layer, or your analysts. -
A column is renamed or removed. SQL models or dbt projects that assume fixed fields will error out when types change or fields disappear — and changes in field names or types can lead to incorrect aggregations, null values, or dropped records.
-
A data type changes. A product team changes
user_statusfrom STRING to INTEGER with no notification to the data engineering team. The next morning, dbt models crash, dashboards go all red, and ML pipelines break — three hours to find the root cause.
The business cost is real. At the ingestion layer the impact is pipeline failures or silent truncation; at the analytics layer it produces misleading dashboards; and in ML pipelines it causes feature inconsistency and model degradation.
In one engagement with a Series A payments company, we traced a silent payment_method omission to a source schema change that had gone undetected for nineteen days. The field had been added to the upstream events table by the product engineering team as part of a new payment flow. Every model downstream of the staging layer had materialised without it. The fix took twenty minutes once found — but the detection took four hours of archaeology across dbt Cloud job logs and BigQuery audit logs. That archaeology is the thing this post eliminates.
📺 Watch: Deploy to custom schemas & override dbt defaults
How to Detect Schema Drift in BigQuery Right Now
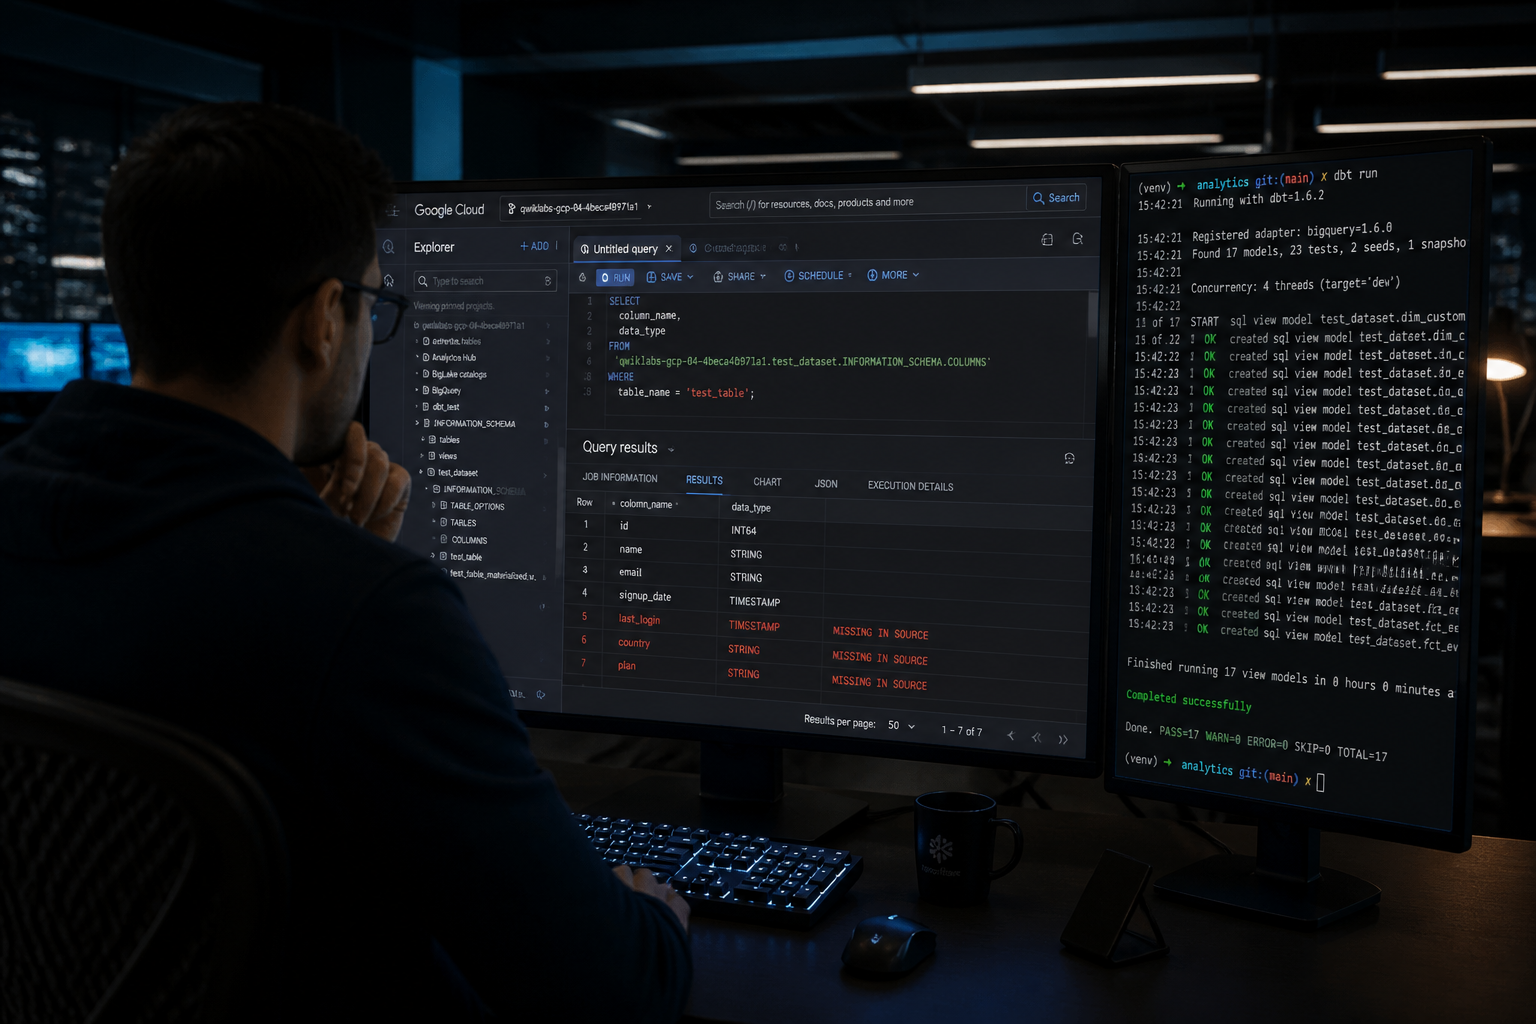
The goal is to compare what your dbt source is expected to contain against what BigQuery's INFORMATION_SCHEMA shows is actually there. You have two places to look.
Step 1 — Find columns in the source table that are missing from your dbt staging model
This query runs against BigQuery's INFORMATION_SCHEMA and shows you any column present in the raw source table that is absent from the corresponding dbt-produced staging table. Substitute your own project, dataset, and table names.
-- Run in BigQuery console or dbt Cloud IDE
-- Replace placeholders with your actual project/dataset/table names

WITH source_cols AS (
  SELECT column_name, data_type
  FROM `your_project.raw_dataset.INFORMATION_SCHEMA.COLUMNS`
  WHERE table_name = 'your_source_table'
),
staging_cols AS (
  SELECT column_name, data_type
  FROM `your_project.dbt_dataset.INFORMATION_SCHEMA.COLUMNS`
  WHERE table_name = 'stg_your_source_table'
)
SELECT
  s.column_name                  AS missing_in_staging,
  s.data_type                    AS source_data_type,
  'Column in source, absent in staging model' AS drift_type
FROM source_cols s
LEFT JOIN staging_cols m
  ON s.column_name = m.column_name
WHERE m.column_name IS NULL
ORDER BY s.column_name;
If this returns rows, you have source columns that have never been propagated through your dbt layer. Each row is a silent data loss event.
Step 2 — Find type mismatches between source and staging
A renamed or retyped column will not show as "missing" in the query above — it will appear in both tables but with different types. Run this to surface those:
WITH source_cols AS (
  SELECT column_name, data_type
  FROM `your_project.raw_dataset.INFORMATION_SCHEMA.COLUMNS`
  WHERE table_name = 'your_source_table'
),
staging_cols AS (
  SELECT column_name, data_type
  FROM `your_project.dbt_dataset.INFORMATION_SCHEMA.COLUMNS`
  WHERE table_name = 'stg_your_source_table'
)
SELECT
  s.column_name,
  s.data_type  AS source_type,
  m.data_type  AS staging_type
FROM source_cols s
JOIN staging_cols m
  ON s.column_name = m.column_name
WHERE s.data_type != m.data_type
ORDER BY s.column_name;
Any row here is a latent type-cast failure waiting to detonate somewhere downstream.
Step 3 — Check your dbt source freshness config is actually running
dbt has a built-in source freshness mechanism, but it only tells you whether new rows have arrived — not whether the schema has changed. Confirm your sources block in schema.yml has a loaded_at_field and a freshness block, then run:
dbt source freshness --select source:your_source_name
This is not a schema drift check, but it is the canary that tells you data has stopped flowing — often the first observable symptom before someone traces it back to a type error.
Running that query for one table is fine. Checking every model in a project is not — fintel-scan is a free open-source CLI that does this check and fourteen others locally, with no warehouse connection:
uvx fintel-scan. It is MIT-licensed and takes about thirty seconds to run across an entire project.
How to Fix Schema Drift Without Destroying Your Incremental Model
The first time you add a new column to an incremental model's SQL, dbt tries to insert rows with the new column into a table that doesn't have that column yet. The default behaviour (on_schema_change='ignore') silently drops the new column from the output. The behaviour when set to 'fail' errors the run. Neither is what you want in production.
The correct fix depends on what kind of drift you found.
Case 1: New column in source, you want it in your model
-
Add the column explicitly to your staging model's SELECT statement.
-
Set
on_schema_change='sync_all_columns'in the model config block. -
Run
dbt run --select stg_your_source_table --full-refresh— but only on the staging model, not the whole project.{{ config( materialized='incremental', on_schema_change='sync_all_columns' ) }}
Note that on_schema_change='sync_all_columns' only kicks in when your dbt model's SELECT statement includes the new column — if you haven't updated the model to select the new column, there's nothing for it to sync. The config change alone is not enough. You must also update the SELECT.
Case 2: Source column renamed or removed
This is the dangerous one. If schema drift hits a core object, many downstream models fail at once and reports are suddenly outdated. The remediation steps are:
- Identify every downstream model referencing the old column name using
dbt ls --select +stg_your_source_table+. - Update each model in dependency order (staging first, then intermediates, then marts).
- If the column is gone permanently, replace it with a
NULL AS column_namecast in staging to protect downstream models from a hard failure — this buys you time to clean up properly. - Add a dbt
not_nulltest to the staging model for any column that must never be absent. It will not prevent the drop, but it will fail the run loudly rather than silently.
Case 3: Data type change
Type mismatch errors occur when models cast columns into incompatible types. The goal is not just to avoid failures — it's to control and standardise schema evolution so business teams can trust the data.
Add an explicit CAST in your staging model rather than relying on implicit type coercion. Then add a dbt accepted_values or custom schema test to catch future type changes early.
How to Stop This Recurring: Enforce Schema Contracts
Detection and manual fixes are not a long-term answer. The right posture is to make schema drift a blocked pull request rather than a production incident.
Use dbt model contracts
With contract.enforced: true, dbt validates at compile time whether the model's output schema matches the YAML definition. If it doesn't, CI/CD fails and breaking changes can't reach production — turning schema changes from "surprises" into "controlled conversations."
Add this to your staging model's YAML:
models:
  - name: stg_your_source_table
    config:
      contract:
        enforced: true
    columns:
      - name: payment_method
        data_type: string
        constraints:
          - type: not_null
      - name: amount
        data_type: numeric
        constraints:
          - type: not_null
This is available in dbt Core 1.5+ and dbt Cloud. It is the single highest-leverage change you can make to a project that has had schema drift incidents.
Layer pre-build source validation
Most data pipelines fail silently when a source schema drifts. dbt tests run after the model — they catch the broken state, they do not prevent it from being written.
For pre-build validation, use Elementary's schema_changes test on your source nodes. It runs a diff against the last observed schema before the model executes — meaning a column drop triggers a failure before a single bad row lands in staging:
sources:
  - name: your_source_name
    tables:
      - name: your_source_table
        tests:
          - elementary.schema_changes
For dbt-native anomaly detection in 2026, Elementary adds Z-score based drift detection on a configurable historical window.
Add the INFORMATION_SCHEMA diff to your CI pipeline
The two SQL queries from the detection section above can be wrapped into a CI step — run them as part of a GitHub Actions job after each ingestion run and fail the pipeline if either returns rows. This costs almost nothing to implement and eliminates the four-hour archaeology sessions.
For a broader treatment of how event-driven source changes propagate into pipeline failures, see our post on Event-Driven Data Architecture for Fintech: Build It Right in 2026 — the same upstream volatility that causes schema drift also affects event ingestion architecture.
And if you are seeing silent failures surface downstream in your dashboards or alerting layer, Pipeline Incident Analytics: Stop Silent Data Failures in 2026 covers how to build observability that catches these issues before your stakeholders do.
Frequently Asked Questions
Q: What is dbt source schema drift and why is it dangerous?
A: Source schema drift occurs when an upstream source table changes its structure — adding, removing, or renaming columns, or changing data types — without the dbt project being updated to match. It is dangerous because dbt's default on_schema_change='ignore' setting means these changes propagate silently: models run successfully, tests pass, and no error is raised, but data is either missing from or corrupted in your mart layer.
Q: How do I detect schema drift in a BigQuery dbt project?
A: Query BigQuery's INFORMATION_SCHEMA.COLUMNS for both your raw source table and the corresponding dbt staging table, then LEFT JOIN on column_name to find columns present in the source but absent in the staging model. A second query joining on column_name and comparing data_type will surface type mismatches. Both queries are runnable in the BigQuery console or dbt Cloud IDE in under two minutes.
Q: What does on_schema_change='ignore' actually do in dbt?
A: It tells dbt to make no changes to the target table schema when it detects that the SELECT statement in your incremental model differs from the existing materialised table. New columns in the source that you have added to your SELECT will be silently dropped from the output. This is the default in dbt Core and dbt Cloud as of 2026.
Q: Should I use on_schema_change='sync_all_columns' or model contracts?
A: Use both, for different purposes. sync_all_columns is a runtime safety net — it will ALTER the target table if your SELECT adds a new column. Model contracts are a compile-time gate — they prevent a model from being built at all if the declared schema does not match the output. Contracts are the stronger control; sync_all_columns handles legitimate schema evolution gracefully once a contract change has been reviewed and merged.
Q: How do I find all dbt models affected by a source schema change?
A: Run dbt ls --select +stg_your_source_table+ in your terminal. The + prefixes and suffixes instruct dbt to return all ancestors and descendants of that model in the DAG — giving you the complete blast radius of a source change before you touch a single file.
Silent schema drift is one of the most corrosive problems in a dbt project — not because it is technically complex, but because it destroys trust in your data without ever raising its hand. At Fintel Analytics, we have audited and remediated this exact class of failure across dbt projects in fintech, payments, and e-commerce — usually finding it within the first hour of a project health check, and always finding something downstream that had been quietly wrong for longer than anyone realised. If your team is running incremental models without enforced contracts or pre-build schema validation, the diagnostic queries in this post will tell you what you need to know — and if the findings are larger than a quick fix, we are a message away.