
Pipeline incident analytics is the practice of instrumenting, recording, and analysing the failure modes of your data pipelines so you can detect bad data before it reaches dashboards, models, or business decisions. Done properly, it transforms your data stack from a system that breaks silently into one that surfaces problems within minutes of occurrence — and tells you exactly where to look.
Most early-stage companies discover their pipeline has a problem when a founder asks why Monday's revenue number looks odd, or when a head of finance notices that the weekly report doesn't reconcile with the bank. By that point, bad data has often been sitting in production dashboards for hours or days. Stakeholders have made decisions on it. Trust in the entire data stack starts to erode — and once that happens, it is very hard to rebuild.
This is not an abstract risk. When a data pipeline silently fails or feeds wrong information into dashboards, analytics initiatives grind to a halt — and poor data quality costs the average enterprise approximately $15 million per year. For a Series A company running lean, the cost is less about the headline figure and more about the decisions made on bad numbers: the channel budget allocated based on corrupted attribution data, the lending decision made on a miscalculated risk score, the board pack presented with a revenue metric nobody can reproduce.
The fix is not simply "add more tests." It is building an analytics layer around your pipeline incidents themselves — capturing them, classifying them, measuring their frequency and blast radius, and using that data to prioritise where your engineering effort goes next.
Why Do Data Pipelines Fail Silently?
The worst pipeline failures are not the ones that crash loudly. A crashed Airflow DAG at least sends an alert. The truly dangerous failures are the ones where the pipeline runs, the job completes, the status light stays green — and the data is still wrong.
The worst data failures do not happen when pipelines go down due to significant crashes. They occur because of silent issues: a supplier changes their API response schema overnight without updating downstream contracts; a third-party tool starts producing null values for customer ID fields in certain geographies; a slight numerical distribution shift breaks an ML model for price prediction.
In our work with early-stage fintech and payments companies, we see four failure patterns repeat with striking regularity:
Schema drift without contracts. An upstream API or SaaS tool changes a field name or type. Your ingestion layer accepts it without complaint. Three transformations downstream, a join breaks silently and starts producing nulls. By the time this surfaces, the corrupted data has populated a week of dashboard history.
Referential integrity breaks. A new record type gets introduced in a source system. Your staging models don't handle it, so those rows are silently dropped. Your transaction count is now understated by a percentage nobody has noticed.
Volume anomalies. A feed that normally delivers 50,000 rows delivers 500. Nothing breaks — the pipeline completes. But every downstream aggregate is now built on 1% of the expected data.
Duplicate injection. An at-least-once delivery guarantee in a webhook or event stream produces duplicate events. Without deduplication logic and a uniqueness test, your revenue metrics are overstated every time a retry occurs.
According to an analysis of over 1,000 data pipelines in 2024, technical teams spend nearly half their working time resolving issues rather than building solutions. The reason is almost always the same: failures are discovered reactively, traced manually, and fixed in isolation — with no systematic record of what broke, how often, or what the downstream impact was.
📺 Watch: OPALUTION: Solution for Oil Pipeline Accidents based on the analysis of the accident dataset
What Does a Pipeline Incident Analytics Layer Actually Look Like?
Building pipeline incident analytics means treating your pipeline's failure history as a first-class dataset — one you model, query, and build dashboards on, just like any other operational data.
At its simplest, this means capturing the following for every pipeline run:
- Run metadata: pipeline name, run timestamp, duration, row count in vs. row count out, status
- Test results: every dbt test or Great Expectations check, pass/fail, number of failing rows, affected model
- Anomaly signals: volume deviation vs. 7-day rolling average, null rate vs. baseline, schema change detected (yes/no)
- Incident classification: when a failure is detected, was it a schema issue, a volume issue, a referential integrity issue, or a data value issue?
- Blast radius estimate: which downstream models and dashboards depend on the failing model?
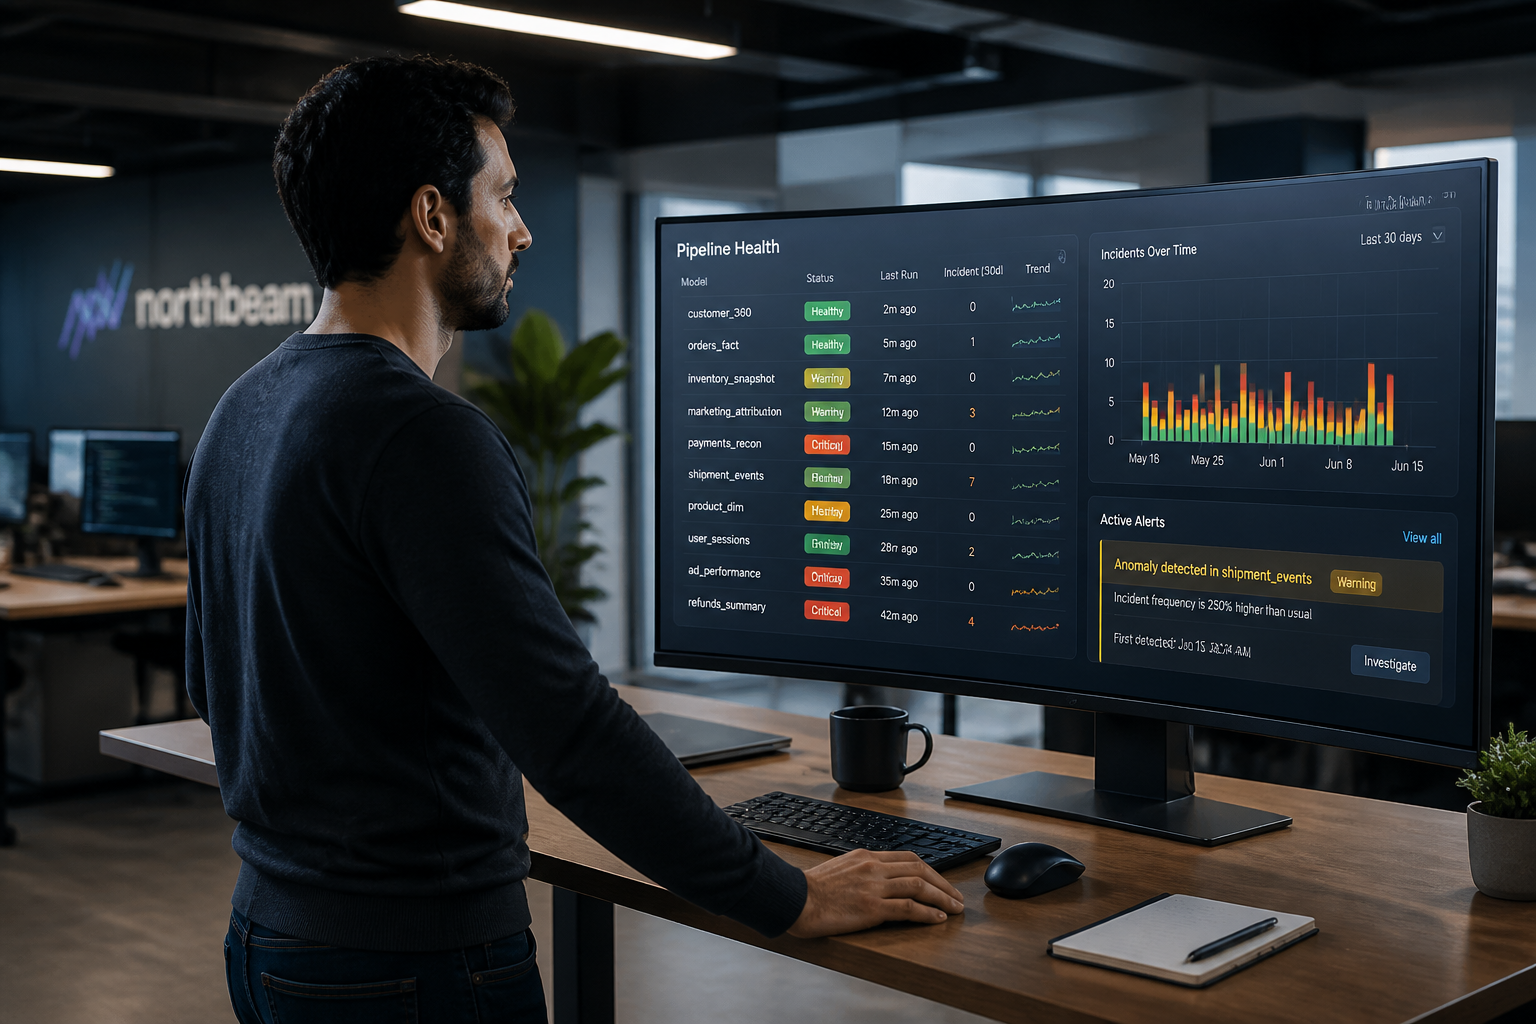
Once this data is being captured — in BigQuery or your warehouse of choice — you can build a pipeline health dashboard that gives your data team (or your on-call engineer) genuine operational visibility. Not just "did the job run?", but "did the job produce trustworthy output?"
A pattern we see repeatedly in companies that have crossed the 50-person mark: they have invested in orchestration (Airflow, Prefect, or similar) and have dbt tests in place, but nobody has ever modelled the test result history. Every test run overwrites the last. There is no trend data, no frequency analysis, no way to ask "which model has failed the most times in the last 30 days?" or "which source system is our biggest reliability risk?"
This is the gap that pipeline incident analytics closes.
How to Build Pipeline Incident Analytics in dbt and BigQuery
If your stack is dbt plus BigQuery (or any warehouse), you can implement the foundation of this in a few days of focused engineering effort. Here is the approach we use with clients.
Step 1: Persist dbt test results.
dbt's store_failures configuration causes failing rows to be written to your warehouse rather than just logged to the console. Enable this at the project level and you immediately have a queryable record of every test failure, with the specific rows that failed. Combine this with dbt's metadata artifacts (run_results.json) and you have a structured log of every test run, its pass/fail status, and its execution time.
Pipe these artifacts into your warehouse on every CI/CD run. A simple Cloud Function or Lambda triggered on dbt job completion can handle this. Now you have an incident_log table that grows with every pipeline execution.
Step 2: Model your incident history.
Build a set of dbt models on top of your incident log:
-- models/monitoring/fct_pipeline_incidents.sql
SELECT
  run_id,
  model_name,
  test_name,
  failure_count,
  run_timestamp,
  DATE_DIFF(CURRENT_DATE(), DATE(run_timestamp), DAY) AS days_ago
FROM {{ ref('stg_dbt_run_results') }}
WHERE status = 'fail'
From this foundation, you can build:
- A
dim_model_reliabilitymodel that tracks pass rate per model over rolling windows - A
fct_blast_radiusmodel that joins your incident log to your dbt DAG lineage to show which downstream assets are at risk when a given model fails - An
int_volume_anomaliesmodel that compares row counts to rolling averages and flags deviations beyond a defined threshold
Step 3: Build the operational dashboard.
In Holistics BI, Looker, or your BI layer of choice, surface this data as a Pipeline Health dashboard. The key views are:
- Reliability leaderboard: which models have the worst pass rates over the last 30 days?
- Incident timeline: when did failures cluster? Are there patterns around certain source systems or ingestion windows?
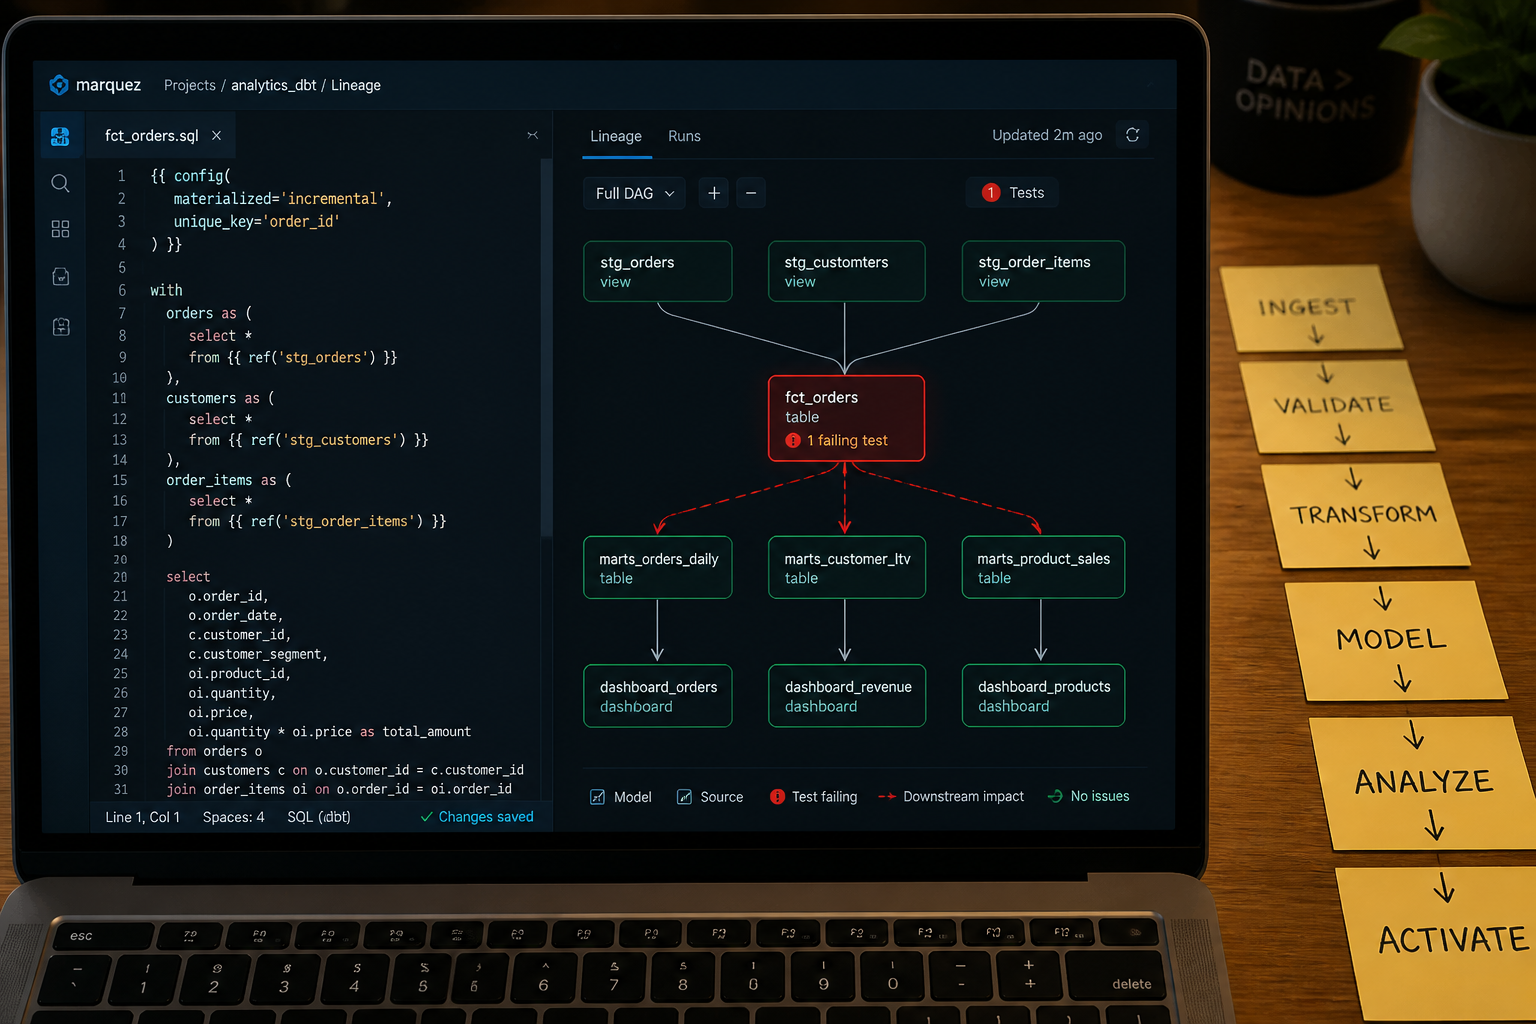
- Blast radius map: for any given failing model, which dashboards or downstream reports are affected?
- Volume trend chart: for high-stakes feeds, what is the row-count trend, and when did it last diverge from expectation?
This dashboard becomes your on-call tool. When something breaks — or when a stakeholder reports a suspicious number — you open it first, not your orchestrator's log output.
If you are looking to implement this kind of infrastructure in your organisation, explore how Fintel Analytics approaches data reliability and pipeline engineering — we work with growth-stage businesses globally to design and deliver exactly this kind of solution.
What Gets Measured Gets Fixed: Using Incident Data to Prioritise Engineering Work
The second-order value of pipeline incident analytics is not in catching the immediate failure — it is in the prioritisation intelligence it gives you over time.
Once you have three to six months of incident history, you can answer questions that most data teams cannot: which source system is responsible for the most downstream disruption? Which transformation model fails most often under load? Which tests are genuinely signal versus noisy false positives that engineers have started ignoring?
A pattern we see repeatedly in our work with early-stage companies: teams write 200 dbt tests and then, after three months of alert fatigue, stop paying attention to them. The tests still run. The failures still occur. But nobody acts because the signal-to-noise ratio has degraded.
Pipeline incident analytics gives you the data to fix this. You can identify which tests have a >30-day streak of failures that nobody has resolved (systematic data quality issue upstream — needs investigation at source, not a suppression rule). You can identify which tests fire once every 90 days (probably a genuine edge case worth keeping). You can identify which tests have never failed in 12 months (consider whether they are actually testing anything meaningful, or whether the threshold is set too loosely).
This is the discipline of data reliability engineering — treating your pipeline's operational behaviour as something you measure, analyse, and improve continuously, not just react to when a stakeholder complains.
In our delivery work, one outcome we encounter consistently: once a capital or revenue reconciliation process gets instrumented at this level, incidents that were previously "discovered" two or three days after occurrence start getting caught within minutes. In one engagement with a global fintech, rebuilding a reconciliation process as an automated SQL pipeline with embedded volume and integrity checks reduced the detection-to-resolution time from multi-day manual investigation to under 15 minutes — and the reconciliation itself dropped from 30–50 minutes of manual effort to under three seconds.
For companies operating at any meaningful transaction volume, the difference between a 3-day and a 15-minute detection window is not trivial. According to the DORA 2024 report, low-performing teams have change failure rates of up to 40%, compared to less than 5% in elite teams — and the primary differentiator is not the sophistication of their stack, but the speed and quality of their feedback loops.
How Do You Know When Your Incident Analytics Is Actually Working?
This is the question most implementation guides skip. You can build a beautiful pipeline health dashboard and still have the same underlying reliability problems — if you are not acting on what it shows.
Three metrics tell you whether your pipeline incident analytics is delivering value:
Mean time to detect (MTTD). How long between a failure occurring and your team knowing about it? If the answer is still "when a stakeholder complains", your monitoring is not working. Target: under 30 minutes for any model feeding an executive or operational dashboard.
Incident recurrence rate. What percentage of incidents in the last quarter were repeat failures on the same model? High recurrence means you are firefighting rather than fixing root causes. Target: below 20% repeat incidents after a first-occurrence fix.
Test coverage of critical paths. What percentage of the models feeding your most important dashboards have at least one volume test, one not-null test, and one uniqueness test? This is your minimum viable testing baseline. Track it as a metric, not a one-off audit.
In 2026, an effective data quality testing strategy embeds automated validation natively into pipelines, runs checks on every CI/CD pipeline commit, applies AI-assisted anomaly detection to catch schema drift and volume anomalies before production, and uses metadata-driven lineage to trace any quality failure to its upstream source within minutes.
That last point — lineage-aware incident routing — is where the more mature implementations go. When your incident log is joined to your dbt lineage graph, you can automatically surface not just "model X failed" but "model X failed, and it feeds dashboards Y and Z, which are used by your head of finance and your head of operations." That context is what turns an alert into a prioritised action.
For teams that have invested in an event-driven data architecture, this kind of lineage-aware alerting integrates naturally with the event stream — failures in the pipeline emit events that trigger downstream notifications, Slack alerts, or even automatic rollback logic.
Frequently Asked Questions
Q: What is pipeline incident analytics?
A: Pipeline incident analytics is the practice of capturing, modelling, and analysing the failure history of your data pipelines — including test failures, volume anomalies, schema changes, and integrity breaks — so you can detect bad data before it reaches dashboards and build a systematic picture of where your pipeline reliability risks actually lie.
Q: How is pipeline incident analytics different from data observability?
A: Data observability is the broader capability of understanding the health of your data across its full lifecycle. Pipeline incident analytics is more specific: it focuses on using the structured record of pipeline failures as an analytical dataset in its own right — modelling incident frequency, blast radius, and recurrence to drive engineering prioritisation decisions, not just real-time alerting.
Q: What tools do you need to build pipeline incident analytics?
A: The core tooling is your existing dbt setup (with store_failures enabled), your cloud data warehouse (BigQuery, Snowflake, or Redshift), and a BI layer to visualise the results (Holistics, Looker, or similar). You do not need a dedicated observability platform to get started — most of the value comes from modelling the data you already have in dbt artifacts and warehouse logs.
Q: How long does it take to build a pipeline incident analytics layer?
A: A functional MVP — incident log ingestion, three to four dbt monitoring models, and a pipeline health dashboard — typically takes three to five engineering days to build if your dbt project and warehouse are already in place. The more significant investment is in discipline: ensuring the artifacts are persisted on every run and that the dashboard is reviewed as part of a regular operational cadence.
Q: What is the biggest mistake teams make with data pipeline monitoring?
A: Writing many tests but not persisting or analysing the results over time. Most teams check whether tests pass or fail in the moment but never build a historical model of which tests fail most often, which sources are least reliable, or which failures have gone unresolved for weeks. This leaves them reacting to incidents rather than systematically eliminating their root causes.
At Fintel Analytics, we have helped fintech, payments, and e-commerce businesses go from reactive firefighting to genuine pipeline reliability — building the monitoring layers, dbt testing frameworks, and operational dashboards that give data and engineering teams the visibility they need to catch bad data in minutes, not days. If your team is still finding out about pipeline failures from a Slack message from a stakeholder who noticed something odd in a report, that is a solvable problem — and solving it pays for itself the first time it prevents a bad decision from reaching your board.