
When Should You Use dbt Incremental Models? (The Short Answer)
Use dbt incremental models whenever your table grows faster than you can afford to rebuild it, and when the data in that table is either append-only or has a reliable updated-at timestamp. In practice, that means most fact tables at Series A scale and beyond. The mistake teams make is not switching to incremental models too early — it is switching to them incorrectly, then spending weeks debugging silent data quality issues that are far more expensive than the compute they were trying to save.
If you have landed on this page because your BigQuery bill tripled last quarter and your dbt runs are timing out, you are not alone. This is one of the most consistent patterns we see in growth-stage companies: a stack that was perfectly efficient at a few million rows becomes a slow, expensive liability at a few hundred million. The good news is that it is a solvable problem — but the fix requires a clear framework, not just a configuration change.
Why Full Table Rebuilds Break Down at Scale
When you first build a dbt project, every model defaults to table materialisation. dbt drops and recreates the table on every run. For small datasets this is fine — simple, predictable, no edge cases. Then your transaction volume grows.
The cost mechanics are unforgiving. BigQuery charges by data processed under on-demand pricing, and a full rebuild scans the entire source table every time. If your source table has 500 million rows and only 100,000 changed since the last run, you are doing 5,000 times more work than necessary on every pipeline execution. Run that model hourly — as many operational pipelines need to — and the numbers compound fast.
A team at a growth-stage fintech we worked with had a core transactions model that was being rebuilt from scratch on an hourly schedule. At under 50 million rows it was tolerable. By the time they hit 400 million rows, that single model was scanning over 2 TB per run. Under BigQuery's on-demand pricing model, this kind of workload can rack up thousands of dollars per month from a single poorly configured model — before you account for the other forty models in the same DAG.
The cumulative effect is the billing shock that founders and CTOs tend to notice only at quarter-end, when the cloud cost line has quietly tripled. By that point, the pipeline architecture has usually become harder to untangle, because downstream models and dashboards have been built on top of a materialisation strategy that was never designed for the volume it is now serving.
Industry analysis published in 2026 confirms what we see in delivery: shifting to incremental models can slash compute consumption by 80% to 95% compared to full rebuilds. That is not a marginal gain — it is a structural change in how your transformation layer consumes resources.
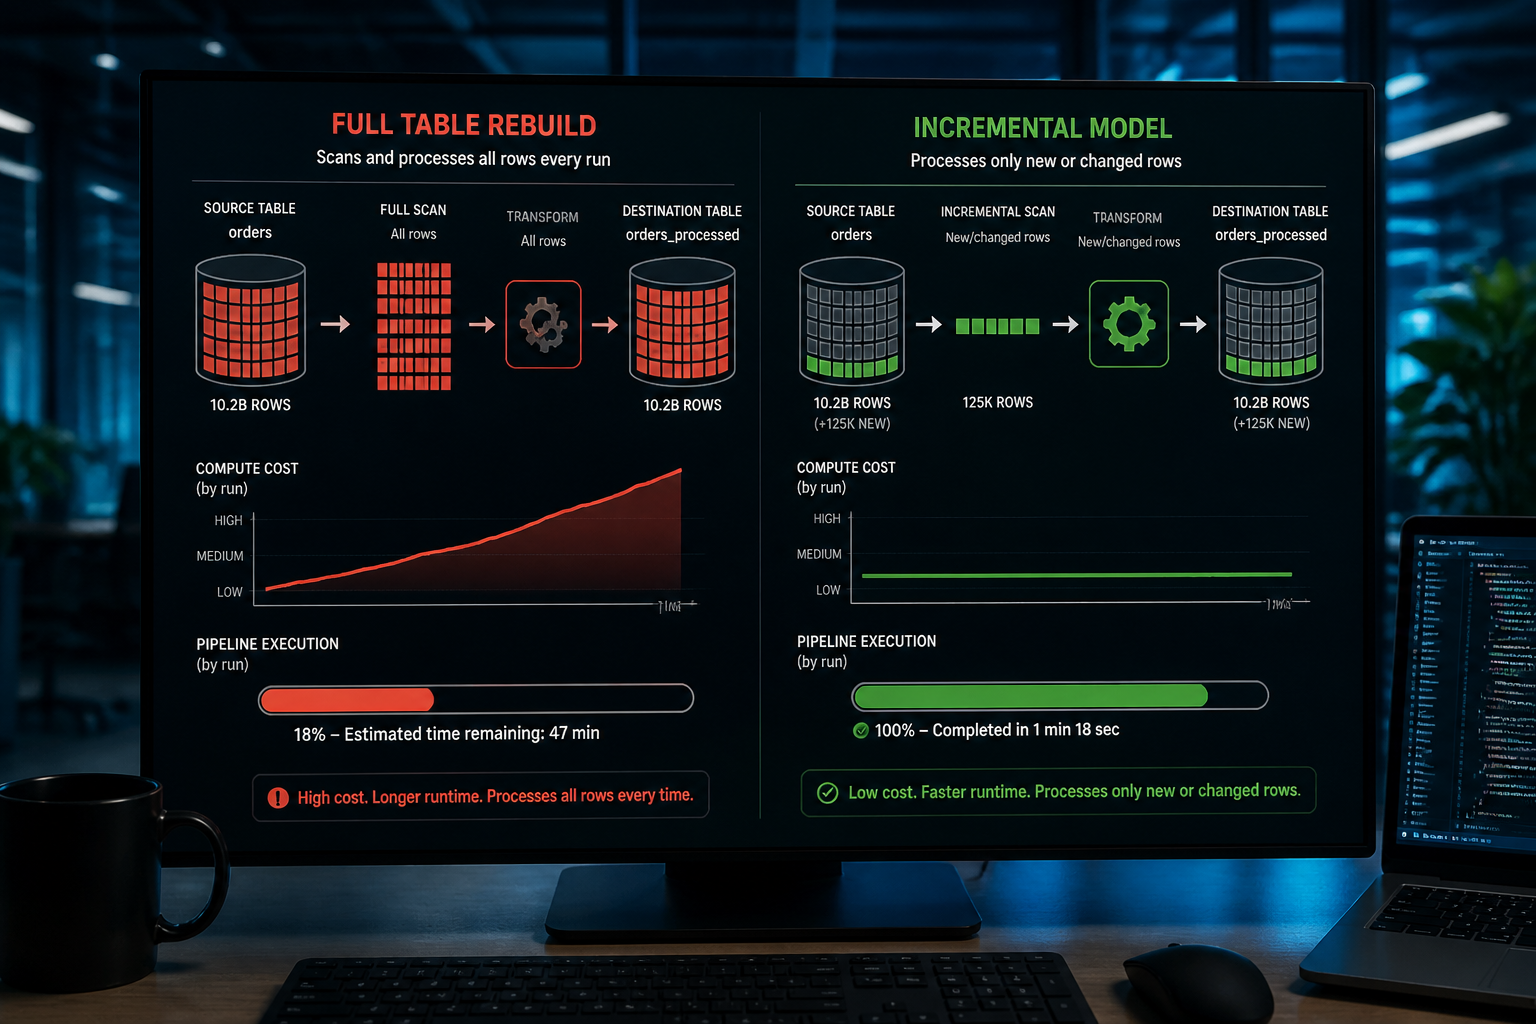
📺 Watch: How to Build Incremental Models | dbt tutorial

The dbt Incremental Strategy Decision Framework
Not every model should be incremental. Getting this wrong in the other direction — over-indexing on incremental materialisation for models that genuinely need full rebuilds — introduces data correctness risks that are harder to detect and far more damaging than an oversize cloud bill.
Here is the decision framework we apply when auditing a client's dbt project:
Step 1 — Ask: Does the data change, or just grow?
If rows are only ever inserted (event logs, transaction records, API call logs, webhook payloads), you have an append-only pattern. This is the cleanest case for incremental models — use the append strategy and filter on a reliable inserted_at or event_timestamp column.
If rows can be updated after insertion (order status fields, customer profile data, subscription state), you need to handle updates. This is where teams go wrong: they apply append strategy to mutable data, silently lose updates, and only discover it weeks later when a metric looks wrong and nobody can explain why.
Step 2 — Ask: Do you have a reliable high-watermark column?
Incremental models depend on being able to identify "what has changed since the last run." That requires a column — typically updated_at, created_at, or an event sequence ID — that you can trust. If your source system does not populate this field consistently, or if third-party data arrives with unreliable timestamps, incremental models will silently miss records. This is a data quality problem that needs fixing at the source layer before you apply incremental materialisation downstream.
Step 3 — Choose the right strategy for your BigQuery environment
dbt supports three incremental strategies on BigQuery: insert_overwrite, merge, and append. Each has different cost and correctness profiles:
append: Cheapest and simplest. Only suitable for truly immutable event streams. No deduplication, no update handling.insert_overwrite: Overwrites specific partitions rather than the full table. Ideal for date-partitioned tables where late-arriving data lands within a predictable window (e.g., the last 3 days). More forgiving thanappendon correctness, more efficient thanmergeon cost.merge: Handles both inserts and updates correctly using a unique key. The default MERGE statement scans the entire destination table to find matching rows — which is slow and costly on large partitioned tables unless you addincremental_predicatesto constrain the scan to recent partitions.
Step 4 — Add a lookback window for late-arriving data
One of the most common failure modes in incremental models is late-arriving data. Your pipeline runs at midnight. A payment processor delivers events with a 6-hour lag. Those records arrive after your model has already set its high-watermark and will never be processed unless you explicitly handle them.
The standard fix is a lookback window: extend your WHERE filter to reprocess the last 24–72 hours on every run. This adds a small amount of compute overhead but prevents the kind of silent gap that erodes trust in your metrics. Pair this with a scheduled full refresh (weekly or monthly, depending on your data volume) to catch anything the lookback missed.
Step 5 — Know when a full refresh is the right answer
Some models should never be incremental: dimension tables with complex SCD logic, models that aggregate across the full historical dataset, or any model where the transformation logic has changed and you need to backfill. dbt's --full-refresh flag exists for exactly this reason. The discipline is knowing which models belong in which category and documenting that decision in your project.
If you are thinking through how this applies to your current stack, explore how Fintel Analytics approaches data engineering and transformation layer design — we work with growth-stage businesses globally to design and deliver exactly this kind of solution, from initial audit through to production deployment.
The Hidden Cost of Getting Incremental Models Wrong
Most articles about dbt incremental models focus on the cost savings. Fewer talk honestly about the ways incremental models silently corrupt data — and why that outcome is worse than the compute bill you were trying to reduce.
A pattern we see repeatedly: a team switches a high-volume fact table from table to incremental materialisation, sees their BigQuery costs fall immediately, and considers the problem solved. Six weeks later, a finance analyst notices that their transaction count for a particular month is lower than it should be. An investigation reveals that records updated by the source system (status corrections, refund postings, delayed settlements) were never reprocessed after the incremental switch. The model appended new rows correctly but missed every update to existing rows.
The data was wrong for six weeks before anyone noticed. By that point, reports had been sent to investors. Decisions had been made.
The fix here is not complex — it is a strategy choice and a unique key — but it requires someone to have asked the right question before making the configuration change, not after.
Another failure mode we encounter regularly is the merge strategy without incremental_predicates. By default, the MERGE statement scans the entire destination table to find matching rows. On a large partitioned table, this effectively turns your incremental model into a full table scan in disguise — you get the operational complexity of incremental models without the cost benefit. Adding incremental_predicates to constrain the MERGE to recent partitions is the fix, but most teams only discover this when they run a cost attribution report and find that their "optimised" incremental model is still scanning terabytes.
This connects to a broader principle in data engineering: optimisation without monitoring is a one-time fix that decays. Once you have implemented incremental models, you need query cost labelling, partition filter enforcement on large tables, and scheduled audits of your most expensive jobs — otherwise the savings erode silently as data volumes grow and new models get added without the same rigour.
For teams dealing with upstream schema instability — where source systems change column types or drop fields without warning — incremental models introduce an additional failure surface. A schema change at the source that goes undetected will cause your incremental model to silently diverge from reality. This is why schema drift detection is not optional once you commit to incremental materialisation at scale. If this is a risk in your stack, our post on dbt source schema drift covers exactly how to detect and respond to it before it reaches production.
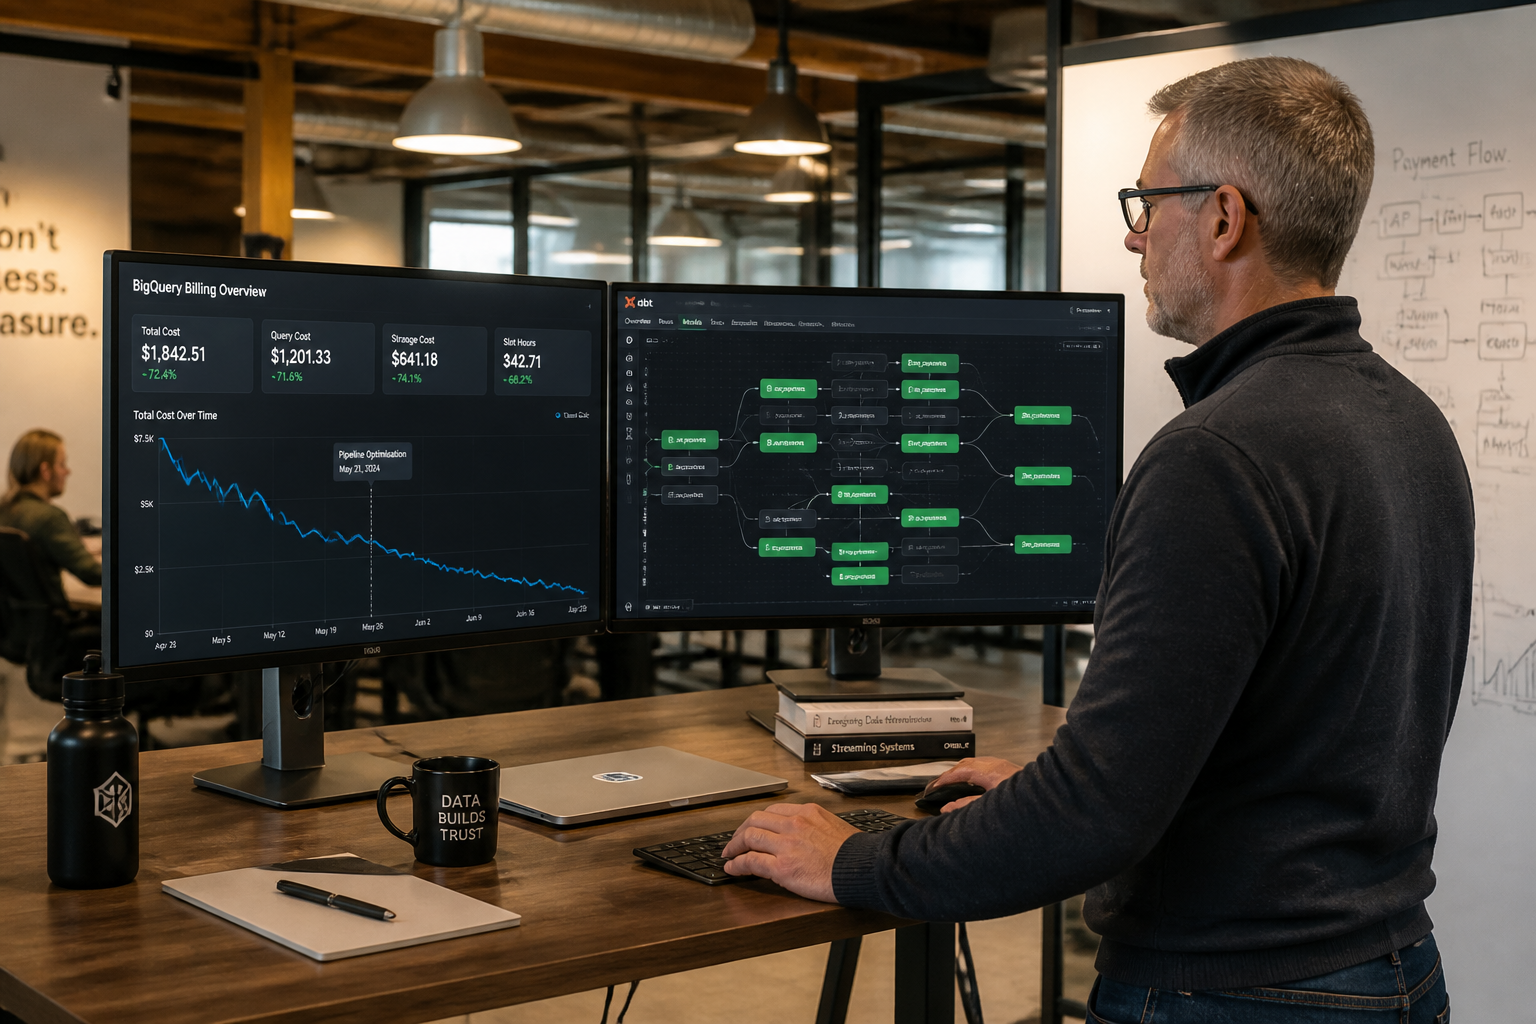
Partitioning, Clustering, and the Full Configuration Picture
Incremental strategy selection is only one part of the configuration. The other two — partitioning and clustering — determine whether your incremental model actually scans less data or just pretends to.
Partitioning splits your BigQuery table into segments based on a date or timestamp column. When your incremental model filters on that column, BigQuery scans only the relevant partitions rather than the full table. Without partitioning, even a well-written WHERE created_at >= last_run_timestamp clause may still trigger a full table scan depending on how the query planner handles it.
Clustering controls how data is physically ordered within each partition. Adding clustering on columns like user_id, merchant_id, or event_type — columns that frequently appear in your WHERE and JOIN clauses — allows BigQuery to skip irrelevant data blocks within a partition. Clustering does not reduce the bytes billed on the first scan of a partition, but it significantly reduces compute on repeated filtered queries against the same partitioned data.
In practice, the right configuration for a high-volume fact table on BigQuery looks like this:
- Partition on the event or transaction date column
- Cluster on your most-queried filter columns (2–4 columns maximum)
- Use
insert_overwriteormergewithincremental_predicatesreferencing the partition column - Add a
require_partition_filterconstraint on tables large enough that an accidental full scan would be materially expensive - Enforce a lookback window of 24–72 hours to handle late-arriving data
- Schedule a monthly
--full-refreshto close any gaps
When this configuration is in place, the cost profile changes dramatically. What was a 2 TB scan on every hourly run can reduce to scanning a few gigabytes — the most recent partition only. The model runs faster, the bill falls, and the data remains correct.
For teams operating at the point where transformation layer costs are material — typically somewhere between $3,000 and $10,000 per month in BigQuery spend — the investment in getting this configuration right pays back within a single billing cycle.
Frequently Asked Questions
Q: When should I switch from table to incremental materialisation in dbt?
A: Switch when your table rebuild time is materially impacting pipeline run time, or when you are paying for full table scans on data that is mostly unchanged. A practical threshold: if a model processes more than 10 GB per run and fewer than 10% of rows change between runs, it is a strong candidate for incremental materialisation. Always validate that you have a reliable high-watermark column before making the switch.
Q: What is the difference between dbt incremental strategies: append, merge, and insert_overwrite?
A: append adds new rows only — cheapest but only safe for immutable event data. merge handles both inserts and updates using a unique key — correct for mutable data but can trigger full table scans without incremental_predicates. insert_overwrite replaces full partitions — a good middle ground for date-partitioned tables where late data arrives within a known window. Choose based on whether your source data is mutable, not based on cost alone.
Q: How do I handle late-arriving data in a dbt incremental model?
A: Add a lookback window to your incremental filter — typically 24 to 72 hours depending on your source system's delivery lag. This reprocesses the most recent partitions on every run, catching late arrivals at a small additional compute cost. Pair this with a periodic full refresh (weekly or monthly) to close any gaps that fall outside the lookback window.
Q: Can dbt incremental models cause data quality issues?
A: Yes — and this is the risk most teams underestimate. Using append strategy on mutable data silently misses updates to existing rows. Using merge without incremental_predicates on large tables negates the cost benefit. Changing transformation logic without running --full-refresh leaves stale data in the table. Incremental models require more deliberate configuration and ongoing monitoring than full-refresh models — treat them as a production engineering decision, not a quick configuration tweak.
Q: How much can dbt incremental models reduce BigQuery costs?
A: Based on documented outcomes and published analysis from 2025–2026, shifting from full table rebuilds to correctly configured incremental models can reduce compute consumption by 80% to 95% on high-volume datasets. Real-world examples include companies reducing daily warehouse usage by 70% while also cutting data latency. The actual saving depends on your data volume, run frequency, and how well your partitioning and clustering are configured.
The Decision Is Not Just Technical — It Is Operational
Getting dbt incremental models right is not primarily a syntax problem. It is an architectural decision that determines whether your transformation layer scales cost-efficiently, and a data quality decision that determines whether the outputs of that layer can be trusted. At Fintel Analytics, we have helped fintech companies, payments businesses, and e-commerce platforms audit and rebuild their dbt transformation layers — replacing expensive full-rebuild patterns with correctly configured incremental models that maintain data correctness under real production conditions. If your BigQuery bill is growing faster than your revenue, or your pipeline runs are becoming a bottleneck, that is a solvable problem and the fix pays for itself within weeks.