
The Short Answer
To find dbt models with no test coverage, query dbt ls with the --select flag and cross-reference your project's manifest.json against the nodes that have zero associated tests. In BigQuery environments, you can also cross-reference INFORMATION_SCHEMA.TABLES against the sources and nodes sections of manifest.json to surface every materialised model that has never been validated. If you are running a project of any meaningful size and have not done this audit, the results are almost always worse than you expect.
Here is a scenario that comes up more often than it should: a Series A fintech has been running dbt for eight months. The project looks healthy — there are 60-odd models, a CI job that runs on every PR, and Slack alerts wired up for pipeline failures. Someone in finance raises a question about a number in the weekly revenue dashboard. The analytics engineer pulls the query, traces it back through three models, and discovers that the final mart model — fct_revenue — has exactly zero tests on it. Not not_null. Not unique. Nothing. It has been shipping to production, untouched by any validation, since the day it was created.
This is not a story about carelessness. It is a story about what happens when projects grow faster than the habits that should govern them. A test gets skipped once because of deadline pressure, a model gets copied from a template without the YAML block, a new column gets added to a mart and no one thinks to add assertions for it. Slowly, the project accumulates a class of silent risk: models that are materialised, trusted, and completely unvalidated.
57% of data teams say data quality is their biggest problem, according to dbt's 2024 State of Analytics Engineering survey. In our work with early-stage companies, the pattern is consistent: by the time a team reaches 40–60 models in a dbt project, at least a third of them have either no tests or only a single not_null on the primary key — which is the minimum viable check, not meaningful coverage.
This post gives you the exact commands and SQL to find every untested model in your BigQuery project right now, and a lightweight process to stop new gaps appearing.
Why Untested dbt Models Are Worse Than No Tests at All
An untested model creates a specific kind of risk that is harder to manage than a broken pipeline. A broken pipeline is visible — it fails, it pages someone, it gets fixed. An untested model that produces wrong output fails silently. The data lands in your mart, it looks plausible, and it gets used.
Accidental logic errors — missing join conditions, fan-out from many-to-many relationships, duplicate keys — happen when a JOIN between two or more tables is missing the condition that tells the database how rows should match. Without that condition, the database pairs every row from one table with every row from the other, creating a result set that explodes in size. A query that should return a few dozen rows can suddenly return millions. Without a unique test on the grain of the mart, that explosion is completely invisible until someone notices the revenue figure is three times last month's — or until a $25M reconciliation gap surfaces, which is exactly what happened with one of our clients.
In that case — a capital reconciliation project for a global payments company — a discrepancy that had gone undetected for months was only found when we rebuilt the transformation layer with proper test coverage. The gap was costing over $6,000 per day at market borrowing rates. The missing test was not the root cause, but it was the reason the error was never caught.
Think of dbt tests as unit tests for your data. Just like software engineers write tests to catch bugs before deployment, data engineers write dbt tests to catch data quality issues before they reach production dashboards. The analogy is exact. A software engineer who ships code with no unit tests would not last long. The same standard should apply to data models that feed executive dashboards and financial reports.
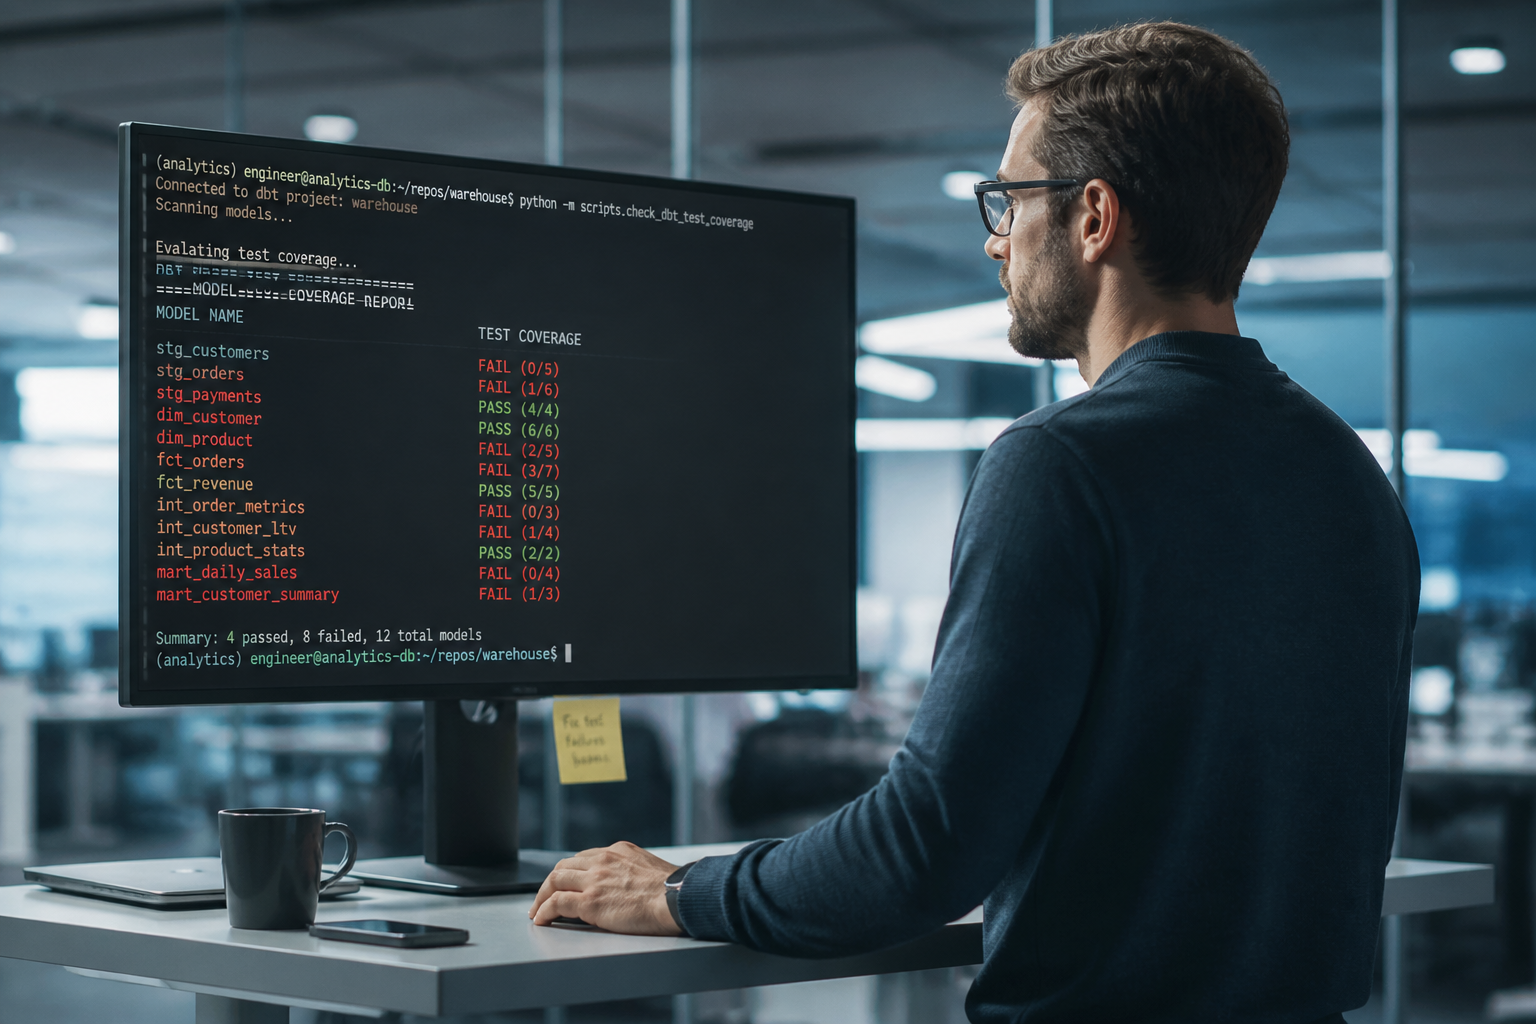
📺 Watch: How to test and debug your dbt models

How to Find Every Untested dbt Model in Your Project
There are two complementary approaches: querying the dbt manifest.json directly, and querying BigQuery INFORMATION_SCHEMA to cross-reference what is materialised against what has tests. Use both.
Method 1: Parse the manifest with dbt ls
First, generate a fresh manifest:
dbt compile
Then run this command to list every model that has no tests defined:
dbt ls --select "*" --output json \
  | python3 -c "
import sys, json for line in sys.stdin: line = line.strip() if not line: continue try: node = json.loads(line) except json.JSONDecodeError: continue print(node) "
That works if your version of dbt CLI supports --output json at the node level. A more reliable approach is to parse manifest.json directly after compiling:
python3 - <<'EOF'
import json
with open('target/manifest.json') as f: manifest = json.load(f)
nodes = manifest.get('nodes', {}) sources = manifest.get('sources', {})
Collect all unique_ids that have at least one test
tested_node_ids = set() for node_id, node in nodes.items(): if node.get('resource_type') == 'test': # Generic tests reference depends_on nodes for dep in node.get('depends_on', {}).get('nodes', []): tested_node_ids.add(dep)
Now find all model nodes with no test coverage
untested = [] for node_id, node in nodes.items(): if node.get('resource_type') != 'model': continue if node_id not in tested_node_ids: untested.append({ 'node_id': node_id, 'name': node.get('name'), 'schema': node.get('schema'), 'materialized': node.get('config', {}).get('materialized', 'unknown'), 'path': node.get('original_file_path') })
untested.sort(key=lambda x: x['name'])
print(f"\nUntested models: {len(untested)}\n") for m in untested: print(f" {m['name']:40s} [{m['materialized']:10s}] {m['path']}") EOF
Run this in the root of your dbt project. It will print every model with zero test dependencies — the model name, its materialisation type, and the file path. On a project with 60 models, this typically takes under three seconds.
Method 2: Cross-reference BigQuery INFORMATION_SCHEMA
This method surfaces materialised tables and views in BigQuery that have no corresponding test in the manifest. It is useful for catching models that were deployed before your current manifest was generated, or that were created outside of dbt entirely.
Step one: Export your untested model names from the Python script above into a temp table or a hardcoded list. Step two: run this against BigQuery:
SELECT
  t.table_schema,
  t.table_name,
  t.table_type,
  t.creation_time,
  t.row_count,
  t.size_bytes / POW(1024, 3) AS size_gb
FROM
  `your_project.your_dataset.INFORMATION_SCHEMA.TABLE_STORAGE` t
WHERE
  t.table_name IN (
    -- paste your untested model names here, or drive from a temp table
    'fct_revenue',
    'fct_orders',
    'dim_customers'
    -- ...
  )
  AND t.deleted = false
ORDER BY
  t.size_bytes DESC;
This tells you exactly which untested models are large and heavily materialised — the ones where a silent data error would have the biggest downstream impact. Sort by row_count or size_gb and those are your highest-priority targets.
Method 3: Find models with only a primary key test (worse than it looks)
A common false sense of security: models where someone added unique and not_null on the primary key and nothing else. The primary key test tells you the grain is intact — it does not tell you whether the numbers in the rows are correct.
Extend the Python script above to flag models with fewer than three tests:
# Replace the condition in the loop above with:
test_count = sum(
    1 for node_id2, node2 in nodes.items()
    if node2.get('resource_type') == 'test'
    and node_id in node2.get('depends_on', {}).get('nodes', [])
)
if test_count < 3:
    undertested.append({**node, 'test_count': test_count})
In practice, models with fewer than three tests — especially marts — should be treated as untested for the purposes of a quality audit.
Running that audit for one model is straightforward. Running it across an entire project, tracking it over time, and catching regressions in CI is a different problem. fintel-scan is a free, open-source MIT-licensed CLI that does this check — and fourteen others — locally, with no warehouse connection required: uvx fintel-scan. Worth adding to your pre-commit or CI step.
How to Fix the Coverage Gap Without Rewriting Everything
The mistake most teams make when they discover a coverage gap is trying to fix everything at once. They schedule a "test sprint", write 200 YAML entries in a week, and then never update them again because it felt like a chore. That is not a testing culture — that is a one-off clean-up that decays immediately.
A better approach: triage by risk, then fix incrementally.
Step 1 — Triage by downstream impact. Use the manifest's depends_on graph to identify models that feed the most downstream nodes. A staging model with five dependants is lower risk than a mart with zero tests that directly powers a finance dashboard. Prioritise the latter.
Step 2 — Apply a minimum viable test set to every untested mart. For any fct_ or dim_ model, the minimum is:
models:
  - name: fct_revenue
    columns:
      - name: revenue_id
        data_tests:
          - unique
          - not_null
      - name: transaction_date
        data_tests:
          - not_null
      - name: gross_revenue_gbp
        data_tests:
          - not_null
          - dbt_utils.accepted_range:
              min_value: 0
Note that data_tests replaced tests as the YAML key in dbt v1.8 — use the new syntax if you are on a current version to avoid deprecation warnings.
Step 3 — Add a row count assertion for every mart. This is the single highest-value test most teams skip. A mart that returns zero rows is indistinguishable from a mart that returns correct rows — unless you test for it:
- name: fct_revenue
  data_tests:
    - dbt_utils.recency:
        datepart: day
        field: transaction_date
        interval: 1
    - dbt_utils.expression_is_true:
        expression: "COUNT(*) > 0"
A mart that silently empties because of an upstream schema change will now fail the run instead of propagating empty data downstream.
With the release of dbt v1.8, dbt introduced a built-in unit testing framework, enabling users to conduct isolated, customizable tests at the model level. If your transformation logic is complex — currency conversion, proration, attribution weighting — unit tests against mock inputs are now the correct tool. They let you validate the SQL logic independently of whatever data happens to be in your warehouse today.
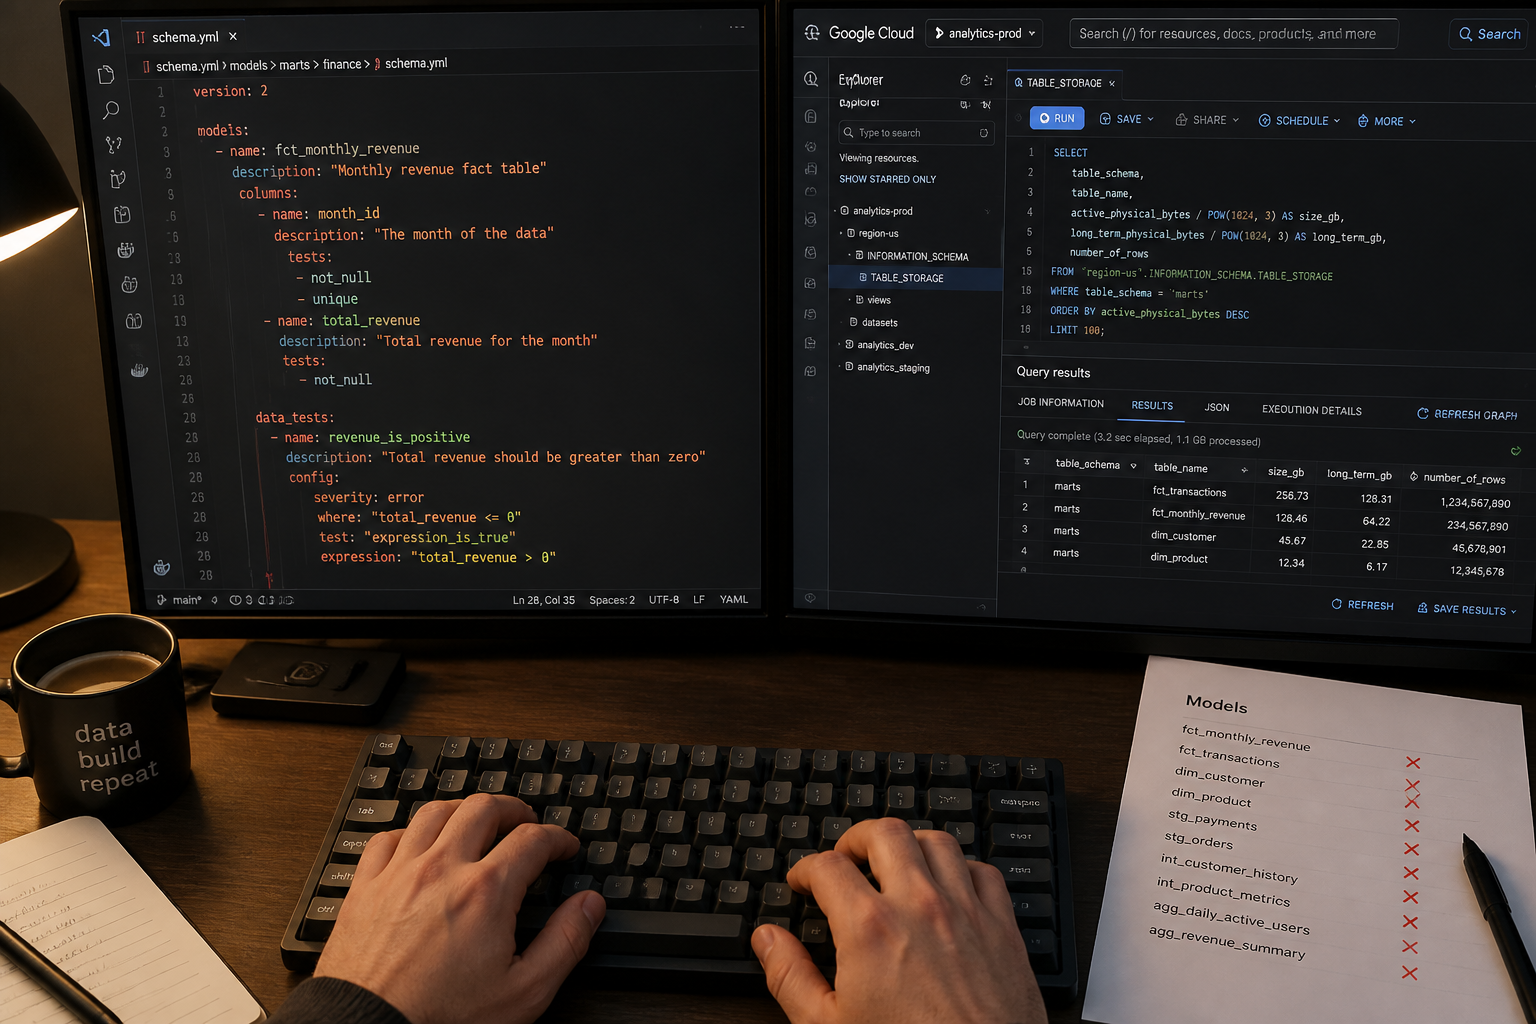
How to Stop New Untested Models Appearing in CI
Detection and remediation are only half the solution. The other half is preventing regressions — new models merging to main without test coverage.
Block PRs with dbt-checkpoint
Tools like dbt-checkpoint enforce governance and documentation standards on every pull request, so testing coverage does not depend on manual code review.
Add dbt-checkpoint to your pre-commit hooks:
# .pre-commit-config.yaml
repos:
  - repo: https://github.com/dbt-checkpoint/dbt-checkpoint
    rev: v2.0.0
    hooks:
      - id: check-model-has-all-columns
      - id: check-model-has-tests-by-name
        args: ["--test-names", "unique,not_null"]
      - id: check-model-has-description
With this in place, a PR that adds a model without at least unique and not_null on its primary key will fail the pre-commit hook before it ever reaches review. You shift the enforcement left — from "someone notices in production" to "the hook catches it before the branch is pushed".
Add a coverage check to your CI job
Re-run the Python manifest parser as a CI step and fail the job if any model in the marts layer has fewer than two tests:
- name: Check test coverage
  run: |
    python3 scripts/check_test_coverage.py --min-tests 2 --layer marts
    if [ $? -ne 0 ]; then
      echo "Coverage gate failed: untested mart models detected"
      exit 1
    fi
This turns test coverage from a "nice to have" into a hard gate on deployment. In our experience, it takes about two PRs being blocked before the habit becomes automatic.
For further context on how dbt project governance fits into a broader quality strategy, see our post on dbt project governance for startups — it covers model naming conventions, layer separation, and documentation standards that complement the testing approach described here. And if silent failures deeper in your pipeline are also a concern, dbt lineage blind spots covers the related problem of downstream models that break without any visible error.
Frequently Asked Questions
Q: How do I find dbt models with no test coverage quickly?
A: Run dbt compile to generate a fresh manifest.json, then parse it with Python to find all model nodes that have zero test dependencies. The script in this post produces a full list in under three seconds. Alternatively, use uvx fintel-scan to run this and fourteen other checks locally with no warehouse connection required.
Q: What is the minimum test coverage for a dbt model in production?
A: Every production model should have at minimum unique and not_null on its primary key column, plus a not_null on any business-critical metric columns. Mart models (fct_ and dim_ prefixed) should additionally have a row count or recency assertion to catch silent empty-table failures. Fewer than three tests on a mart is effectively untested for practical purposes.
Q: How do I prevent untested dbt models from being merged to main?
A: Add dbt-checkpoint to your pre-commit hooks and configure the check-model-has-tests-by-name rule to require unique and not_null at minimum. Add a manifest coverage check as a CI gate that fails the job if any model in your marts layer has fewer than two tests. This enforces the standard at the point of development, not after deployment.
Q: Does BigQuery INFORMATION_SCHEMA show me which tables are untested?
A: INFORMATION_SCHEMA shows you what is materialised in your warehouse — tables, views, their sizes and row counts. It does not know anything about dbt tests. To find untested materialised objects, you need to cross-reference INFORMATION_SCHEMA table names against the set of models with zero tests extracted from your dbt manifest.json. The combination gives you a prioritised list sorted by table size or row count.
Q: What changed in dbt v1.8 for testing?
A: dbt v1.8 introduced two significant changes: native unit tests that validate transformation logic against mock inputs before materialisation, and the renaming of the tests: YAML key to data_tests: for generic tests. If you are on v1.8 or later, use data_tests: in your YAML to avoid deprecation warnings. Unit tests are particularly valuable for complex calculation logic — currency conversion, proration, attribution — where data tests on real data may not expose incorrect logic.
Untested dbt models are one of the most common and most costly silent risks we encounter in analytics engineering audits — not because teams are careless, but because projects grow faster than the governance that should surround them. At Fintel Analytics, we have helped fintech, payments, and e-commerce businesses audit their dbt projects from scratch, establish coverage standards, and wire enforcement into CI so that regressions never reach production again. If your project has grown faster than your testing discipline, that is a fixable problem — and fixing it is significantly cheaper than the downstream consequences of shipping bad data.