
The Short Answer
Silent NULL propagation in dbt and BigQuery occurs when a NULL value — introduced by a LEFT JOIN with no matching row, a failed SAFE_CAST, or an upstream schema change — flows through your transformation layer without triggering a single test failure, eventually corrupting SUM, AVG, and COUNT DISTINCT aggregates in your marts. The models build green, the pipeline completes, and a dashboard quietly serves wrong numbers.
This is the failure mode that causes two dashboards to show Q3 revenue as $2M apart with no failed job and no fired alert to explain it. It is also, in our experience, the most under-tested class of problem in early-stage data stacks — because teams add not_null tests on primary keys and call it done. The NULL that kills your revenue metric almost never lives on a primary key.
Why NULL Propagation Is Hard to Catch With Standard dbt Tests
The default dbt testing toolkit — unique, not_null, accepted_values, relationships — is excellent at catching structural problems: duplicate keys, referential integrity failures, values outside an allowed set. What it does not do out of the box is trace where a NULL entered the pipeline or assert that a specific column cannot be NULL at the mart layer after aggregation.
The result is a common and painful gap: a not_null test guards the order_id in your staging model, but nobody has asserted that gross_revenue in fct_orders is always populated. A LEFT JOIN to a payments table with incomplete data means some orders have NULL revenue. SUM(gross_revenue) silently excludes those rows — BigQuery, like standard SQL, treats SUM(NULL) as NULL and skips NULLs in aggregation — and your total is understated by an amount nobody can easily quantify.
There are three common entry points for this class of problem:
1. LEFT JOIN mismatches. A lookup join to a reference table (currency rates, product catalogue, fee schedules) finds no match for a row. Every column from the right-hand side of that join comes back NULL. If downstream logic does not COALESCE those columns before using them in a calculation, the NULL propagates.
2. SAFE_CAST silently returning NULL. BigQuery's SAFE_CAST is genuinely useful — it prevents query failures on bad input — but it returns NULL whenever the cast fails, with no error and no warning. A real-world example from production: a source system quietly changed its timestamp precision from microseconds to nanoseconds. SAFE_CAST silently started returning NULL for every new event timestamp. Without monitoring in place, this kind of issue can go unnoticed for a significant period before anyone traces declining metric coverage back to the cast.
3. Upstream schema changes that coerce a column to NULL. An upstream team renames a column. Your dbt source still references the old name, BigQuery returns NULL for every row, and — if there is no source_freshness check or column-level contract — the model builds fine with a fully NULL column flowing into your mart.
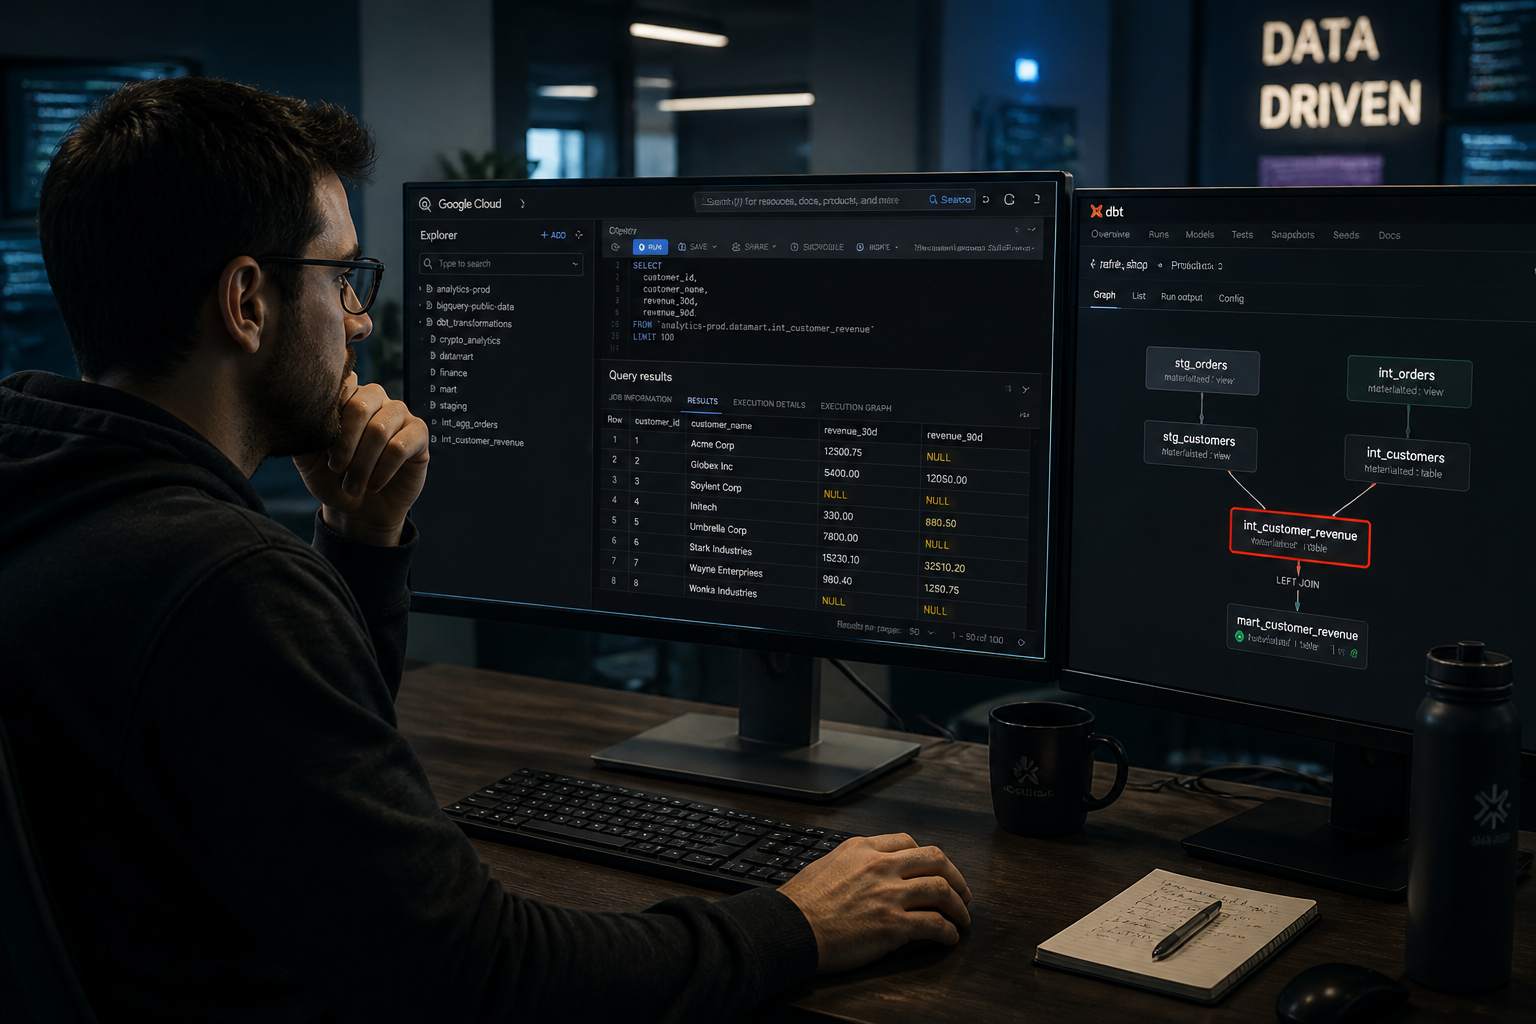
How to Find Silent NULL Propagation in BigQuery (Runnable Diagnostic)
The goal of this diagnostic is to surface mart-layer columns where NULL rates are non-trivially high on columns that should never be NULL — revenue, amounts, foreign keys used in joins. Run this against your BigQuery project in under five minutes.
Step 1 — Find columns with unexpected NULL rates in your marts
This query scans INFORMATION_SCHEMA.COLUMN_FIELD_PATHS for your mart dataset and then samples the actual NULL rate per column using dynamic SQL. In practice, you will want to run the second part for the specific tables that feed your key metrics. Here is a targeted version for a known fact table:
-- Replace `your_project.your_mart_dataset.fct_orders` with your table
SELECT
  column_name,
  COUNTIF(column_value IS NULL) AS null_count,
  COUNT(*) AS total_rows,
  ROUND(
    SAFE_DIVIDE(
      COUNTIF(column_value IS NULL),
      COUNT(*)
    ) * 100, 2
  ) AS null_pct
FROM (
  SELECT
    'gross_revenue' AS column_name,
    CAST(gross_revenue AS STRING) AS column_value
  FROM `your_project.your_mart_dataset.fct_orders`
  UNION ALL
  SELECT
    'payment_method',
    CAST(payment_method AS STRING)
  FROM `your_project.your_mart_dataset.fct_orders`
  UNION ALL
  SELECT
    'currency_code',
    CAST(currency_code AS STRING)
  FROM `your_project.your_mart_dataset.fct_orders`
)
GROUP BY column_name
ORDER BY null_pct DESC;
Anything above 0% on a column like gross_revenue or currency_code is worth investigating immediately. A 2% NULL rate on revenue in a table with 500,000 rows is not a rounding issue — it is missing money.
Step 2 — Trace which dbt model introduced the NULL
Once you know which column has unexpected NULLs, trace backwards through the model DAG. Check whether the NULL first appears in staging, intermediate, or only in the mart:
-- Run against your staging table to test if the NULL originates there
SELECT
  COUNT(*) AS total,
  COUNTIF(gross_revenue IS NULL) AS nulls_in_staging,
  ROUND(SAFE_DIVIDE(COUNTIF(gross_revenue IS NULL), COUNT(*)) * 100, 2) AS null_pct
FROM `your_project.your_staging_dataset.stg_orders`;
If the NULL rate in staging is 0% but non-zero in fct_orders, the introduction point is in an intermediate model or mart join — almost certainly a LEFT JOIN. Grep your dbt models for LEFT JOIN on the table feeding that column and check whether the join key has full coverage:
-- Check join key coverage between orders and payments
SELECT
  o.order_id,
  p.payment_id
FROM `your_project.your_staging_dataset.stg_orders` o
LEFT JOIN `your_project.your_staging_dataset.stg_payments` p
  ON o.order_id = p.order_id
WHERE p.payment_id IS NULL
LIMIT 100;
If rows come back, those orders have no matching payment record. Every amount column joined from stg_payments will be NULL for those rows, and SUM(payment_amount) will silently exclude them.
Step 3 — Check for SAFE_CAST silently producing NULLs in staging
-- Find SAFE_CAST columns returning NULL above a 0% threshold
SELECT
  'transaction_ts' AS column_name,
  COUNTIF(SAFE_CAST(raw_transaction_ts AS TIMESTAMP) IS NULL) AS cast_nulls,
  COUNT(*) AS total
FROM `your_project.your_raw_dataset.raw_events`
HAVING SAFE_DIVIDE(cast_nulls, total) > 0;
If this returns rows, your source system has changed the format of that field. This is exactly the failure mode where a precision change (e.g. microseconds to nanoseconds) causes SAFE_CAST to return NULL silently for every new record.
Running that diagnostic for one table is manageable. Checking every model across a full project is not — fintel-scan is a free, open-source MIT-licensed CLI that automates this check and fourteen others locally, with no warehouse connection required: uvx fintel-scan.
How to Fix Silent NULL Propagation in Your dbt Models
Detection is only half the job. Once you have found the entry points, the fix falls into one of three patterns:
Fix 1 — Add column-level not_null tests on mart columns that matter
This sounds obvious, but in practice it is not done. Most projects have not_null on surrogate keys and nothing else. Add it to every column that feeds a business-critical metric:
# In your schema.yml for fct_orders
models:
  - name: fct_orders
    columns:
      - name: gross_revenue
        tests:
          - not_null
      - name: currency_code
        tests:
          - not_null
This will now fail the dbt build if any row has a NULL in gross_revenue — which is exactly what you want. If you have legitimate NULLs (e.g. cancelled orders with no revenue), filter them out in the model or use a where clause on the test:
- name: gross_revenue
  tests:
    - not_null:
        config:
          where: "order_status != 'cancelled'"
Fix 2 — Replace bare SAFE_CAST with an explicit NULL guard
Do not let SAFE_CAST silently nullify a column and move on. Wrap it with a COALESCE or — better — use a macro that both casts and raises a warning:
-- In your staging model
SELECT
  order_id,
  SAFE_CAST(raw_transaction_ts AS TIMESTAMP) AS transaction_ts,
  -- Explicit guard: surface the failure rather than swallow it
  CASE
    WHEN SAFE_CAST(raw_transaction_ts AS TIMESTAMP) IS NULL
      THEN ERROR('Unexpected NULL from SAFE_CAST on transaction_ts')
    ELSE SAFE_CAST(raw_transaction_ts AS TIMESTAMP)
  END AS transaction_ts_strict
FROM {{ source('raw', 'events') }}
For production pipelines where you cannot afford a hard failure, log the NULL rate as a metric to a monitoring table instead, and alert when it exceeds a threshold. The key principle: never let SAFE_CAST silently discard data without somewhere recording that it happened.
Fix 3 — Convert LEFT JOINs to INNER JOINs where coverage should be complete, or assert coverage with a relationships test
If every order should have a payment record, the join should be INNER, not LEFT. If you are using LEFT JOIN defensively because you are not sure about coverage, add a relationships test in dbt to make the gap explicit:
- name: order_id
  tests:
    - relationships:
        to: ref('stg_payments')
        field: order_id
This test will fail if any order_id in stg_orders does not exist in stg_payments — surfacing the join coverage problem before the NULL propagates into your mart.
For a deeper look at how bad joins can corrupt your aggregates in a different but related way, see our post on dbt fan-out joins in BigQuery — the fix patterns overlap significantly.
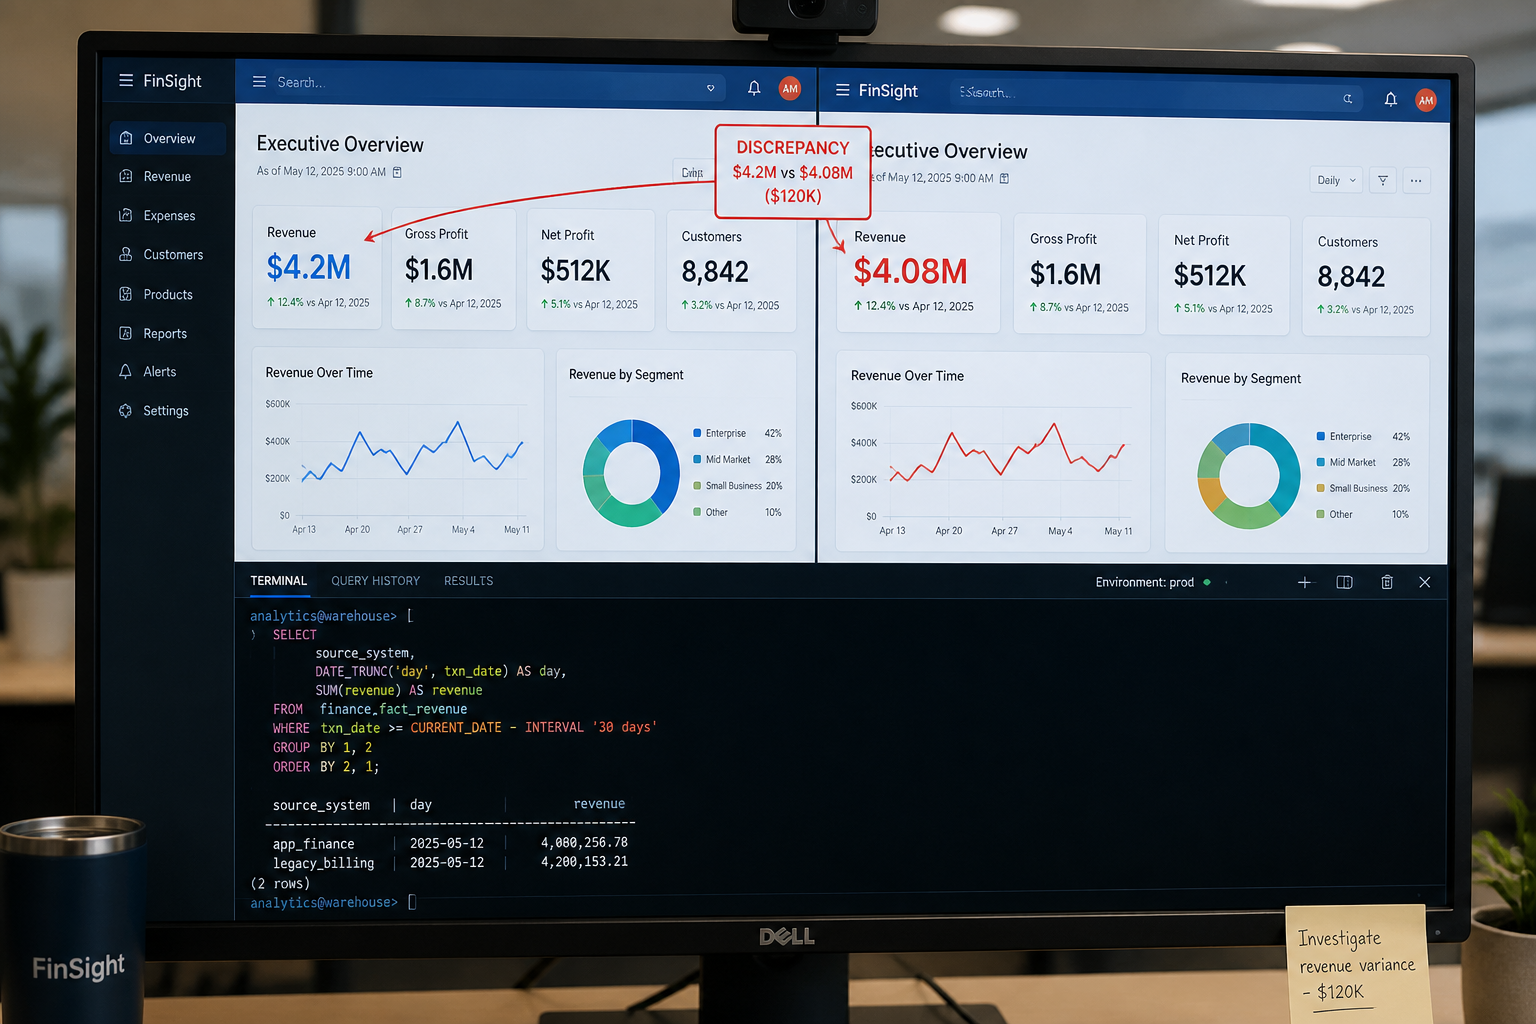
How to Stop It Recurring: A Minimal Prevention Layer
Detection and fixing the current problem is not enough if the same failure class will reappear next quarter when a source system changes. Here is the minimum viable prevention layer for a dbt + BigQuery project:
Layer 1 — Source-level column contracts. Use dbt source columns: definitions with not_null tests on every column that feeds a critical metric. If the upstream schema changes, the source test fails before the bad data reaches staging.
Layer 2 — NULL rate monitoring as a custom dbt test. Write a singular test that asserts the NULL rate on a mart column stays below a threshold. A sudden spike from 0% to 2% is as diagnostic as an outright failure:
-- tests/assert_gross_revenue_null_rate.sql
SELECT
  CASE
    WHEN SAFE_DIVIDE(COUNTIF(gross_revenue IS NULL), COUNT(*)) > 0.001
    THEN 'NULL rate exceeds 0.1% threshold'
  END AS failure_reason
FROM {{ ref('fct_orders') }}
HAVING failure_reason IS NOT NULL;
Layer 3 — Store test failures for trend analysis. Set store_failures: true in your dbt project config so that test failures are persisted to BigQuery tables. You can then query failure history to see whether a NULL rate is trending upward over time, rather than only catching it when it crosses a hard threshold.
The dbt Labs data team demonstrated in 2024 that a centralised failure management approach — storing test results and routing them to a shared dashboard — can dramatically reduce the time between error detection and resolution while actually reducing total test count by consolidating overlapping checks.
Layer 4 — Source freshness plus column-level schema drift detection. Pair source freshness checks with schema drift monitoring. If you are not already doing this, our post on dbt source schema drift walks through the detection pattern for BigQuery specifically.
A pattern we see repeatedly in early-stage fintech and e-commerce companies: the data team adds not_null on primary keys during the initial dbt setup, ships, and never revisits test coverage as the model layer grows. Six months later the mart has thirty columns, two of which feed the board-level revenue metric, and neither has a single test. The pipeline runs green every morning. The metric is wrong.
In one case we diagnosed for a Series A payments company, a LEFT JOIN to a currency conversion table was producing NULL exchange rates for a small but growing slice of transactions — roughly 3% of volume. The SUM of converted revenue was understated by that proportion. Nobody had noticed because the absolute numbers were growing (masking the undercount) and because every test in the project was green. Once we added a not_null test on the converted amount column and a relationships test on the join key, the failure surfaced immediately and the fix took under an hour. The diagnostic took longer than the fix.
Frequently Asked Questions
Q: Why does BigQuery not throw an error when a SUM includes NULL values?
A: Standard SQL — and BigQuery — treats NULL as "unknown" rather than zero. Aggregate functions like SUM, AVG, and COUNT (without the DISTINCT or asterisk variants) simply skip NULL rows rather than raising an error. This is correct SQL behaviour, but it means an understated metric and no error message — making it one of the hardest failure modes to detect without explicit tests.
Q: Can SAFE_CAST cause silent NULL propagation in BigQuery?
A: Yes. SAFE_CAST returns NULL whenever a type conversion fails, instead of raising an error. This is intentional — it prevents pipeline failures on bad input — but it means a format change in a source system (e.g. a timestamp precision change from microseconds to nanoseconds) can start silently nullifying a column for every new record, with no error surfaced in your dbt run or query logs.
Q: How do I find which dbt model introduced a NULL into my mart?
A: Run NULL rate checks at each layer: raw source, staging, intermediate, and mart. The layer where the NULL rate first becomes non-zero is the introduction point. A LEFT JOIN with missing right-side rows and a SAFE_CAST on a changed source field are the two most common culprits. The diagnostic SQL in this post walks through both checks.
Q: Does dbt's built-in not_null test catch silent NULL propagation?
A: Only if you have applied it to the right column at the right layer. By default, most projects only apply not_null to surrogate keys and primary keys. A not_null test on order_id will not catch a NULL in gross_revenue. You need to add not_null tests to every column that feeds a business-critical metric — at the mart layer, not just in staging.
Q: What is the difference between silent NULL propagation and a dbt fan-out join?
A: A fan-out join inflates row counts and overstates aggregates by multiplying rows when a join key is not unique on the right-hand side. Silent NULL propagation does the opposite — it understates aggregates by excluding NULL rows from SUM and AVG calculations. Both failures pass standard dbt tests and both corrupt your metrics silently. Fan-out detection uses COUNT vs COUNT DISTINCT comparisons; NULL propagation detection uses null rate checks on metric columns.
Silent NULL propagation is one of the most common correctness problems we find when we audit a dbt and BigQuery project — and it is almost always invisible until someone manually compares a dashboard number to a source-system export and finds a gap they cannot explain. At Fintel Analytics, we have helped fintech, payments, and e-commerce teams build the diagnostic and prevention layers that catch this class of failure before it reaches a board deck — from column-level test coverage through to NULL rate monitoring wired into alerting. If your pipeline runs green every morning but your numbers don't always add up, that is a solvable problem, and the diagnostic takes less than a day.