
The Short Answer: How to Detect a Fan-Out Join in a dbt BigQuery Model
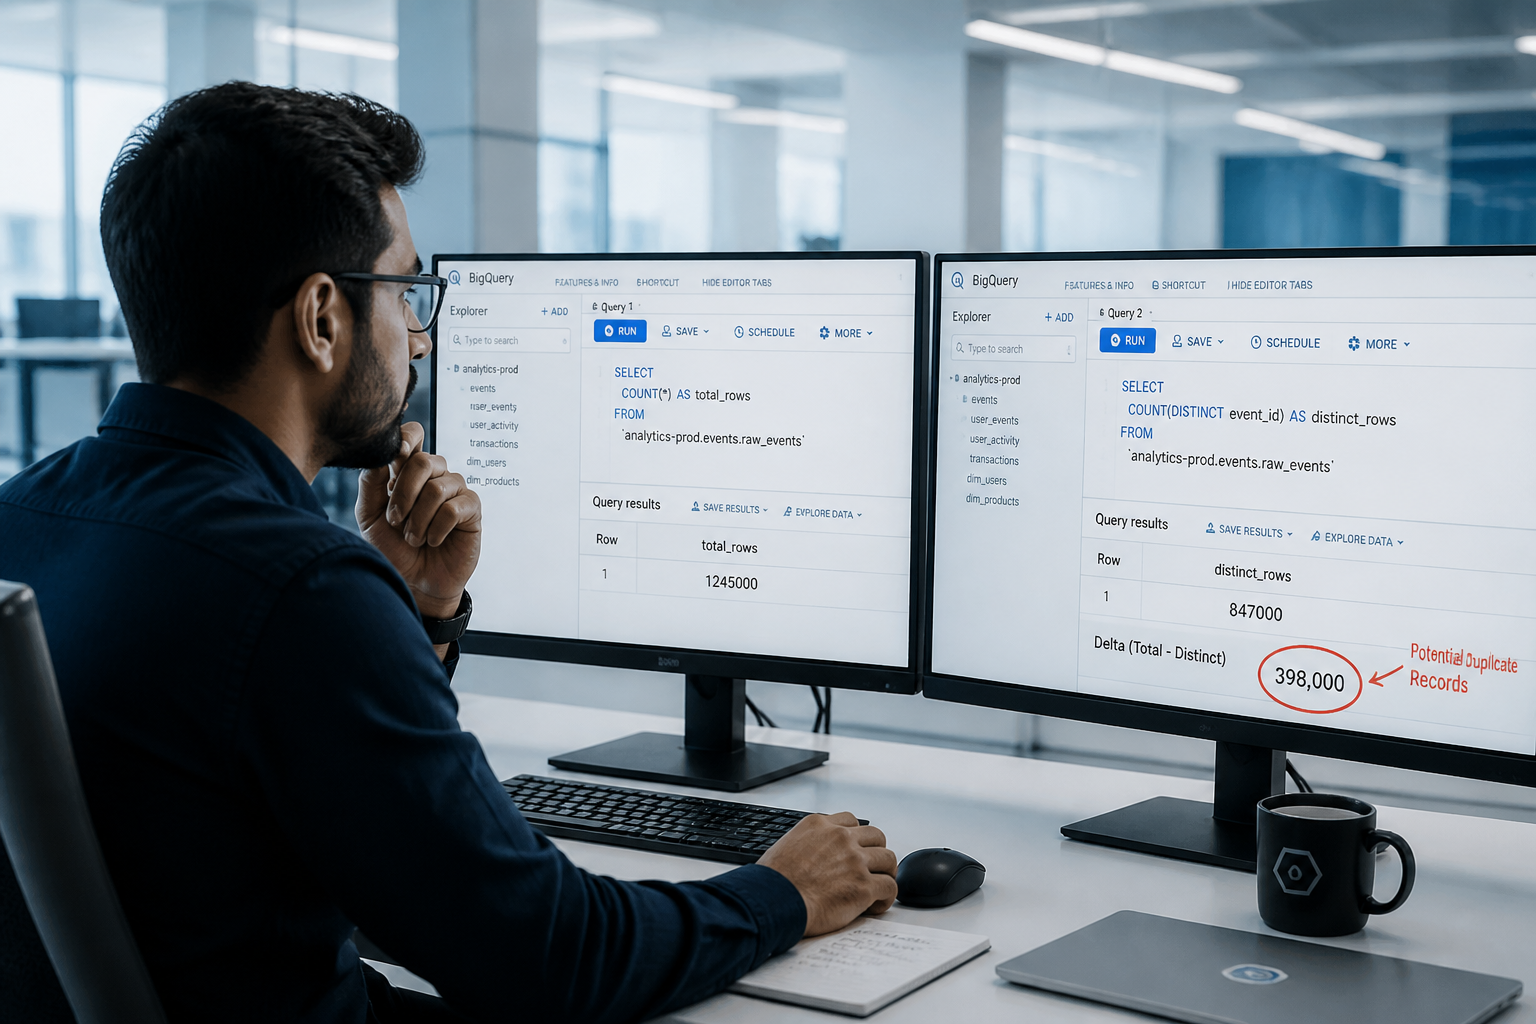
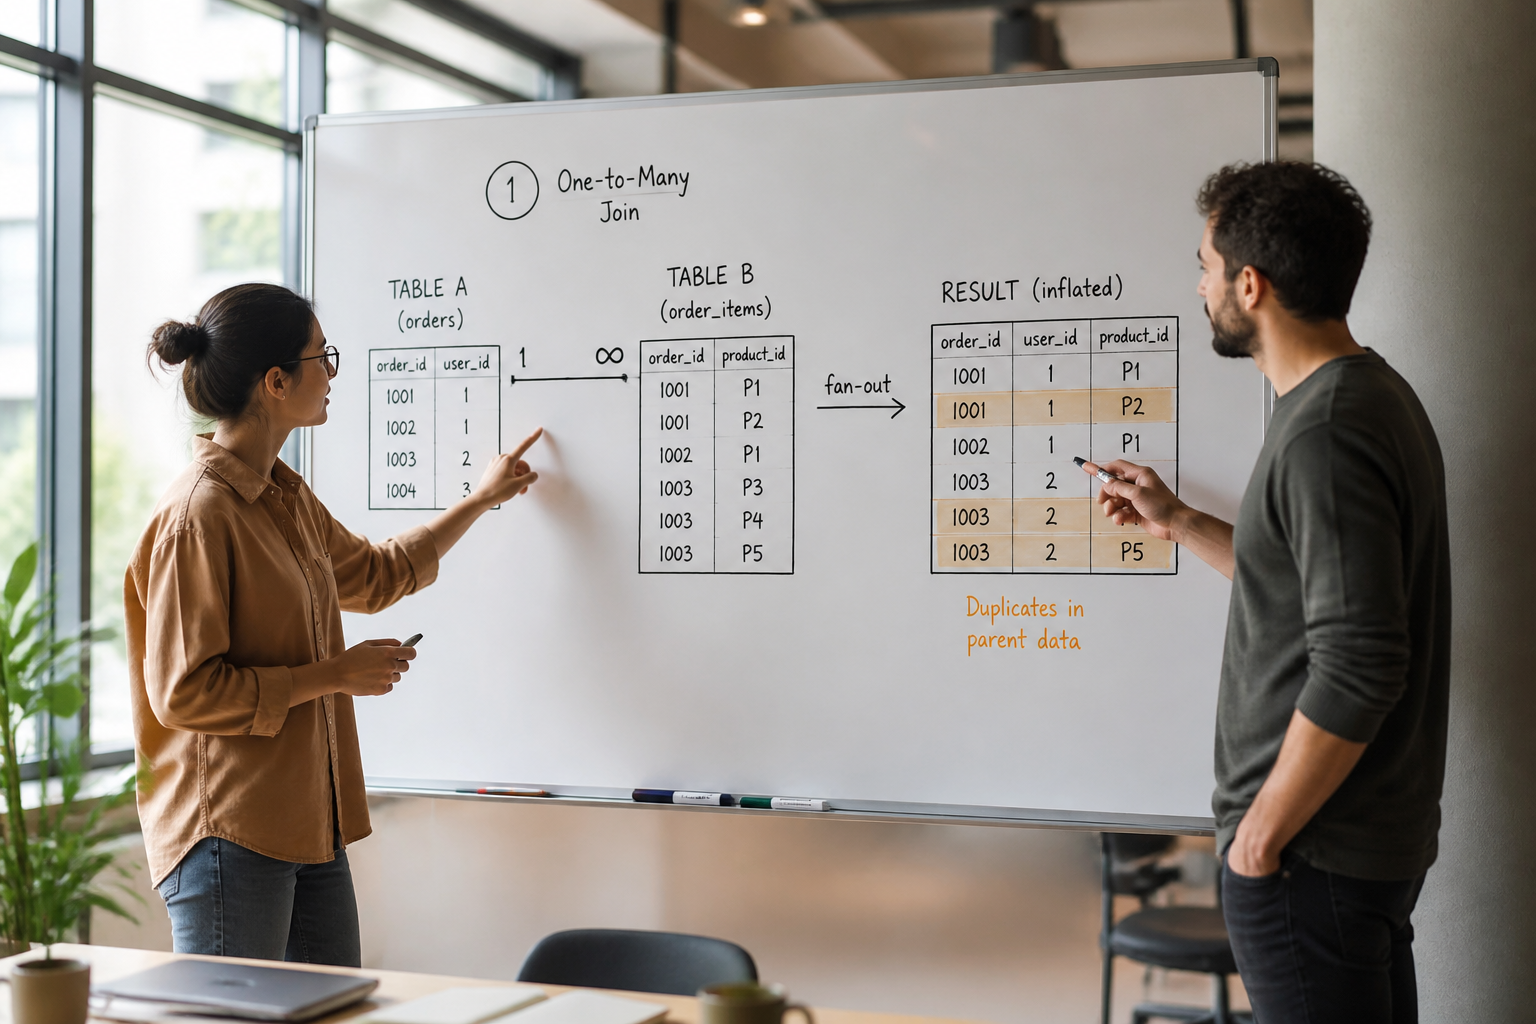
A fan-out join happens when one row in your fact table matches multiple rows in a dimension table, causing the output to contain more rows than the source. In BigQuery dbt projects, the fastest way to detect it is to compare COUNT(*) against COUNT(DISTINCT <primary_key>) on any mart model. If those two numbers differ, you have duplicates — and every aggregated metric downstream is wrong.
The insidious part is that dbt does not raise an error. The model builds cleanly, the pipeline shows green, and your revenue dashboard quietly starts reporting a number that is 15% too high. By the time a finance lead spots it, the inflated figure may have already landed in a board pack.
Why Fan-Out Joins Are So Common in dbt Projects on BigQuery
Fan-out is one of the most frequently encountered data correctness problems in analytics engineering. dbt's semantic layer via MetricFlow is specifically designed to avoid fan-out and chasm joins — but that protection only applies when you use MetricFlow. Fan-out joins occur when one row in a table is joined to multiple rows in another table, producing more output rows than input rows. In hand-written staging and mart models, nobody is protecting you.
There are three patterns that produce fan-out in almost every project we have worked on:
1. A dimension table that was not deduplicated before the join. The canonical example is a promotions table, a tags table, or any entity that can have multiple active records per foreign key. If your orders model joins to a promotions table on customer_id, and a customer has three active promotions, every order row for that customer is now triplicated.
2. A type mismatch on the join key. A join key mismatch between upstream tables — such as user_id migrating from varchar to bigint in one table but not another — causes the join to silently produce NULL join keys, which a LEFT JOIN happily keeps, filling downstream models with zeros and NULLs. This is technically a chasm join variant, but the downstream symptom — aggregated metrics that are wrong — is identical.
3. A many-to-many relationship treated as one-to-many. This is the most common structural error we see when inheriting a dbt project: the engineer who built the join assumed a one-to-many relationship existed in the source, but a schema change upstream introduced duplicates months after the model was written.
According to dbt Labs' 2024 State of Analytics Engineering report, over 57% of data professionals cited poor data quality as a predominant issue — up from 41% in 2022. Fan-out joins are a significant contributor to that figure because they produce data that looks clean from the outside. The model runs, the rows arrive, the dashboard loads. The number is just wrong.
📺 Watch: Why SQL Queries Get Expensive? Slots, Shuffles, and Skew
How to Find Fan-Out in Your BigQuery dbt Models Right Now
This is the diagnostic you can run today. You need two things: the name of the mart model you want to check, and the name of its primary key column.
Step 1 — Single-model row count check
Run this directly in BigQuery against any mart model:
SELECT
  COUNT(*)                    AS total_rows,
  COUNT(DISTINCT order_id)    AS distinct_orders,
  COUNT(*) - COUNT(DISTINCT order_id) AS duplicate_row_count,
  SAFE_DIVIDE(
    COUNT(*) - COUNT(DISTINCT order_id),
    COUNT(*)
  ) * 100                    AS duplication_rate_pct
FROM `your_project.your_dataset.fct_orders`;
Replace order_id and fct_orders with your actual primary key and model name. If duplicate_row_count is anything other than zero, you have fan-out.
Step 2 — Scan the whole project using INFORMATION_SCHEMA
Checking one model manually is useful. Checking thirty mart models across your project is not. The query below pulls every table in your analytics dataset and surfaces any whose row count could be inflated — it does this by joining against your dbt-generated information_schema metadata to identify fact tables, then reporting row counts:
SELECT
  t.table_name,
  t.row_count,
  t.size_bytes / 1024 / 1024 AS size_mb,
  t.creation_time
FROM `your_project.your_dataset.INFORMATION_SCHEMA.TABLE_STORAGE` t
WHERE t.table_schema = 'your_dataset'
  AND t.table_type = 'BASE TABLE'
ORDER BY t.row_count DESC;
This gives you a ranked list of your largest tables. Any model whose row count is unexpectedly large relative to the source system row count is a candidate for further investigation with the Step 1 query.
Step 3 — Find models with NO uniqueness test in your dbt project
The root cause of undetected fan-out is almost always absent test coverage. Run this dbt meta-query locally to surface every model in your project that has no unique test defined on any column:
dbt ls --select "*" --output json \
  | python3 -c "
import sys, json
for line in sys.stdin:
    node = json.loads(line)
    if node.get('resource_type') == 'model':
        tests = node.get('depends_on', {}).get('nodes', [])
        print(node['unique_id'])
"
Or, more directly — run dbt docs generate then inspect the generated manifest.json to find any model node where the column_tests array contains no entry with test_metadata.name == "unique". This is the list of models that are running blind.
Running that query for one table is fine. Checking every model in a project is not — fintel-scan is a free open-source CLI tool (MIT licensed) that runs this check and fourteen others across your whole dbt project locally, with no warehouse connection required:
uvx fintel-scan.
How to Fix a Fan-Out Join in dbt — Three Patterns
Once you have confirmed which model is inflated, the fix depends on which of the three root causes is responsible.
Fix 1: Deduplicate the dimension before joining
If the fan-out comes from a dimension table with multiple rows per foreign key, deduplicate it in a staging model before it ever reaches your mart:
-- models/staging/stg_promotions_deduplicated.sql
WITH ranked AS (
  SELECT
    *,
    ROW_NUMBER() OVER (
      PARTITION BY customer_id
      ORDER BY created_at DESC
    ) AS row_num
  FROM {{ source('crm', 'promotions') }}
)
SELECT * EXCEPT(row_num)
FROM ranked
WHERE row_num = 1
This pattern — ROW_NUMBER() OVER (PARTITION BY <key> ORDER BY <recency>) — is the single most frequently applied fix in fan-out remediation. Keep the deduplication logic in its own staging model so it is visible, testable, and reusable downstream.
Fix 2: Add a uniqueness assertion before the join
Before joining any table into a fact model, add an intermediate model that asserts uniqueness on the join key. Running a unique and not_null test on the join key column means that if a duplicate appears, the pipeline fails at the test stage rather than silently producing inflated revenue figures in the dashboard. This is the difference between a pipeline that works and one that is reliable.
In your schema.yml:
models:
  - name: stg_promotions_deduplicated
    columns:
      - name: customer_id
        tests:
          - unique
          - not_null
This test runs every time dbt build executes. If the source starts sending duplicates again — due to an upstream schema change or a CRM migration — the build fails rather than silently inflating your metrics.
For related guidance on how upstream schema changes can silently break your models before this point, see our post on dbt source schema drift — it covers the detection and alerting patterns that stop schema surprises from reaching your marts in the first place.
Fix 3: Replace the bad join with a scalar subquery or aggregation
Sometimes the right fix is not to deduplicate the dimension but to change the join logic entirely. If you are joining to retrieve a single aggregate value (e.g. total promotion discount for a customer), do not join — aggregate first:
-- Instead of a direct join that fans out:
-- JOIN promotions ON orders.customer_id = promotions.customer_id

-- Use a pre-aggregated CTE:
WITH customer_discounts AS (
  SELECT
    customer_id,
    SUM(discount_amount) AS total_discount
  FROM {{ ref('stg_promotions') }}
  GROUP BY 1
)
SELECT
  o.*,
  cd.total_discount
FROM {{ ref('stg_orders') }} o
LEFT JOIN customer_discounts cd
  ON o.customer_id = cd.customer_id
This pattern eliminates the fan-out at the architecture level rather than patching it downstream.
How to Stop Fan-Out From Recurring in Production
Detecting and fixing one instance of fan-out is not enough. The structural problem is that most dbt projects have no systematic gate that would have caught this before it reached production.
Add uniqueness tests to every primary key in every mart model. This is not optional. Primary keys must be unique — this test catches the dreaded fan-out join that multiplies your metrics. If your project has models without uniqueness tests on their grain column, you are running blind. Run the dbt ls command in Step 3 above, get the list, and work through it.
Add row count assertions to critical models. Checking that the row count is within an expected range — for example, between 900K and 1.1M rows — catches both truncated loads and duplicate explosions. For mart models in a fintech or payments context, the row count of your fct_transactions or fct_orders model should track closely with the source system. A 20% spike in row count with no corresponding business event is a red flag worth alerting on.
Run dbt build not dbt run. dbt tests, when configured correctly, block bad data from propagating downstream — dbt build runs tests immediately after each model materialises, before downstream models consume its output. A failing test is a failing build. The bad data never propagates. Teams that use dbt run only are skipping the gate entirely.
Enforce test coverage in CI. Add a step to your CI pipeline that fails the build if any model in marts/ has no unique test on its primary key. This can be done with a simple Python script that reads the manifest.json after dbt docs generate and asserts coverage. It takes twenty minutes to write and catches every future fan-out before it ships.
For a broader framework on how to build reliable dbt test coverage from scratch — including severity levels, singular tests, and contract enforcement — see our post on dbt testing strategy for startups.
Frequently Asked Questions
Q: What is a fan-out join in dbt and why does it cause problems?
A: A fan-out join occurs when one row in a fact or staging table matches multiple rows in the table being joined, causing the output to contain more rows than the original source. In dbt models on BigQuery, this silently inflates any aggregated metric — revenue, transaction counts, conversion rates — built on top of that model. Because dbt does not error on a fan-out, the model builds cleanly and the problem is invisible until a stakeholder spots an anomaly.
Q: How do I check if my dbt model has inflated row counts in BigQuery?
A: Run SELECT COUNT(*) AS total_rows, COUNT(DISTINCT <primary_key>) AS distinct_rows FROM <your_mart_model>. If total_rows is greater than distinct_rows, you have duplicates caused by a fan-out. The difference divided by total_rows gives you the duplication rate as a percentage.
Q: Does adding a unique test in dbt prevent fan-out joins?
A: Yes — if you add a unique test on the primary key of every mart model and run dbt build, the build will fail immediately if a fan-out causes duplicate primary keys. This gates the bad data before it reaches any dashboard or downstream consumer. It does not prevent the join from being written incorrectly, but it guarantees you will be alerted the moment it materialises.
Q: What is the difference between a fan-out join and a chasm join in dbt?
A: A fan-out join produces more rows than expected because one fact row matches multiple dimension rows, inflating aggregated metrics upward. A chasm join produces fewer rows than expected because rows fall out of the join due to missing matches, deflating metrics. Both are silent in dbt without appropriate tests. Fan-out inflates; chasm deflates. Both destroy metric accuracy.
Q: How do I find all dbt models without a uniqueness test in my project?
A: Run dbt docs generate to produce a manifest.json, then parse the JSON to find any model node under nodes where no child test node has test_metadata.name == "unique". Alternatively, use dbt ls --select "test_type:unique" --output json to list all unique tests that do exist, then cross-reference against your full model list to identify gaps. The open-source CLI tool fintel-scan (MIT licensed, uvx fintel-scan) automates this check across the whole project.
Fan-out joins are one of the most damaging silent failures in a dbt project — the kind that inflates a revenue figure by 15%, survives three sprint cycles, and then surfaces in a board meeting. At Fintel Analytics, we have audited dozens of dbt projects across fintech, payments, and e-commerce businesses and found uncovered fan-out in the majority of them — often in the models closest to the metric surfaces that matter most. If your team is not certain that your mart-layer row counts are clean, that uncertainty has a cost, and it is fixable faster than you think.