
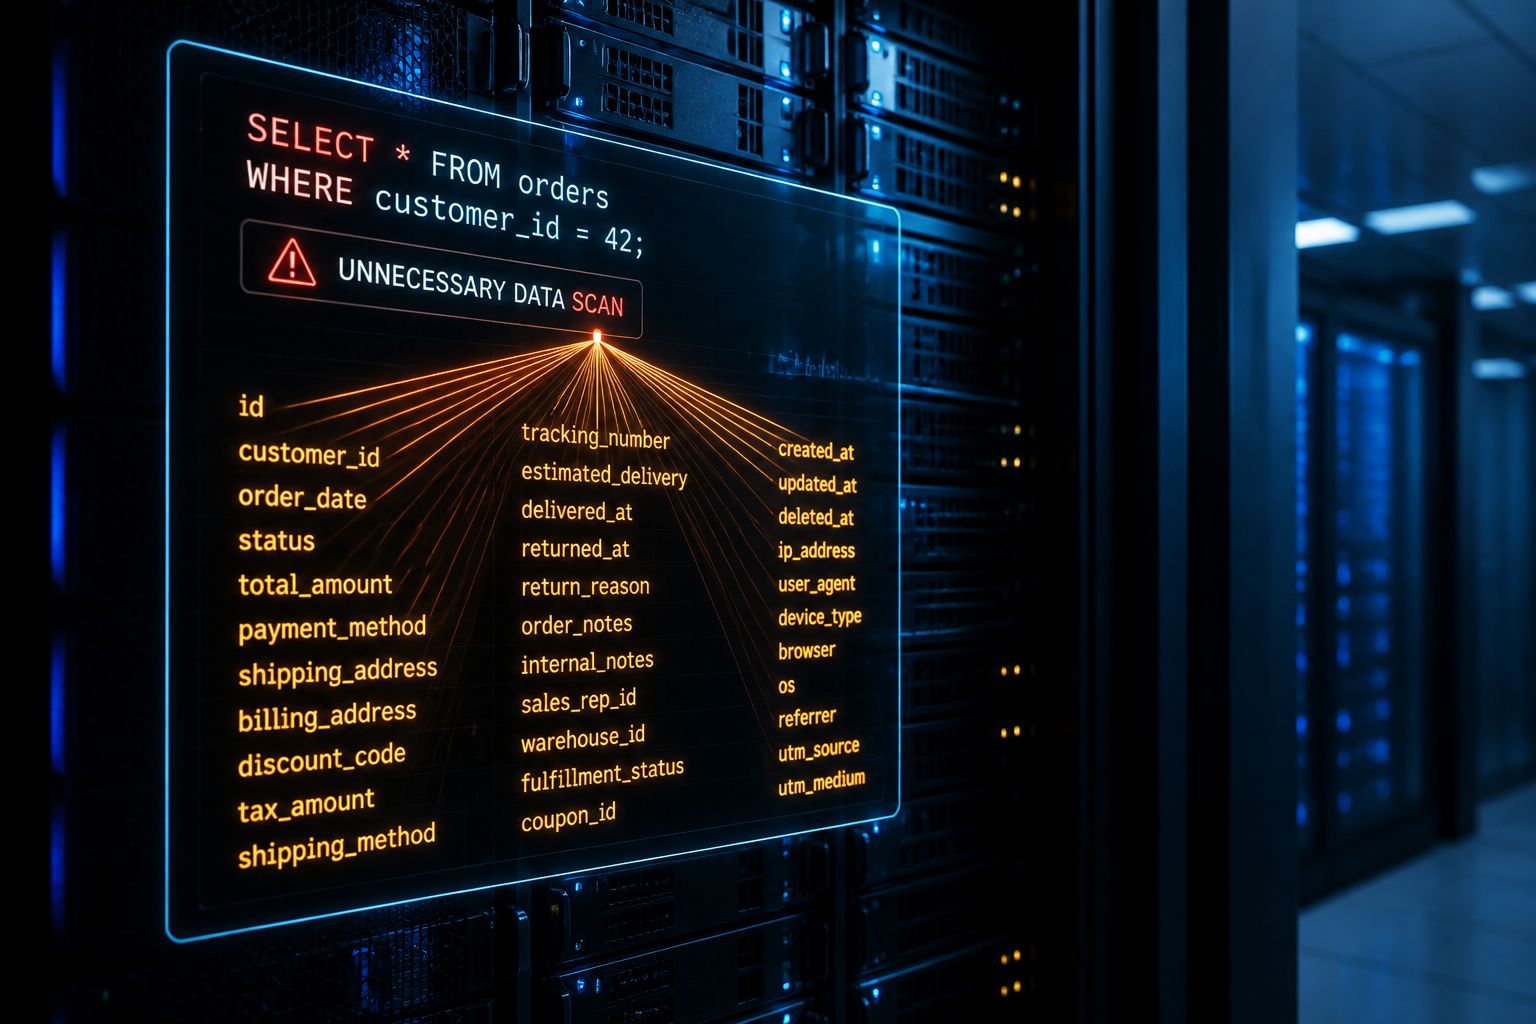
SELECT * in dbt BigQuery models forces BigQuery to scan every column in every upstream table on every run — and because BigQuery bills by bytes read, not by rows returned, a single wildcard SELECT in a wide staging model can silently multiply your query costs across every downstream model that references it. Here is how to find every instance in your project in under five minutes and eliminate the bleed.
This problem is more common than it should be. Engineers reach for SELECT * during prototyping — it is fast, it is flexible, and it works. The issue is that it rarely gets replaced before the model goes into production, and once it is in production it gets copied into downstream models, intermediate layers, and marts. By the time the BigQuery bill arrives, the wildcard pattern has propagated through half the DAG.
Because billing is tied to bytes scanned instead of query count or runtime, a single poorly written query run against a large table can leave you with a shockingly large bill. On BigQuery's on-demand pricing, the rate is $6.25 per TiB in U.S. regions — and that rate is applied per model run, per scheduled refresh, per downstream dependency. If your dbt project runs on a schedule and you have a SELECT * sitting inside a staging model with fifty columns that feeds four mart models, you are paying for all fifty columns four times over, every single run.
Why SELECT * Is Especially Dangerous in dbt
In a plain SQL query, SELECT * is a nuisance. In a dbt project, it is a cost amplifier.
Here is why: when you write SELECT * in a dbt model, you are not just pulling all columns for that model's output. You are telling BigQuery to read every column from the upstream source or ref every time that model materialises. If the model is materialised as a view (which is the default for many staging layers), the SELECT * is re-evaluated every time a downstream model queries it. If it is materialised as a table, the full column scan happens at materialisation time — and then every downstream model that references it gets the full column set passed through, whether it uses those columns or not.
A pattern we see repeatedly in early-stage companies: a Stripe or Segment source lands in BigQuery with 80–120 columns. A junior engineer stubs out a staging model with SELECT * to get something working quickly. That model feeds three marts, each of which feeds two dashboards. The SELECT * never gets replaced. Six months later, the team is wondering why their BigQuery bill has tripled — and the answer is sitting in a single line of SQL they wrote during a hackathon sprint.
Repeated transformations can significantly inflate costs, as each transformation run generates additional queries against the same underlying data. When SELECT * is involved, those additional queries are scanning the full column width every time.
The fix is not complicated. But you need to find the problem first.
📺 Watch: dbt Tutorial: dbt incremental models in bigquery; MERGE vs. INSERT_OVERWRITE #dbt #bigquery #sql
How to Find Every SELECT * in Your dbt BigQuery Project
There are two places to look: your dbt SQL files directly, and BigQuery's INFORMATION_SCHEMA query history.
Step 1 — Search your dbt project source files
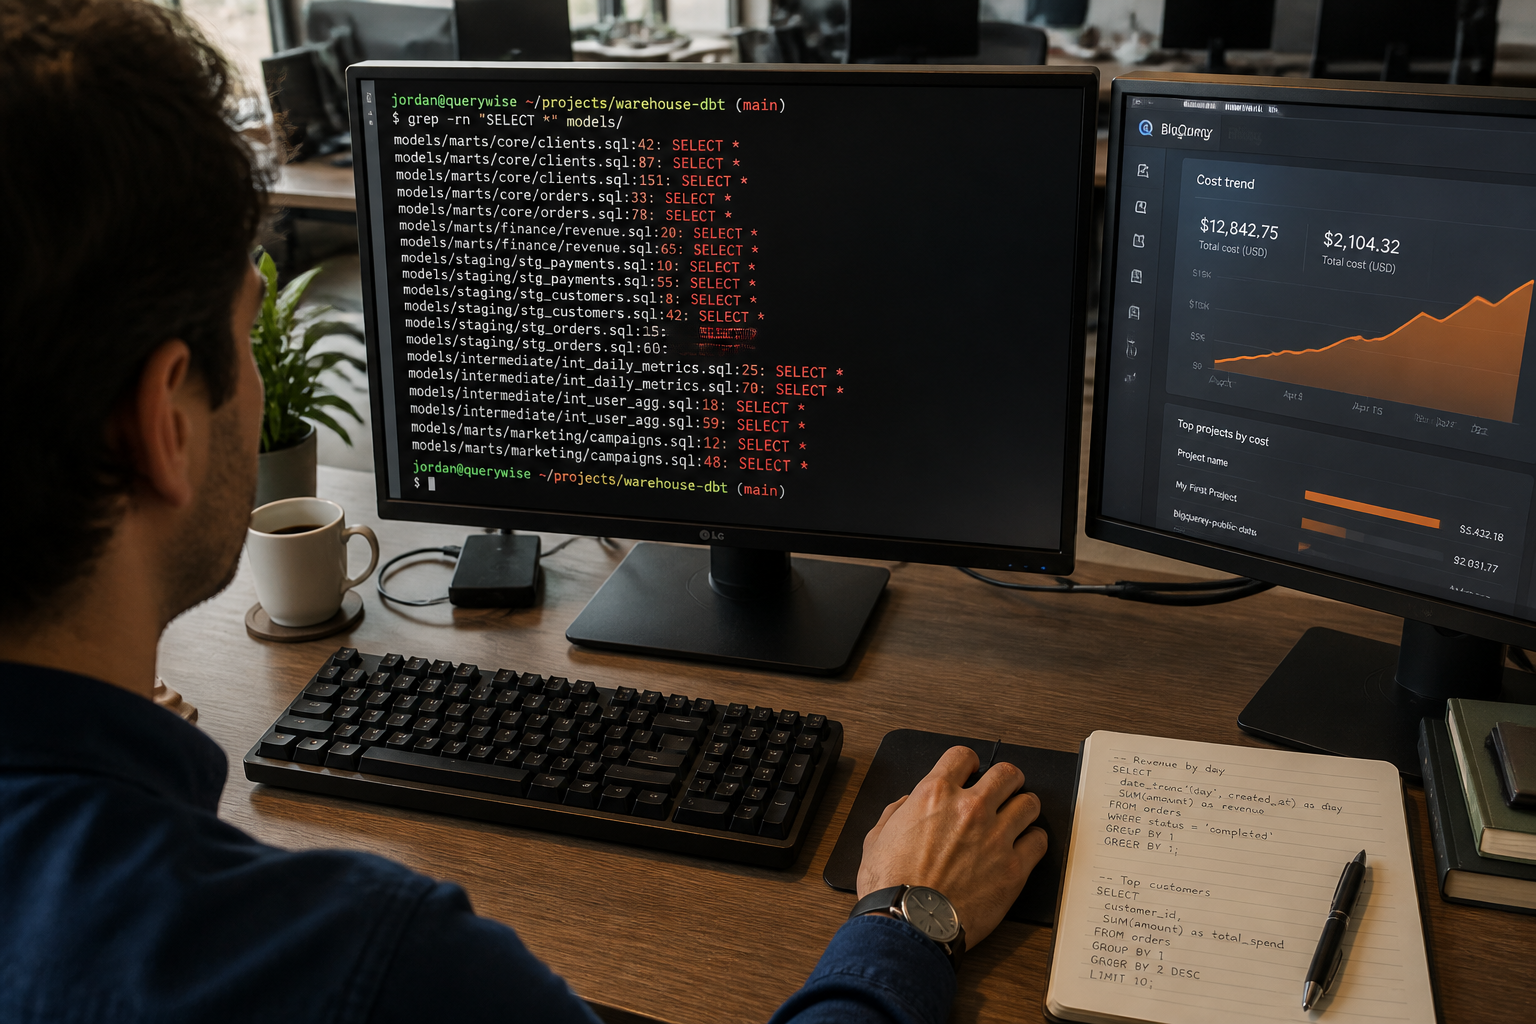
The fastest starting point is a grep across your models directory. Run this from the root of your dbt project:
grep -rn "SELECT \*" models/
This returns every file path and line number where a wildcard SELECT appears. It will catch the obvious cases — staging models that open with SELECT *, CTEs that pipe SELECT * between layers, and final SELECT * passthroughs at the bottom of a model file.
Be aware of two legitimate patterns that grep will also catch and that you should not blindly remove:
SELECT * EXCEPT (column_name)— this is intentional column exclusion and is fineSELECT * REPLACE (expression AS column_name)— also intentional
Filter these out of your list before proceeding.
Step 2 — Confirm the cost impact via INFORMATION_SCHEMA
Once you have a list of suspected models, confirm how much they are actually costing you by querying BigQuery's job history. This query returns the top offenders by bytes billed in the last 30 days, filtered to show only jobs that match your dbt model naming pattern:
SELECT
  user_email,
  REGEXP_EXTRACT(query, r'`[^`]+`\.`[^`]+`\.`([^`]+)`') AS model_name,
  SUBSTR(query, 1, 300) AS query_preview,
  COUNT(*) AS execution_count,
  ROUND(SUM(total_bytes_billed) / POW(1024, 4), 4) AS total_tib_billed,
  ROUND(SUM(total_bytes_billed) / POW(1024, 4) * 6.25, 2) AS estimated_cost_usd,
  ROUND(AVG(total_bytes_billed) / POW(1024, 3), 2) AS avg_gib_per_run
FROM
  `region-us`.INFORMATION_SCHEMA.JOBS_BY_PROJECT
WHERE
  creation_time > TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND job_type = 'QUERY'
  AND state = 'DONE'
  AND error_result IS NULL
  AND REGEXP_CONTAINS(query, r'(?i)SELECT\s+\*\s+FROM')
GROUP BY
  1, 2, 3
ORDER BY
  total_tib_billed DESC
LIMIT 30;
Replace region-us with your actual BigQuery region. The REGEXP_CONTAINS filter on SELECT\s+\*\s+FROM catches wildcard selects even when they have whitespace or newlines between SELECT and FROM. The results will show you exactly which queries are scanning the most data unnecessarily.
If a single model is appearing repeatedly in the results with a high avg_gib_per_run figure, that is your first target.
Running that query for a single model is straightforward. Auditing every model across a large dbt project is not — fintel-scan is a free, open-source MIT-licensed CLI that runs this check and fourteen others locally without a warehouse connection:
uvx fintel-scan.
How to Fix SELECT * in dbt Models Without Breaking Downstream Dependencies
Once you have identified the offending models, the fix is to replace the wildcard with an explicit column list. That sounds simple, but in practice there are three traps engineers fall into.
Trap 1 — Removing columns that downstream models reference
Before you delete a column from a staging model's SELECT list, check whether any downstream model references it. In dbt, you can do this by running:
dbt ls --select +your_staging_model_name+
This returns the full list of models that depend on the model you are editing. Cross-reference that list against the columns you are thinking of dropping. If a downstream mart references raw_metadata_json and you remove it from the staging model, the mart will fail on the next run.
For wide tables with 60+ columns, we recommend a staged approach: first add SELECT * EXCEPT (columns_confirmed_unused) as an interim step, then progressively replace with an explicit list as you confirm usage across the DAG. This is safer than a one-shot replacement and does not require you to audit every downstream model before making any change.
Trap 2 — Propagated wildcards in CTEs
GREP for SELECT * inside CTE blocks, not just at the top of a model. A common anti-pattern:
WITH base AS (
  SELECT * FROM {{ ref('stg_orders') }}
),
filtered AS (
  SELECT * FROM base WHERE status = 'completed'
)
SELECT
  order_id,
  amount
FROM filtered
The final SELECT is explicit, but BigQuery still scans all columns from stg_orders to satisfy the CTE chain. The fix is to push column selection into the first CTE:
WITH base AS (
  SELECT
    order_id,
    amount,
    status
  FROM {{ ref('stg_orders') }}
),
filtered AS (
  SELECT * FROM base WHERE status = 'completed'
)
SELECT
  order_id,
  amount
FROM filtered
Now BigQuery only reads the three columns it actually needs from stg_orders.
Trap 3 — Assuming views are free
BigQuery views do not store data — but they do execute their SQL on every query against them. If a view contains SELECT *, BigQuery scans the full upstream table every time a downstream model or dashboard queries that view. If a staging model feeds multiple downstream marts, recomputation can quietly increase BigQuery costs — persisting these models as views allows BigQuery to reuse cached results, but only when queries are deterministic and underlying data is unchanged. A SELECT * in a view breaks cache eligibility for non-deterministic queries and guarantees full column scans on every hit.
In our work with early-stage fintech and e-commerce companies, a recurring finding during data audits is a GA4 or Stripe events table — often 100+ columns wide — with a view sitting on top of it that opens with SELECT *. That view feeds five dashboards. Every dashboard load triggers a full column scan of a multi-gigabyte events table. The fix — replacing SELECT * with the twelve columns the dashboards actually use — cuts bytes billed for those dashboard queries by 80–90% in most cases.
See also: BigQuery Partitioning & Clustering Mistakes Killing Your Bill — because fixing SELECT * and ignoring partition filters will leave money on the table.
How to Prevent SELECT * From Re-entering Your dbt Project
Detecting and fixing is only half the job. The other half is making sure the pattern does not come back.
dbt project-level enforcement
Add a custom generic test in your dbt project that flags SELECT * in staging and mart models. You can also add a pre-commit hook that runs the grep check on every commit and fails if it finds an unexcepted wildcard SELECT outside of explicitly allowlisted files.
A simpler approach for smaller teams: add a note to your dbt project's CONTRIBUTING.md that SELECT * is not permitted outside of models in an explicitly named raw/ or sources/ directory — and enforce it during code review.
dbt model contracts
If your team is on dbt 1.5 or later, model contracts let you define an explicit schema for each model's output. Enforcing contracts on your staging and mart layers makes it structurally impossible for SELECT * to propagate silently — if the output schema does not match the contract, the model fails at compile time rather than at query time.
Query cost monitoring via INFORMATION_SCHEMA
Set up a scheduled query or dbt model that runs the INFORMATION_SCHEMA diagnostic above on a weekly basis and sends results to a Slack alert if any model exceeds a bytes-billed threshold you define. This gives you a repeating safety net without requiring manual audits.
For teams managing costs more broadly, pairing this with maximum_bytes_billed set at the dbt profile or connection level adds a hard circuit-breaker: when you set maximum bytes billed, the number of bytes that the query reads is estimated before execution — if the estimated bytes exceed the limit, the query fails without incurring a charge. This will not catch every SELECT * pattern, but it will catch the catastrophic ones before they hit your bill.
For a related issue that compounds the SELECT * problem in wide event tables, see dbt UNNEST Without Filters in BigQuery: Fix the Row Explosion — combining SELECT * with an unfiltered UNNEST is one of the most expensive patterns we encounter in the field.
Frequently Asked Questions
Q: Does SELECT * always increase BigQuery costs?
A: Yes, in practice. BigQuery's columnar storage means it only reads the columns referenced in a query. SELECT * forces it to read every column, regardless of how many the query actually needs. On wide tables — event logs, raw API payloads, GA4 exports — this can mean scanning 10–100x more data than an explicit column list would require.
Q: Is SELECT * safe in dbt ephemeral models?
A: It is less dangerous in ephemeral models because they are inlined as CTEs rather than materialised as tables — but the underlying column scan still happens. If an ephemeral model with SELECT * is referenced by multiple downstream models, BigQuery scans the full upstream table multiple times. Replace the wildcard with an explicit column list even in ephemeral models.
Q: How do I find which columns are actually used downstream in a large dbt project?
A: Run dbt ls --select +model_name+ to get all dependent models, then grep those model files for column references. For large projects, dbt's built-in --select and --exclude flags combined with dbt compile output let you inspect the rendered SQL to see exactly which columns are being referenced after Jinja resolution. The fintel-scan CLI can also surface unused column patterns across the project without a warehouse connection.
Q: Will removing SELECT * break my dbt tests?
A: Only if your tests reference columns that you remove from the SELECT list. Run dbt test --select model_name after making changes to catch any broken column-level tests. If you use schema.yml column-level tests (not_null, accepted_values, relationships), those will fail at test time if the column no longer exists in the model output — which is a safe failure mode that catches the problem before it reaches production.
Q: What is the fastest way to estimate how much SELECT * is costing me right now?
A: Run the INFORMATION_SCHEMA query in the "How to Find Every SELECT * in Your dbt BigQuery Project" section above. Filter to the last 7 days, sort by total_tib_billed descending, and multiply by $6.25 per TiB. That gives you the floor — the actual cost is likely higher once you account for repeated runs across scheduled refreshes and downstream view evaluations.
If your BigQuery bill has been climbing without a clear explanation, SELECT * is one of the first places to look — and it is almost always fixable within a single sprint. At Fintel Analytics, we have identified and eliminated this exact pattern across dbt projects at fintech startups, e-commerce businesses, and payments platforms, and the cost reductions are consistently material: in one case, replacing wildcard selects across six staging models cut weekly bytes billed by over 70%. If your team suspects the problem exists but does not have the bandwidth to track it down and fix it cleanly, that is exactly the kind of hands-on audit and remediation work we do.