
BigQuery partitioning and clustering mistakes are responsible for a significant share of runaway cloud bills at growth-stage companies — not missing partitions, but broken ones. If your tables are already partitioned yet your bill keeps climbing and your dashboards are slow, the problem is almost certainly a silent pruning failure, not a missing feature.
This post is for data engineers, analytics engineers, and technical founders who have implemented partitioning and clustering in BigQuery but are still seeing costs they cannot explain. We will cover the six mistakes that kill the value of your table design, why each one happens, and exactly what to fix.
Why Does BigQuery Partitioning Fail Even When It's Set Up?
The core of BigQuery's cost model is deceptively simple: you pay for data scanned, not for query execution time. Partitioning and clustering reduce costs directly by reducing scan volume — but only when the query engine can actually use them.
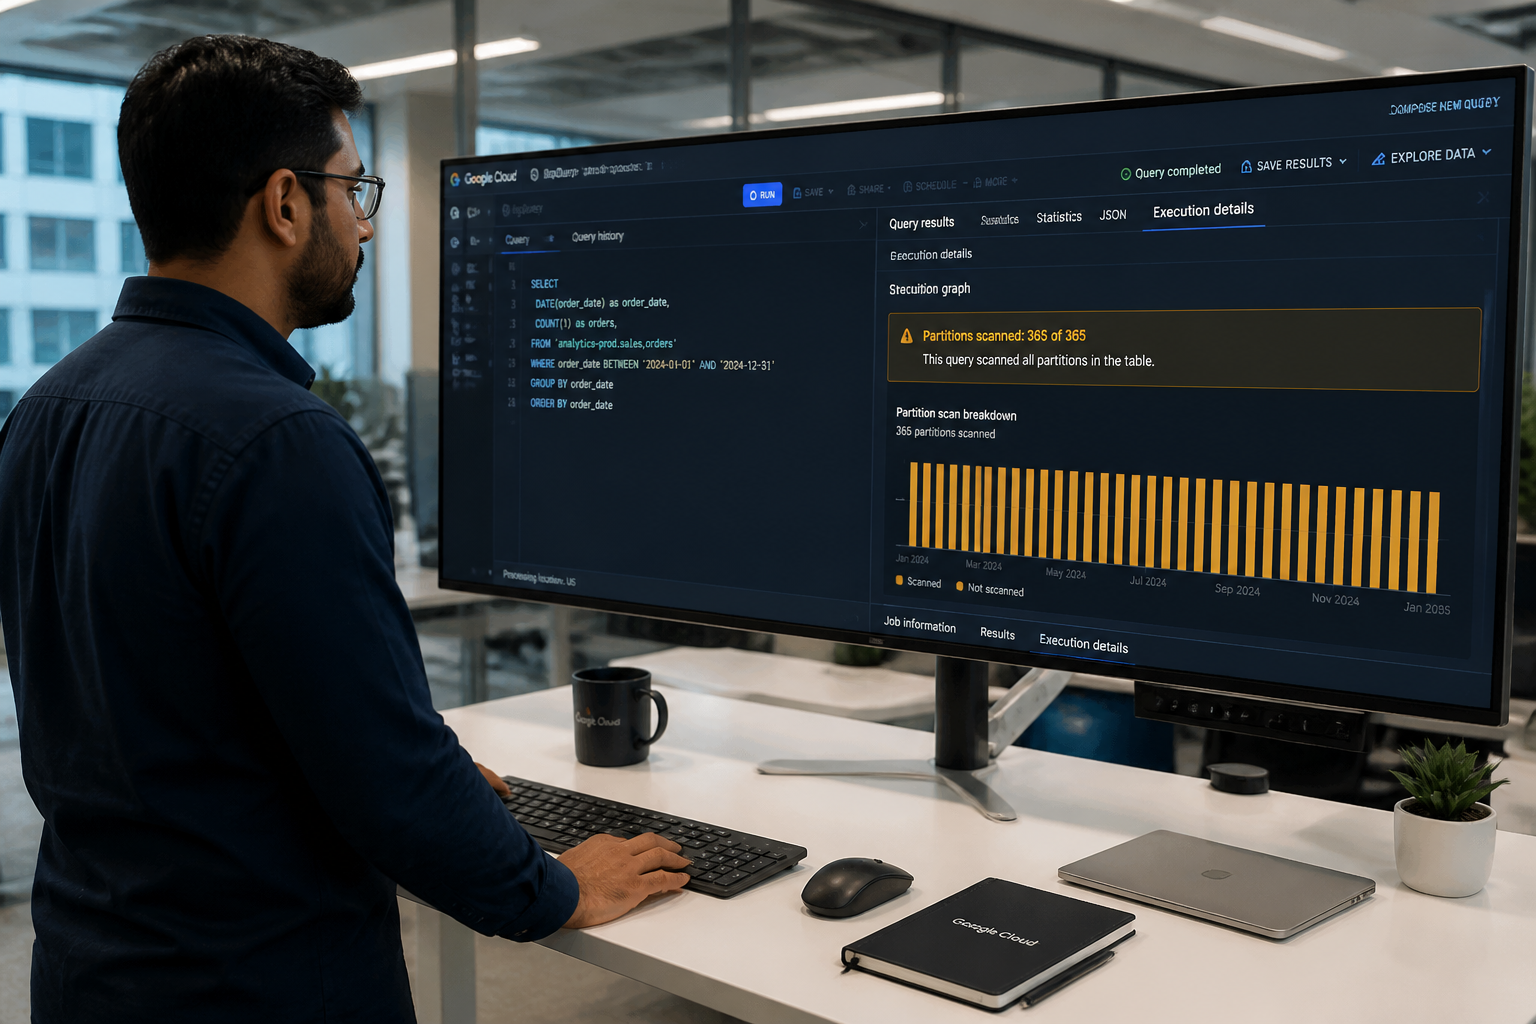
The failure mode is equally simple: your table is partitioned, your analysts write queries with date filters, and you assume pruning is happening. In many cases, it isn't. BigQuery's query execution logs will show "Partitions scanned: 365 of 365" on a query that was supposed to touch a single day. Every partition, scanned. Full cost, every time.
This is the pattern we see repeatedly when we audit analytics infrastructure for Series A and Series B companies that have scaled faster than their data engineering practices. The tables look correct. The schema looks fine. The filters are present. But something in the filter expression, the model structure, or the dbt configuration has silently disabled pruning — and the bill tells the story months later.
As of 2026, BigQuery charges $6.25 per TB scanned on-demand. A single SELECT * on a 10 TB table costs $62.50 instantly. A dashboard refreshing every 15 minutes on unoptimised tables can cost $9,000 per month. Fixing partition and clustering configuration properly can cut query costs by 60–90%.
📺 Watch: BigQuery Partitioning & Clustering Explained | Reduce Cost & Boost Query Performance 🚀
Mistake 1: Wrapping the Partition Column in a Function
This is the single most common and expensive mistake we encounter, and it is entirely invisible unless you check the execution plan.
Suppose your table is partitioned on DATE(event_timestamp). An analyst writes:
SELECT *
FROM analytics.events
WHERE DATE(event_timestamp) BETWEEN '2026-01-01' AND '2026-01-07'
This looks correct. It is not. BigQuery sees the filter as operating on the output of a function applied to event_timestamp, not on the underlying partition column directly. It cannot apply partition pruning through a function wrapper. The result: all partitions are scanned.
The correct approach depends on how the table was partitioned:
-
If partitioned on
DATE(event_timestamp): filter directly on the raw timestamp column using a range, not aDATE()function -
If partitioned on a
DATEcolumn: filter on that column directly without wrapping it-- CORRECT: filter on raw timestamp if partitioned by DATE(event_timestamp) WHERE event_timestamp >= '2026-01-01' AND event_timestamp < '2026-01-08'
-- WRONG: wrapping in DATE() defeats pruning WHERE DATE(event_timestamp) BETWEEN '2026-01-01' AND '2026-01-07'
The same logic applies to clustered columns. If you have clustered on customer_id and your filter is WHERE LOWER(customer_id) = 'abc123', BigQuery treats this as a new, unknown column and skips all block-level elimination.
In dbt, this problem surfaces when analysts query marts directly rather than through the semantic layer, and the models themselves are built with function-wrapped filters in their incremental predicates. The fix is to transform timestamp columns to the appropriate type before materialisation, then filter on the clean column downstream.
Mistake 2: Clustering Without Partition Pruning First
Clustering is frequently treated as a standalone fix, applied to tables that have poor partitioning — or no partitioning at all. This is a misunderstanding of how the two mechanisms interact.
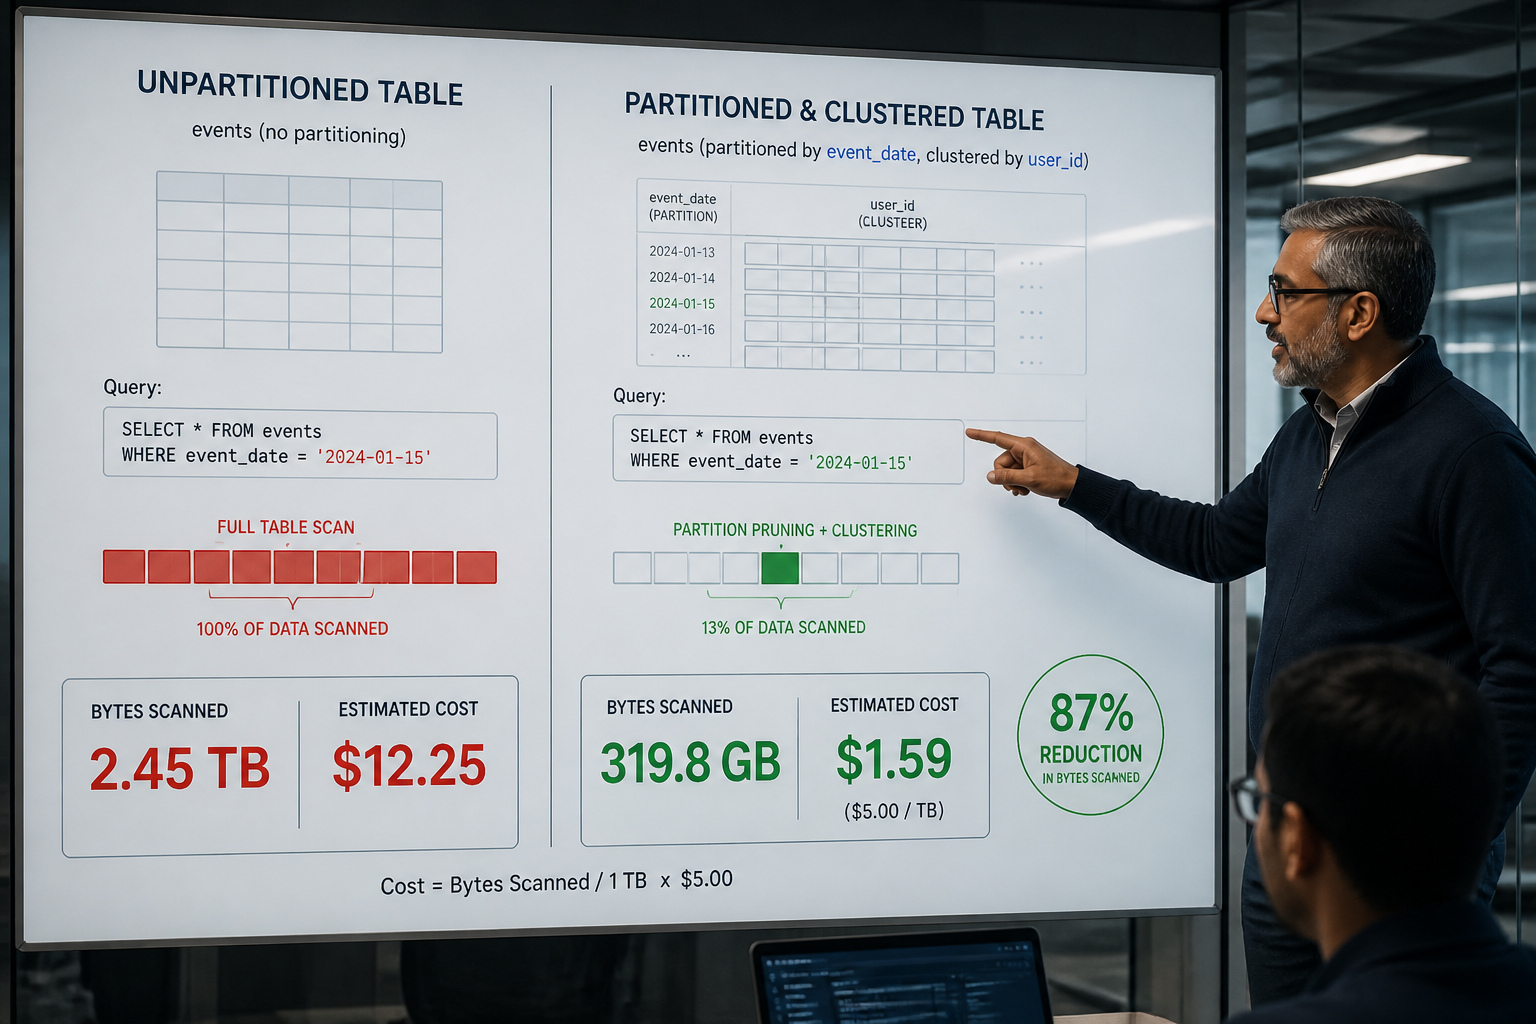
Clustering organises rows within each partition by the values of your clustered columns, allowing BigQuery to skip blocks during a scan. But if partition pruning is not working — if all 365 partitions are being scanned — clustering can only reduce the bytes read within the full scan. The savings are marginal compared to what combined pruning delivers.
In benchmark analysis of production BigQuery tables, clustering alone on a non-pruned table shows negligible byte reduction (~1%) compared to a correctly pruned and clustered table, which can reduce scan volume by 90% or more. The real magic, as practitioners consistently find, comes from combining them: partition pruning eliminates irrelevant partitions first, then clustering eliminates irrelevant blocks within the surviving partitions.
The correct sequence when designing a BigQuery table for an analytics workload:
- Identify the most common time-range filter in production queries — this is your partition column
- Confirm that partition pruning is provably working by checking execution details in the query plan
- Then identify the next 2–4 highest-cardinality filter columns used across dashboards and SQL models — these become your clustering columns, applied left to right in order of selectivity
If you are using dbt, your config block should declare both explicitly:
{{ config(
    materialized='table',
    partition_by={
      "field": "event_date",
      "data_type": "date",
      "granularity": "day"
    },
    cluster_by=["country", "product_category"]
) }}
For teams building dbt incremental models on top of large event tables, getting this wrong compounds quickly — each model run scans more data than necessary, and the downstream dashboards inherit the same inefficiency. If your incremental models are already causing headaches, the dbt Incremental Models Strategy guide covers when and how to apply them correctly.
Mistake 3: No require_partition_filter Enforcement
This one is a governance failure as much as a technical one — and it is exactly the kind of thing that disappears into a growing data team.
When a table has require_partition_filter set to FALSE (the default), any analyst or automated process can run an unfiltered query against it. SELECT * FROM events on a 5 TB table will scan all 5 TB without warning. There is no guardrail.
The fix is a single DDL statement:
ALTER TABLE `project.dataset.events`
SET OPTIONS (require_partition_filter = TRUE);
Once this is set, any query without a valid partition filter on that table throws an error rather than silently scanning the full dataset. This is not just a cost control — it is a quality signal. If a query breaks after you enable this option, that query was always doing a full scan. Now you know.
We enforce this as a standard on every table above 1 GB in production environments. The first time a scheduled query or BI tool breaks because of it, you find out that some process has been doing full scans in the background for months. We have seen dashboards that looked fine — refreshing on schedule, returning correct results — that were scanning hundreds of GB per day unnecessarily because no one had enforced this setting.
For teams looking to build systematic controls around this and related BigQuery governance issues, explore how Fintel Analytics approaches data engineering delivery — we implement these guardrails as part of every production data stack we build.
Mistake 4: Wrong Partition Granularity for Your Query Patterns
BigQuery supports four time-partition granularities: HOUR, DAY, MONTH, and YEAR. Most teams default to DAY without checking whether it matches actual query patterns.
The mismatch problem works in both directions:
Too fine (HOUR on a dataset queried by week or month): You end up with thousands of partitions, each very small. BigQuery's partition metadata overhead increases. Queries that span 30 days now need to open 720 hourly partitions rather than 30 daily ones. Performance can degrade relative to daily partitioning, and partition expiry management becomes complex.
Too coarse (MONTH on a dataset where analysts frequently query single days): You have gained almost nothing. A query for "yesterday" still scans the entire month's partition. The pruning benefit collapses.
The correct granularity is derived from the smallest time window your most common queries filter to. If 80% of production queries look at "last 7 days" or "last 30 days", DAY is almost always correct. If queries nearly always span full quarters, MONTH partitioning may be a better fit.
This should be a deliberate design decision, not a default. When we onboard a new client and audit their BigQuery project, misconfigured partition granularity — usually DAY partitioning on a dataset where the dominant access pattern is monthly — is consistently in the top three cost inefficiencies we find.
The related issue: old partitions that were never given an expiry. Partition expiration is set per table and tells BigQuery to automatically drop partitions older than N days. Without it, staging tables and log tables accumulate years of data in storage, accruing storage costs that compound quietly. For staging tables, 7 days is usually sufficient. For production fact tables, align with your data retention policy and compliance requirements.
Mistake 5: Clustering Column Order Chosen Arbitrarily
BigQuery applies clustering columns left to right. This is not a footnote — it is the mechanism by which block elimination works, and choosing the wrong order materially changes which queries benefit.
Suppose you cluster on [product_category, country, user_id]. A query filtering only on country receives minimal benefit because product_category — the leftmost column — was not in the filter. BigQuery has to read blocks from every product category to find the country-filtered rows.
The rule is straightforward: the column that appears most frequently in WHERE clauses across your production query patterns goes leftmost. Then the next most frequent, and so on. For an e-commerce event table, this is often [event_date, country, product_category] — but the right answer depends on your actual workload, not on what feels logical from a schema perspective.
In practice, the way to get this right is to pull the top 20 queries by bytes scanned from INFORMATION_SCHEMA.JOBS over a 30-day window, identify which columns appear most frequently in filter conditions, and rank by that frequency. That ranking is your cluster column order.
This is particularly important in multi-tenant SaaS or payments contexts where tenant or merchant identifiers are almost always in every query — merchant_id or tenant_id should typically be the leftmost clustering column on any table that has it, because it eliminates the largest share of irrelevant data for the widest range of queries.
Mistake 6: Streaming Inserts Bypassing Partition Benefits
This final mistake is architectural, and it catches teams who have otherwise done everything correctly.
When data is inserted into BigQuery via streaming inserts (the Storage Write API in streaming mode), it first lands in an internal buffer called the streaming buffer. Data in this buffer is not yet part of any partition — it is unpartitioned and unclusterable for queries until BigQuery flushes it into the physical table structure, which happens in the background on its own schedule.
For tables with very recent data freshness requirements — think fraud monitoring, real-time payment dashboards, or operational alerting — queries filtering for "the last hour" will still hit the streaming buffer and bypass all partition and clustering benefits on that slice of data. Batch loads, by contrast, write directly into the correct partition from the moment they complete.
The cost implication is also significant: streaming inserts cost $0.01 per 200 MB ingested ($50 per TB), while batch loading from Google Cloud Storage is free. Teams that default to streaming because it feels like the "real-time" choice — without an actual sub-minute freshness requirement — are paying 50x the ingestion cost for data that still has a clustering delay on read.
For most analytics use cases, a micro-batch approach — buffering records and loading every 5 to 10 minutes — delivers near-real-time freshness at zero ingestion cost, with full partition and clustering benefits the moment each batch lands.
Frequently Asked Questions
Q: How do I check whether partition pruning is actually working in BigQuery?
A: Open the execution details for your query in the BigQuery console. Look for the "Partitions scanned" figure. If a query filtering a single day shows "365 of 365" partitions scanned, pruning is not working. The cause is almost always a function-wrapped partition column in the WHERE clause, or a filter referencing a column that does not match the declared partition field.
Q: What is the difference between BigQuery partitioning and clustering, and which should I use?
A: Partitioning divides a table into physical segments by a column value (typically a date), allowing BigQuery to skip entire partitions. Clustering physically sorts data within each partition by up to four columns, allowing BigQuery to skip blocks. Both reduce bytes scanned and therefore cost. Use them together: partition first on your primary time dimension, then cluster on your most-filtered categorical columns. Neither replaces the other.
Q: How many clustering columns should I use in BigQuery?
A: BigQuery supports up to four clustering columns. The practical rule is to use as many as reflect distinct, frequently used filter patterns in your workload — but no more. Every column you add must appear in real queries to provide value. More is not always better: a fourth clustering column that only appears in 5% of queries adds metadata overhead without meaningful scan reduction.
Q: Does BigQuery partitioning and clustering affect dbt model builds?
A: Yes. Partition and cluster configuration in dbt's config block controls how the underlying BigQuery table is materialised. Incorrect configuration — especially function-wrapped partition fields or wrong granularity — affects not only dashboard query costs but also the cost and speed of each dbt model run. For incremental models, the partition_by config directly controls which partitions are reprocessed on each run, making correct setup critical to controlling pipeline compute costs.
Q: How much can BigQuery partitioning and clustering actually reduce query costs?
A: When implemented correctly with valid partition pruning and well-ordered clustering, BigQuery's own documentation and independent benchmarks consistently show 60–90% reductions in bytes scanned for filter-heavy analytical queries on large tables. The actual saving depends on your data distribution and query patterns. Teams querying more than 20–30 TB per month should also evaluate whether switching from on-demand to capacity (BigQuery Editions) pricing delivers additional savings on top of the structural optimisations.
Conclusion
The most expensive BigQuery mistake is not failing to partition your tables — it is believing that partitioning them is enough. Silent pruning failures, wrong granularity choices, unenforced partition filters, and streaming buffer bypasses can quietly negate every optimisation you have implemented, leaving you with a bill that climbs regardless of how clean your schema looks. At Fintel Analytics, we audit and rebuild BigQuery data stacks for growth-stage companies across fintech, payments, and e-commerce — and the pattern is consistent: the teams with the highest per-query costs are not the ones who skipped partitioning, they are the ones who set it up once and never verified it was actually working. If your BigQuery bill is trending in the wrong direction and your query plans are a black box, that is a solvable problem — and solving it typically pays back the effort within the first billing cycle.