 Fintel Analytics
Postgres Table Bloat: Find Dead Tuples Slowing Your Queries
Queries on a Postgres table getting slower while the data barely grows? Here is the SQL to find dead tuples, the blockers behind them, and the fix.
Postgres table bloat is the space taken up by dead row versions that VACUUM has not been able to reclaim, so tables and indexes grow far beyond the size of their live data. To find it, rank your tables by dead tuples in pg_stat_user_tables, confirm the worst offenders with pgstattuple, then check what is stopping autovacuum from cleaning up: usually a long-running transaction, a stale replication slot, or a scale factor that is too lax for the table's size.
The symptom people search for is rarely the word bloat. It is a query that was fast six months ago and is now slow, on a table whose row count has barely moved. Or a disk-usage alert on a database that nobody thinks is that big. A pattern we see repeatedly in growth-stage companies is a Postgres instance that started as the application database and quietly became the analytics database too, with a BI tool pointed straight at it. Status columns get updated constantly, dashboards hold long queries open, and autovacuum quietly falls behind. Nobody notices until the finance dashboard times out on month-end.
This post is the fix, not the theory. Run the queries below and you will know in under five minutes whether bloat is your problem.
How Do You Know Postgres Table Bloat Is Slowing Your Queries?
Bloat is worth investigating when three things line up:
- Sequential scans got slower without the data growing. Postgres reads pages, not rows. A table full of dead tuples means more pages to read for the same visible result.
- Disk usage grows faster than business volume. Heavily updated tables (orders, payments, ledger status rows, job queues) are the usual culprits, because in Postgres an UPDATE writes a new row version and leaves the old one behind until vacuum clears it.
last_autovacuumis old or null on a busy table. Autovacuum either is not triggering or is triggering and not finishing useful work.
One caveat before the queries: n_dead_tup is a statistics-collector estimate, not an exact count, and it resets after a crash or a manual stats reset. Treat it as a ranking signal, then confirm with a precise tool.
📺 Watch: PostgreSQL Table Bloat: VACUUM Won't Save You
How Do You Find Postgres Table Bloat With SQL?
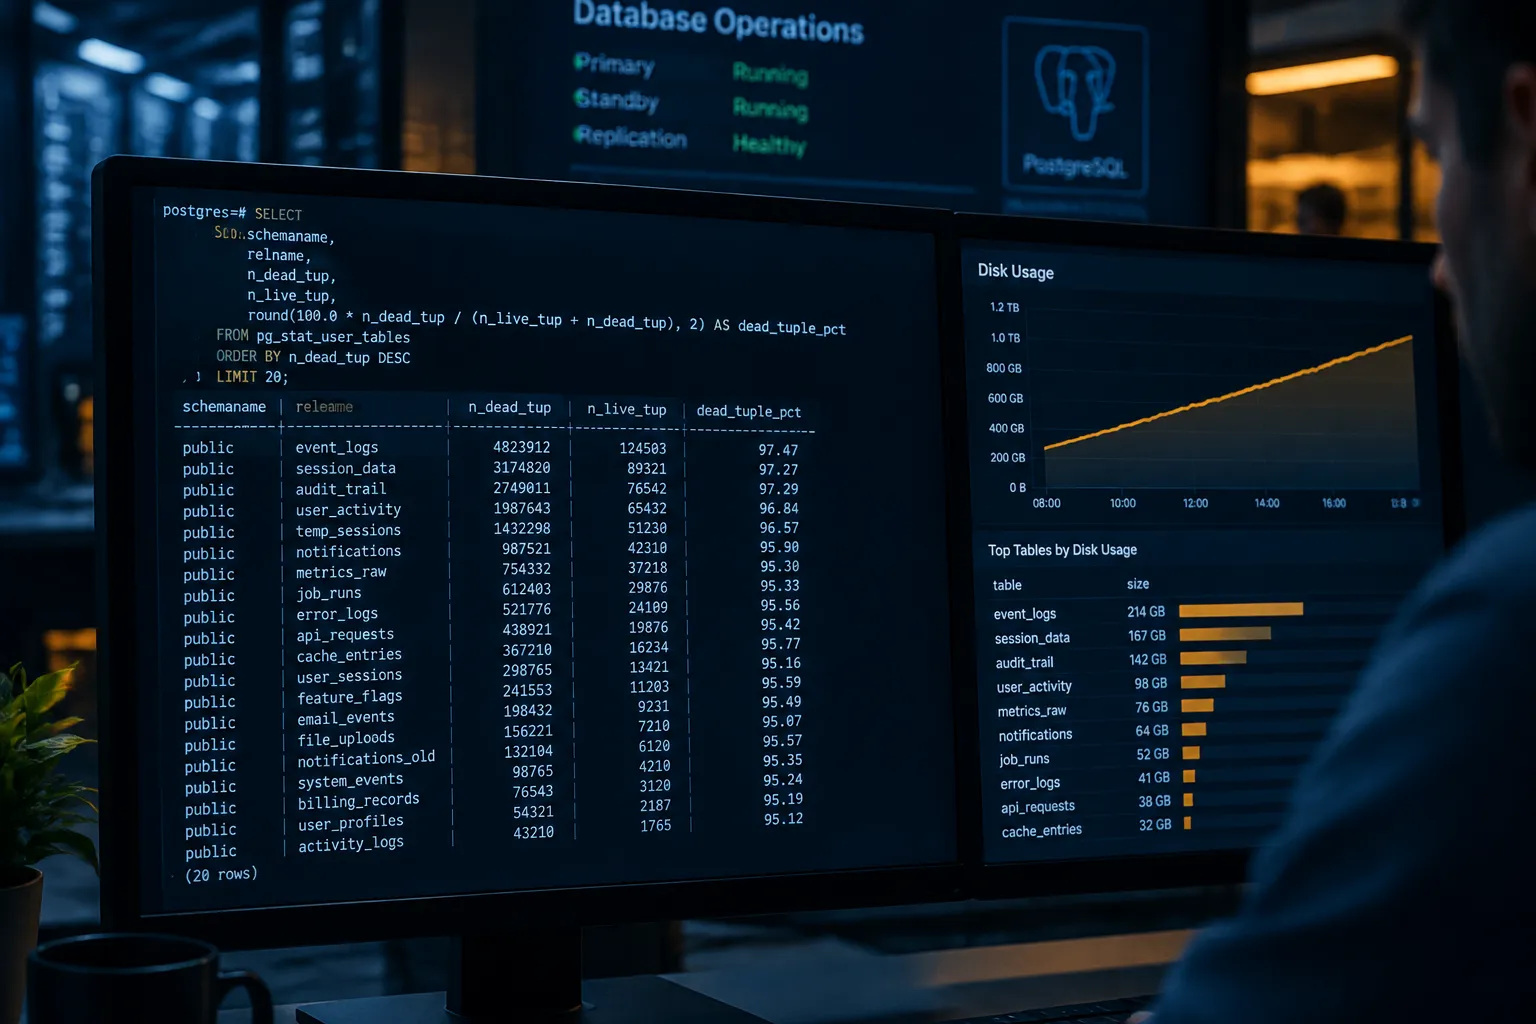
Start with the cheap query. It ranks user tables by dead tuples, shows the dead percentage, and tells you when autovacuum last touched each one.
SELECT
  schemaname,
  relname,
  n_live_tup,
  n_dead_tup,
  round(100.0 * n_dead_tup / nullif(n_live_tup + n_dead_tup, 0), 1) AS dead_pct,
  last_autovacuum,
  last_autoanalyze,
  pg_size_pretty(pg_total_relation_size(relid)) AS total_size
FROM pg_stat_user_tables
WHERE n_dead_tup > 10000
ORDER BY n_dead_tup DESC
LIMIT 20;
As a rough working rule, anything above 10 to 20 percent dead on a table that queries read heavily deserves a closer look. A large table with a high absolute dead count and a stale last_autovacuum is the one to chase first.
Next, check whether autovacuum is even meant to be running on those tables. This compares each table's dead tuples against its trigger point and shows any per-table overrides:
SELECT
  s.relname,
  s.n_dead_tup,
  (current_setting('autovacuum_vacuum_threshold')::int
    + current_setting('autovacuum_vacuum_scale_factor')::float * c.reltuples
  )::bigint AS default_trigger_point,
  c.reloptions
FROM pg_stat_user_tables s
JOIN pg_class c ON c.oid = s.relid
WHERE s.n_dead_tup > 10000
ORDER BY s.n_dead_tup DESC;
The reason this matters is arithmetic. The default scale factor is 0.2, or 20% of table size, so a 100M-row table waits for 20M dead tuples before vacuum runs. That is fine for a small lookup table and painful for a big, hot one. If n_dead_tup is sitting just below default_trigger_point on your largest tables, you have found your cause without going any further.
To get an exact measurement for a suspect table, use the pgstattuple extension:
CREATE EXTENSION IF NOT EXISTS pgstattuple;

SELECT table_len, dead_tuple_count, dead_tuple_percent, free_percent
FROM pgstattuple('public.orders');
pgstattuple reads the whole table, so on anything large use the sampled version instead, SELECT * FROM pgstattuple_approx('public.orders');, and run either one off-peak. High free_percent with a low dead percentage means vacuum has already done its job, but the file has not shrunk. That is bloat in the disk-space sense, and it needs a different fix, covered below.
Running those queries for one database is fine. If your analytics stack also includes a dbt project, fintel-scan is a free, open-source (MIT) CLI that runs fifteen static checks across a project locally, with no warehouse connection: uvx fintel-scan. It will not read your Postgres statistics, so the SQL above is still the way to diagnose bloat itself.
Why Is Autovacuum Not Cleaning Up Your Bloated Tables?
This is the question that separates a one-off cleanup from a permanent fix. If autovacuum runs and dead tuples stay high, something is holding back the cleanup horizon. VACUUM can only remove a dead row version once no open transaction could still need to see it. Three things commonly pin that horizon.
1. Long-running or idle-in-transaction sessions. This is the classic BI-tool problem: a dashboard connection opens a transaction, runs a heavy query, and sits there. Find them:
SELECT
  pid,
  usename,
  application_name,
  state,
  now() - xact_start AS xact_age,
  left(query, 80) AS query
FROM pg_stat_activity
WHERE xact_start IS NOT NULL
ORDER BY xact_start
LIMIT 10;
Anything in state idle in transaction for minutes or hours is a vacuum blocker. If the top rows belong to your BI role, our guide to finding slow Postgres queries caused by your BI tool shows how to trace them back to specific dashboards.
2. Stale or inactive replication slots. Logical replication slots, including the ones feeding a CDC pipeline into your warehouse, retain old row versions and WAL until the consumer catches up. A consumer that has been switched off but whose slot still exists is a silent bloat generator and a disk-space risk:
SELECT
  slot_name,
  slot_type,
  active,
  age(xmin) AS xmin_age,
  age(catalog_xmin) AS catalog_xmin_age,
  restart_lsn
FROM pg_replication_slots
ORDER BY greatest(age(xmin), age(catalog_xmin)) DESC NULLS LAST;
An inactive slot with a large age is a prime suspect. Drop it with SELECT pg_drop_replication_slot('slot_name'); only once you are certain nothing will consume it again.
3. A scale factor that is wrong for the table. On PostgreSQL 17 and earlier, the guidance from Postgres specialists is to set a per-table scale factor of 0.02 or smaller on tables over a few million rows. PostgreSQL 18 helps here: it adds autovacuum_vacuum_max_threshold, and the default cap is 100,000,000 tuples. That default is generous, though. A table where 100 million dead rows is itself unacceptable still needs deliberate tuning.
In one engagement with a payments company, the bloat was concentrated in a single high-churn status table. Autovacuum was running, but a long-lived reporting connection kept the cleanup horizon pinned, so every pass reclaimed almost nothing. Tuning autovacuum would have changed nothing. Fixing the session behaviour did.
How Do You Fix Postgres Table Bloat Without Downtime?
Order matters. Remove the blocker first, then tune, then reclaim space.
Step 1: Clear the blockers. Terminate or fix the idle-in-transaction sessions and drop dead replication slots, using the queries above. Without this, nothing else sticks.
Step 2: Make autovacuum fire earlier on the hot tables. Per-table storage parameters can override these server-wide settings, so you do not need to change the whole instance:
ALTER TABLE public.orders SET (
  autovacuum_vacuum_scale_factor = 0.02,
  autovacuum_vacuum_threshold = 5000,
  autovacuum_vacuum_cost_limit = 1000
);
The cost limit matters more than people expect. Autovacuum is throttled by default, and on a busy table it can be technically running but too slow to keep up.
Step 3: Run a manual vacuum to catch up.
VACUUM (VERBOSE, ANALYZE) public.orders;
Plain VACUUM makes dead space reusable, and it does not block reads or writes. What it generally does not do is return disk space to the operating system. That is why people run it, see no change in table size, and conclude it did not work.
Step 4: Reclaim disk only if you truly need to. If pgstattuple shows large free space and you need the disk back, you have two options. VACUUM FULL rewrites the table but takes an ACCESS EXCLUSIVE lock, blocking all reads and writes for the duration, which is rarely acceptable on a live table. The pg_repack extension rebuilds a table and its indexes while keeping it available, apart from brief locks at the start and end. Check that your managed Postgres provider supports it before you plan around it. Often the better answer is to leave the space reusable: if the table is not shrinking in volume, the freed pages will be filled by new rows anyway.
While you are in there, remember that indexes bloat too, and unused ones add write cost on every update. Our walkthrough on finding and dropping unused Postgres indexes safely pairs well with this cleanup.
How Do You Stop Postgres Table Bloat Coming Back?
A cleanup without guardrails lasts a quarter. Three controls keep it from recurring.
Cap how long BI and reporting sessions can hold a transaction open. Set it on the role, not the server, so you do not break application behaviour:
ALTER ROLE bi_reader SET idle_in_transaction_session_timeout = '60s';
ALTER ROLE bi_reader SET statement_timeout = '5min';
Move analytical reads off the primary. A read replica removes dashboard snapshots from the primary's vacuum horizon. Be aware that hot_standby_feedback can push replica query pressure back onto the primary, so check that setting deliberately instead of leaving it at whatever the last engineer chose.
Alert on the ranking query, not on disk. Disk alerts fire after the damage. Schedule the first query in this post, store the output daily, and alert when any table crosses a dead-percentage threshold you have chosen for it. Use the same discipline for replication slots: set max_slot_wal_keep_size so an abandoned consumer cannot fill the disk, and add a check for inactive slots.
The broader lesson matches what we see with warehouse cost problems generally: the fix is rarely a clever setting. It is visibility plus a boundary. If your analytics layer is still reading directly from an operational database, the longer-term answer is replicating into a proper warehouse and serving dashboards from modelled tables, not from live transactional tables.
Frequently Asked Questions
Q: What causes Postgres table bloat?
A: Postgres keeps old row versions after every UPDATE or DELETE until VACUUM removes them. Bloat builds up when vacuum cannot keep pace or cannot clean up, typically because of long-running transactions, inactive replication slots, or autovacuum thresholds that are too high for a large table.
Q: How do I check for Postgres table bloat?
A: Query pg_stat_user_tables and order by n_dead_tup to get a fast ranking, then confirm suspect tables with pgstattuple or pgstattuple_approx for exact dead and free space percentages. Check last_autovacuum too: a stale value on a busy table is a strong warning sign.
Q: Does VACUUM reduce table size?
A: Usually not. Plain VACUUM marks dead space as reusable inside the table file but typically does not return it to the operating system. To shrink the file you need VACUUM FULL, which locks the table, or pg_repack, which rebuilds it online.
Q: Why is autovacuum running but my table is still bloated?
A: Something is holding back the cleanup horizon. Check pg_stat_activity for long or idle-in-transaction sessions and pg_replication_slots for inactive slots. Until those are cleared, vacuum cannot remove the dead rows however often it runs.
Q: What is a safe autovacuum scale factor for large tables?
A: The default of 0.2 is slow for big, frequently updated tables. On PostgreSQL 17 and earlier, a per-table value of 0.02 or lower is a common starting point for tables over a few million rows. On PostgreSQL 18, the new maximum threshold cap helps, but very hot tables may still need individual tuning.
Conclusion
Postgres table bloat is a slow, boring failure: dashboards creep from fast to sluggish, storage costs drift upward, and the real blocker is often a connection or replication slot nobody remembered. At Fintel Analytics, we have helped fast-growing fintech, payments and e-commerce teams trace exactly this kind of problem, from a BI tool hammering a production database through to a clean, modelled warehouse layer with query governance and alerting in place. If your analytics are still running against an operational Postgres instance and performance is getting worse each quarter, that is a fixable problem, and it is far cheaper to fix before it takes down a month-end close.