 Fintel Analytics
Find Slow Postgres Queries Caused by Your BI Tool (SQL)
Dashboards hitting your production Postgres database can slow your whole product. Here is the SQL to find the culprit queries in five minutes, fix them and keep them from coming back.
To find slow Postgres queries caused by a BI tool, enable the pg_stat_statements extension and rank queries by total_exec_time. Then separate dashboard traffic from application traffic by giving the BI tool its own database role. Confirm the worst offenders with EXPLAIN (ANALYZE, BUFFERS) and fix them with an index, a materialised view or a read replica. The diagnosis takes about five minutes.
Postgres is where most growth-stage companies start their analytics, simply because it is already there. The 2025 Stack Overflow survey found PostgreSQL used by 58.2% of professional developers, so there is a good chance your product database is Postgres and your first dashboards were pointed straight at it. That works until the day checkout latency creeps up at 9am on Monday, exactly when finance opens the weekly report. This post shows how to find the queries responsible, prove it, and fix it without a rewrite.
Why Do BI Dashboards Slow Down a Production Postgres Database?
A transactional database is tuned for many small, indexed lookups. A dashboard does the opposite: it scans large ranges of rows, aggregates them and does it again every time someone opens the page or a refresh schedule fires. Three patterns cause most of the damage we see:
- Sequential scans on large tables. A filter on an unindexed timestamp or status column forces Postgres to read the whole table for every tile on the dashboard.
- Refresh schedules multiplied by tiles. One dashboard with twelve tiles refreshing every 15 minutes is 48 queries an hour. Ten dashboards is nearly 500, whether anyone is looking or not.
- Sessions left open. Some BI tools hold connections idle inside a transaction. That blocks autovacuum from cleaning dead rows and slowly degrades everything else.
A pattern we see repeatedly in early-stage fintech and e-commerce companies is that the first symptom is not a slow dashboard. It is a slow product, and the engineering team spends a week blaming the application before anyone looks at who else is querying the database.
📺 Watch: 51 - PostgreSQL : Slow long running and blocked queries in PostgreSQL
How Do You Find Slow Postgres Queries With pg_stat_statements?
pg_stat_statements records cumulative execution statistics for every normalised query. It must be listed in shared_preload_libraries, which needs a restart on self-managed Postgres or a parameter-group change on managed services. Once that is done, create the extension:
CREATE EXTENSION IF NOT EXISTS pg_stat_statements;
Now rank queries by the total time they have cost your database, not by how slow a single run was. A 200ms query that runs 50,000 times a day hurts far more than a 20-second query that runs once.
SELECT
  r.rolname AS role_name,
  s.calls,
  round((s.total_exec_time / 1000)::numeric, 1) AS total_seconds,
  round(s.mean_exec_time::numeric, 1) AS mean_ms,
  round(s.max_exec_time::numeric, 1) AS max_ms,
  round((100 * s.total_exec_time / sum(s.total_exec_time) OVER ())::numeric, 1) AS pct_of_total,
  left(regexp_replace(s.query, '[[:space:]]+', ' ', 'g'), 120) AS query_snippet
FROM pg_stat_statements s
JOIN pg_roles r ON r.oid = s.userid
ORDER BY s.total_exec_time DESC
LIMIT 20;
This uses the Postgres 13+ column names. On older versions, use total_time and mean_time. Look at pct_of_total first. In most databases we audit, a handful of statements account for the large majority of execution time, and that is the list worth fixing.
Next, check which statements are spilling to disk or reading heavily from storage rather than memory:
SELECT
  left(regexp_replace(query, '[[:space:]]+', ' ', 'g'), 100) AS query_snippet,
  calls,
  shared_blks_read,
  shared_blks_hit,
  temp_blks_written
FROM pg_stat_statements
WHERE temp_blks_written > 0 OR shared_blks_read > shared_blks_hit
ORDER BY temp_blks_written DESC, shared_blks_read DESC
LIMIT 15;
Non-zero temp_blks_written means a sort or hash spilled to temporary files because work_mem was too small for that query. That is classic analytical behaviour on an OLTP database.
Finally, find the tables being read end to end most often:
SELECT
  relname,
  seq_scan,
  seq_tup_read,
  idx_scan,
  n_live_tup
FROM pg_stat_user_tables
WHERE seq_scan > 0
ORDER BY seq_tup_read DESC
LIMIT 15;
A big table with a huge seq_tup_read and a tiny idx_scan is almost always missing an index on the column your dashboards filter by, usually a created_at or status column.
How Do You Find Slow Postgres Queries Coming From Your BI Tool?
Here is the part most guides skip: pg_stat_statements does not record application_name. You cannot tell which statements came from the BI tool unless the BI tool connects as its own role. The pg_stat_statements query above already joins to pg_roles, so if your dashboards share a login with the application, you are blind. Fix that first by creating a dedicated role (shown in the next section).
For live traffic right now, use pg_stat_activity:
SELECT
  pid,
  usename,
  application_name,
  state,
  now() - query_start AS running_for,
  wait_event_type,
  left(query, 120) AS query_snippet
FROM pg_stat_activity
WHERE state <> 'idle'
  AND pid <> pg_backend_pid()
  AND now() - query_start > interval '30 seconds'
ORDER BY running_for DESC;
Then look for sessions that are open but doing nothing inside a transaction:
SELECT pid, usename, application_name, now() - xact_start AS xact_age
FROM pg_stat_activity
WHERE state = 'idle in transaction'
ORDER BY xact_age DESC;
Anything idle in transaction for more than a few minutes is holding back vacuum. We have seen a single forgotten BI session do this for hours.
Running those queries against one database is fine. Checking every dbt model downstream of it is not. fintel-scan is a free, open-source (MIT) CLI that runs static cost, correctness and governance checks across a whole dbt project locally, with no warehouse connection: uvx fintel-scan. It will not inspect your Postgres instance, but it is a useful next step once your data lands in a warehouse.
To confirm a suspect statement, run it under EXPLAIN. Because ANALYZE actually executes the query, wrap it in a transaction you roll back:
BEGIN READ ONLY;
EXPLAIN (ANALYZE, BUFFERS)
SELECT date_trunc('day', created_at) AS day, count(*), sum(amount)
FROM payments
WHERE created_at >= now() - interval '90 days'
GROUP BY 1;
ROLLBACK;
If you see Seq Scan on a large table with a high rows-removed-by-filter count, you have found your problem.
How Do You Fix Slow Postgres Queries From Dashboards?
Work down this list in order. Each step is cheaper and less disruptive than the next.
1. Isolate the BI tool with its own role and guardrails. This gives you attribution and a safety net in one move.
CREATE ROLE bi_reader LOGIN PASSWORD 'change-me' CONNECTION LIMIT 5;
GRANT USAGE ON SCHEMA public TO bi_reader;
GRANT SELECT ON ALL TABLES IN SCHEMA public TO bi_reader;
ALTER ROLE bi_reader SET statement_timeout = '60s';
ALTER ROLE bi_reader SET idle_in_transaction_session_timeout = '30s';
ALTER ROLE bi_reader SET work_mem = '32MB';
A 60-second statement_timeout means a runaway dashboard query gets cancelled instead of starving checkout. Tune the numbers to your workload, but set something.
2. Add the missing index. Use CONCURRENTLY so you do not lock writes:
CREATE INDEX CONCURRENTLY idx_payments_created_at ON payments (created_at);
3. Pre-aggregate the heavy tiles. If ten tiles each re-scan 90 days of payments, build one daily summary and point them at it:
CREATE MATERIALIZED VIEW daily_payment_summary AS
SELECT date_trunc('day', created_at) AS day, currency, count(*) AS txns, sum(amount) AS volume
FROM payments
GROUP BY 1, 2;

CREATE UNIQUE INDEX ON daily_payment_summary (day, currency);
REFRESH MATERIALIZED VIEW CONCURRENTLY daily_payment_summary;
The unique index is what allows the concurrent refresh without blocking readers.
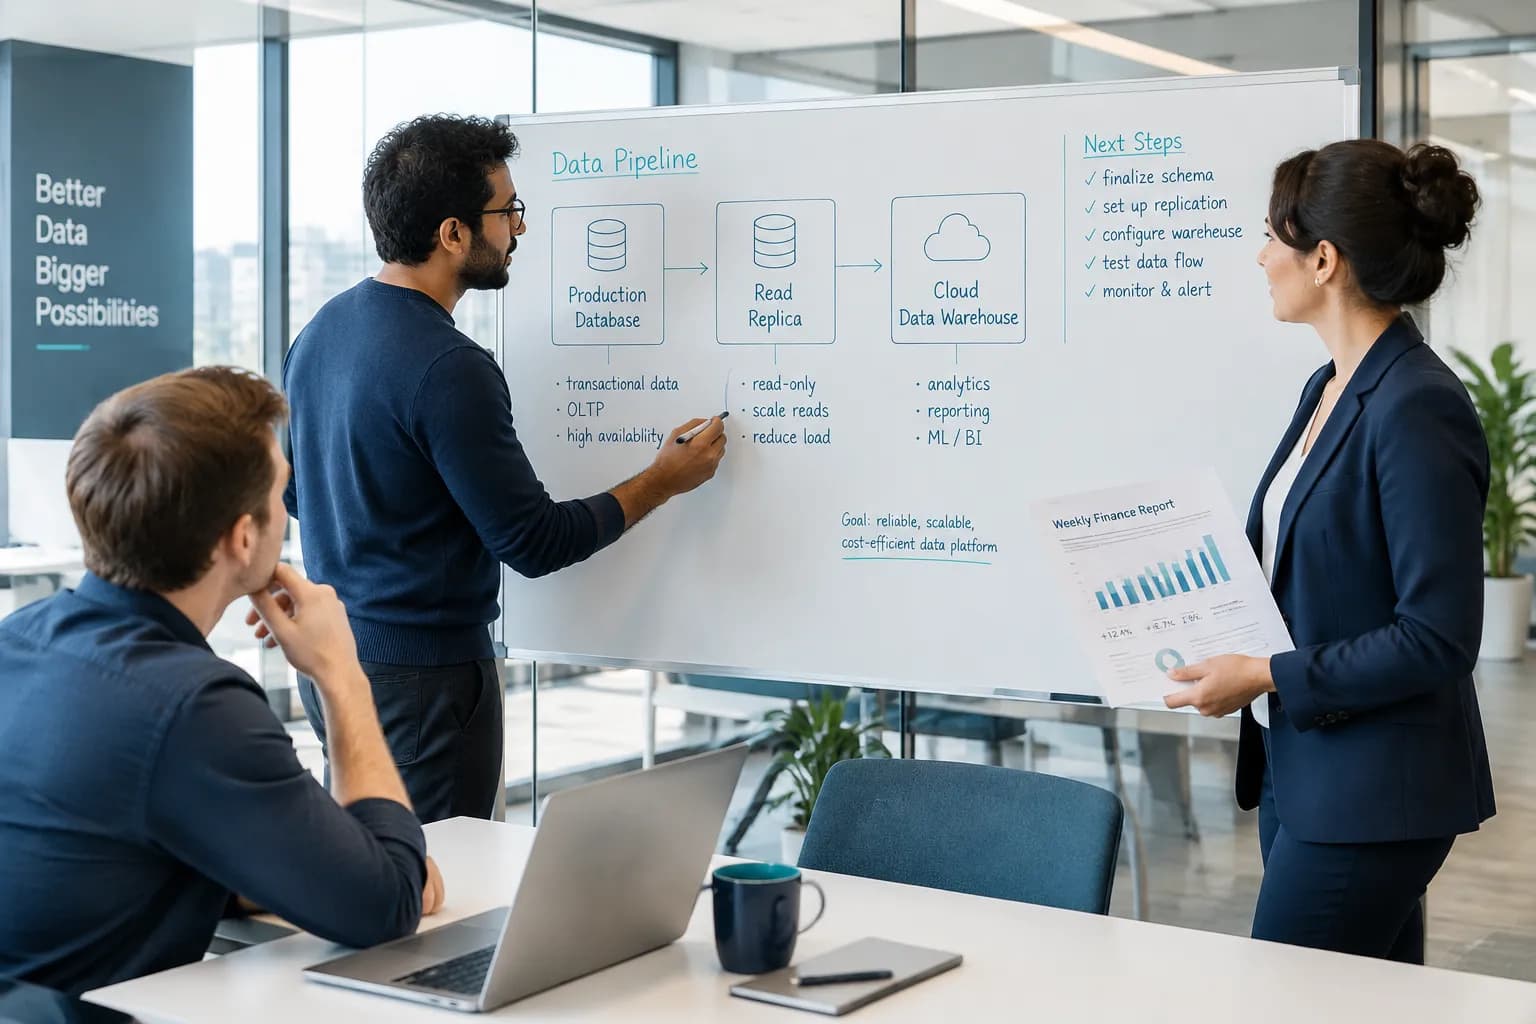
4. Point the BI tool at a read replica. This removes the load from the primary entirely. Be aware that replicas lag, and long-running queries on a replica can be cancelled by replication conflicts, so keep the statement_timeout in place.
The same principle applies beyond dashboards. In one engagement, a reconciliation process that took 30 to 50 minutes to run was rebuilt as an automated SQL pipeline and now completes in under 3 seconds. The gain came from moving set-based logic into well-modelled SQL, not from bigger hardware.
How Do You Stop Slow Postgres Queries Coming Back?
Fixing today's top five does nothing if next month's dashboard adds five more. Build three habits:
-
Snapshot pg_stat_statements weekly. The view is cumulative and resets on restart, so history disappears. Store a snapshot and you can see which queries are getting worse over time:
CREATE SCHEMA IF NOT EXISTS ops; CREATE TABLE IF NOT EXISTS ops.pgss_snapshot AS SELECT now() AS captured_at, * FROM pg_stat_statements WITH NO DATA; INSERT INTO ops.pgss_snapshot SELECT now(), * FROM pg_stat_statements;
-
Log slow statements. Set log_min_duration_statement to something like 1000 (milliseconds) so slow queries appear in your logs with their role attached.
-
Review dashboards on a schedule. Most refresh load comes from dashboards nobody opens. Our dashboard sprawl audit walks through retiring the ones that burn resources and erode trust.
When Should You Move Analytics Off Postgres Entirely?
Indexes, materialised views and replicas buy you time. They do not change the fact that Postgres is a row store built for transactions. These are rules of thumb from our delivery work, not hard limits.
Stay on Postgres (with a replica) if you have a small number of dashboards, your largest tables are well indexed, and analysts mostly run simple aggregations.
Move to a warehouse if any of these are true:
- Dashboards need joins across your product database and external sources such as payment providers or ad platforms.
- Your replica is now a full-time performance project.
- Finance and operations disagree on numbers because each team built its own queries against raw tables.
- You need modelled, tested, documented metrics in a semantic layer rather than ad-hoc SQL.
If that sounds like you, our guide to Postgres to BigQuery replication compares change-data-capture and batch approaches. You can also explore our services to see how we build the warehouse, dbt models and BI layer for growth-stage teams.
Frequently Asked Questions
Q: How do I find slow queries in Postgres?
A: Enable pg_stat_statements, then query it ordered by total_exec_time to see which statements consume the most database time overall. Use pg_stat_activity to see long-running queries live, and EXPLAIN (ANALYZE, BUFFERS) to confirm why a specific query is slow.
Q: Does pg_stat_statements slow down Postgres?
A: The overhead is generally modest and it is widely run in production, but measure it on your own workload. The bigger cost is that it needs a restart to enable on self-managed instances, so plan the change for a quiet window.
Q: How do I see which application ran a query in Postgres?
A: pg_stat_activity shows application_name for live sessions, but pg_stat_statements does not record it. The reliable approach is to give each application or BI tool its own database role and group the statistics by role.
Q: Should BI tools query a Postgres read replica?
A: Yes, in almost every case. A replica removes dashboard load from the primary. Keep a statement_timeout on the BI role, because long queries on a replica can be cancelled by replication conflicts, and remember the data can lag slightly behind the primary.
Q: When should I move analytics out of Postgres?
A: Move when dashboards need data from multiple sources, when tuning the replica becomes a constant effort, or when teams disagree on metric definitions. A warehouse with dbt models and a semantic layer gives you one tested definition per metric and isolates analytics from your product database.
Conclusion
The challenge is not writing one faster query. It is knowing which queries are hurting your product, who is running them, and whether Postgres is still the right place for analytics at your stage. At Fintel Analytics, we have helped payments, fintech and e-commerce teams trace exactly this kind of load, then move their reporting into properly modelled BigQuery, dbt and BI layers, so that dashboards stop competing with customers for the same database. If your team is guessing which dashboard slowed down production, that is a fixable problem, and a short data audit will usually show you the answer in days rather than weeks.