 Fintel Analytics
Postgres Replication Slot Filling Disk: Find & Drop It Safely
Postgres replication slot filling your disk? Run these pg_replication_slots queries to find the culprit, drop it safely and cap WAL retention for good.
A Postgres replication slot fills your disk when its consumer is inactive or lagging, because Postgres must keep every WAL segment from the slot's restart_lsn onwards. To find the culprit, query pg_replication_slots on the primary and sort by retained WAL. Drop slots that have no live consumer, and set max_slot_wal_keep_size so one dead slot can never take the database down again.
If you are reading this, you probably have a disk-space alert, a pg_wal directory that keeps growing, and tables whose sizes look completely normal. That combination is the signature of this problem. It usually shows up in analytics teams, because change data capture (CDC) into a warehouse is one of the most common reasons a replication slot exists in the first place. The slot belongs to a pipeline, the pipeline belongs to the data team, and nobody remembers creating it.
Why Is My Postgres Replication Slot Filling the Disk?
A replication slot is a promise. Postgres will not remove WAL until the consumer has processed it. That is exactly what you want from a CDC connector, and exactly what hurts when the connector disappears.
The dangerous part is the default. With max_slot_wal_keep_size left at -1, a single inactive slot can consume all available disk space. Slot retention also sits outside the normal limit: slot-bound retention is independent of max_wal_size. Tuning your checkpoints will not help.
In practice, we see four causes repeatedly:
- An orphaned slot from a decommissioned tool. Someone trialled a CDC vendor, switched it off, and never dropped the slot. Orphaned logical slots from retired CDC tools show active = false with WAL growing steadily.
- A connector that crashed and is retrying badly. The slot flips between active and inactive, and the retained WAL only ever goes up.
- A consumer that is alive but too slow. It is reading, just not as fast as your writes.
- A quiet database on a managed service. On AWS RDS, internal heartbeats generate WAL that logical replication consumers never see, so WAL can grow even on an idle database. The usual fix is a heartbeat table that your connector writes to and consumes.
A pattern we see repeatedly in early-stage companies: a Series A payments business had a Postgres-to-warehouse CDC job that was migrated to a new tool. The old slot stayed behind. Nothing broke for days, then the primary's disk alarm fired out of hours. The data team found out because the product team's database was in trouble, not because anything in the warehouse looked wrong.
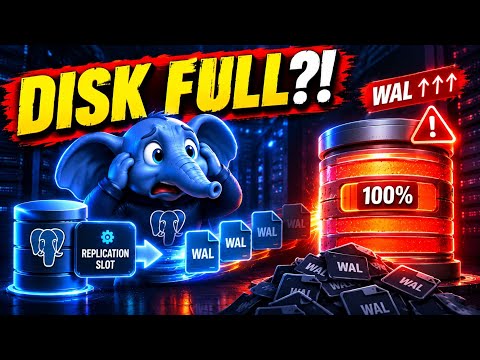
📺 Watch: The PostgreSQL Feature That Can Fill Your Disk Silently Overnight
How Do You Find the Replication Slot Filling Your Disk?
Run this on the primary. It will not work on a standby, because it calls pg_current_wal_lsn().
SELECT
  slot_name,
  slot_type,
  plugin,
  database,
  active,
  active_pid,
  wal_status,
  safe_wal_size,
  pg_size_pretty(
    pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn)
  ) AS retained_wal,
  pg_size_pretty(
    pg_wal_lsn_diff(pg_current_wal_lsn(), confirmed_flush_lsn)
  ) AS unconfirmed_logical_lag
FROM pg_replication_slots
ORDER BY pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn) DESC;
Read it top-down. The slot at the top with active = false is your prime suspect. The columns that matter:
- retained_wal: how much WAL this slot is pinning. This is the number that explains your disk.
- active / active_pid: whether anything is connected right now. On PostgreSQL 17 and later you can also select inactive_since to see how long it has been dead.
- wal_status: available since PostgreSQL 13, with four values: reserved, extended, unreserved and lost. Extended means the slot is holding more than your normal WAL limits would keep. Unreserved means it has exceeded max_slot_wal_keep_size and is about to be invalidated.
Then confirm the settings and the actual WAL footprint:
SHOW max_slot_wal_keep_size;

SELECT pg_size_pretty(sum(size)) AS pg_wal_size
FROM pg_ls_waldir();
If max_slot_wal_keep_size returns -1, you have no safety net. pg_ls_waldir() needs pg_monitor or superuser rights, and some managed services restrict it. In that case use your provider's transaction-log-disk metric instead.
Now match slots to real consumers. Physical standbys appear here:
SELECT pid, application_name, client_addr, state, sent_lsn, replay_lsn
FROM pg_stat_replication;
For logical slots, join the slot's active_pid to pg_stat_activity to see which application is attached. If a logical slot has no active_pid and nobody on your team can name its owner, you have found the problem.
One more check, because it is easy to miss. Long-running open transactions on the source can hold a logical slot back even when the consumer is healthy:
SELECT pid, usename, application_name, state,
       now() - xact_start AS xact_age
FROM pg_stat_activity
WHERE xact_start IS NOT NULL
ORDER BY xact_start
LIMIT 5;
This is a different problem from table bloat, where dead tuples inflate the data files. If your table sizes are flat but disk is climbing, look at WAL first. If table sizes are climbing, read our guide to finding dead tuples slowing your Postgres queries.
How Do You Tell an Orphaned Slot From a Lagging One?
Do not drop anything until you have answered this. Dropping a slot is instant and irreversible, and a CDC consumer whose slot disappears has to re-snapshot its tables.
Use this decision framework:
- active = false, nobody owns it, no connector in your tooling references it. Orphaned. Drop it.
- active = false, owned by a connector that is down. Restart the connector first. If it cannot catch up before the disk fills, accept the re-snapshot and drop the slot.
- active = true, retained_wal growing. The consumer is too slow, blocked downstream, or pinned by a long transaction. Fix the consumer or the transaction. Dropping the slot treats the symptom.
- wal_status = unreserved. You are close to losing the slot automatically. Decide now whether the data in it is worth saving.
- wal_status = lost. Postgres has already removed WAL that the slot still needed, so you must create a new slot and re-bootstrap the consumer. There is no resuming.
Running those queries on one database is fine. Checking every model in a project is not. For the warehouse side of your stack, fintel-scan is a free, open-source (MIT) CLI that runs fifteen checks on your project code locally, with no warehouse connection: uvx fintel-scan. It cannot see live slot state, because that only exists inside your running database, so use the SQL above for this one.
How Do You Drop or Fix a Stuck Replication Slot Safely?
First, tell the owner. If there is no owner, write down the slot name, its plugin and its database in a ticket so there is a record of why it was removed.
Then drop it. Postgres will refuse to drop a slot that is currently active, which is a useful guard:
SELECT pg_drop_replication_slot('old_cdc_slot');
WAL is not released the instant you drop the slot. Segments are recycled at the next checkpoint, so force one if you are short on space:
CHECKPOINT;
Then re-run the pg_ls_waldir() query to confirm the directory is shrinking. If you are about to run out of disk and the slot belongs to a pipeline you cannot afford to re-snapshot, the safer order is: add disk first, then let the consumer catch up. Provider-side volume expansion is usually faster than a full re-sync of a large table.
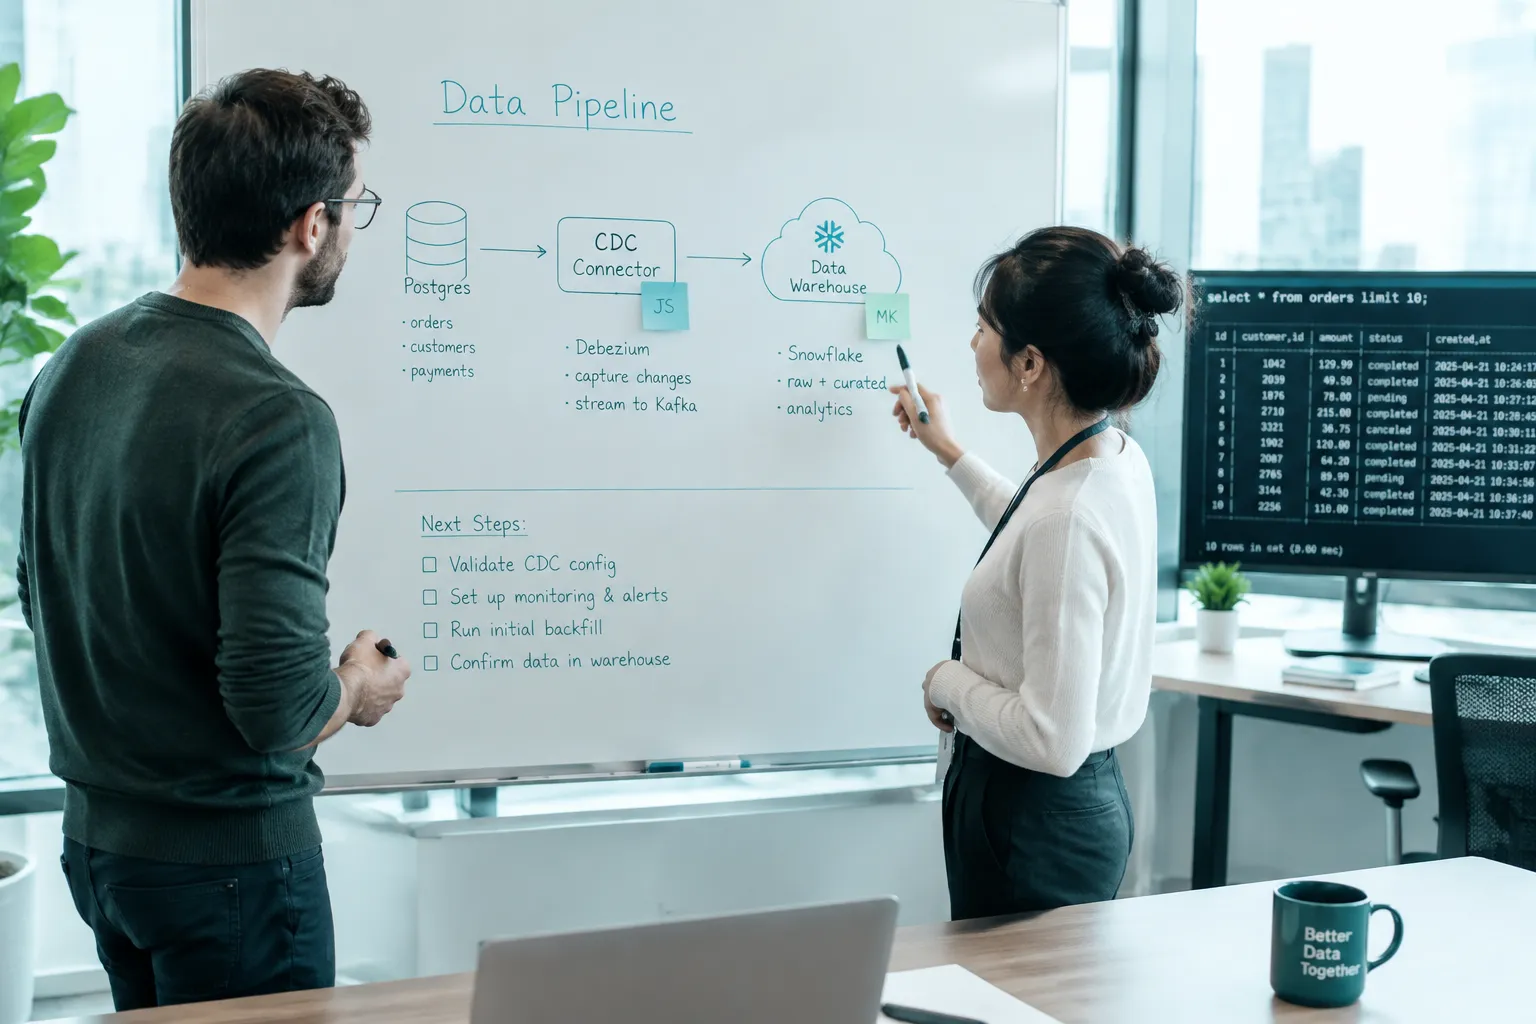
Once the slot is gone, check the downstream consequence. A dropped or lost slot means a gap in whatever the consumer was feeding. For a Postgres-to-BigQuery pipeline, that means any dbt models built on those raw tables are now quietly stale or incomplete. Check source freshness and run a row-count reconciliation between source and warehouse before anyone trusts Monday's numbers.
How Do You Stop a Postgres Replication Slot Filling Disk Again?
There are three controls, and the first is the one that matters.
1. Cap retention. max_slot_wal_keep_size was introduced in version 13, and leaving it unset means there is no limit. Set it:
ALTER SYSTEM SET max_slot_wal_keep_size = '50GB';
SELECT pg_reload_conf();
The value is a judgement call. One practitioner guide suggests 2-5x your hourly WAL generation rate, but small enough that a dead slot can't fill your disk. The ceiling is simple: it must be comfortably below your free disk space. The trade-off is real. When a slot exceeds the cap it is invalidated and the consumer must re-snapshot. We choose that every time, because a re-snapshot is an inconvenience and a full primary is an outage.
2. Alert before it gets there. Alert on any slot with active = false for more than a few minutes, and on retained WAL as a share of your cap. One suggested threshold is to warn at 50% of max_slot_wal_keep_size and page at 80%. Also alert on wal_status moving away from reserved.
3. Give every slot an owner. Use a naming convention that identifies the consumer and environment, such as cdc_bigquery_prod, and keep a register of slots. Document every slot's consumer, and make dropping the slot part of decommissioning that consumer. Inactive slots are widely described as the most common cause of uncontrolled WAL accumulation. Almost all of them are ownership failures, not technical ones.
The same lesson applies across data infrastructure: anything that holds a resource on your behalf needs an owner, a limit and an alarm. We apply the same thinking when we build production AI agents, with a spend cap and a kill switch on every pipeline. If that is useful, see our guide to an AI agent kill switch.
Frequently Asked Questions
Q: Why is my Postgres replication slot filling the disk?
A: The slot is pinning WAL because its consumer is inactive, crashed or lagging. Postgres will not recycle WAL that a slot still needs, and by default there is no upper limit on how much it will keep.
Q: Is it safe to drop an inactive replication slot?
A: It is safe if you have confirmed that no consumer needs it. Dropping is instant and irreversible, and a CDC consumer that loses its slot must re-snapshot its tables. Check the owner first, then run pg_drop_replication_slot.
Q: What should max_slot_wal_keep_size be set to?
A: Pick a value comfortably above what a healthy consumer would retain during a short outage, and well below your free disk space. A common starting point is two to five times your hourly WAL generation. The parameter exists from PostgreSQL 13 onwards.
Q: What does wal_status lost mean in pg_replication_slots?
A: Postgres has already removed WAL that the slot still required, so the slot can never resume. You must create a new slot and re-bootstrap the downstream consumer.
Q: Can a replication slot fill the disk on an idle database?
A: Yes, particularly on managed services such as AWS RDS, where internal activity generates WAL that a logical consumer never reads. A heartbeat table that your connector writes to and consumes is the usual remedy.
Fix the Slot, Then Fix the Ownership Gap
The hard part of a Postgres replication slot filling your disk is rarely the SQL. It is that a data pipeline quietly became a production dependency of your core database, with no owner, no limit and no alert. At Fintel Analytics, we have helped fast-growing fintech and e-commerce teams audit exactly this kind of hidden infrastructure risk, from CDC pipelines and dbt projects through to warehouse cost and access controls, and we build the monitoring so it does not come back. If you would rather find the next one before the disk alarm does, that is a short audit, and it costs far less than an out-of-hours outage.