
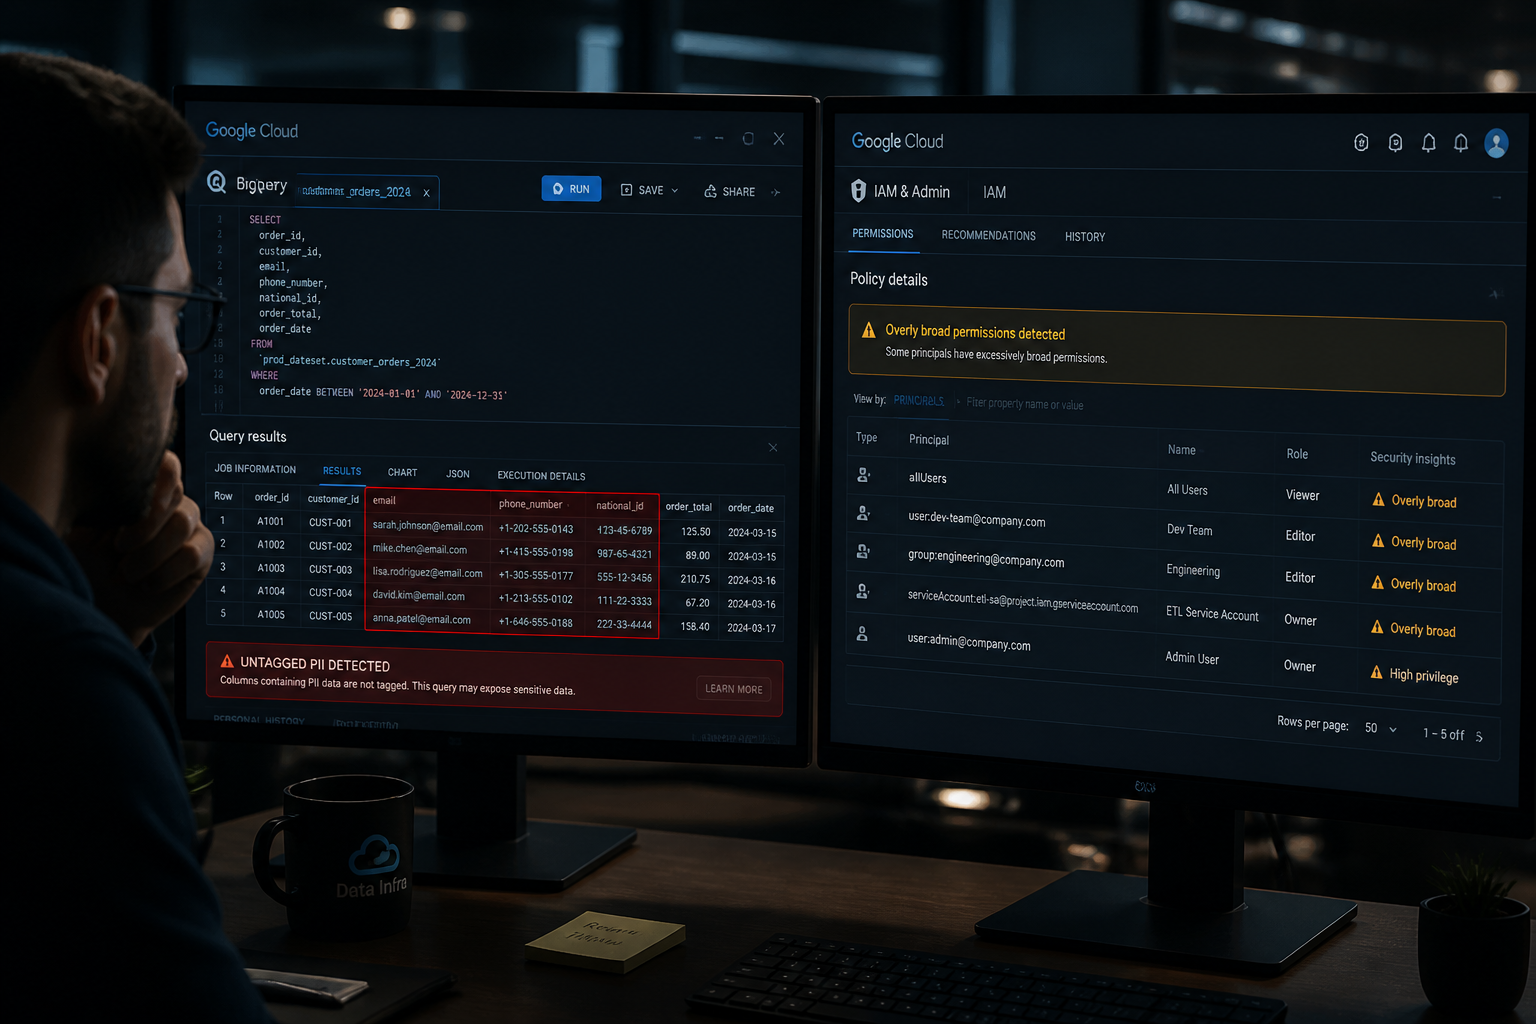
Unmasked PII in BigQuery is almost always present in warehouses that have grown faster than their governance practices. A single SQL query against INFORMATION_SCHEMA can surface columns whose names suggest sensitive data — emails, phone numbers, national IDs — with no policy tag, no masking rule, and no row-level security applied. If you have not run this check, you should assume you have a problem until you can prove otherwise.
This is not a theoretical risk. The average cost of a data breach hit a record high of $4.88 million in 2024, a 10% increase from the previous year. Nearly 46% of all data breaches involve the exposure of customer PII — data such as tax IDs, emails, phone numbers, and home addresses. For a growth-stage company navigating GDPR, SOC 2, or PCI-DSS, a single auditor asking "show me who can query your customers table" can stop a fundraising round or trigger a regulatory investigation. The scary part is that in most warehouses we have worked in, the answer is: almost everyone.
How Does PII End Up Unmasked in BigQuery?
It rarely happens through deliberate negligence. The pattern we see repeatedly in early-stage companies is incremental: an engineer creates a stg_users model that lands raw Fivetran or Airbyte data into a staging dataset. The model includes email, phone_number, and national_id columns because those fields exist in the source. No one applies a policy tag because the dataset is labelled "staging" and assumed to be internal. Then a BI analyst needs to join on email for attribution. Then a customer success analyst gets dataViewer on the whole project "just temporarily". The staging model gets promoted into a mart. The permissions never get cleaned up.
Sensitive data is exposed because BigQuery datasets are inadvertently or maliciously made public, or shared too broadly with other Google Cloud projects outside the intended trust boundary. The "inadvertent" path is far more common at growth-stage companies. Nobody decided to expose PII — it accumulated there through a dozen individually reasonable decisions.
Overly broad dataset access happens when teams grant dataViewer on all datasets to avoid permission request tickets. Broad admin grants to avoid access friction create security risks, audit noise, and confusion. When a credential leaks, the blast radius is the entire project. The pattern typically emerges when someone needed access quickly and the permissions were never cleaned up.
📺 Watch: Column-Level Security in BigQuery using Policy Tags | Google Cloud Data Protection
How to Find Unmasked PII Columns in Under Five Minutes
This is a two-part diagnostic: first find the suspicious columns, then check whether any policy tag (masking rule) is actually applied.
Step 1 — Surface columns whose names suggest PII
Run this against your BigQuery project. Substitute your_project with your actual project ID. This scans all datasets in a single pass:
SELECT
  table_catalog,
  table_schema AS dataset_id,
  table_name,
  column_name,
  data_type,
  is_nullable
FROM
  `your_project`.INFORMATION_SCHEMA.COLUMNS
WHERE
  LOWER(column_name) IN (
    'email', 'email_address', 'phone', 'phone_number',
    'mobile', 'national_id', 'ssn', 'social_security_number',
    'dob', 'date_of_birth', 'passport_number', 'ip_address',
    'full_name', 'first_name', 'last_name', 'home_address',
    'street_address', 'postcode', 'zip_code', 'bank_account',
    'card_number', 'iban', 'sort_code', 'tax_id'
  )
ORDER BY
  dataset_id, table_name, column_name;
This returns a flat list of every column that matches a known-PII name pattern — regardless of dataset, regardless of whether it is a staging model or a production mart.
Step 2 — Check which of those columns have no policy tag applied
BigQuery surfaces policy tag information through COLUMN_FIELD_PATHS. Run this to identify columns with a PII-like name but no masking policy:
SELECT
  c.table_schema AS dataset_id,
  c.table_name,
  c.column_name,
  cfp.field_path,
  cfp.policy_tags
FROM
  `your_project`.INFORMATION_SCHEMA.COLUMNS AS c
LEFT JOIN
  `your_project`.INFORMATION_SCHEMA.COLUMN_FIELD_PATHS AS cfp
    ON  c.table_catalog = cfp.table_catalog
    AND c.table_schema  = cfp.table_schema
    AND c.table_name    = cfp.table_name
    AND c.column_name   = cfp.field_path
WHERE
  LOWER(c.column_name) IN (
    'email', 'email_address', 'phone', 'phone_number',
    'national_id', 'ssn', 'dob', 'date_of_birth',
    'ip_address', 'full_name', 'iban', 'card_number', 'tax_id'
  )
  AND (cfp.policy_tags IS NULL OR cfp.policy_tags = '')
ORDER BY
  dataset_id, table_name, column_name;
Any row returned by this query is a column with a PII-pattern name and zero masking protection. In a warehouse that has grown organically over 12–18 months, it is not unusual to see dozens of results.
Step 3 — Check who actually has access to query those tables
If you want to understand blast radius, pair the above with an audit of project-level IAM bindings. Run this in the Cloud Shell or via gcloud:
gcloud projects get-iam-policy your_project \
  --format="json" \
  | python3 -c "
import json, sys
policy = json.load(sys.stdin)
broad_roles = [
  'roles/bigquery.admin',
  'roles/bigquery.dataViewer',
  'roles/bigquery.dataEditor',
  'roles/editor',
  'roles/owner'
]
for binding in policy.get('bindings', []):
  if binding['role'] in broad_roles:
    print(binding['role'], '->', binding['members'])
"
This surfaces every principal with a project-level BigQuery role — the ones where a single compromised credential exposes every unmasked column you just found in Steps 1 and 2.
Running those queries for one dataset is straightforward. Auditing every model across a project — including checking for test coverage, schema drift, and NULL propagation — is where manual effort compounds fast. fintel-scan is a free, open-source MIT-licensed CLI that automates this check and fourteen others locally, with no warehouse connection required: uvx fintel-scan.
What the Results Actually Tell You (And What They Don't)
A name-pattern match is a strong signal, not proof. A column called email in a dim_marketing_suppression table might contain hashed values — the column name is PII-shaped but the data itself is not sensitive. Your remediation workflow needs a human judgement step before you apply masking.
What the results definitively tell you:
- Which tables to physically inspect first. Start with anything in a mart or reporting dataset (not just staging) — those are the tables BI tools, Looker, or Holistics are querying directly and therefore have the widest access surface.
- Where policy tags are completely absent. If
policy_tagscomes back NULL across your entire project, you have never deployed column-level security — that is a finding in its own right. - Which datasets your broad IAM grants are covering. The combination of Steps 2 and 3 gives you a risk matrix: unmasked column × over-broad access = highest-priority remediation.
A pattern we see repeatedly in Series A fintech and payments companies: the raw or landing dataset has bigquery.dataViewer granted to an entire Google Group that was created during onboarding and has never been audited. That group contains the current data team, three former contractors, and a BI tool service account that has dataEditor because someone hit the wrong dropdown. None of this was malicious — it just accumulated.
For a deeper look at how schema changes in source systems can compound this problem by landing unexpected new columns into your warehouse without triggering any alerts, see our post on dbt Source Schema Drift: Find It Before It Breaks Production.
How to Fix Unmasked PII in BigQuery
Fix in three layers, in this order:
Layer 1 — Apply policy tags and column-level masking (Bigquery Data Catalog)
BigQuery's column-level security works through a taxonomy of policy tags. A masked column returns NULL (or a partial value, depending on the masking rule) to any principal who does not hold the datacatalog.categoryFineGrainedReader role on that tag.
To apply a policy tag via SQL:
ALTER TABLE `your_project.your_dataset.customers`
ALTER COLUMN email
SET OPTIONS (
  policy_tags = STRUCT(
    'projects/your_project/locations/eu/taxonomies/TAXONOMY_ID/policyTags/TAG_ID'
  )
);
You need to create the taxonomy and tag first in the Data Catalog UI or via Terraform. Terraform is strongly preferred — it makes the tags reviewable, versionable, and auditable.
Layer 2 — Enforce least-privilege IAM
IAM roles in BigQuery come in three types: primitive roles (Owner, Editor, Viewer), predefined roles, and custom roles. Skip primitive roles for production — they are too broad and violate the principle of least privilege. The fix is to revoke project-level data roles and re-grant at dataset level, scoped to the minimum required:
-- Remove over-broad project-level grant
-- (do this in gcloud or Terraform, not in the console)
gcloud projects remove-iam-policy-binding your_project \
  --member='group:[email protected]' \
  --role='roles/bigquery.dataViewer'

-- Re-grant at dataset level only
bq add-iam-policy-binding \
  --member='group:[email protected]' \
  --role='roles/bigquery.dataViewer' \
  your_project:reporting_dataset
The solution to permission sprawl is treating IAM as code: define permissions in Terraform or similar, require review for changes, and audit regularly.
Layer 3 — Add a dbt test to catch new PII columns before they reach production
Create a custom generic test in your dbt project that fails if a column matching a PII name pattern exists in a mart model without a meta.pii: true tag in the schema YAML:
-- tests/generic/no_untagged_pii.sql
{% test no_untagged_pii(model, column_name) %}
  -- Fails if a PII-named column exists without explicit pii metadata
  SELECT 1
  WHERE '{{ column_name }}' IN (
    'email', 'phone_number', 'national_id', 'dob',
    'ip_address', 'full_name', 'iban', 'card_number'
  )
  AND (
    SELECT COUNT(*) FROM (
      SELECT column_meta
      FROM {{ ref('meta_check') }}
      WHERE column_name = '{{ column_name }}'
      AND pii_tagged = TRUE
    )
  ) = 0
{% endtest %}
For most teams, a simpler and faster approach is to enforce naming conventions in the schema.yml YAML: any column whose name matches a PII pattern must include meta: {pii: true, masked: true}. Add a CI check using dbt ls and a shell script to validate this before merge.
How to Stop This From Recurring
Detection and one-time remediation solve today's problem. Tomorrow's engineer will still land a new source that contains date_of_birth in the raw layer and forget to tag it. Prevention requires process:
-
Taxonomy-first onboarding for new sources. Before any new Fivetran connector or custom ingestion job is promoted to staging, a checklist item requires identifying PII columns and assigning policy tags. This takes five minutes when done proactively; it takes five weeks when retrofitted across 40 tables.
-
Automated column-name scanning in CI. Add the INFORMATION_SCHEMA query from Step 1 as a scheduled query that runs nightly and writes results to a monitoring table. Alert (via Slack or email) when new untagged PII-pattern columns appear. This is the same pattern described in our Pipeline Incident Analytics: Stop Silent Data Failures in 2026 post — apply it to security, not just freshness.
-
Quarterly IAM audit as code. The
gcloudcommand from Step 3 should be wrapped into a script that runs quarterly and outputs a structured report. Any principal with a project-level data role triggers a review ticket automatically. -
Service account per pipeline, not per team. Each ingestion job, dbt run, and BI tool connection gets its own service account with the minimum permissions it needs. Overly permissive IAM roles might allow excessive access to sensitive data stored in BigQuery tables. An attacker who compromises a principal with broad data access permissions can exfiltrate large volumes of data, leading to a significant data breach.
Frequently Asked Questions
Q: How do I find all PII columns in BigQuery without querying each table individually?
A: Use INFORMATION_SCHEMA.COLUMNS filtered by a list of known PII column name patterns (email, phone_number, national_id, etc.). This scans metadata across all datasets in a single query — no full table scans, no data access required. The query in Step 1 above does exactly this and returns results in seconds regardless of warehouse size.
Q: What is the difference between BigQuery column-level security and data masking?
A: Column-level security (policy tags) controls whether a user can see the raw value at all — users without the fine-grained reader role receive NULL. Data masking is a related feature that can return partial values (e.g. the last four digits of a card number) rather than NULL. Both are applied through BigQuery Data Catalog policy tags; masking rules are an additional layer on top of the access control.
Q: Does applying a policy tag in BigQuery require any code changes in dbt?
A: Not necessarily. Policy tags are applied at the BigQuery table/column level and are independent of your dbt models. However, if you manage your BigQuery infrastructure as code via Terraform, you should define the taxonomy and tag assignments there so they are version-controlled and auditable. dbt's persist_docs and meta fields can be used to document PII intent in your YAML, but the actual enforcement happens in BigQuery.
Q: What counts as PII under GDPR for BigQuery governance purposes?
A: Under GDPR, PII (referred to as personal data) includes any information that can identify a natural person directly or indirectly. In a warehouse context this covers: names, email addresses, phone numbers, IP addresses, location data, national ID numbers, and any combination of attributes that together make someone identifiable. The name-pattern query in this post covers the most common column-name representations, but you should also audit free-text or JSON columns that may embed identifiers.
Q: How do I check if BigQuery row-level security is enabled on a sensitive table?
A: Run SELECT * FROM your_project.your_dataset.INFORMATION_SCHEMA.TABLE_PRIVILEGES to see what grants exist. Then query SELECT * FROM your_project.your_dataset.row_access_policies (available from the BigQuery API or via the console under "Security > Row-level security") to see whether any row access policy has been defined. If this view returns zero rows for a table containing PII, row-level security is not active on that table.
Unmasked PII in BigQuery is one of the most common and most remediable security findings we encounter when working with growth-stage companies — and it is almost always the result of legitimate infrastructure debt, not negligence. At Fintel Analytics, we have helped fintech, payments, and e-commerce businesses audit their full warehouse surface, apply column-level masking and least-privilege IAM in a single sprint, and build the CI and monitoring checks that prevent the problem from returning. If your team has not run a PII audit against your BigQuery project, you almost certainly have unmasked sensitive data in a table that more people can query than you think — and that is exactly the kind of problem that is cheap to fix before someone finds it for you.