
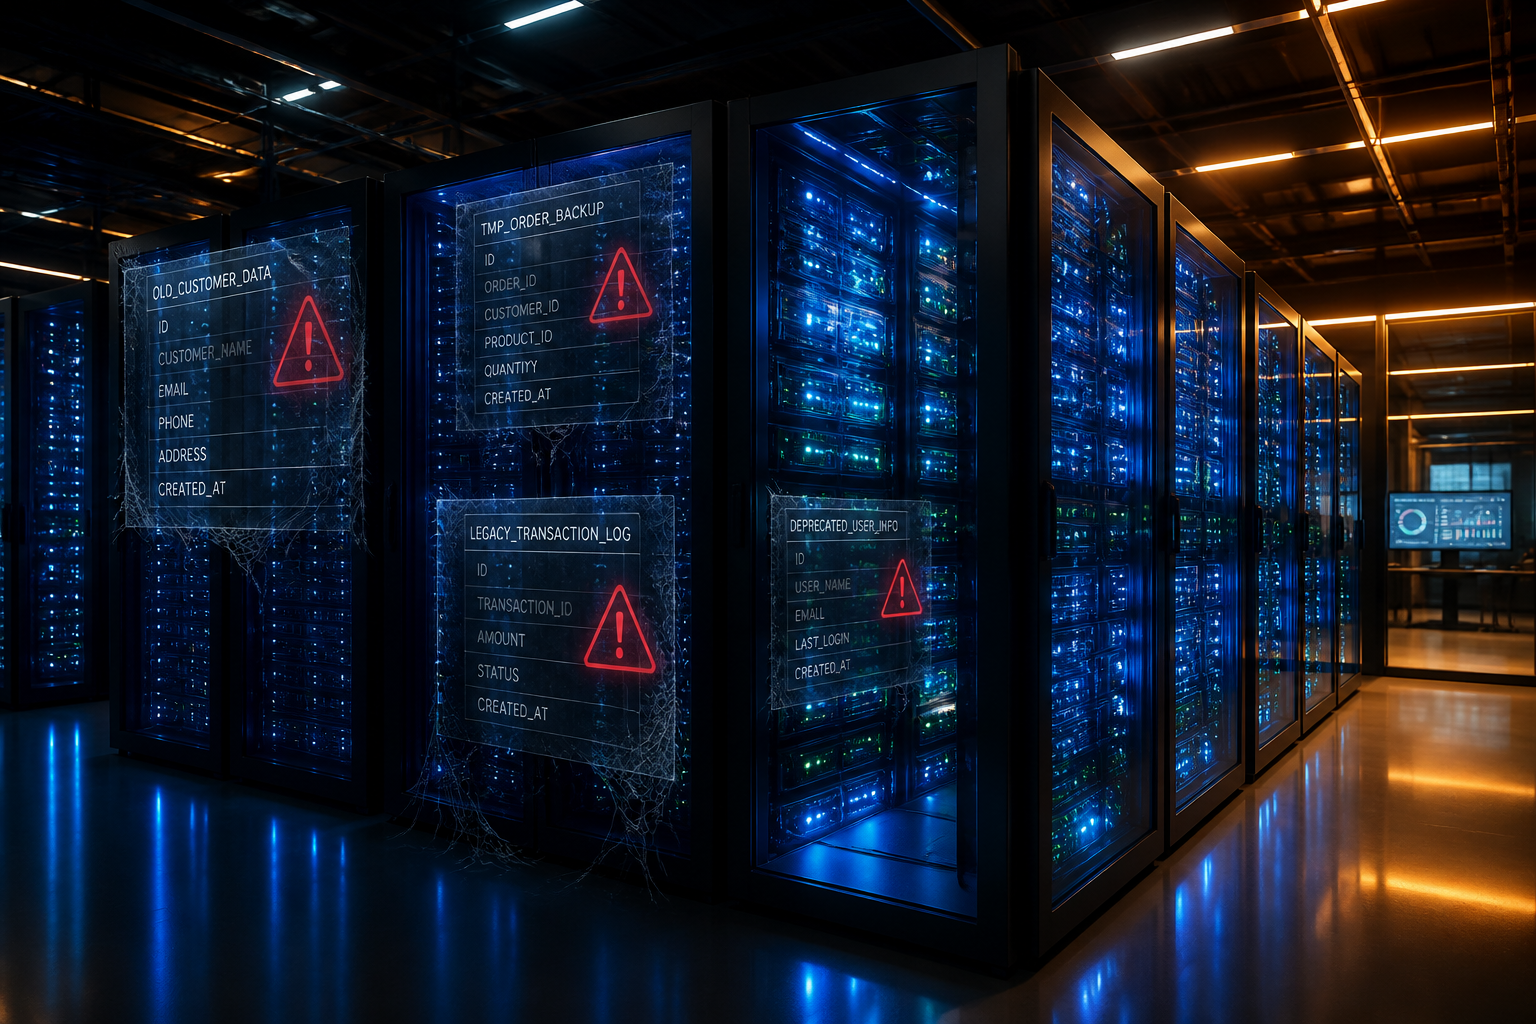
Orphaned dbt models in BigQuery are tables and views that still exist in your warehouse after their corresponding dbt model has been deleted or renamed. dbt does not drop relations automatically — it only creates them. Left unmanaged, these ghost tables accumulate over months, inflate your storage bill, and quietly mislead analysts who do not know the model was retired.
This post shows you how to detect them with a single SQL query against INFORMATION_SCHEMA, how to safely drop them, and how to stop them building up again.
Why dbt Leaves Ghost Tables Behind
This is not a bug — it is a deliberate design decision. dbt's philosophy is that it only manages objects it has been told to create. When you delete a .sql file from your project and run dbt run, dbt happily builds everything remaining and moves on. The table that used to live at analytics.fct_old_revenue is still there, unchanged, exactly as it was the last time it ran.
One of the less obvious quirks of dbt is how it handles — or rather, does not handle — cleanup when you delete or rename models. When you delete or rename a dbt model, the underlying table or view just stays there.
The problem compounds fast on active projects. A team refactoring a staging layer will rename a dozen models, move them between schemas, and consolidate marts. Six months later, the analytics dataset in BigQuery contains a graveyard of tables no one dares touch because they cannot tell whether something downstream still depends on them.
Tables and views in your BigQuery target schema are not dropped by default even if their corresponding dbt models no longer exist in your project — this can lead to confused analysts using outdated data and a cluttered schema that is hard to navigate.
A pattern we see repeatedly in client projects: an analyst queries stg_payments_v2 because it appeared in autocomplete — not realising stg_payments_v2 was retired eight months ago and stg_payments is the live version with the corrected logic. The numbers look plausible. The report gets filed. The discrepancy surfaces in a board review.
Orphaned tables — tables that were created at some point but are no longer tied to any active dbt models — not only take up space but can also lead to confusion and inefficiencies when managing your data infrastructure.
On the cost side, BigQuery's storage billing applies to every table, active or orphaned. Any table or partition that goes unmodified for 90 consecutive days automatically transitions to long-term storage, which is roughly half the active storage price. That sounds like good news — but it means an orphaned 50 GB intermediate table from a refactor six months ago is still costing you real money every month, just at the discounted rate. Multiply that across a two-year-old project with regular model churn and the numbers add up.
📺 Watch: How to Bring Ahrefs Data Into Screaming Frog
How to Find Orphaned dbt Models in BigQuery in Under Five Minutes
The core of this detection is a comparison between two sets:
- What BigQuery actually contains — queried from
INFORMATION_SCHEMA.TABLES - What dbt thinks should exist — derived from your compiled
manifest.json
The gap between those two sets is your orphan list.
Step 1 — Query what BigQuery holds
Run this against each dataset you want to audit. Replace your_project and your_dataset with your own values:
SELECT
  table_catalog,
  table_schema,
  table_name,
  table_type,
  TIMESTAMP_MILLIS(CAST(creation_time AS INT64)) AS created_at,
  TIMESTAMP_MILLIS(CAST(last_modified_time AS INT64)) AS last_modified_at,
  size_bytes
FROM
  `your_project.your_dataset.INFORMATION_SCHEMA.TABLES`
WHERE
  table_schema NOT IN ('INFORMATION_SCHEMA')
ORDER BY
  last_modified_at ASC;
Sort by last_modified_at ascending. The tables at the top — untouched for 90+ days while everything else has been updated — are your first suspects.
Step 2 — Extract dbt's expected relations from the manifest
Your compiled manifest.json lives at target/manifest.json after any dbt run or dbt compile. The nodes key contains every model, seed, and snapshot dbt currently knows about. You can extract the expected BigQuery relations with this shell one-liner:
cat target/manifest.json \
  | python3 -c "
import json, sys
m = json.load(sys.stdin)
for k, v in m['nodes'].items():
    if v['resource_type'] in ('model', 'seed', 'snapshot'):
        print(v['database'] + '.' + v['schema'] + '.' + v['name'])
" | sort > expected_relations.txt
This gives you every fully-qualified table name dbt expects to exist.
Step 3 — Compare against what BigQuery holds
Now run the BigQuery side into a file and diff the two:
bq query --nouse_legacy_sql --format=csv \
  'SELECT CONCAT(table_catalog,".",table_schema,".",table_name)
   FROM `your_project.your_dataset.INFORMATION_SCHEMA.TABLES`' \
  | tail -n +1 | sort > actual_relations.txt

comm -23 actual_relations.txt expected_relations.txt
The output of comm -23 is every table in BigQuery that dbt does not know about — your full orphan list.
Step 4 — Single-dataset SQL audit (no manifest required)
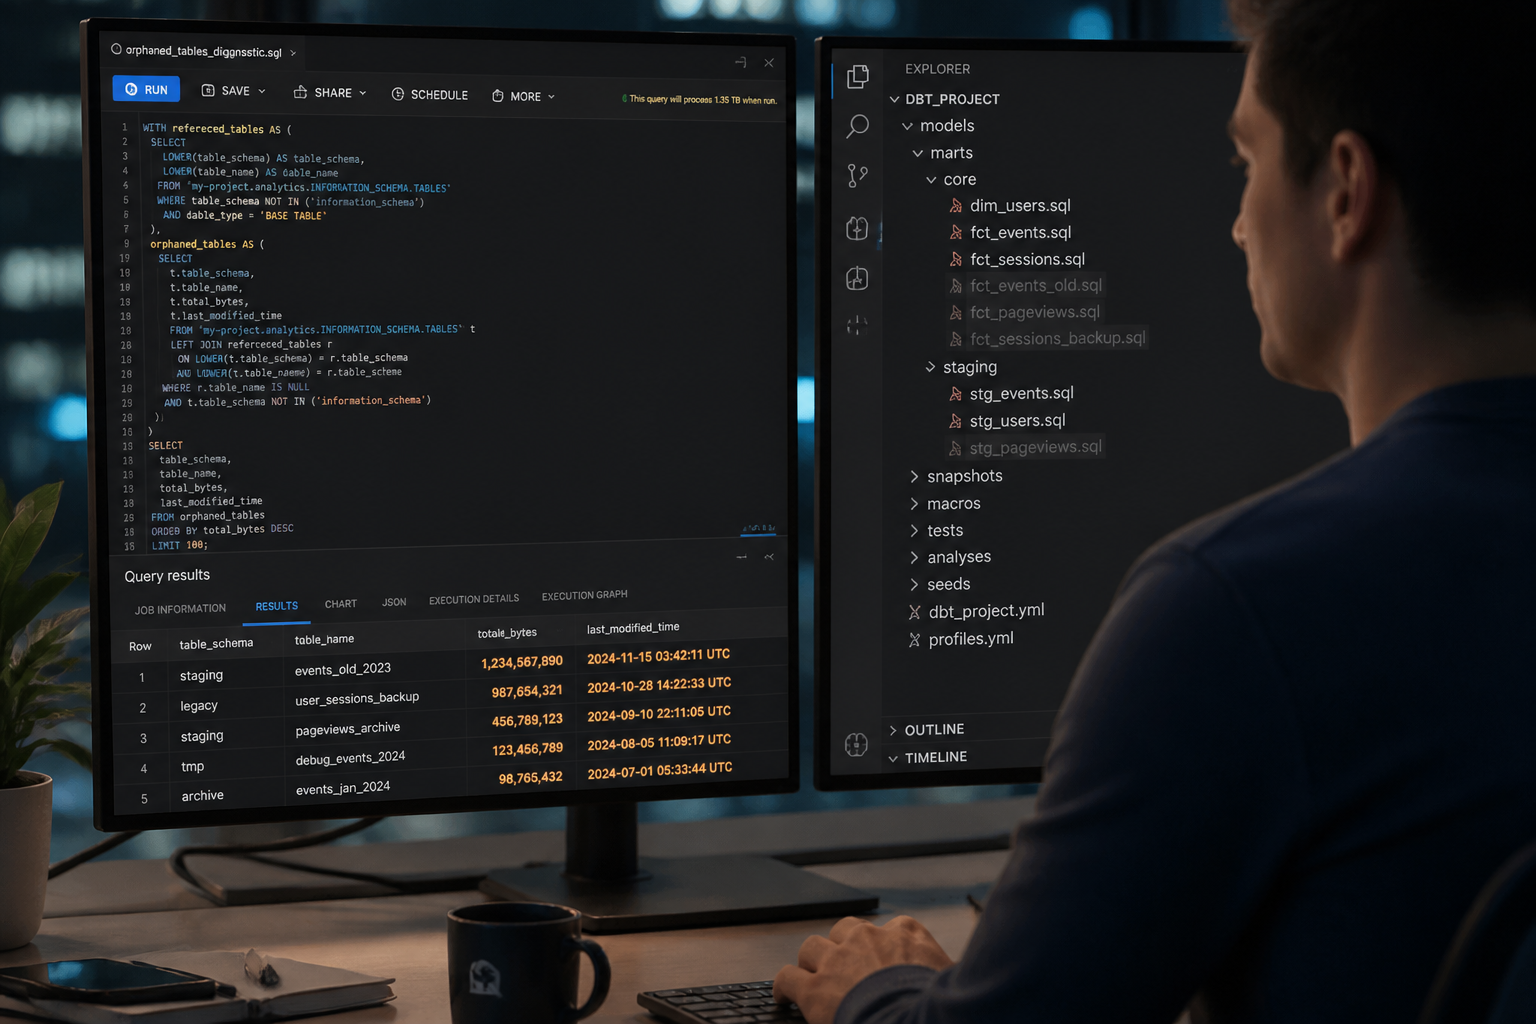
If you do not want to touch the manifest, this SQL gives you a strong signal directly in BigQuery — all tables in a dataset that have not been modified in over 90 days and are larger than 10 MB:
SELECT
  table_name,
  table_type,
  ROUND(size_bytes / POW(1024, 3), 3) AS size_gb,
  TIMESTAMP_MILLIS(CAST(last_modified_time AS INT64)) AS last_modified_at,
  DATE_DIFF(
    CURRENT_DATE(),
    DATE(TIMESTAMP_MILLIS(CAST(last_modified_time AS INT64))),
    DAY
  ) AS days_since_modified
FROM
  `your_project.your_dataset.INFORMATION_SCHEMA.TABLES`
WHERE
  size_bytes > 10 * 1024 * 1024
  AND DATE_DIFF(
    CURRENT_DATE(),
    DATE(TIMESTAMP_MILLIS(CAST(last_modified_time AS INT64))),
    DAY
  ) > 90
ORDER BY
  size_gb DESC;
That query alone, run across your staging, intermediate, and marts datasets, surfaces the worst offenders in seconds.
Running that audit for one dataset manually is straightforward. Checking every model in a project, including nested schemas and multi-environment deployments, is another matter. fintel-scan is a free, open-source MIT-licensed CLI that runs this check and fourteen others locally without a warehouse connection:
uvx fintel-scan.
How to Safely Drop Orphaned Tables in BigQuery
Never drop blind. Before you run a single DROP TABLE statement, do three things:
1. Check for downstream consumers outside dbt
If any BI tool, scheduled query, Looker explore, or external script references the orphaned table directly by name, dropping it will break something that has nothing to do with dbt. Query BigQuery's INFORMATION_SCHEMA.JOBS to check for recent references:
SELECT
  job_id,
  user_email,
  query,
  creation_time
FROM
  `region-eu.INFORMATION_SCHEMA.JOBS`
WHERE
  creation_time > TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 90 DAY)
  AND LOWER(query) LIKE LOWER('%your_orphaned_table_name%')
ORDER BY
  creation_time DESC
LIMIT 50;
If this returns results, someone or something is still hitting that table. Investigate before dropping.
2. Use dbt run-operation with a dry-run macro before anything destructive
A dbt package that identifies and removes orphaned tables and views in target databases by comparing database objects in information_schema with the current dbt models, seeds, and snapshots supports a safe dry-run mode to preview DROP statements and verbose logging to inspect the generated cleanup SQL before any destructive action.
3. Drop in batches, starting with views, then tables
Views carry no storage cost, but they do carry confusion cost — an analyst autocompleting table names in a BI tool will see every view regardless of whether it is live. Drop views first, then tackle tables by size, largest first.
-- Dry run: generate DROP statements, do not execute them
SELECT
  CONCAT('DROP ', table_type, ' IF EXISTS `',
         table_catalog, '.', table_schema, '.', table_name, '`;') AS drop_statement
FROM
  `your_project.your_dataset.INFORMATION_SCHEMA.TABLES`
WHERE
  table_name IN (
    'old_model_name_1',
    'old_model_name_2',
    'stg_payments_v2'
    -- add your confirmed orphan list here
  );
Review the output. Then execute each statement individually — do not bulk-execute without review.
For dbt-native cleanup at scale, the open-source dbt-orphan package wraps this pattern cleanly. It automatically cleans up orphaned database objects (tables and views) that are no longer defined in your dbt project, and provides a get_orphans macro to create a model that lists all orphaned objects without dropping them. The dry-run mode is your friend here.
How to Stop Orphaned Models Accumulating Again
Detecting and cleaning up once is a weekend's work. The real win is building the check into your regular workflow so you catch orphans within days, not months.
Add a post-run orphan audit to dbt Cloud
If you run dbt Cloud, add a scheduled job that calls a get_orphans-style macro after every production run. Set it to write results to a monitoring table in BigQuery. Then add a Holistics or Looker alert that fires when that table is non-empty.
Build a lineage check into CI
Before any PR merges that deletes or renames a model, the CI pipeline should output a warning listing the BigQuery relation that will become orphaned. This is not a blocking check — the engineer may intend to clean it up manually — but it puts the orphan on record before it disappears into the background noise.
See our post on dbt Lineage Blind Spots: Why Downstream Models Break Silently for a deeper look at how lineage gaps compound in active projects, and dbt Project Governance for Startups: Stop Model Sprawl for the governance conventions that reduce the churn rate behind orphan accumulation.
Enforce a deletion checklist in your dbt PR template
Add three lines to your pull request template:
## Model deletion checklist
- [ ] Confirmed no downstream dbt models reference this relation (dbt lineage checked)
- [ ] Confirmed no external queries reference this table (INFORMATION_SCHEMA.JOBS checked)
- [ ] DROP statement executed in production or added to post-merge cleanup script
This takes thirty seconds to fill out and eliminates the entire class of accidental ghost table creation.
Set a storage audit schedule
Run the last_modified_at > 90 days query monthly against every managed dataset. Log results to a monitoring table. Chart the orphan count over time. If the trend is flat or declining, your process is working. If it climbs, you have model churn happening without corresponding cleanup.
Many companies treat BigQuery as if it were a perpetual warehouse, loading data and leaving it to sit unless someone complains — over time this approach produces mountains of stale dev and QA snapshots collecting dust, alongside failing to implement automated cleanup for temporary datasets. A monthly audit query and a three-line PR checklist are enough to change that pattern entirely.
Frequently Asked Questions
Q: Does dbt automatically drop tables when I delete a model file?
A: No. If you remove a model from your dbt project, dbt does not automatically drop the relation (table or view) from your schema. You must drop orphaned relations manually, via a dbt macro, or using the dbt-orphan package. This is by design — dbt is a transformation tool, not a lifecycle manager.
Q: How do I find all orphaned dbt models in BigQuery without the manifest?
A: Query INFORMATION_SCHEMA.TABLES in each managed dataset and filter for tables with a last_modified_time older than 90 days and a size above your noise threshold. Cross-reference results against your active model names. This gives you a strong signal without needing to parse the manifest. The SQL in the "Single-dataset audit" section above runs in under ten seconds.
Q: Are orphaned views free in BigQuery?
A: Views carry no storage cost in BigQuery because they store no data. However, abandoned tables not only take up space but can also lead to confusion and inefficiencies when managing your data infrastructure — and views cause the same confusion problem without any cost savings justification for keeping them.
Q: What is the risk of dropping an orphaned BigQuery table?
A: The risk is that something outside your dbt project — a Looker explore, a scheduled query, an external script — still references it. Always check INFORMATION_SCHEMA.JOBS for recent queries against the table before dropping. If you see recent activity, trace the consumer before taking any action.
Q: How often should I audit for orphaned dbt models in BigQuery?
A: Monthly is the minimum for active projects with regular model churn. Teams doing weekly refactoring sprints should audit weekly. The SQL takes under a minute to run; the bottleneck is always the manual review, which is why integrating it into CI or a scheduled monitoring table is worth the one-off setup cost.
Orphaned dbt models in BigQuery are one of those problems that seems trivial until a senior analyst presents a number from a retired table in a board meeting, or until you open a storage cost breakdown and find half your bill is tables nobody has touched in a year. At Fintel Analytics, we have seen this pattern across fintech, payments, and e-commerce clients — and we have built the detection, cleanup, and governance processes that stop it recurring. If your BigQuery environment has been running dbt for more than six months without a systematic orphan audit, there is almost certainly storage bloat and stale data waiting to be found — and we can help you find it fast.