 Fintel Analytics
How to Automate Job Board Monitoring With AI (Scored Matches)
How to automate job board monitoring with AI: scheduled checks, scored matches with a visible breakdown, and a human who makes the call. Includes costs and limits.
The reliable way to automate job board monitoring is to split the work into three stages. Scheduled checks collect new listings from each board. An enrichment and scoring step ranks every listing against a written profile and shows its working. A person then makes the yes/no call. Automate the collecting and the first-pass judgement, never the decision. A task that used to eat an hour a day becomes a short review of ranked matches, each linked to its original post, with every model call costed.
If you own a process like this, you probably know it already. Someone on your team, or you, opens ten tabs every morning, scans for new postings, copies the interesting ones into a sheet, looks up the employer, and tries to remember what 'a good fit' meant last week. It is skilled work, but most of it is repetition. It is also easy to get wrong, because a good listing posted at 4pm can be gone from the front page by the next morning.
This post explains how we built exactly this kind of system. It covers how it runs, what it costs to run, where it still needs a human, and how to decide whether to build your own or buy an alert tool.
Why Does Manual Job Board Monitoring Break Down?
Manual monitoring breaks down for three reasons: coverage, consistency and memory.
Coverage. Nobody checks ten boards twice a day for long. Checking drops to once a day, then to when someone remembers. Listings that matter get seen late, or not at all.
Consistency. The person doing the checking applies a different standard at 8am than at 5pm. Two people on the same team apply different standards altogether. There is no record of why a listing was rejected, so the same weak listing gets re-evaluated every time it reappears on a different board.
Memory. The research behind a decision lives in someone's browser history. Pay, location, employer reputation and whether the role is genuinely new all get looked up again and again.
This is a version of a pattern we see repeatedly in our work with early-stage companies. Skilled people spend hours a week on repetitive research, monitoring or drafting that an agent could do daily and hand over for a yes/no. The cost is rarely visible on an invoice. It shows up as a senior person's attention being spent on the wrong layer of the problem.
There is also a reason to be careful before automating anything. Gartner predicted in June 2025 that over 40% of agentic AI projects will be canceled by the end of 2027, due to escalating costs, unclear business value or inadequate risk controls. Those three causes are the design brief for everything below. A monitoring agent has to be cheap enough to ignore, clearly valuable, and controlled enough to trust.
📺 Watch: How to Track Job Applications Automatically With AI (Gmail + Calendar)
How Does Automated Job Board Monitoring Actually Work?
We built a job-search assistant for education professionals that covers ten job boards. The same architecture applies to a recruitment team, a founder hiring for a hard-to-fill role, or an operations lead tracking roles at competitors. This is how it runs.
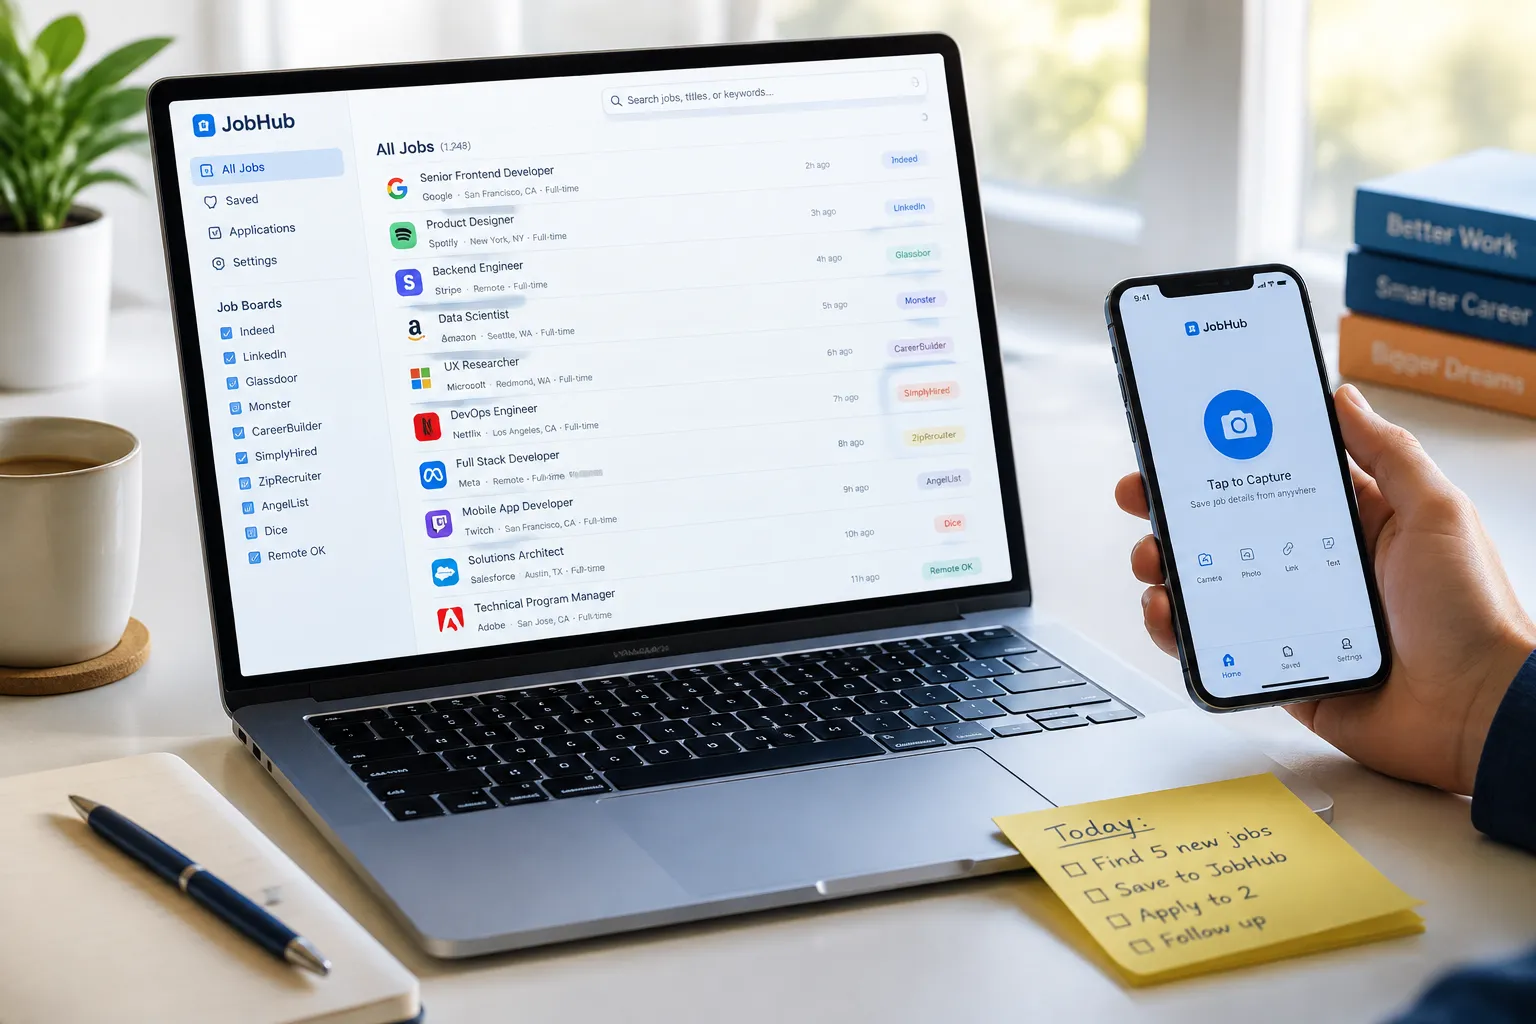
1. Trigger. Most boards are checked automatically twice a day on a schedule. Nobody has to remember anything. Not every board can be read reliably by a machine, though. Some have no stable feed, block automated access or hide listings behind a login. For those, we added a one-click capture. When a person sees a listing on one of those boards, a single click sends it into the same pipeline as everything else. This hybrid matters. Insisting on full automation across all ten boards would have meant brittle workarounds for the awkward ones.
2. Deduplicate and normalise. The same role often appears on several boards with different titles and slightly different wording. Before anything is scored, listings are matched and merged. They are then normalised into one structure: title, employer, location, stated pay, posting date and source link. This is dull work, but if you skip it, everything downstream is noisy.
3. Research the employer. Each new employer is researched once, covering pay, savings potential, reputation and location. The result is stored, so it is not paid for again the next time that employer posts. For a candidate, 'savings potential' means whether the pay stretches further in that location. For a recruiter, the equivalent might be company size, funding stage or review sentiment. The fields change, but the step does not.
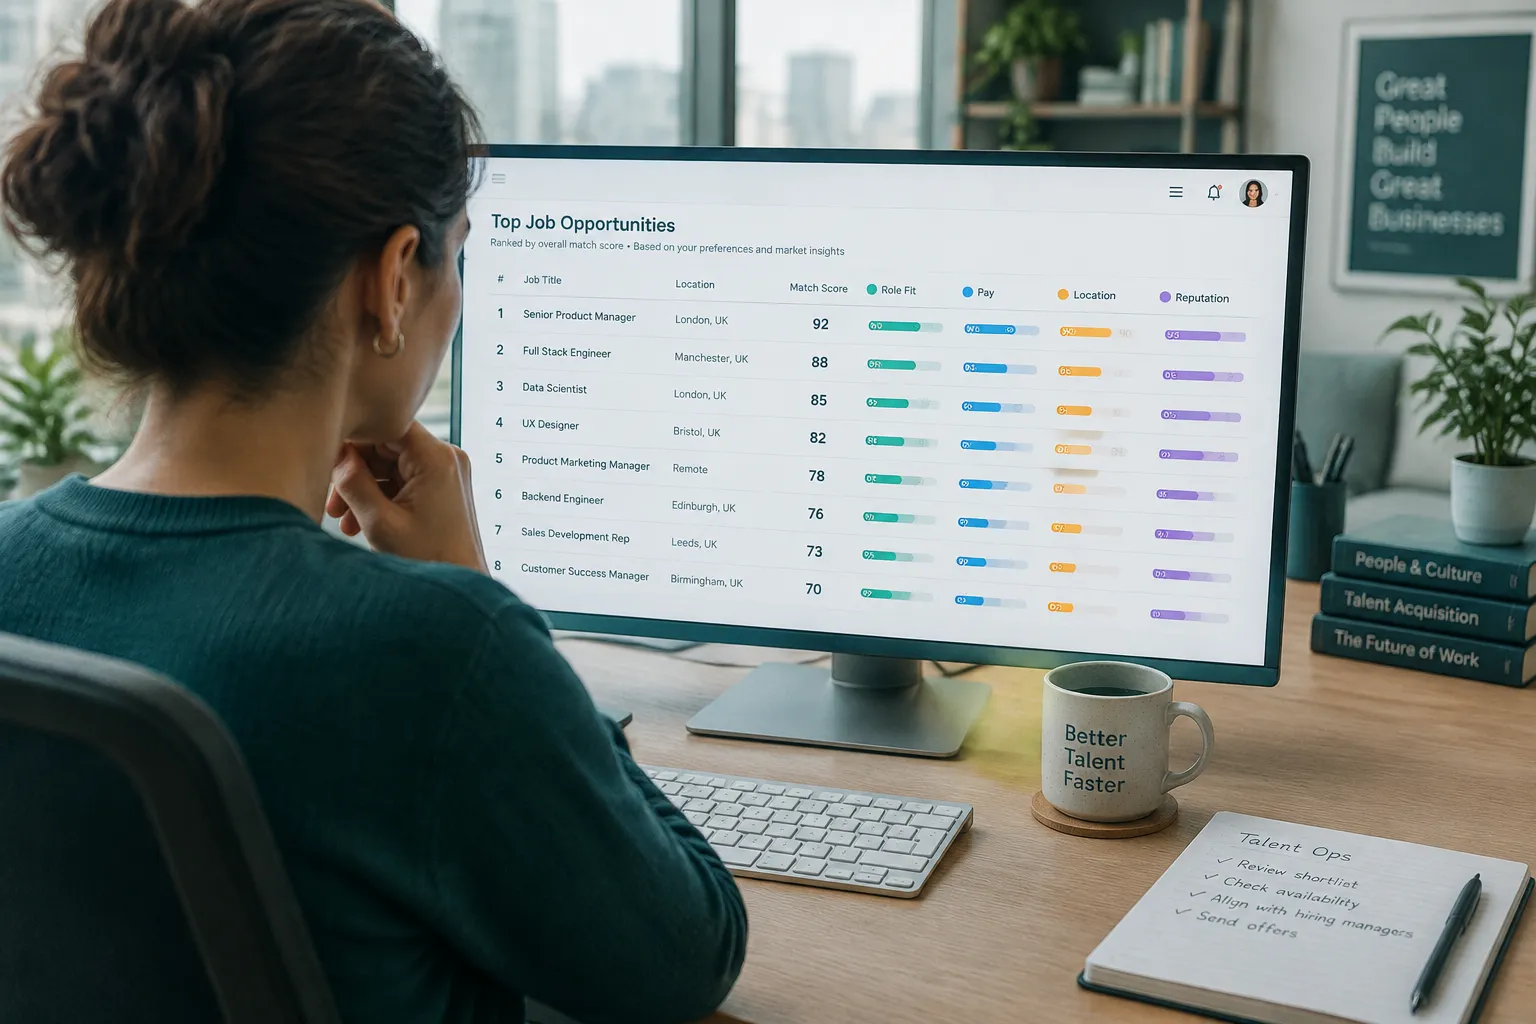
4. Score against a written profile. Each listing is scored against the candidate's profile, with a visible breakdown of how the score was reached. We cover why that matters in the next section.
5. Human review. The person sees a ranked list, with a link back to every original post. They shortlist, dismiss or park each one. Nothing is applied for, sent or committed automatically.
6. Cost visibility. Every paid model call is shown in the app. Nobody has to wonder what the system costs, because they can look.
How Should You Score Matches So People Trust Them?
A single number is the quickest way to make people stop trusting an AI system. If the tool says a listing is an 82 and nobody can tell why, the reviewer either accepts it blindly or ignores it. Both outcomes are bad.
The fix is a visible breakdown. Each score is made up of separate components, such as role fit, pay against target, location, employer reputation and seniority. The reviewer sees each component beside the total. That gives you three practical benefits:
- Disagreements become specific. 'The pay score is too generous' is something you can fix. 'The score feels off' is not.
- Weighting is a decision, not a mystery. If location matters twice as much as reputation, that is written down and can be changed.
- Errors are easy to spot. When a component is clearly wrong, for example a pay figure that was misread from the listing, a reviewer catches it in seconds because the evidence is linked.
A framework we use for any scoring step:
- Write the criteria down first. If you cannot state what a good match is in a paragraph, a model cannot apply it consistently either.
- Separate hard filters from soft scores. Anything that is a hard no, such as wrong country or wrong contract type, should be a rule in code. Do not ask a model to 'consider' it.
- Show the evidence. Every component should link to the text it came from.
- Test against a golden set. Take 30 to 50 listings that a human has already judged, and check whether the system agrees before you trust it on new ones. We describe the method in how to evaluate AI agents before production.
If this is a process your team still runs by hand, see how Fintel Analytics builds tools like this. We design and ship AI agents and internal tools that take over exactly this kind of work, with approval steps and audit trails built in rather than bolted on.
What Does It Cost to Run, and How Do You Know It Is Worth It?
We will not quote a monthly figure here, because it depends on how many boards you cover, how many listings appear and how deep the employer research goes. What we can say is how to keep it small and how to measure it.
Keep it small by routing work to the right model. Extracting fields from a listing is a routine task and does not need the most capable model. Judgement-heavy steps are where a stronger model earns its price. We use the same principle in an operations hub we built for an e-commerce brand, where routine questions go to a cheap model and only marketing analysis goes to a stronger one, so running costs stay small. We go deeper on this in our guide to LLM model routing.
Cache what does not change. An employer's reputation does not change between Tuesday and Wednesday. Research it once and reuse it. Scoring a listing that has not changed since the last run is money wasted.
Show the spend where people can see it. Showing every paid model call inside the app changes behaviour. The cost stops being an invoice you discover in month three. It becomes something you can see move when you add a board.
Measure cost per useful output, not cost per call. The number that decides whether this is worth running is the cost per shortlisted match. It is not the cost of a model call. Count the listings a person reviewed and kept, and divide the total spend by that count. Then compare it with the cost of the hour a day it replaced. If the shortlist rate is very low, the criteria are probably too loose. That is a scoring problem, not a model problem.
Put a stop on it. Any scheduled agent should have a kill switch, so that a bad run does not quietly repeat twice a day for a week. In our go-to-market system for a pre-seed company, a kill switch pauses the whole pipeline. We also learned there that fixing one failing stage moved leads with a contact found from 5% to 86% and cut failing runs from 86% to 14%. Reliability work is where most of the value is. If runs are failing for you, our post on why AI agent pipelines fail covers the common causes.
What Still Needs a Person, and What Went Wrong First?
Being honest about limits is what separates a tool people use from a demo they abandon.
What still needs a person:
- The decision. Whether to apply, contact or pursue a role is a judgement about someone's life or your hiring plan. The system recommends. A person decides.
- Employer research quality. Pay and reputation data are estimates drawn from public sources. They are good enough to rank on and not good enough to negotiate on. Treat them as a prompt to look closer.
- Awkward boards. The one-click capture exists because some sources cannot be automated sensibly. Expect a few of your sources to need a human hand.
- Recalibration. Priorities shift. If the profile changes and the scoring weights do not, the system will confidently rank the wrong things.
What went wrong before it worked. Three problems were worth the lessons.
First, duplicates. The same role across several boards made the early lists look busier and more promising than they were, and reviewers lost confidence quickly. Deduplication has to come before scoring.
Second, opaque scoring. A bare number was ignored, which is why every score now carries its breakdown and a link to the original post.
Third, trusting a single run. Without a record of what each run did and cost, you cannot tell a quiet day from a broken one. A silent failure looks exactly like 'no new listings'. Log every run, including the ones that find nothing.
Should You Build Your Own or Buy a Job Alert Tool?
Off-the-shelf alert tools are fine for a narrow job. Use this framework to decide.
Buy if:
- You only need keyword alerts from one or two major boards
- You do not need employer research or scoring against your own criteria
- Nobody will ask why a listing was ranked where it was
Build if:
- You watch many sources, including ones that standard tools do not cover
- Your definition of a good match is specific, such as a particular mix of pay, location and employer type
- You want research on each employer attached to every listing
- You need a record of what the system did, and what it cost
- The process feeds something else, such as a CRM, a sheet or a reporting layer
The middle ground is the one most teams miss. A small custom tool that does one job properly can cost less to run than a stack of subscriptions that each do a third of it. We explore that trade-off in build vs buy for internal tools.
One more point from Gartner is worth keeping in view. Its analyst commentary noted that many use cases positioned as agentic today do not require agentic implementations. A lot of monitoring is a scheduled job plus a scoring step with a human at the end, rather than an autonomous agent. Build the simplest thing that does the job.
Frequently Asked Questions
Q: How do you automate job board monitoring?
A: Set up scheduled checks that collect new listings from each board, then remove duplicates and normalise them into one format. Next, score each listing against written criteria and send a ranked list to a person for review. For boards that cannot be read automatically, add a one-click capture so they feed the same pipeline.
Q: Can AI monitor multiple job boards automatically?
A: Yes, for boards that expose listings in a way a scheduled process can read. Most can be checked automatically a couple of times a day. A minority block automated access or require a login, and those are better handled by a manual one-click capture into the same system.
Q: How much does it cost to run an AI job monitoring tool?
A: It depends on the number of boards, the volume of listings and how much employer research you do. The cost stays low if routine extraction goes to a cheap model, employer research is cached, and judgement steps are limited to listings that pass hard filters. Show the spend per model call in the tool, and track cost per shortlisted match rather than cost per call.
Q: Should AI make the final decision on which jobs or candidates to pursue?
A: No. The system should rank and explain, and a person should approve. A visible score breakdown with links to the original post lets a reviewer check the reasoning in seconds, and keeps responsibility with a human.
Q: Is it better to build a custom job monitoring tool or buy one?
A: Buy if you need simple keyword alerts from one or two major boards. Build if you track many sources, have specific match criteria, need employer research attached to each listing, or need an audit trail of what the system did and cost.
Ready to Automate Job Board Monitoring Without Losing Control?
The challenge for most teams is not whether they can automate job board monitoring. It is whether they can do it in a way that is cheap, explainable and safe to leave running twice a day. At Fintel Analytics, we have built production AI agents and internal tools, with cost tracking, human approval steps and audit trails, for fast-growing companies that were tired of skilled people doing repetitive checking by hand. If a manual monitoring or research process is eating your team's week, that is a fixable problem, and a well-scoped build pays back in the hours it returns.