 Fintel Analytics
Evaluate AI Agents Before Production: Build a Golden Set
Most AI agents look great in a demo and fall over in week two. Here is how to build a golden set, score output and set ship gates before go-live.
To evaluate AI agents before production, build a golden set of 30–50 real cases from your own data, score every run against rules enforced in code, and measure cost and failure rate per run. Only ship once the agent clears thresholds you set in advance, and keep a human approving anything the rules cannot check. An agent that has only ever been judged by someone reading its best outputs has not been evaluated. It has been demoed.
That gap between a convincing demo and a dependable system is where most agent projects die. The agent works on the five examples the builder tried. Then it meets real supplier emails, malformed spreadsheets, rate limits and edge cases nobody listed, and it fails quietly. The finance lead stops trusting it and the pilot gets shelved. This guide covers how we test agents before they touch real work: what to measure, how to build the test set, how to score without fooling yourself, and how to decide when an agent is ready.
Why Do Teams Struggle to Evaluate AI Agents Before Production?
Because evaluating an agent is a different job from building it, and the skills are different. Building is creative and fast. Evaluation is slow, repetitive and unglamorous, so it gets skipped when a demo already looks good.
The numbers suggest this is widespread. Gartner predicted in June 2025 that over 40% of agentic AI projects will be canceled by the end of 2027, citing escalating costs, unclear business value or inadequate risk controls. Look at those three causes. Escalating costs means nobody measured cost per run. Unclear business value means nobody defined what a good output is. Inadequate risk controls means nobody decided what happens when the agent is wrong. All three are evaluation failures.
Team practice backs this up. LangChain's State of Agent Engineering survey of 1,340 respondents, fielded in late 2025, found that 89% of teams have some observability, but only 52.4% run offline evaluations and 29.5% run none at all. Most teams can watch their agent. Far fewer can say, before launch, whether it is any good.
A pattern we see repeatedly is the AI pilot that never reaches production because nobody can say what it costs per run, what happens when it is wrong, or who approves its output. These are not research questions. They are operational ones, and a small team can answer them in a week or two if it does the work up front. If your agent is already failing in less obvious ways, our breakdown of why AI agent runs fail and how to fix them covers the failure modes we meet most often.
📺 Watch: How to evaluate agents in practice

What Does It Mean to Evaluate an AI Agent?
It means measuring three separate things, not one. Teams that only check whether the final answer looks right miss two of them.
1. Output quality: is the result correct and usable?
This is the obvious layer. If the agent drafts an outreach email, does it follow your style rules? If it researches an employer, is the pay figure real and does it link to a source? If it extracts invoice fields, do the totals match? Output quality is where most people stop, and it is the layer that produces the least surprise.
2. Run reliability: does it finish, every time?
An agent is a pipeline of steps: search, fetch, extract, verify, draft. Each step can fail. A 90% success rate per step sounds fine until you chain five steps and discover that barely six in ten runs complete cleanly. You need to measure the failure rate of the whole run and which step is responsible.
On a go-to-market system we built for a pre-seed tech company, the agent found prospects, found and verified contacts, drafted outreach and ran content publishing. The headline problem looked like bad copy. Measured stage by stage, it was the prospecting step. Fixing it took leads with a contact found from 5% to 86%, cut failing runs from 86% to 14%, and brought cost per outreach-ready lead from $1.28 to $0.05. None of that was visible from reading the emails. It only showed up because every stage was counted.
3. Economics: what does one run cost, and what does one wrong run cost?
Cost per run is a first-class metric, not a finance afterthought. Every model call in that go-to-market system is costed, and every paid call in the job-search assistant we built for education professionals is shown in the app. The second half matters just as much: what is the cost of a wrong output reaching a customer, a supplier or a bank account? That sets how much human review the agent needs. For a deeper look at the cost side, see our guide to AI agent cost per run and how to tell whether an agent is worth the spend.
How Do You Evaluate AI Agents Before Production Without a Research Team?
You do not need a benchmark suite or an ML team. You need a golden set, which is a fixed collection of real inputs with known-good answers that you run every time something changes. Here is how we build one for growth-stage companies.
Step 1: Harvest real cases, not invented ones
Pull 30 to 50 genuine examples from the work the agent will replace. For an invoice agent, that means real invoices from the last quarter. For a prospect-research agent, it means companies your team has already researched by hand. Invented examples are always too clean. Real ones contain the odd currency format, the missing field and the email thread with three forwarded replies, and those are what break agents.
Step 2: Include the awkward 20%
Deliberately include cases that should make the agent stop or ask. A supplier invoice with no purchase order, a prospect with no findable contact, a job post that has been taken down. A good agent declines these cases or escalates them. An agent that confidently produces an answer for every input is one you cannot trust on any input.
Step 3: Write the expected answer before you run anything
Have the person who does this work today write down what a correct output looks like, ideally a domain expert such as the finance lead or the operations manager. Do this before the agent runs, or you will unconsciously adjust the answer key to match what the agent produced.
Step 4: Freeze it, version it, and grow it from incidents
Treat the golden set like code. Version it, and rerun it on every prompt change, model swap or tool update. Then add one new case for every production incident, permanently. After six months, your test set is a record of every way the agent has actually failed, which is far more valuable than any generic benchmark.
If you are looking to implement this in your organisation, explore how Fintel Analytics approaches this. We build production agents and internal tools with cost tracking, human approval steps and audit trails, and the evaluation harness is part of the build, not an extra.
How Do You Score Agent Output Without Fooling Yourself?
Use the cheapest reliable scorer for each check, and be suspicious of any score that comes from the agent grading itself. We layer scoring in three tiers.
Tier 1: Rules enforced in code
Anything that can be checked deterministically should be. Does the email stay under the word limit? Does it avoid banned phrases? Does the extracted total equal the sum of the line items? Does every claim link to a source? On the go-to-market system, outreach style rules are enforced in code rather than requested in a prompt. A prompt asks the model to behave. Code makes it impossible not to. If a rule matters, move it from the prompt into a validator.
Tier 2: Reconciliation against a known truth
For numeric work, compare against an independent source. Our personal investment income tracker replaced a hand-maintained spreadsheet, and the test was simple: reconcile to the cent against the spreadsheet it replaced. A tracker that is a few cents out on a handful of holdings is a tracker that is wrong somewhere you cannot see. The same logic applies to a reconciliation job, a margin calculation or any agent that touches money.
Tier 3: LLM-as-judge, used carefully
For subjective qualities such as tone, relevance or whether a summary is faithful to its source, a second model can grade outputs at scale. It is useful, but not trustworthy unexamined. Judge models can be lenient and can favour outputs that resemble their own style. Before you rely on one, have a human grade a sample, compare the two, and only use the judge where they agree. Never let the same model and prompt that produced an output also grade it.
Show the breakdown
Where an agent scores something, make the scoring visible. The job-search assistant scores each job match against the candidate's profile with a visible breakdown and links back to every original post. That is a product decision and an evaluation decision at once. A reviewer can see why a job scored 82 and click through to check the source, so bad scoring gets noticed on day two rather than month two.
Run it more than once
Agents are non-deterministic. One passing run proves little. Run each golden case several times and look at consistency. An agent that gets a case right two times in three is not 67% reliable in a way you can plan around, because you cannot know which run you are getting. For anything customer-facing, you want the same case to pass every time.
This same discipline is why we built the autonomous trading agent the way we did. It paper-trades against live market data with real fees and minimum order sizes, and writes every trade to an append-only, hash-chained ledger, so the simulation cannot flatter itself. We cover the thinking behind that in building an AI trading agent simulation that can't lie. The principle transfers to any agent: if the evaluation can be quietly improved by the thing being evaluated, it is not an evaluation.
When Is an AI Agent Ready to Ship? A Decision Framework
Define the gates before you see the results. Once you have seen the scores, everyone, including you, will find reasons the current number is good enough. We use four gates.
Gate 1: Quality threshold. What pass rate on the golden set is required, and for which checks? Be specific. For example, a hard rule that no output may break a compliance constraint, plus a softer target for tone. Hard rules should be 100%, not 95%.
Gate 2: Reliability threshold. What share of full runs must complete without human rescue? If a run fails, does it fail loudly and stop, or silently produce a plausible wrong answer? Loud failure is acceptable. Silent failure is not.
Gate 3: Cost ceiling. What is the maximum acceptable cost per run, and per useful output? On the operations hub we built for an e-commerce brand, routine questions go to a cheap model and only marketing analysis goes to a stronger one, so running costs stay small. We only made that split after running the golden set against both models and confirming the cheap one held up on routine work. Do not downgrade a model on instinct. Test the downgrade. Our guide to LLM model routing strategy walks through that decision.
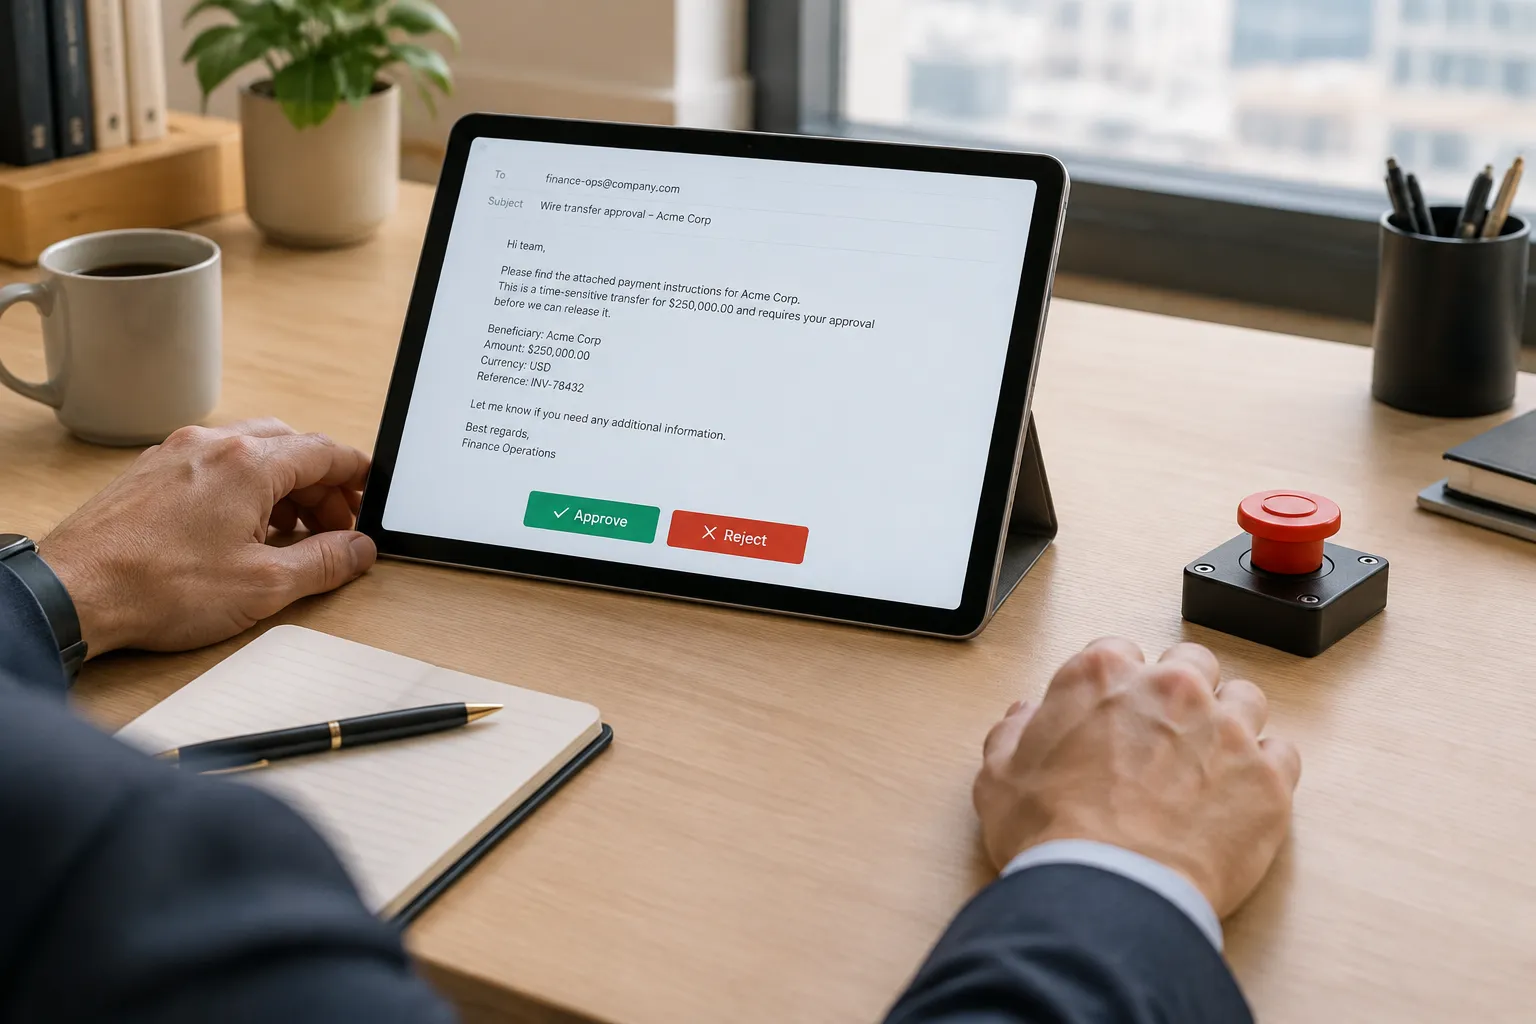
Gate 4: Control plane. Before go-live, three things should exist: a human approval step for any output with external consequences, an audit trail of who approved what, and a kill switch that pauses the pipeline. The blog and social pipelines on the operations hub draft content for human approval before anything is published. Our guide to the AI agent approval workflow explains how to design that so approval does not become a rubber stamp.
A simple rule of thumb on autonomy: start with the agent drafting and a human approving, measure approval and edit rates for a few weeks, and only widen autonomy for the categories where humans are approving almost everything unchanged. Gartner's own framing points the same way: software handles routine execution at scale, while people handle exceptions, oversight and accountability.
What Should You Monitor After an AI Agent Goes Live?
Production is where the evaluation continues, not where it ends. The inputs drift, suppliers change their email formats, a model provider updates a model, and your golden set slowly stops representing reality. Four things are worth tracking from day one:
- Cost per run and per useful output, trended weekly, with an alert if it moves materially.
- Failure rate by pipeline stage, so you can see which step is degrading rather than just that something is.
- Human edit and rejection rate, which is the most honest quality signal you have. If approvers start rewriting outputs, quality has slipped even if every automated check still passes.
- Incidents turned into test cases. Every wrong output that reaches a person becomes a permanent golden set entry.
This is also where a data foundation matters. Agents run on top of data. If the underlying metrics are inconsistent, finance showing one figure and operations another, an agent will confidently act on whichever it finds first. A pattern we see repeatedly is critical operations living in spreadsheets with no input validation, so the agent inherits bad numbers and amplifies them. Fixing the data layer first, with SQL models in a semantic layer and tested dbt transformations, is often the cheapest improvement you can make to agent quality. Our post on manual data entry validation covers the input side of that problem.
Frequently Asked Questions
Q: How do you evaluate an AI agent before deploying it?
A: Build a golden set of 30–50 real cases with known-correct answers written in advance, including cases where the agent should refuse or escalate. Run it repeatedly, score outputs with code-enforced rules first and a human-verified LLM judge second, and measure failure rate and cost per run. Set ship thresholds before you look at results.
Q: What is a golden dataset for LLM testing?
A: It is a fixed, versioned set of real inputs paired with expert-approved expected outputs, rerun every time you change a prompt, model or tool. It acts as a regression test for AI behaviour. The best ones grow over time, with a new case added for every production failure.
Q: Is LLM-as-a-judge reliable enough for production evaluation?
A: It is useful for scoring subjective qualities at scale, but it should not be trusted unexamined. Compare its scores against a human-graded sample before relying on it, never let a model grade its own output, and use deterministic code checks for anything that can be verified exactly.
Q: How many test cases do you need to evaluate an AI agent?
A: For a single-workflow agent at a growth-stage company, 30 to 50 well-chosen real cases is enough to start, provided they include edge cases and expected refusals. Quality of cases matters more than quantity. Add a case for every incident after launch.
Q: Why do most AI agent pilots fail to reach production?
A: Typically because nobody defined what a good output is, measured what a run costs, or decided who approves the result. Gartner's 2025 prediction that over 40% of agentic AI projects will be canceled by end of 2027 cites escalating costs, unclear business value and inadequate risk controls, all of which are measurable before launch.
Ship an Agent You Can Defend
The challenge most growth-stage teams face is not building an agent that works once. It is proving, to a finance lead, a founder or an investor, that it works reliably, costs what you expect and has a human in the loop where it matters. At Fintel Analytics, we have built production agents and internal tools for fintech, e-commerce and early-stage tech companies, each with costed model calls, approval steps, audit trails and a kill switch, and each tested against real data before it went anywhere near live work. If you want to evaluate AI agents before production rather than discover their flaws in front of customers, that is a fixable problem, and a week spent on evaluation costs far less than a pilot that gets cancelled.