 Fintel Analytics
AI Agent Pipeline Failures: Why Runs Fail and How to Fix
Most AI agent pipeline failures come from one weak stage, not the model. Here is how to find it, fix it, and keep cost per output low.
AI agent pipeline failures are rarely caused by the language model itself. In most production agents, one weak stage upstream or downstream of the model, such as a data lookup, a verification step or an output check, causes the majority of failed runs. The fix is to measure how many items survive each stage, repair the worst stage first, and put cost and approval controls around the whole pipeline.
If you own a process that an agent now runs for you, whether prospecting, monitoring or drafting, you have probably seen the pattern. The demo worked. The first week in production looked fine. Then runs started failing, the output got thin, and the bill did not shrink. Nobody could say which part was broken, so the usual response was to swap the model or rewrite the prompt. That rarely helps.
This post walks through how we diagnose AI agent pipeline failures in practice, using a go-to-market system we built for a pre-seed tech company, where fixing a single stage took failing runs from 86% to 14%.
Why Do AI Agent Pipeline Failures Usually Start Outside the Model?
Because an agent that does real work is a chain, and a chain fails at its weakest link. A prospecting agent, for example, does not just write. It finds companies, finds people at those companies, finds and verifies contact details, drafts outreach, checks the draft against style rules, and queues it for approval. The model is involved in some of those steps. The rest is lookups, parsing, rate limits, validation and plumbing.
A pattern we see repeatedly in early-stage companies is that the team judges the whole system by its final output, then blames the most visible component, which is the model. Meanwhile the real loss is happening quietly in the middle. If a contact-finding stage returns nothing for 95 out of 100 prospects, the best drafting model in the world has nothing to draft against.
That is exactly what we found in the go-to-market system mentioned above. Before the fix, only 5% of leads ended up with a contact found, and 86% of runs failed. Every one of those failed runs still cost money, because paid calls earlier in the chain had already been made.
This matters beyond one project. Gartner has predicted that over 40% of agentic AI projects will be canceled by the end of 2027, due to escalating costs, unclear business value or inadequate risk controls (Gartner, 2025). Notice that two of those three causes, cost and risk controls, are pipeline problems, not model problems. They are also fixable if you can see where the pipeline is leaking.
📺 Watch: Self-Healing Data Pipelines: How Agents Fix Failures Before You Wake Up
How Do You Find the Stage Where Your AI Agent Pipeline Is Failing?
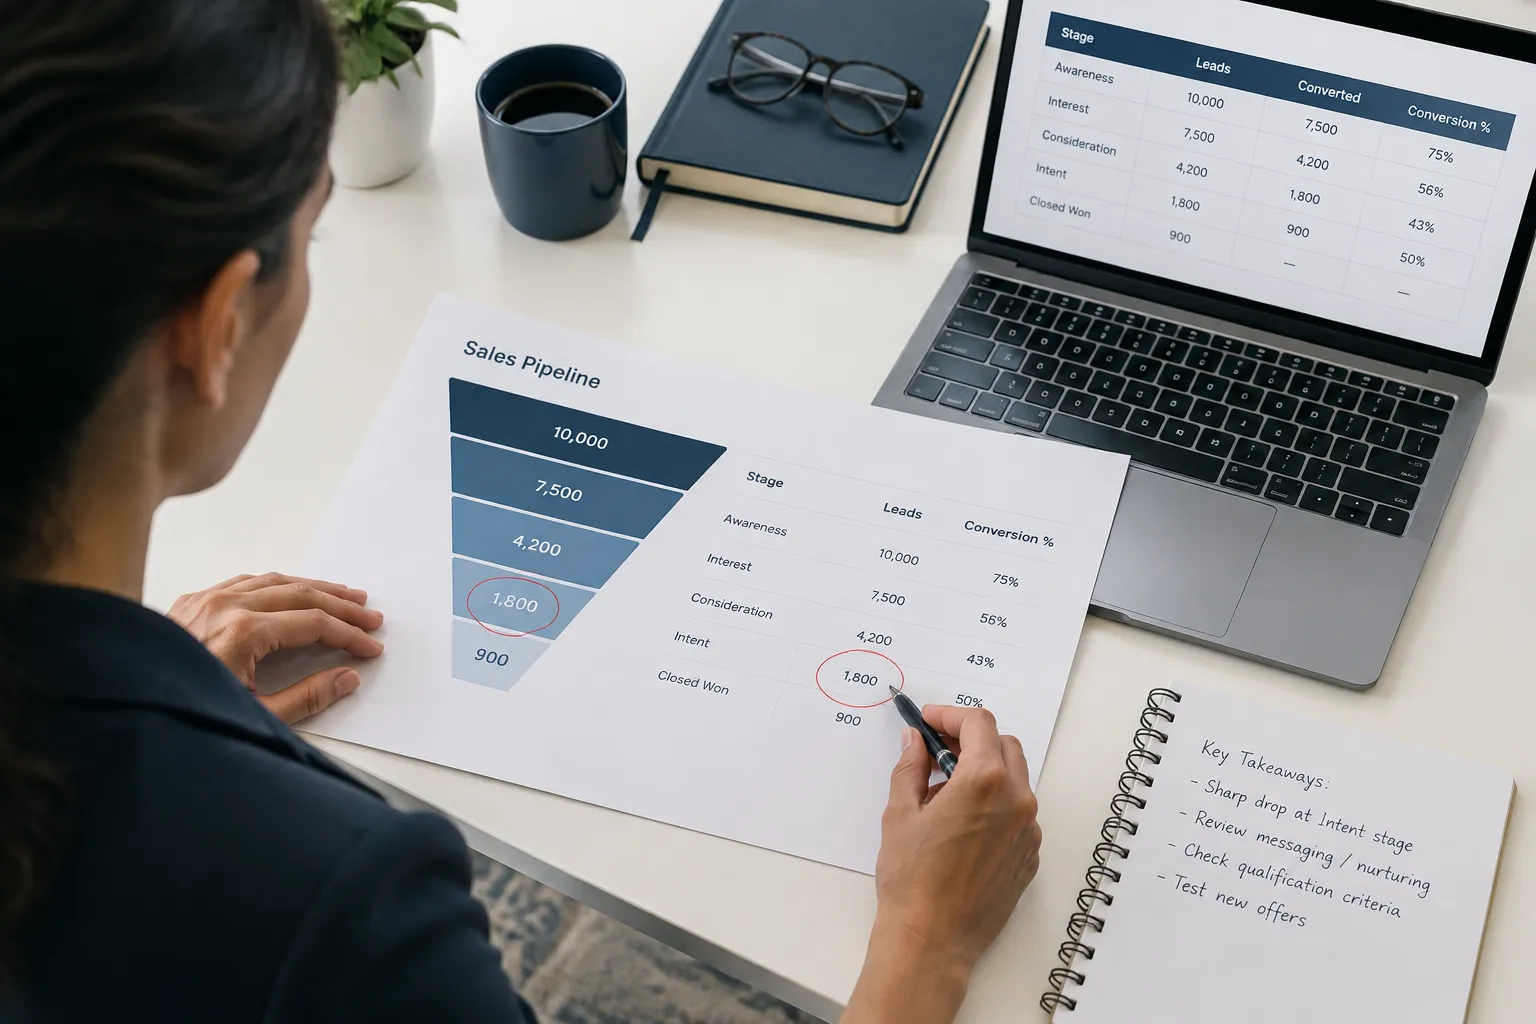
Measure stage-level yield. For every stage, record how many items went in, how many came out usable, and what the stage cost. Do this before you touch a prompt.
A simple stage log looks like this, in plain terms:
Stage 1: prospects identified. 100 in, 100 out. Stage 2: people identified at each prospect. 100 in, some number out. Stage 3: contact found and verified. This is where the collapse was. Stage 4: outreach drafted. Only as good as what Stage 3 hands it. Stage 5: draft checked against style rules, then queued for approval.
When you lay the funnel out this way, the weakest stage is usually obvious within a day. In our build it was the prospecting stage, specifically getting from a prospect to a verified contact. Everything downstream was starved.
Three habits make this diagnosis possible:
- Define a failed run precisely. We count a run as failed if it errors out or produces nothing usable, not just if it crashes. A run that completes quietly with zero outputs is a failure that looks like a success.
- Log the reason, not just the status. Failure categories such as lookup returned nothing, verification rejected the contact, or timeout tell you whether to fix a data source, a rule or an integration.
- Attach cost to every model call. If you cannot say what a stage costs per run, you cannot tell whether a fix is paying off. We cover that discipline in more detail in our guide to AI agent cost per run.
This is the same instinct a data engineer applies to a broken reporting pipeline: trace the row counts through each transformation and find where they fall off. An agent pipeline is a data pipeline with a language model in a few of the steps.
What Happens When You Fix the One Stage That Is Actually Broken?
The numbers moved a lot more than a prompt tweak would have moved them. After we rebuilt the prospecting stage of that go-to-market system:
- Leads with a contact found rose from 5% to 86%.
- Failing runs fell from 86% to 14%.
- Cost per outreach-ready lead dropped from $1.28 to $0.05.
The cost drop is worth understanding, because it is the number a finance lead cares about. Cost per call barely changed. What changed was cost per useful output. Before the fix, the pipeline paid for lookups, retries and model calls on runs that were never going to produce a lead. After the fix, most runs produced one. Dividing total spend by outreach-ready leads, rather than by runs or calls, is what exposed the problem and then showed the improvement.
That is the metric we recommend any operator track: cost per outcome-ready output, not cost per token and not cost per run. A cheap run that produces nothing is the most expensive run you have.
If this is a process your team still runs by hand, or an agent pilot that is failing without anyone knowing why, explore our services to see how Fintel Analytics designs and ships AI agents and internal tools that take over exactly this kind of work, with the stage-level measurement built in from day one.
Which Guardrails Stop AI Agent Pipeline Failures From Going Unnoticed?
A fixed pipeline still degrades. Data sources change, a provider alters its response format, a rate limit tightens. The goal is not a pipeline that never fails but one that fails loudly, cheaply and safely. These are the controls we put around every production agent.
A kill switch that pauses everything
In the go-to-market system, a single switch pauses the pipeline. It sounds trivial, but most pilots do not have one. When a stage starts misbehaving at 2am, the difference between a paused pipeline and one that burns budget until morning is real money. Make the switch something a non-engineer can use.
Every model call costed
Every call is logged with its cost, and the totals are visible in the app. The same applies to the job-search assistant we built for education professionals, where every paid model call is shown to the user. If cost is visible, nobody has to ask what the agent is spending.
Rules enforced in code, not in the prompt
Style rules for outreach are enforced by code that checks the draft, not by politely asking the model to comply. A prompt is a request. A check is a guarantee. Where an output must meet a rule, such as length, banned phrases or required fields, validate it programmatically and reject or regenerate on failure.
Cheap models for routine work, stronger models only where they earn it
In the operations hub we built for an e-commerce brand, routine questions go to a cheap model and only marketing analysis goes to a stronger one, which keeps running costs small. Routing is one of the quickest ways to lower the cost per output without touching quality. We break the approach down in our post on LLM model routing strategy.
A human approving anything that leaves the building
Drafts of blog posts, social posts and outreach go to a person for a yes or no before publishing. The agent does the repetitive work of research and drafting; the person keeps accountability. If you are designing this layer, our guide to AI agent approval workflows covers audit trails and sign-off design.
What Went Wrong Before It Worked, and What Still Needs a Person?
Honesty matters here, because this reader has usually been burned by hype.
First, the 86% failure rate was not a surprise to anyone who had looked at it, but it was invisible to everyone who had not. The pipeline reported activity, not outcomes. The first real step was not a clever fix. It was making yield per stage visible so we could see where items disappeared.
Second, fixing the prospecting stage did not make the system autonomous. Contact data goes stale, verification is probabilistic, and a verified contact is not the same as a contact who wants to hear from you. A person still decides who gets contacted and approves the wording. That is by design.
Third, an agent will confidently produce something plausible when its inputs are thin. This is the opposite of a crash and harder to catch. Our protection is checking inputs before the model runs: if there is no verified contact, the pipeline should stop and say so rather than draft anyway.
Fourth, not every task needs an agent. Gartner has noted that many use cases positioned as agentic today don't require agentic implementations. If a fixed script with one model call at the end does the job, build that. It is cheaper, easier to audit and easier to debug. We reserve agent-style behaviour for steps where the path genuinely varies from item to item.
A Decision Framework for Diagnosing Your Own Pipeline
If you own a manual process that an agent is supposed to be taking over, or one that is already underperforming, work through these questions in order:
- Can you state the outcome in one countable unit? For example, an outreach-ready lead, a matched job, a reconciled order. If not, you cannot measure success.
- Do you know the yield at each stage? If you only see the final output, you are guessing.
- Do you know the cost per outcome-ready output? Total spend divided by usable results, not by runs.
- Can someone stop it in one click? If not, add a kill switch before anything else.
- Is every rule that matters enforced in code? If a rule lives only in a prompt, treat it as unenforced.
- Is there a named person who approves what leaves the building? If not, the agent is not ready for production, however good the demo looked.
If you can answer yes to all six, you have something that can run unattended most days. If you answer no to three or more, you probably have a pilot, and it is more likely to be cancelled than scaled.
Frequently Asked Questions
Q: Why does my AI agent keep failing?
A: Most repeated failures come from a weak stage in the pipeline, such as a data lookup, an integration or a validation step, rather than from the model. Log yield at each stage and record failure reasons, and the weakest link usually shows up quickly. Changing the prompt before you have done this is mostly guesswork.
Q: How do I measure whether an AI agent is worth its cost?
A: Track cost per outcome-ready output, meaning total spend divided by the number of usable results, rather than cost per call or per run. In one go-to-market system we built, cost per outreach-ready lead fell from $1.28 to $0.05 once the failing stage was fixed. The model price barely changed; the share of runs producing something useful did.
Q: What guardrails does an AI agent need before going into production?
A: At minimum: a kill switch that pauses the pipeline, cost logged for every model call, output rules enforced in code rather than only in prompts, and a named person who approves anything that goes outside the business. An audit trail of what the agent did and why is the fourth leg that most pilots lack.
Q: Why do so many AI agent projects get cancelled?
A: Gartner predicted in 2025 that over 40% of agentic AI projects will be cancelled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls. Those three causes are largely about measurement and controls, which is why cost tracking and approval steps matter more than model choice.
Q: Should I fix the pipeline or switch to a better model?
A: Fix the pipeline first. If a stage is returning nothing usable, a better model downstream cannot recover the lost input. Only once stage yields are healthy does model choice become a meaningful lever for quality and cost.
Conclusion
The challenge for most founders and operations leads is not building an agent that works once; it is running one that keeps working, at a cost they can defend, with a person still in charge of what goes out. At Fintel Analytics, we have built production agents and internal tools for fast-growing companies, with cost tracking, human approval and kill switches built in, and we have seen again and again that fixing one failing stage beats rewriting the whole system. If your AI pilot is failing runs you cannot explain or costing more than it saves, that is a diagnosable problem, and the earlier you measure it, the sooner it starts paying for itself.