
dbt sources with no freshness configuration are invisible to your pipeline monitoring. When an upstream feed goes silent — a webhook stops arriving, a batch job quietly fails, an API integration breaks — dbt keeps running, your models keep building, and your dashboards keep showing numbers. They are just the wrong numbers, and nobody knows.
This post shows you how to find every dbt source in your BigQuery project that lacks a freshness check, why they are more dangerous than failing tests, and exactly how to close the gap before it bites you in a board meeting.
Why Missing Freshness Configs Are Worse Than Failing Tests
A failing dbt test is visible. It breaks your run, it shows up in your alerts, and an engineer investigates within the hour. A source with no freshness config is the opposite: it fails silently and indefinitely. The absence of a check is the problem, and absence is invisible by default.
Despite massive investments in analytics, 80% of organisations still rely on stale data for decision-making, and 85% of data leaders admit that making decisions with outdated data has directly cost their companies money (IBM, 2026). In our experience, the mechanism behind a significant portion of those stale-data incidents is not a broken pipeline — it is a pipeline that ran perfectly on yesterday's data because nobody told it to check whether yesterday's data had actually arrived.
A pattern we see repeatedly in early-stage companies: a data source is added during a sprint, the source YAML block gets the bare minimum — name, schema, tables — and it ships. The team is moving fast. The freshness block is a "nice to have" and it stays unwritten. Six months later there are thirty sources defined in the project and perhaps four of them have freshness configured. The other twenty-six are invisible to your monitoring.
A 2025 IBM Institute for Business Value report found that 43% of chief operations officers identify data quality issues as their most significant data priority, and over a quarter of organisations estimate they lose more than USD 5 million annually due to poor data quality. Unchecked source freshness is one of the most direct contributors to that figure — and it is one of the cheapest to fix.
📺 Watch: Elementary Automated Freshness & Volume Monitors
How to Find Every Unconfigured Source in Under Five Minutes
There are two approaches here, and you should run both.
Step 1: Query BigQuery INFORMATION_SCHEMA to find tables that haven't been updated recently
This query scans your BigQuery dataset metadata and returns any table that has not been modified in the past 24 hours. It does not require any dbt context — it works against raw warehouse metadata and gives you a ground-truth view of which tables are stale right now:
SELECT
  table_schema,
  table_name,
  TIMESTAMP_MILLIS(last_modified_time) AS last_modified_at,
  TIMESTAMP_DIFF(CURRENT_TIMESTAMP(), TIMESTAMP_MILLIS(last_modified_time), HOUR) AS hours_since_update
FROM
  `your_project.your_dataset.__TABLES__`
WHERE
  TIMESTAMP_DIFF(CURRENT_TIMESTAMP(), TIMESTAMP_MILLIS(last_modified_time), HOUR) > 24
ORDER BY
  hours_since_update DESC;
Replace your_project.your_dataset with your source dataset — the one your raw ingestion lands into. Run this for each source dataset in your project. Anything with hours_since_update in triple digits deserves immediate attention.
A note for BigQuery specifically: if your table has a mandatory partition filter, the default freshness check will fail without a filter clause — so if you see errors when you eventually wire up dbt source freshness, that is why. We'll cover the fix below.
Step 2: Find which dbt sources have no freshness block defined
This is a dbt-level problem, and the right place to audit it is your sources.yml files. Run this shell command from the root of your dbt project to list every source table entry that does not contain the word freshness:
grep -rn "- name:" models/ | grep -v "freshness" | grep -A2 "tables:"
That is a rough signal, not a surgical audit. For a more precise view, use dbt ls combined with source output:
dbt ls --select source:* --output json 2>/dev/null | python3 -c "
import sys, json
for line in sys.stdin:
    line = line.strip()
    if not line:
        continue
    try:
        node = json.loads(line)
        if node.get('resource_type') == 'source':
            freshness = node.get('freshness') or {}
            if not freshness.get('warn_after') and not freshness.get('error_after'):
                print(f\"NO FRESHNESS: {node.get('unique_id')}\")
    except json.JSONDecodeError:
        pass
"
This pipes the dbt manifest through a small Python snippet and prints every source node where neither warn_after nor error_after is defined. On a project with forty sources, this typically surfaces ten to twenty unconfigured entries.
You can also check the compiled manifest.json directly after a dbt compile run:
cat target/manifest.json | python3 -c "
import sys, json
manifest = json.load(sys.stdin)
sources = manifest.get('sources', {})
for uid, node in sources.items():
    freshness = node.get('freshness') or {}
    has_warn = bool((freshness.get('warn_after') or {}).get('count'))
    has_error = bool((freshness.get('error_after') or {}).get('count'))
    if not has_warn and not has_error:
        schema = node.get('schema', '')
        name = node.get('name', '')
        print(f\"UNCONFIGURED: {uid} ({schema}.{name})\")
"
This is the most reliable method. It reads directly from the compiled manifest and catches sources where the freshness block exists but is empty — a common misconfiguration that grep alone will miss.
Running those queries for one or two sources is fine. Auditing an entire project across all your YAML files is not something you want to do manually every sprint. fintel-scan is a free, open-source CLI (MIT licence) that runs this check and fourteen others locally against your dbt project without needing a live warehouse connection: uvx fintel-scan.
What Good Freshness Configuration Actually Looks Like
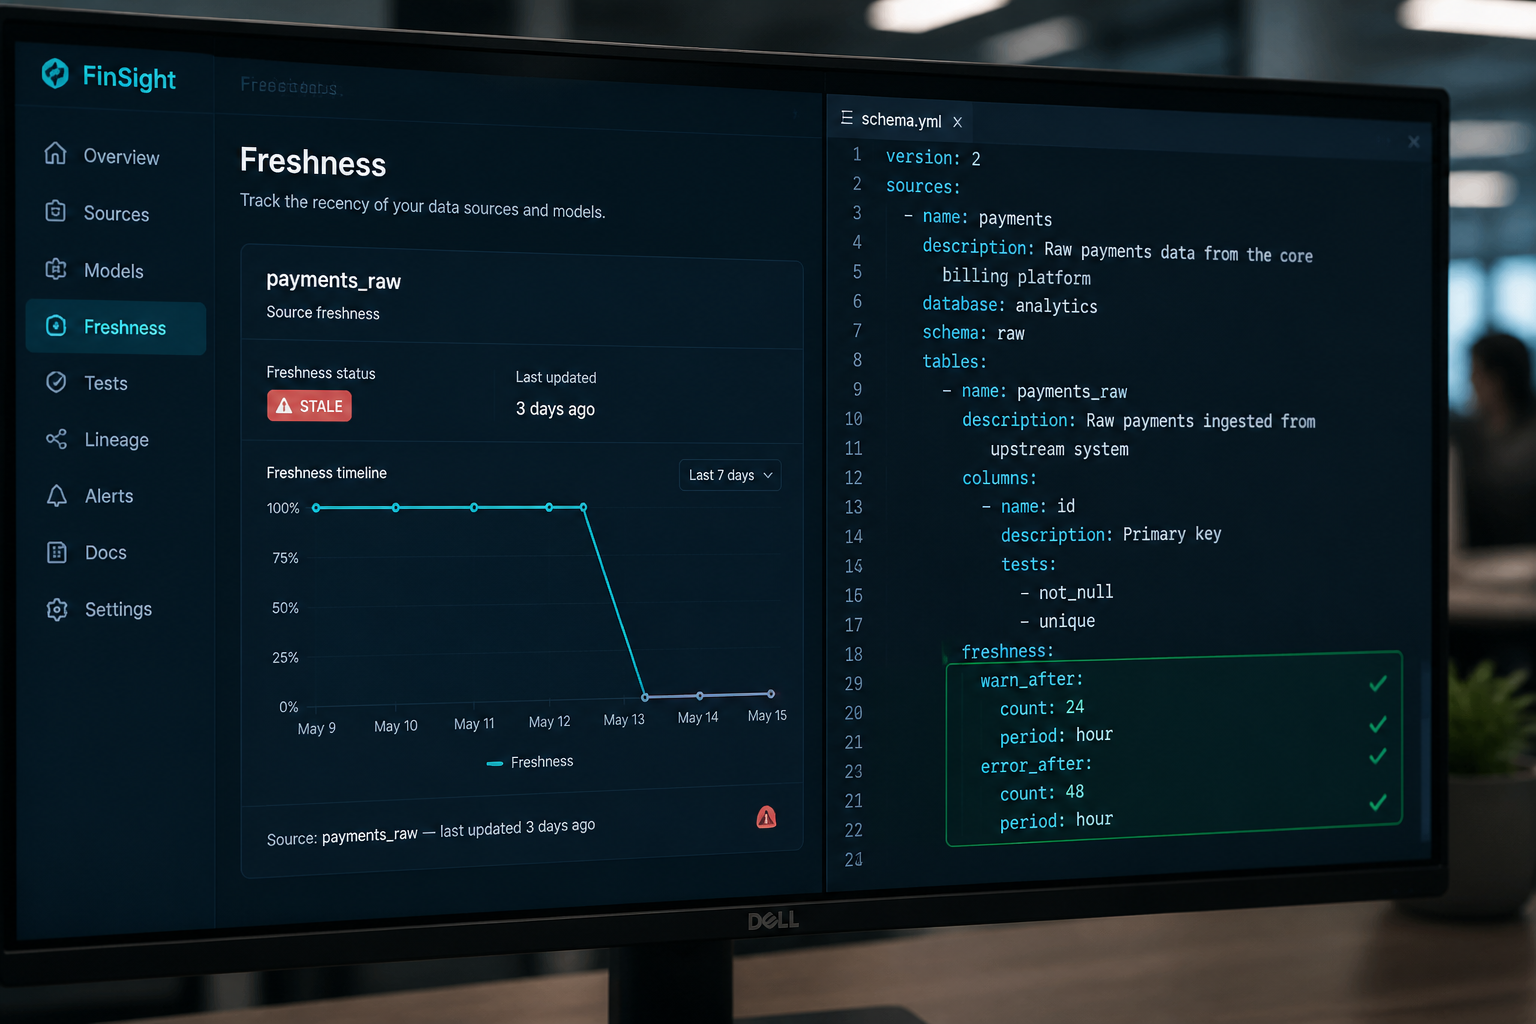
Once you have your list of unconfigured sources, the fix is straightforward. Here is what a properly configured source block looks like in BigQuery with the most common settings:
version: 2

sources:
  - name: payments_raw
    database: your_project
    schema: payments_ingestion
    tables:
      - name: transactions
        description: "Raw transaction events from the payment processor webhook"
        loaded_at_field: _ingested_at
        freshness:
          warn_after: {count: 6, period: hour}
          error_after: {count: 24, period: hour}

      - name: settlements
        description: "Daily settlement files from the acquiring bank"
        loaded_at_field: _ingested_at
        freshness:
          warn_after: {count: 25, period: hour}
          error_after: {count: 49, period: hour}
A few things to get right:
Choose warn_after and error_after thresholds based on actual delivery cadence, not gut feel. Flaky freshness checks occur when timing windows are too tight. If your source updates at 6:00 AM but occasionally arrives at 6:15 AM, a freshness check at 6:05 AM will intermittently fail. Build a realistic buffer on top of your expected delivery window. For a daily batch source that arrives by 7 AM, a warn_after of 25 hours and error_after of 49 hours is more useful than 24/48 on the dot.
The loaded_at_field must be in UTC. Timezone mismatches are common mistakes — if your ingestion layer stamps records in local time and BigQuery interprets them as UTC, your freshness check will report false errors or, worse, false passes.
For tables with no timestamp column, since dbt 1.7, some adapters including BigQuery can automatically retrieve the last update time from database metadata, so you can omit loaded_at_field and let dbt use INFORMATION_SCHEMA instead. This is useful for reference tables that are loaded wholesale rather than appended.
For static reference tables that genuinely never change, set freshness: null explicitly. This signals intent — it tells anyone reading the YAML that the absence of a freshness check is a deliberate decision, not an oversight. That distinction matters enormously when someone is debugging a pipeline at 11 PM.
For more on controlling BigQuery query costs generated by freshness checks at scale, see our post on BigQuery Scheduled Query Costs: Find the Query Wrecking Your Bill — the same discipline applies to orchestrating freshness runs efficiently.
How to Stop This Happening Again
Finding and fixing the current gap is one problem. Preventing the next engineer from shipping a source without freshness configured is a different one — and it requires process, not just documentation.
Add a dbt project-level default freshness block. In dbt_project.yml, you can set a default freshness policy at the source level:
sources:
  your_project_name:
    +freshness:
      warn_after: {count: 12, period: hour}
      error_after: {count: 24, period: hour}
    +loaded_at_field: _ingested_at
This applies to every source in the project unless explicitly overridden. It means a new source added without its own freshness block inherits a sensible default rather than having no check at all. This single change is the highest-leverage fix available — it closes the gap for all future sources automatically.
Run dbt source freshness in your CI pipeline, not just in production. If you run it only after deployment, you find stale data in production. If you run it in CI with a --select flag scoped to sources touched by the PR, you catch broken ingestion before it merges. The dbt source freshness command queries all defined source tables, determining their freshness based on your config — and if any source is stale, dbt exits with a nonzero exit code, which fails the CI run cleanly.
Wire freshness failures to your alerting channel. A freshness error that appears only in your orchestration logs at 3 AM and is cleared silently by the next successful run is not alerting — it is logging. The check needs to route to Slack, PagerDuty, or wherever your team actually looks. Monitor scheduled jobs so failures surface as alerts, not as stale dashboards.
Add a PR checklist item for new sources. Low-tech, high-impact. A single line in your PR template — "Does every new source table have a freshness block or an explicit freshness: null?" — catches the vast majority of omissions before they merge. Pair this with dbt project governance practices that make source YAML the authoritative contract for every raw table.
In our work with fintech and payments companies, we have seen a single missing freshness check on a transaction source cause a reconciliation dashboard to show T-2 data for three days without anyone noticing — until a client escalated a discrepancy. The source pipeline had silently failed, the dbt models had rebuilt successfully on cached data, and the dashboard looked completely normal. The only signal that anything was wrong was the reconciliation gap that a client caught before the internal team did. That is the real cost of an unconfigured freshness block: not a broken pipeline, but a pipeline that looks healthy while serving wrong data downstream.
Frequently Asked Questions
Q: What happens if I run dbt source freshness on a source with no freshness config?
A: dbt skips it entirely and reports no result for that source. There is no warning, no error, and no indication that the source was not checked. This is the core problem — the absence of config produces the absence of signal, not a visible failure.
Q: Can I set a project-wide default freshness in dbt so I don't have to configure every source individually?
A: Yes. In dbt_project.yml, add a +freshness block and +loaded_at_field under your sources configuration. Every source without its own override will inherit the project default. This is the single most effective way to eliminate unconfigured sources going forward.
Q: What should I set for warn_after and error_after thresholds?
A: Base them on your actual ingestion cadence, not round numbers. For hourly sources, warn_after: 2 hours and error_after: 6 hours is a reasonable starting point. For daily batch sources, warn_after: 25 hours and error_after: 49 hours gives you a realistic buffer above the expected delivery window without generating false alarms.
Q: Does BigQuery INFORMATION_SCHEMA __TABLES__ give accurate last-modified timestamps?
A: Yes — last_modified_time in __TABLES__ reflects the time of the most recent DML operation on the table (INSERT, UPDATE, DELETE, or LOAD). It is a reliable proxy for freshness for append-only ingestion patterns. For streaming inserts, there can be a short lag before the metadata updates, so factor in a small buffer.
Q: My source has no timestamp column — can I still use dbt source freshness?
A: Yes. Since dbt 1.7, BigQuery (along with Snowflake, Redshift, and Databricks) can compute freshness from warehouse metadata without a loaded_at_field. Simply omit the loaded_at_field key from your source config and dbt will use INFORMATION_SCHEMA metadata to determine when the table was last modified.
Unconfigured dbt sources are one of the quietest ways a data platform accumulates trust debt — dashboards that look live but are serving yesterday's numbers, reconciliations that drift without anyone noticing, and engineering teams that only find out something broke when a stakeholder escalates. At Fintel Analytics, we audit source freshness coverage as a core part of every data stack review we deliver for early-stage and growth-stage companies — and we almost always find gaps. If your dbt project has grown faster than your data quality coverage, that is a fixable problem, and the fix takes hours, not weeks.