
The Short Answer: You Are Probably Overwriting Data You Will Never Get Back
dbt snapshots in BigQuery implement Slowly Changing Dimensions (SCD) Type 2 — they capture every historical version of a dimension record, timestamping when each version was valid. If your data warehouse does not have snapshots running, every time a customer changes tier, a product changes category, or a merchant changes status, the old value is gone. Your historical reports silently shift, and nobody notices until someone asks a question the data can no longer answer.
This is one of the most common and most damaging data modelling gaps we see in growth-stage companies. It does not announce itself. It just quietly corrupts your understanding of the past.
Why Most Early-Stage Data Teams Get SCD Wrong
When a company first builds its data warehouse on BigQuery, the immediate pressure is to get something working. Ingestion gets set up, staging models get built, a few dashboards go live. The question of what happens when dimension data changes rarely surfaces until much later — and by then, history has already been lost.
Here is the problem in concrete terms. Customers move to new addresses, products change categories, and employees switch departments. If your analytics only stores the current state, you lose the ability to answer questions like "what was this customer's region when they placed that order?" or "how has this product's category changed over the past year?"
The way you choose to model these changes determines what your business can actually measure. Get it right, and you unlock powerful data insights. Get it wrong, and your metrics become unreliable.
In practice, what we see most often is one of three failure modes:
SCD Type 1 masquerading as something intentional. The source system sends an updated record, the ELT tool overwrites the row, and the warehouse reflects only the current state. Nobody made a deliberate choice here — it is just the default behaviour of most ingestion tools. If a dimension like customer_segment or product_pricing is clearly changing but the current process simply overwrites the data, those tables represent the biggest risks to your reporting and analysis.
Snapshots configured but never tested. The team adds a dbt snapshot, runs it once, and moves on. Nobody validates whether the check strategy is actually detecting changes. Nobody tests whether the updated_at column in the source system is reliably populated. Six months later, the snapshot table has a single row per customer — because the source never emits a reliable change signal.
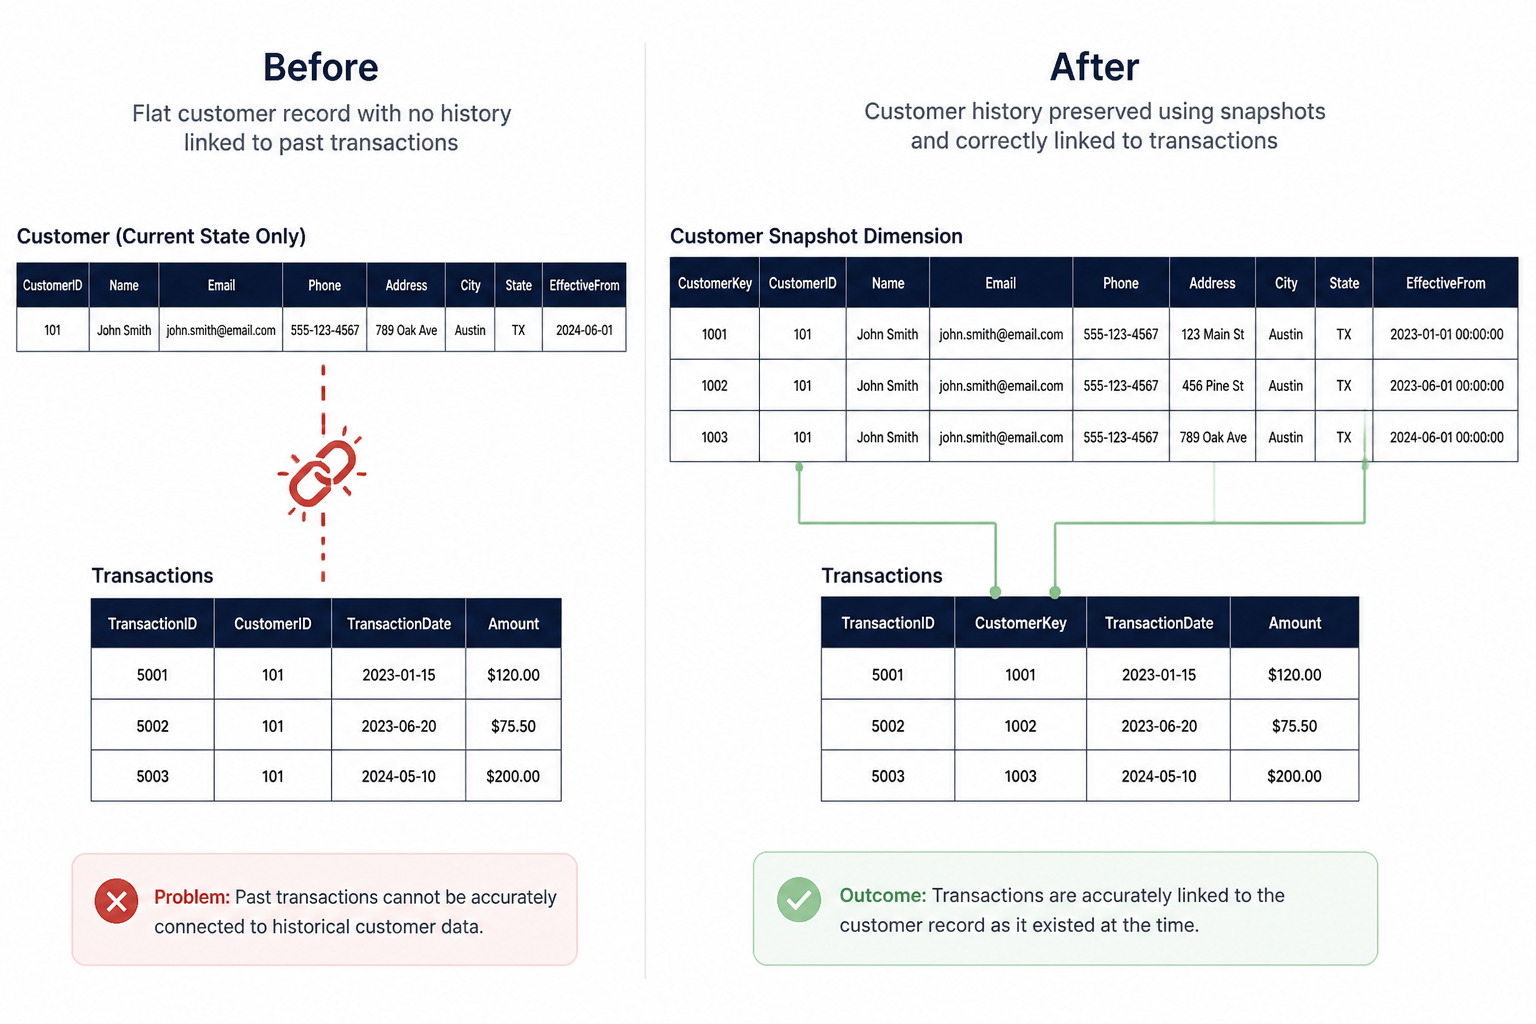
Snapshots running but joined incorrectly in downstream models. This is the worst one. The snapshot table is correct, but the downstream dim_customers model joins to it using the natural key rather than the surrogate key, pulling the current version of the record rather than the version that was active at the time of the event. If an order was placed on a specific date and the customer changed region after that date, the order should join to the old version of the customer record — the one that was active when the order happened. Getting this join wrong means your historical segmentation analysis is based on where customers are now, not where they were then.
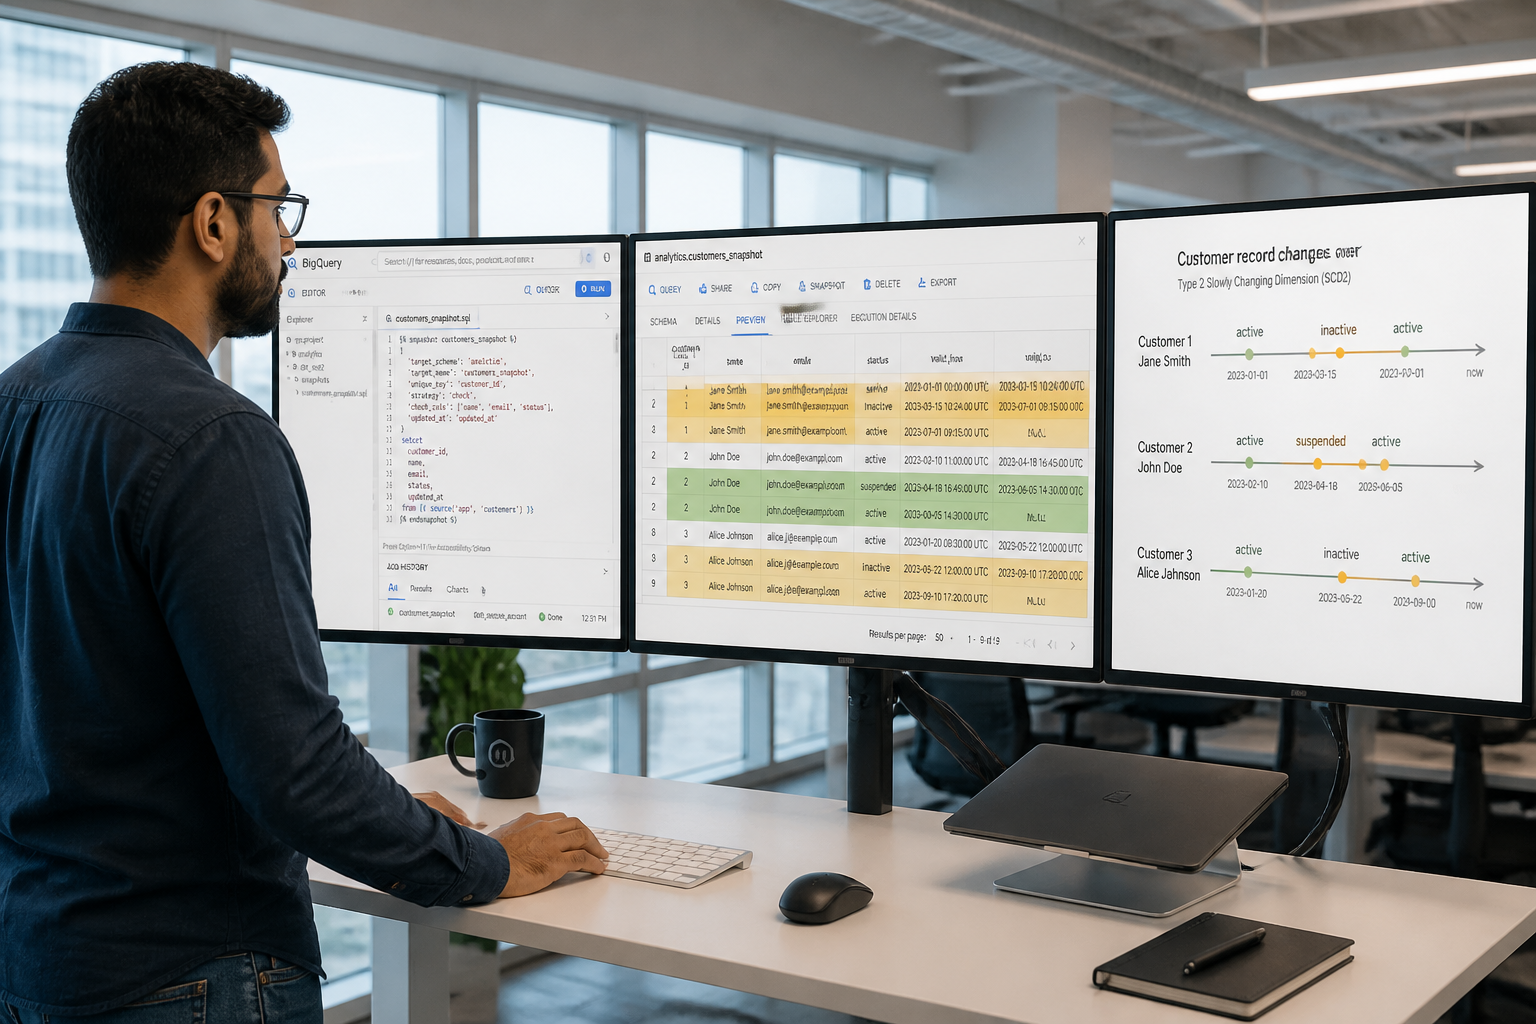
📺 Watch: Dbt Materializations - Incremental Snapshot | data build tool | Slowly Changing Dimension SCD Type 2

How dbt Snapshots Actually Work in BigQuery
Slowly changing dimensions solve the historical tracking problem by keeping a history of changes. dbt snapshots implement SCD Type 2 automatically — they track when values change and maintain a complete history with valid-from and valid-to timestamps.
Here is what the resulting snapshot table looks like in practice. A customer who starts on a Silver tier in one region, upgrades to Gold, then moves to a different region produces three rows:
customer_id | region   | tier   | dbt_valid_from      | dbt_valid_to
cust-001    | us-west  | silver | 2026-01-01 00:00:00 | 2026-01-15 00:00:00
cust-001    | us-west  | gold   | 2026-01-15 00:00:00 | 2026-02-01 00:00:00
cust-001    | us-east  | gold   | 2026-02-01 00:00:00 | NULL
A snapshot in dbt creates a version history of each row of data. When you create a snapshot, dbt adds metadata columns including dbt_valid_from and dbt_valid_to, which indicate the time range during which a particular version of a record was valid — this is the mechanism that implements Type 2 SCDs.
There are two strategies for detecting changes:
Timestamp strategy — dbt compares the updated_at column in the source. If the timestamp is newer, the row has changed. This is more efficient, but it requires a reliable timestamp in the source. The check strategy, by contrast, compares column values directly. The check strategy is slower but safer when source systems do not reliably update a timestamp on every change.
One BigQuery-specific consideration: dbt snapshots use MERGE statements under the hood, which on BigQuery are billed differently from standard INSERT or SELECT operations. On large dimension tables, a check strategy comparing all columns can become expensive if your ingestion layer is loading full refreshes. In practice, we scope check_cols to only the attributes that actually matter for historical analysis — typically status, tier, segment, pricing band, and region — rather than diffing every column on every run.
The other configuration worth getting right from day one: invalidate_hard_deletes. If a customer disappears from the source entirely, dbt will close their latest row instead of leaving it as current (falsely). Without this, deleted records stay flagged as active indefinitely, and your active customer counts become meaningless.
The Attributes That Actually Need Type 2 Tracking
Not every column in a dimension table needs historical tracking. Applying Type 2 to everything is overkill — it inflates your snapshot tables and makes downstream joins more complex than necessary. Type designations that vary by attribute are the rule rather than the exception. A single customer dimension routinely has Type 1 attributes for fields like display name, Type 2 attributes for region and tier, and possibly a Type 3 attribute for prior-territory analysis. Implementations that treat SCD type as a dimension-wide setting either over-version everything or fail to track the attributes that matter.
In our work with growth-stage companies, the attributes that consistently need Type 2 tracking fall into three categories:
Attributes that drive cohort or segment analysis. Customer tier, subscription plan, risk band, merchant category, pricing cohort. These are the dimensions you will want to slice your historical transaction data by — and the analysis only makes sense if you are using the segment the customer was in at the time of the event, not the one they are in today.
Attributes used in compliance or audit contexts. Regulatory status, KYC verification level, AML risk score, account status. If a regulator asks what status a customer held on a particular date, you need Type 2 history. An overwritten field is not an audit trail.
Attributes that affect revenue attribution. Sales region assignment, account owner, partnership tier, referral channel. If commission calculations or partner revenue splits are tied to these dimensions, you need the version that was active when the transaction occurred — not the current assignment.
Attributes that do not need Type 2 tracking: contact details like email or phone number (Type 1 is typically fine), display names, and any field that is corrected rather than changed (a typo fix is not a dimension change worth preserving).
If you are already thinking about how this pattern applies to your stack, explore how Fintel Analytics approaches data modelling and warehouse design — we build these patterns for growth-stage companies from the ground up, and we have seen every variant of this problem in production.
The Production Mistakes We See Repeatedly
A pattern we see repeatedly when joining engagements mid-flight: the snapshot infrastructure exists but has never been validated end to end. Here are the specific failure modes that actually hurt businesses.
Snapshots not running in the right orchestration order. dbt snapshots must run before dbt run — they need to capture the source state before any transformation models touch it. dbt has SCD Type 2 functionality baked in with snapshots, and they should be run before dbt run in production. When orchestration is set up incorrectly and snapshots run after transformations, they may be reading from a partially transformed layer rather than the raw source — corrupting the history silently.
Missing surrogate keys in fact table joins. This is the join problem described above. Always use surrogate keys in fact tables — never natural keys — when joining to SCD dimensions. The surrogate key in a Type 2 setup is what ties a fact record to a specific version of the dimension. Joining on the natural key pulls the current version every time, collapsing all historical versions into one.
No test coverage on snapshot freshness. Snapshots silently stop working when source schemas change, when the updated_at column stops being populated, or when the source ingestion layer starts loading data late. Without a freshness test or a row-count assertion on the snapshot table, you may not notice for weeks. We always pair snapshot models with tests on dbt_valid_from recency and record count trends.
A related risk worth flagging: schema drift in the source. If the source system adds or removes columns that appear in your check_cols list, the snapshot can fail or produce unexpected results. For a deeper treatment of how to detect and handle source schema changes before they break production, see our post on dbt source schema drift.
One real example from our delivery work: a Series A fintech had been running customer tier snapshots for eight months. When we audited the stack, we found the check_cols configuration had been set to a single column that the source system had stopped populating six months earlier. The snapshot table showed one version per customer — none of the tier changes that had happened in that period were captured. The team's cohort analysis for the previous two quarters was based entirely on current-state tiers, not historical ones. The analysis had to be rebuilt from scratch using event logs where they existed and marked as unavailable where they did not.
Implementing dbt Snapshots in BigQuery: A Practical Checklist
For teams setting this up for the first time or auditing an existing implementation, here is the sequence that actually works in production:
1. Identify which dimensions need Type 2 tracking. Work backwards from the analytical questions your business needs to answer historically. If the question involves attributing past events to dimension states ("what was the customer's plan when they churned?"), you need Type 2.
2. Confirm your source has a reliable change signal. If you have a trustworthy updated_at column, use the timestamp strategy. If you do not, use the check strategy on a scoped list of check_cols. Never use check_cols = 'all' on large tables in BigQuery — it will scan every column on every run and your query costs will reflect that.
3. Configure invalidate_hard_deletes: true unless you have a specific reason not to. Stale active records in your snapshot table will eventually cause incorrect active counts.
4. Use surrogate keys in fact table joins. Generate a surrogate key in the snapshot model itself (dbt's dbt_utils.generate_surrogate_key macro works well here), and carry that key into your fact tables at load time — not at query time.
5. Add freshness and coverage tests. At minimum: assert that dbt_valid_from for current records has been updated within your expected pipeline latency window. Add a row count check that compares snapshot record counts to source record counts.
6. Run snapshots in orchestration before dbt run. Whether you use dbt Cloud, Airflow, or Dagster, the snapshot step must precede the transformation DAG.
7. Document which attributes are Type 1 vs Type 2 in your dbt model descriptions. Future team members (and your future self) should not have to reverse-engineer this from the SQL.
For teams who also need to track how incremental loads interact with snapshot tables under high data volumes, the patterns we describe in our guide to dbt incremental models strategy apply directly here — particularly around late-arriving data and how to handle records that arrive out of sequence.
Frequently Asked Questions
Q: What is the difference between dbt snapshots and dbt incremental models?
A: dbt incremental models process only new or changed rows in a fact or event table, appending or updating records efficiently. dbt snapshots specifically implement SCD Type 2 for dimension tables — they track versions of records over time, adding metadata columns (dbt_valid_from, dbt_valid_to) that let you join facts to the dimension version that was active at the time of the event. They serve different purposes and are typically used together in a well-structured warehouse.
Q: How do dbt snapshots handle hard deletes in BigQuery?
A: By default, dbt snapshots do not detect records that disappear from the source — the last known version stays marked as current indefinitely. Setting invalidate_hard_deletes: true in your snapshot configuration tells dbt to close the dbt_valid_to timestamp on any record that no longer appears in the source query, correctly marking it as inactive. This is almost always the right setting for production snapshots.
Q: How expensive are dbt snapshots to run in BigQuery?
A: Cost depends heavily on your strategy choice and table size. The timestamp strategy is cheaper — it only needs to compare the updated_at field. The check strategy triggers full column comparisons, and using check_cols = 'all' on a large table will scan every column on every run. On BigQuery's on-demand pricing model, scope your check_cols to the minimum set of attributes needed for historical analysis, and consider partitioning your snapshot tables on dbt_valid_from to reduce scan costs on downstream queries.
Q: Can I backfill historical dimension data if I did not have snapshots running?
A: Rarely, and never completely. If your source system retains an event log or change log, you can sometimes reconstruct historical states from that. If the source only stores current state and you have no change log, the history is gone. This is why starting snapshots as early as possible matters — retroactive correction of Type 2 history is operationally complex and often incomplete.
Q: Which dbt snapshot strategy should I use — timestamp or check?
A: Use the timestamp strategy if your source system reliably populates an updated_at column on every change — it is faster and cheaper to run. Use the check strategy if the source does not have a reliable timestamp, or if you have seen cases where records are updated without the timestamp being refreshed. When in doubt, validate the timestamp strategy against a known change in your source data before trusting it in production.
Losing dimension history is one of those data modelling problems that compounds silently — by the time you notice your cohort analysis is broken or your historical segmentation reports have shifted, the data needed to reconstruct the truth may already be gone. At Fintel Analytics, we have helped fintech, payments, and e-commerce businesses audit and rebuild their dimension modelling from the ground up — identifying which tables need Type 2 history, instrumenting the correct snapshot configurations, and building the test coverage that catches failures before they corrupt production dashboards. If your team is not certain whether your historical dimension data is being preserved correctly, that uncertainty is worth resolving now, before your next investor review or board reporting cycle depends on it.