
dbt Full-Refresh Models in BigQuery Are Silently Draining Your Budget
dbt full-refresh models in BigQuery recompute and rewrite an entire table on every pipeline run — and at small data volumes, that's fine. But as your tables grow past a few hundred gigabytes, every full-refresh run becomes a full-table scan billed at $6.25 per TB, repeated hourly or daily, indefinitely. The cost doesn't announce itself. It compounds. And most teams don't notice until the GCP bill lands.
This is one of the most predictable cost failures we see in early-stage data stacks. A team builds a clean dbt project on BigQuery, everything works beautifully at low volumes, and then — six months and a few million rows later — the infrastructure bill has tripled without any obvious cause. The culprit is almost always a cluster of full-refresh models that were never revisited after initial build.
This post covers exactly how to find those models, how to calculate what they're actually costing you, and how to migrate them to incremental safely — without breaking downstream dependencies.
Why Full-Refresh Models Become a Cost Problem in BigQuery
To understand the cost mechanics, you need to understand how BigQuery charges. BigQuery charges by bytes scanned, not rows returned. This is the detail that catches teams off guard. A WHERE clause filters your output, but if your model is materialised as a table using full_refresh, dbt drops and recreates the entire table on every run — which means BigQuery reads every byte of every source table involved in the transformation, every single time.
Google BigQuery charges $6.25 per TB scanned on-demand in 2026. That number sounds manageable in isolation. It isn't once you account for frequency and fan-out.
Consider a straightforward example: a staging model that reads from a 200 GB raw events table, runs hourly via an Airflow DAG, and is materialised as a table with no partitioning or incremental logic. At $6.25 per TB, each run costs roughly $1.25. Across 24 hours that's $30. Across a month, $900 — for a single model. Stack five or six models with similar characteristics and you're looking at a meaningful monthly line item that buys you nothing extra over an incremental equivalent.
Full-refresh model run times balloon from minutes to hours as data grows — and scanning a 2 TB table every hour just to retrieve a few MB of new data pushes monthly BigQuery bills sharply upward.
The most expensive habit in BigQuery is the broad scan. Because BigQuery uses columnar storage and reads only the columns you request, full-refresh models that use SELECT * force BigQuery to scan every column in the source — billing you for data you don't need.
The compounding factor is scheduling frequency. Most teams configure their dbt jobs to run more frequently than the data actually needs to be refreshed — because the run felt fast when the table was 10 GB. Nobody revisits that cadence once the table is 500 GB.
📺 Watch: What Is DBT and Why Is It So Popular - Intro To Data Infrastructure Part 3

How to Find All Full-Refresh Models in Your dbt Project
Before you can fix anything, you need a complete inventory. There are two places to look: your dbt project configuration files, and BigQuery's own job history.
Step 1: Grep your project for full-refresh materialisations
In your dbt project, any model can be a silent full-refresh offender if it meets one of three conditions:
- It has
materialized='table'in its config — which defaults to full-refresh behaviour on every run - It has
materialized='incremental'but also hasfull_refresh=truehardcoded in its config or in the job invocation flags - It has no materialisation set at all and inherits a project-level
materialized='table'default
Run this in your terminal from the project root to catch the first and third categories:
grep -r "materialized='table'" models/
grep -r "materialized: table" models/
Also check your dbt_project.yml for project-level defaults:
models:
  your_project:
    +materialized: table
A single line like this at the project root will make every model a full-refresh table unless individually overridden — and in a large project, dozens of models may be inheriting this silently.
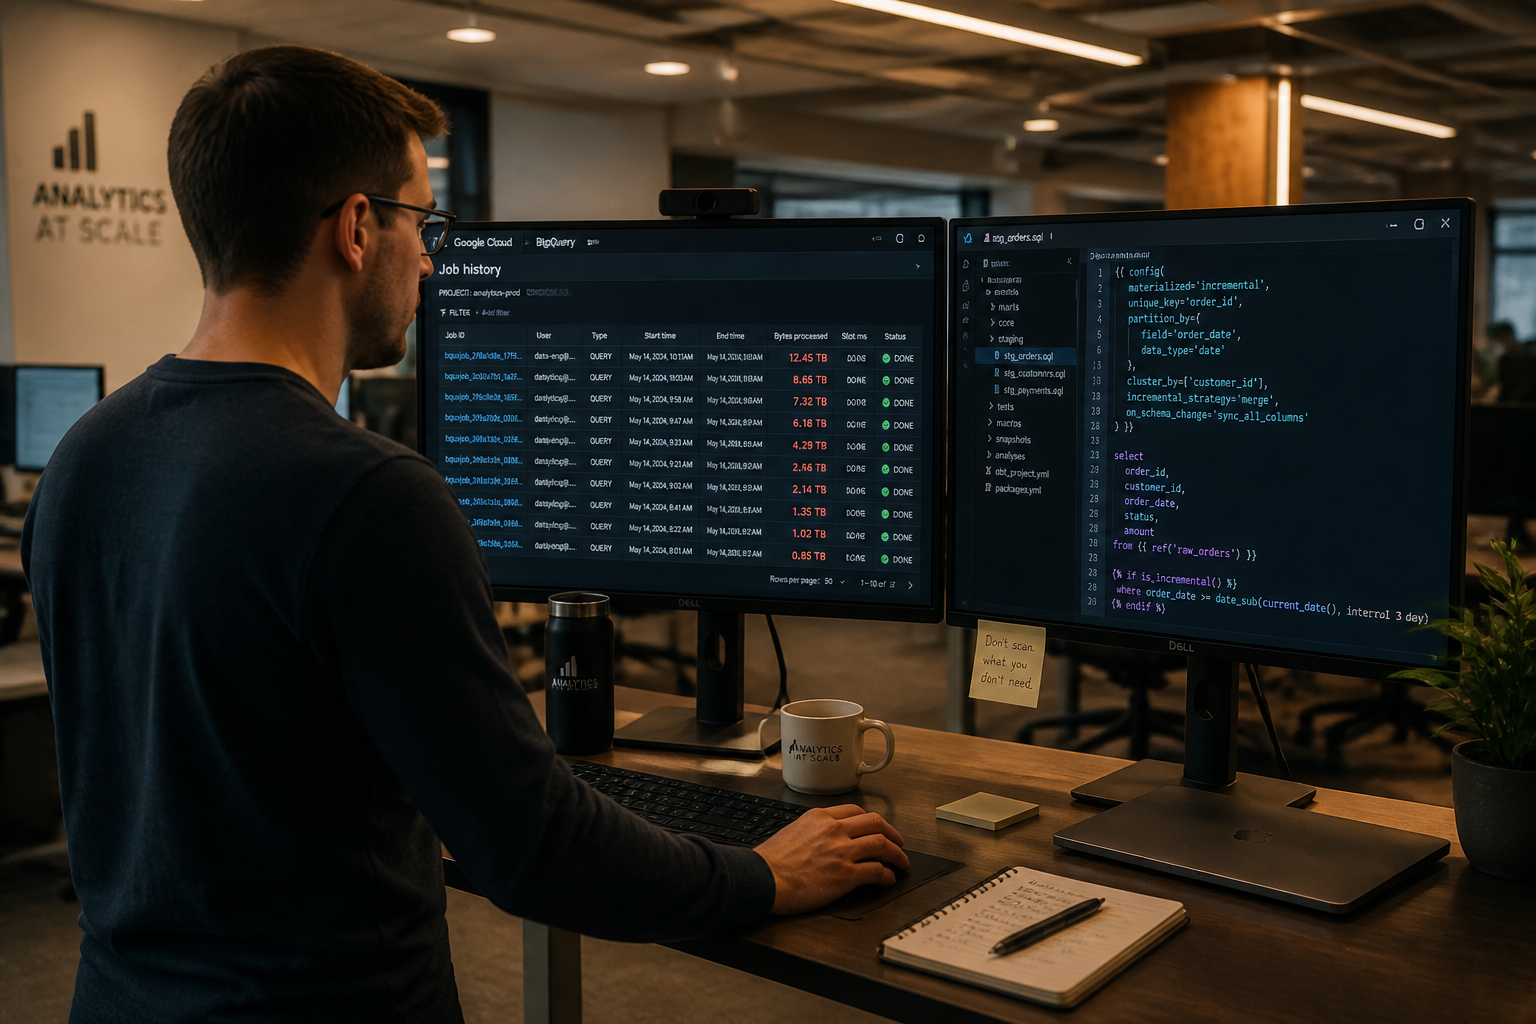
Step 2: Cross-reference with BigQuery INFORMATION_SCHEMA
Once you have the list of model names, query BigQuery's job history to see how much data each corresponding table write is scanning:
SELECT
  job_id,
  destination_table.table_id AS model_name,
  total_bytes_processed / POW(1024, 4) AS tb_scanned,
  ROUND((total_bytes_processed / POW(1024, 4)) * 6.25, 4) AS estimated_cost_usd,
  creation_time
FROM
  `region-us`.INFORMATION_SCHEMA.JOBS_BY_PROJECT
WHERE
  statement_type = 'CREATE_TABLE_AS_SELECT'
  AND creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
ORDER BY
  total_bytes_processed DESC
LIMIT 50;
This surfaces the highest-scanning table writes in the last seven days — which is almost always dominated by your worst full-refresh offenders. Sort by estimated_cost_usd and you'll see exactly where the money is going.
If you want to look specifically at BigQuery scheduled query costs across your entire environment, that post covers the broader INFORMATION_SCHEMA approach in detail.
What the Real Cost Actually Looks Like (With Numbers)
A pattern we see repeatedly in our work with growth-stage companies: the BigQuery bill is climbing quarter-on-quarter, the team assumes it's driven by data volume growth, and they start investigating storage. Storage is almost never the problem. The bill spikes when data volumes grow, a few scheduled queries get added, and someone writes a broad scan against a multi-terabyte table — and the embarrassing part is that most of these costs come from scanning data you don't actually need.
Let's build a realistic cost model for a Series A fintech with a moderately mature dbt project:
| Model | Table size | Run frequency | TB scanned/day | Daily cost |
|---|---|---|---|---|
fct_transactions | 800 GB | Every 2 hrs | 9.6 TB | $60.00 |
fct_user_events | 400 GB | Hourly | 9.6 TB | $60.00 |
dim_merchants | 120 GB | 4× daily | 0.48 TB | $3.00 |
fct_settlements | 250 GB | Every 3 hrs | 2.0 TB | $12.50 |
| Total | 21.68 TB | $135.50 |
That's roughly $4,065 per month from four models — before you account for the query cost of dashboards and analysts running ad-hoc queries against those same tables. Partitioning and clustering reduce query costs by 60–90% by limiting data scanned. Converting just these four models to incremental with correct partition filters could cut that bill to somewhere between $400 and $1,600 per month.
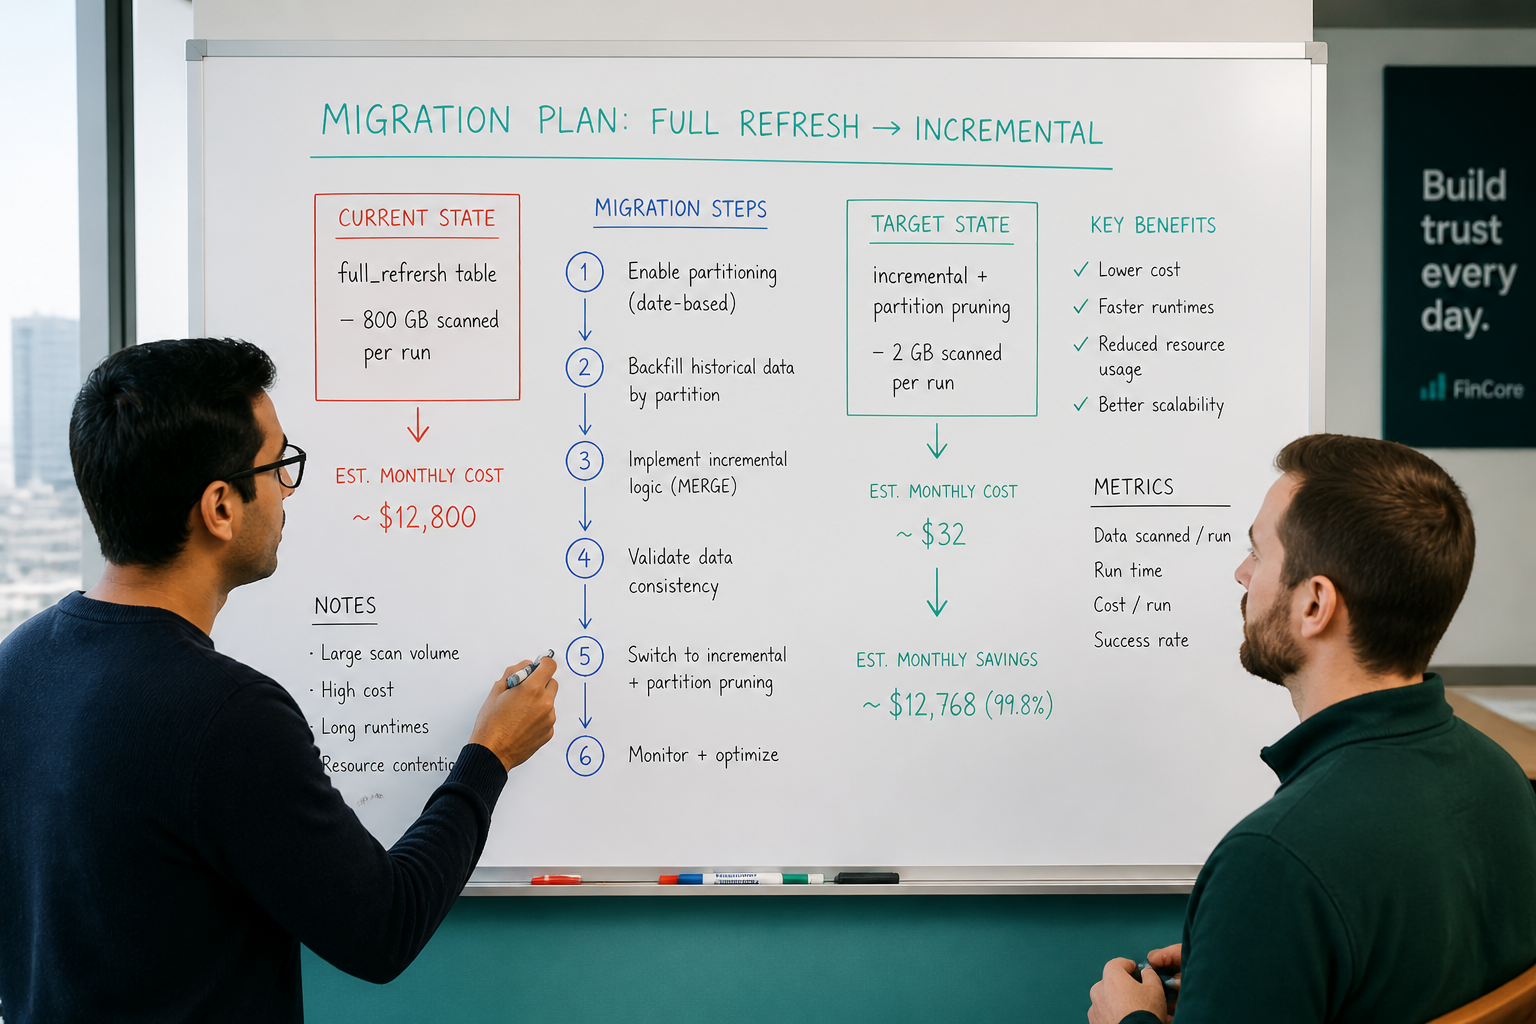
One fintech we worked with had a reconciliation model running as a full-refresh table on a 30-minute schedule. By the time we audited it, the table was 1.1 TB and the model was responsible for over 40% of total monthly BigQuery spend. Rebuilding it as an incremental model with date-based partitioning and a merge strategy reduced the per-run scan to under 2 GB — the day's new records only.
If you're looking to implement a systematic audit of your BigQuery spend, explore how Fintel Analytics approaches this — we work with growth-stage companies globally to find and eliminate exactly these kinds of cost leaks before they compound.
How to Migrate a Full-Refresh Model to Incremental Without Breaking Production
This is where most engineers hesitate — and rightly so. A badly executed migration to incremental can produce silent duplicates, missed records, or broken downstream models. Here is the safe migration path we follow in production.
Step 1: Understand the model's update pattern
Before touching anything, answer three questions:
- Does the source data mutate (updates to existing rows) or only append (new rows only)?
- Is there a reliable
updated_ator event timestamp column? - What is the acceptable staleness tolerance for downstream consumers?
If the source only appends and has a reliable timestamp, you can use insert_overwrite or append strategy with high confidence. If the source mutates, you need merge — which is more powerful but requires a unique key and careful deduplication logic.
Step 2: Add partitioning and clustering before switching strategy
Partition filters must use literal values, not subqueries — otherwise BigQuery cannot trigger partition pruning and effectively scans the full table. On top of partitioning, cluster by high-frequency filter columns such as user_id, event_type, or status to accelerate WHERE conditions and aggregations.
Your config block should look something like this:
{{ config(
  materialized='incremental',
  incremental_strategy='merge',
  unique_key='transaction_id',
  partition_by={
    'field': 'created_date',
    'data_type': 'date',
    'granularity': 'day'
  },
  cluster_by=['merchant_id', 'status']
) }}
Step 3: Write the incremental filter
The incremental filter is the most critical part. It tells dbt which records from the source to process on each run:
WHERE created_at >= (
  SELECT
    TIMESTAMP_SUB(MAX(created_at), INTERVAL 1 HOUR)
  FROM {{ this }}
)
The one-hour lookback buffer is deliberate — it handles late-arriving records and protects against edge cases where the pipeline ran slightly late and the timestamp boundary would otherwise miss data.
Step 4: Do a controlled first-run backfill
Run the model once with --full-refresh explicitly, then switch to normal incremental runs. This ensures the table is fully populated before the incremental logic takes over. Never assume the incremental filter will correctly backfill missing history — it won't.
Step 5: Validate downstream models
Run your dbt tests across all downstream models after migration. If you're not sure which models depend on the one you just changed, the dbt lineage blind spots post covers exactly how to audit your dependency graph before making structural changes.
The operations performed by dbt while building a BigQuery incremental model can be made cheaper and faster by using a clustering clause in the model configuration — and these performance and cost benefits apply to incremental models built with either the merge or the insert_overwrite incremental strategy.
When Should You Keep Full-Refresh Materialisations?
Not every table should be incremental. Full-refresh is the right choice in specific, well-understood scenarios — and forcing incremental where it doesn't fit creates more problems than it solves.
Keep full-refresh when:
- The source table is small (under 50 GB) and the transformation logic is complex enough that incremental filtering would be error-prone
- The model is a
dim_(dimension) table where SCD (slowly changing dimension) logic is being handled by dbt snapshots instead - The business logic requires recalculating derived metrics from the full historical dataset on every run (e.g. rolling 90-day aggregates that reference every row)
- The table is only refreshed once per day and the scan cost is genuinely low
Switch to incremental when:
- The source table is large and growing (above 100 GB is a reasonable trigger point)
- The model runs more than once per day
- The update pattern is append-only or has a clear
updated_atcolumn - The model appears in your top 10 BigQuery cost queries by bytes scanned
One of the most dangerous things in BigQuery is allowing uncontrolled queries to run indefinitely — without safeguards, a single query can run for a very long time consuming slots and generating large costs. Full-refresh models on large tables with high run frequency are precisely this failure mode in slow motion.
For teams querying more than 20–30 TB per month, switching from on-demand to BigQuery Editions capacity pricing saves 40–60% — but that switch only makes sense if you've already eliminated the unnecessary scans that full-refresh models generate. Paying for reserved capacity against a workload that still runs full-refresh on large tables is paying twice for the same waste.
Frequently Asked Questions
Q: What is the difference between a dbt full-refresh model and an incremental model in BigQuery?
A: A full-refresh model drops and recreates the entire table on every dbt run, causing BigQuery to scan all source data every time — regardless of how much new data actually exists. An incremental model only processes records that are new or updated since the last run, drastically reducing bytes scanned and therefore cost. At small data volumes the difference is negligible; at hundreds of gigabytes it becomes the dominant cost driver in your BigQuery bill.
Q: How do I find which dbt models are causing the most BigQuery cost?
A: Query INFORMATION_SCHEMA.JOBS_BY_PROJECT in BigQuery, filtering for CREATE_TABLE_AS_SELECT statement types in the last 7–30 days, and sort by total_bytes_processed descending. Cross-reference the destination table names against your dbt model manifest to identify the offending models. This gives you a ranked cost list tied directly to specific dbt transformations.
Q: Is it safe to convert a dbt full-refresh model to incremental in production?
A: Yes, if done carefully. The key steps are: (1) add partitioning and clustering config first, (2) write a correct incremental filter with a lookback buffer for late-arriving data, (3) run with --full-refresh once to populate the base table, then switch to incremental runs, and (4) run all downstream dbt tests before declaring success. Skipping the backfill step or using a poorly designed incremental filter are the most common causes of silent data quality issues post-migration.
Q: How much can I save by switching dbt full-refresh models to incremental in BigQuery?
A: The savings depend on table size and run frequency, but in practice the reduction is significant. Partitioning and clustering reduce query costs by 60–90% by limiting the data BigQuery scans. For a model running hourly against a 500 GB table, switching to incremental with a 1-hour lookback and correct partition pruning can cut per-run scan from 500 GB to under 5 GB — a 99% reduction in bytes billed for that model.
Q: What dbt incremental strategy should I use for BigQuery?
A: Use insert_overwrite for append-only sources with a reliable date partition — it's the fastest and cheapest strategy in BigQuery. Use merge when your source data can update existing rows and you have a reliable unique key. Avoid append in production unless you have deduplication logic downstream — it will silently create duplicate rows on reruns. For most fintech and payments use cases, merge with a composite unique key is the safest default.
The cost of running full-refresh dbt models against large BigQuery tables is one of those problems that stays invisible right up until it becomes a budget conversation — and by that point, months of unnecessary spend have already gone out the door. At Fintel Analytics, we have audited and restructured dbt projects for Series A and Series B companies across fintech, payments, and e-commerce, consistently finding that a small number of full-refresh models account for a disproportionate share of total BigQuery spend — and that fixing them is faster than most teams expect. If your BigQuery bill has been climbing without a clear explanation, that is where we would start.