
Misusing BigQuery's STRUCT and ARRAY types in dbt models is one of the most overlooked sources of silent cost bleed in a growing data stack. Teams that flatten nested fields unnecessarily, query STRUCT sub-fields with wildcards, or unnest repeated records without upstream filters can easily double the bytes scanned on their most-run models — without a single alert firing. If your BigQuery bill is climbing quarter-on-quarter and your dbt models look "fine", there is a good chance this is part of the reason.
This post covers the specific anti-patterns we see most often in early-stage and growth-stage companies, how to detect them in your project today, and what the fix actually looks like in practice.
Why STRUCT and ARRAY Misuse Is So Hard to Spot
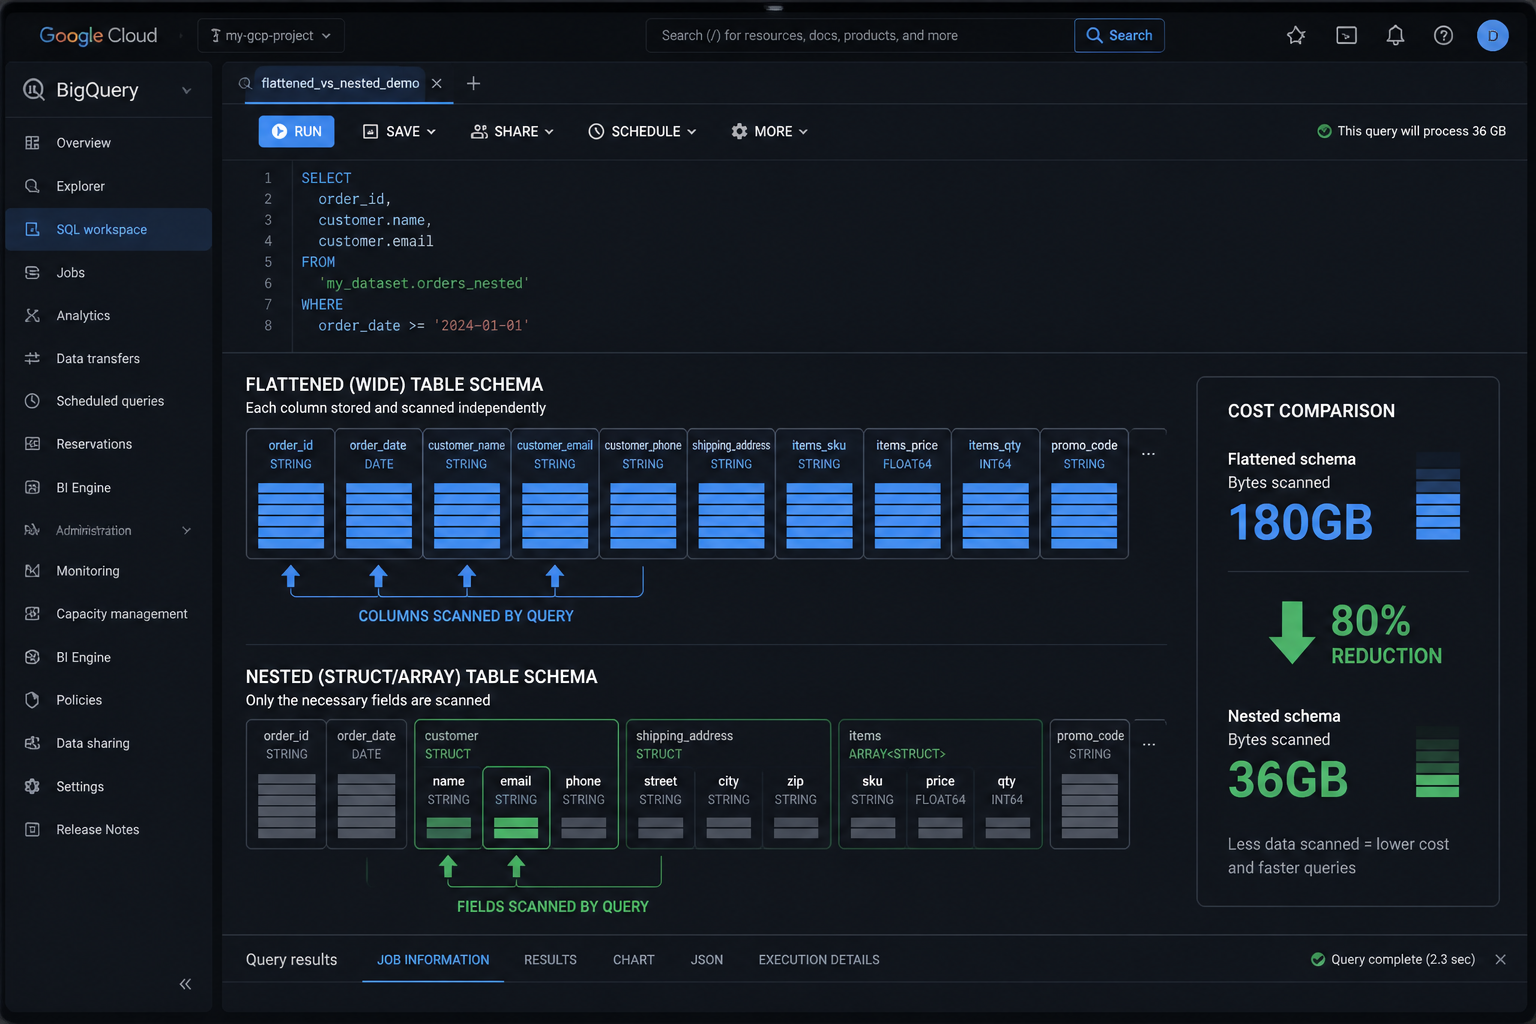
BigQuery is a columnar analytics engine. It stores each field — including each sub-field of a STRUCT — independently on disk. That means when you query only order.customer_id, BigQuery physically reads only that sub-field's column data. When you query order.* or flatten the entire STRUCT into individual columns you never use downstream, you force BigQuery to read everything.
The problem is that this cost is invisible at the model level. Your dbt run completes. Your tests pass. Your dashboard loads. The only signal is a slowly rising line on your BigQuery billing graph — and most teams only look at that when the invoice lands.
There is a second layer to this problem. Nested and repeated fields — ARRAY of STRUCT types — are genuinely powerful. BigQuery's documentation is explicit: nested and repeated columns can maintain relationships without the performance impact of preserving a fully normalised schema, and denormalising into nested structures typically outperforms equivalent multi-table joins because it eliminates the network shuffling involved in grouping operations. When teams misunderstand this and try to "fix" their nested data by flattening it into wide flat tables — often the first instinct for engineers coming from a Postgres or MySQL background — they frequently make performance worse, not better, while also increasing bytes scanned.
The result is a pattern we see repeatedly in our work with growth-stage companies: a data stack that started with sensible nested schemas from a source API, got "normalised" by well-meaning engineers, then got queried back with joins and aggregations that replicate the original nested structure — at roughly three times the cost.
The Four Anti-Patterns That Actually Cost You Money
1. Querying STRUCT sub-fields with wildcards
This is the STRUCT equivalent of SELECT *. Instead of specifying order.customer_id or order.total_amount, a model references order.* or selects the parent STRUCT column and relies on downstream models to project out what they need. Because BigQuery charges based on data scanned, and because the columnar engine has to read every sub-field of the STRUCT to satisfy the wildcard, this compounds across every model that references the output.
A practical example: a payments platform ingests transaction events with a nested metadata STRUCT containing 40 sub-fields — device info, session context, geolocation data, risk signals. If a staging model selects metadata.* and materialises that as a table, every downstream model that touches that table pays to scan all 40 sub-fields every run, even if 37 of them are never used.
2. Flattening ARRAYs without a WHERE clause before UNNEST
UNNESTing a repeated field explodes rows multiplicatively. If a transaction record contains an ARRAY of 12 line items and you unnest before filtering, BigQuery expands every row in the table — including rows you will immediately discard — before applying your predicate. The bytes scanned reflect the post-explosion row count.
The fix is to push the outer WHERE clause above the UNNEST, or to use the correlated cross join form only after partitioned pruning has reduced your working set. We covered the specific mechanics of this in our post on dbt UNNEST Without Filters in BigQuery — if you have UNNEST calls in your dbt models, that post is worth reading alongside this one.
3. Unnecessary flattening of nested source data
This is the schema design problem rather than the query problem. When a source system delivers JSON with nested objects — webhook payloads, API event streams, GA4 exports — a common instinct is to immediately flatten everything into a wide flat table in a staging model. The rationale is usually "it is easier to query". In practice, BigQuery's columnar engine handles nested structures more efficiently than the equivalent denormalised wide table with many sparse columns, because each sub-field compresses independently and queries that only touch a handful of sub-fields read a proportionally small fraction of the total data.
By flattening, you often increase both storage footprint and bytes-per-query, while also losing the ability to use BigQuery's native ARRAY aggregation functions that can eliminate otherwise expensive GROUP BY operations.
4. Materialising intermediate STRUCT-heavy models as full tables
When a model that references a deeply nested STRUCT — or that has already been partially unnested — is materialised as a table rather than a view or an incremental, every run rewrites the full dataset. If that model runs on a 4-hour schedule and the underlying table has 200GB of nested event data, you are paying for a full 200GB scan four times a day, every day. The nested fields make this worse because the row count after unnesting is typically far higher than the source row count.
This overlaps with the broader full-refresh materialisation problem we cover in dbt Full-Refresh Models in BigQuery: Stop the Silent Cost Bleed — but the nested field dimension makes the cost multiplier significantly larger than in flat-table equivalents.
How to Find This in Your dbt Project Right Now
You do not need specialised tooling to audit for these patterns. BigQuery's INFORMATION_SCHEMA and your dbt project's compiled SQL are all you need.
Step 1: Identify your most expensive repeated jobs
Run this against INFORMATION_SCHEMA.JOBS in BigQuery:
SELECT
  job_id,
  query,
  total_bytes_processed,
  total_bytes_billed,
  creation_time
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND job_type = 'QUERY'
  AND statement_type = 'CREATE_TABLE_AS_SELECT'
ORDER BY
  total_bytes_billed DESC
LIMIT 50
Match the job IDs back to your dbt model names using the job labels BigQuery attaches when dbt runs (look for dbt_invocation_id and dbt_node_id in the labels field). Your top 10 by bytes billed are where your audit starts.
Step 2: Inspect the compiled SQL for STRUCT wildcard and pre-filter UNNEST patterns
In your dbt project's target/compiled directory, grep for:
- Any reference to
STRUCT_FIELD.*patterns (wildcard sub-field selection) UNNEST(that is not preceded by aWHEREclause in the same CTE or subquery scopeSELECT *from a CTE that itself contains a STRUCT column — which propagates the wildcard silently
Step 3: Check your staging layer schema decisions
Pull the schema of your BigQuery source tables using:
SELECT
  table_name,
  column_name,
  data_type,
  is_nullable
FROM
  `your_project.your_dataset`.INFORMATION_SCHEMA.COLUMNS
WHERE
  data_type IN ('STRUCT', 'ARRAY')
ORDER BY
  table_name
For every STRUCT or ARRAY column in your sources, ask whether your staging model re-flattens it into individual columns that are never all used by any downstream model. If the answer is yes, you have a schema design issue at the staging layer.
Step 4: Review materialisation strategies for STRUCT-heavy models
In your dbt_project.yml and model-level configs, find any model that references a nested source and is configured as materialized='table'. For each one, check the run frequency and the bytes billed per run from INFORMATION_SCHEMA. If a model runs more than once a day and processes more than 50GB, it is a candidate for either incremental materialisation or a BigQuery materialised view — depending on whether the query pattern supports it.
If you are looking to implement a systematic audit of your dbt project's cost profile, explore how Fintel Analytics approaches this — we work with growth-stage businesses globally to identify exactly these patterns and restructure models for sustainable cost and performance.
What the Fix Actually Looks Like in Practice
A global payments platform we worked with had a staging model that ingested webhook event payloads. The source table had a payload STRUCT with 52 sub-fields. The staging model selected payload.* and materialised as a full table on a 2-hour schedule. The table was 180GB and the model was the second most expensive job in the project — running 12 times a day.
The fix had three components:
-
Replace
payload.*with explicit sub-field selection. Of the 52 fields, only 9 were ever referenced by any downstream model. Projecting only those 9 reduced bytes scanned per run by approximately 80%. -
Switch to incremental materialisation with a timestamp filter. The webhook payload table was append-only. Each event had a
received_attimestamp. By switching to an incremental model withWHERE received_at > (SELECT MAX(received_at) FROM {{ this }}), each run processed only the new events since the last run — typically 2-4GB rather than 180GB. -
Move UNNEST operations downstream. The staging model also unnested an
itemsARRAY unconditionally. By removing the UNNEST from staging and handling it only in the mart model — which applied a date filter before unnesting — the row explosion was eliminated from the high-frequency run.
The combined effect: a model that cost approximately $540/month in on-demand query charges was reduced to under $40/month. The model ran faster. The downstream tests ran faster. Nothing broke.
This is a common outcome. BigQuery's on-demand pricing is $6.25 per TiB of data processed, so a model that saves 80GB per run on a 12x daily schedule is saving roughly 960GB per day — just under 1TB — which at on-demand rates is approximately $6 per day, or $180 per month, from a single model fix. Multiply that across a project with 15-20 STRUCT-heavy models with similar patterns, and the monthly saving is significant at growth-stage scale.
When Nested Schemas Are the Right Answer — and When They Are Not
Nested and repeated fields are not universally correct. The guidance from Google's own documentation is nuanced: denormalising into nested structures typically outperforms equivalent multi-table join patterns because it eliminates the shuffling involved in grouping operations — but star schemas are already optimised for analytics, and further denormalisation does not always yield performance gains.
The practical rule we use in delivery:
- Use ARRAY of STRUCT when the nested relationship is one-to-many, the parent and child are almost always queried together, and the child array has bounded cardinality (typically under 100 elements per row). Order line items, event parameters, and transaction tags are good candidates.
- Avoid ARRAY of STRUCT when different teams need access to the child records independently, the array is unbounded (some rows with 2 elements, some with 10,000), or when the child table needs its own partitioning and clustering strategy for efficient filtering.
- Flatten to a proper dimensional model when you are building a mart layer that end users or BI tools query directly. BI tools — including Holistics, Looker, and most SQL-based semantic layers — work better against flat, well-defined mart tables than against deeply nested structures.
The architecture pattern that works in practice: keep nested structures in your staging and intermediate layers where they match the source system's natural shape, and flatten selectively and explicitly in your mart layer where only the specific sub-fields required by each use case are projected out. That way you get the scan efficiency of columnar nested storage throughout the transformation chain, and the queryability of flat tables at the consumption layer.
Frequently Asked Questions
Q: Does BigQuery charge more for queries on STRUCT columns than flat columns?
A: BigQuery charges based on bytes scanned, not column type. However, a STRUCT column that contains many sub-fields effectively stores more data per logical column, so querying it without specifying sub-fields (e.g. using a wildcard or selecting the parent STRUCT) causes BigQuery to scan all sub-field data. Explicitly selecting only the sub-fields you need is the primary cost control mechanism.
Q: Is it always better to use nested fields in BigQuery instead of joining tables?
A: Not always. Nested and repeated fields outperform multi-table joins when the one-to-many relationship is queried together and the array cardinality is bounded. For independent access patterns, or when children need their own partitioning strategy, separate tables with joins are often the better choice. Star schemas in particular are already well-optimised and don't always benefit from further denormalisation.
Q: How do I find which dbt models are causing the most BigQuery cost from nested field misuse?
A: Query INFORMATION_SCHEMA.JOBS filtered by statement_type = 'CREATE_TABLE_AS_SELECT' and sort by total_bytes_billed. Match job IDs back to dbt model names using the dbt_node_id label. Then inspect the compiled SQL for those models in your target/compiled directory, specifically looking for STRUCT wildcard selects and pre-filter UNNEST patterns.
Q: Can dbt tests catch STRUCT and ARRAY misuse before it hits production?
A: Standard dbt schema tests (not_null, unique, accepted_values) do not catch performance anti-patterns. You need custom query audits or a tool like dbt's cost-tagged runs with INFORMATION_SCHEMA analysis. Building a post-run audit model that checks bytes billed against thresholds per model is a practical approach for ongoing governance.
Q: What is the most impactful single change for reducing BigQuery cost from nested field queries?
A: Replacing wildcard STRUCT sub-field selection with explicit column projection is typically the highest-impact single change. In models with deeply nested source data, this alone can reduce bytes scanned by 60-80% per run. Combine this with incremental materialisation for append-only nested sources and you will see the largest cost reduction for the least structural change to your project.
If your BigQuery bill is climbing and your dbt project ingests data from APIs, webhooks, or event streams — the kind of sources that naturally produce nested JSON — there is a high probability that STRUCT and ARRAY misuse is a meaningful contributor. At Fintel Analytics, we have audited and restructured data stacks for fintech, payments, and e-commerce companies at exactly this stage, and the cost savings from fixing nested field anti-patterns alone are routinely significant enough to justify the work many times over. If your team is watching the BigQuery invoice grow without a clear line of sight into why, that is a problem we have solved before, and the fix is more straightforward than it looks from the outside.