
BigQuery materialized views with dbt give data engineering teams a powerful lever for cutting query costs and accelerating dashboard performance — but only when used for the right workloads. The short answer: use materialized views for high-frequency aggregation queries against large tables where freshness requirements allow for a short refresh lag. Use dbt incremental models when you need row-level transformation logic or tighter latency control. Get the boundary wrong and you will either overspend on storage and refresh compute, or miss the cost savings entirely.
That distinction sounds clean on paper. In practice, most teams we work with have blurred the line — materialising views they should have left as logical, leaving expensive aggregations as standard views that scan full tables every time a dashboard loads, or building dbt incremental models for workloads that a materialized view would serve faster and cheaper. This guide is the decision framework we use when auditing and building analytics stacks for growth-stage companies running on BigQuery and dbt.
Why Standard Views in BigQuery Are Costing You More Than You Think
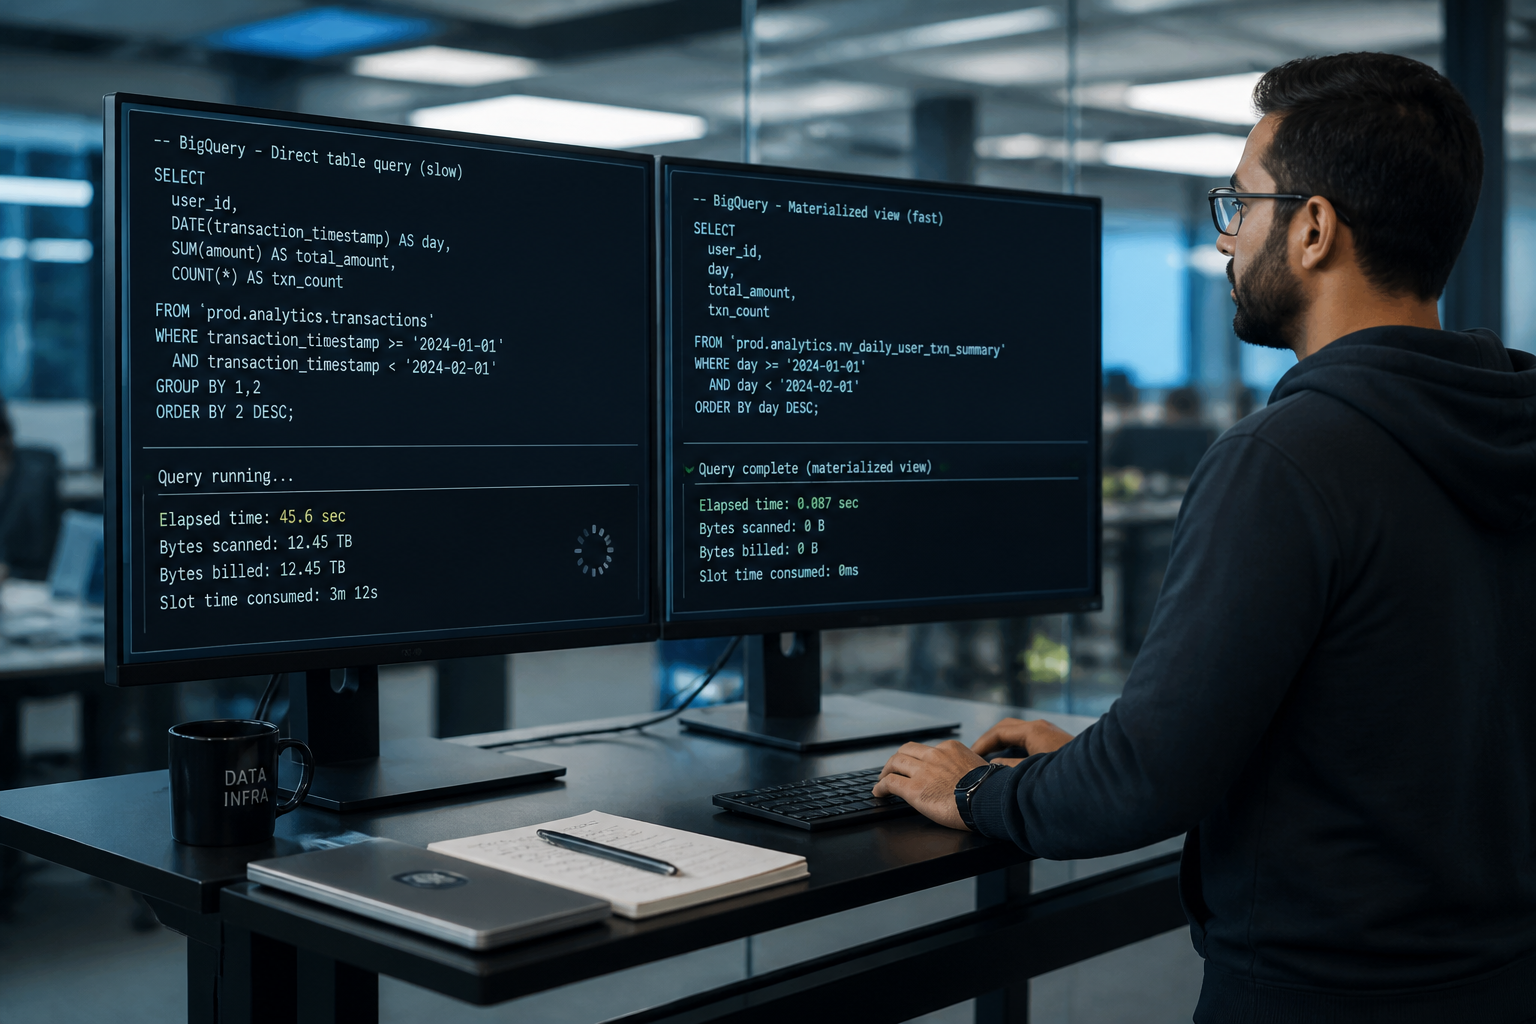
A standard view in BigQuery is a virtual table that dynamically computes the result of its defining query whenever it is queried — it stores no data of its own. That means every time a finance analyst opens a dashboard powered by a standard view joining three large tables and computing a rolling 90-day aggregation, BigQuery runs the full underlying query from scratch. Every single time.
For a team with five analysts opening dashboards throughout the day, you are potentially running that expensive query dozens of times daily. If you have a dashboard that runs the same expensive aggregation query every time someone opens it, you are paying for the same computation over and over.
A pattern we see repeatedly in our work with Series A and Series B companies: the data team has done excellent work building well-structured dbt models, but the final reporting layer — the models that dashboards query directly — are materialised as views rather than tables or materialized views. The dbt default materialisation is view, which maps directly to BigQuery's standard view behaviour. The team ships the models, the dashboards load, everything appears to work. Then the BigQuery bill arrives.
This is worth distinguishing from the separate (but related) problem of dbt models unnecessarily materialised as full tables on every run — which we have covered in detail in our post on dbt models materialised as table in BigQuery. The problem discussed here is the inverse: models that should be pre-computed, left as views.
📺 Watch: Materialized View in SQL | Faster SQL Queries using Materialized Views

What BigQuery Materialized Views Actually Do (And What "Smart Tuning" Means)
In BigQuery, materialized views are pre-computed views that cache a query's results, enhancing performance and efficiency. They periodically refresh to capture changes from the underlying base tables, allowing BigQuery to read only the updated data. This means that queries using materialized views can be executed faster and with fewer resources compared to those that rely solely on base tables.
The mechanism that makes this particularly powerful is what Google calls "smart tuning." Materialized views use smart tuning to transparently rewrite queries against source tables to use existing materialized views for better performance and efficiency. In practice, this means that even if an analyst or a BI tool queries the base table directly, BigQuery will intercept that query and redirect it to the pre-computed materialized view if doing so would return the same result faster and at lower cost. The analyst does not need to know the materialized view exists.
When you create a materialized view, BigQuery runs the query once and stores the results. When the source table changes, BigQuery incrementally updates the materialized view — it does not recompute the entire result set. This incremental refresh behaviour is what keeps the cost of maintaining a materialized view low relative to a full dbt table materialisation.
There is a freshness trade-off to understand here. The data in a materialized view is only as fresh as its last refresh, so there can be a lag compared to querying base tables directly. By default, BigQuery updates materialized views once every 24 hours. For many analytics workloads — daily executive dashboards, weekly finance reports, rolling cohort metrics — that lag is entirely acceptable. For near-real-time operational monitoring, it is not.
dbt and BigQuery Materialized Views: How They Interact
This is where most tutorials stop being useful and start being misleading. dbt has its own materialisation options — view, table, incremental, and ephemeral — and since dbt Core 1.6, it also supports materialising models as BigQuery materialized views using materialized_view as the materialisation type. That is a meaningful addition, but it introduces a set of decisions that are not well documented outside of the dbt source docs.
Here is how the different options behave in practice on BigQuery:
dbt view → Creates a BigQuery standard view. Zero storage cost, but every query re-executes the full SQL. Fine for lightweight transformations or models that are rarely queried directly. Expensive when placed directly behind BI dashboards on large tables.
dbt table → Creates a physical BigQuery table, rebuilt in full on every dbt run. Fast to query, but can be expensive at the compute and storage layers for large models run on a frequent schedule. Best suited for smaller, frequently-queried lookup tables or final semantic models where you want full control.
dbt incremental → Appends or merges new rows into an existing table based on a filter condition. The right choice for event-stream style data where you are processing new rows on every run. Requires careful strategy around late-arriving data, schema changes, and partition management. We have a detailed guide on dbt incremental models strategy worth reading alongside this one.
dbt materialized_view → Instructs dbt to create and manage a BigQuery materialized view. dbt handles the DDL, tracks changes in dbt state, and will ALTER or recreate the view when the SQL definition changes. Unlike regular views, which run the full query every time, materialized views store their results physically. When you query a materialized view, BigQuery reads the cached results instead of scanning the entire source table. This makes dashboard queries faster and cheaper.
Using dbt to manage materialized views gives you version control, CI/CD integration, documentation, and testing — all the things that make dbt valuable — applied to a materialisation type that BigQuery handles exceptionally well for the right workloads.
If you are looking to implement this in your organisation's dbt project, explore how Fintel Analytics approaches BigQuery and dbt delivery — we work with pre-seed through Series B companies globally to design and ship exactly this kind of data stack.
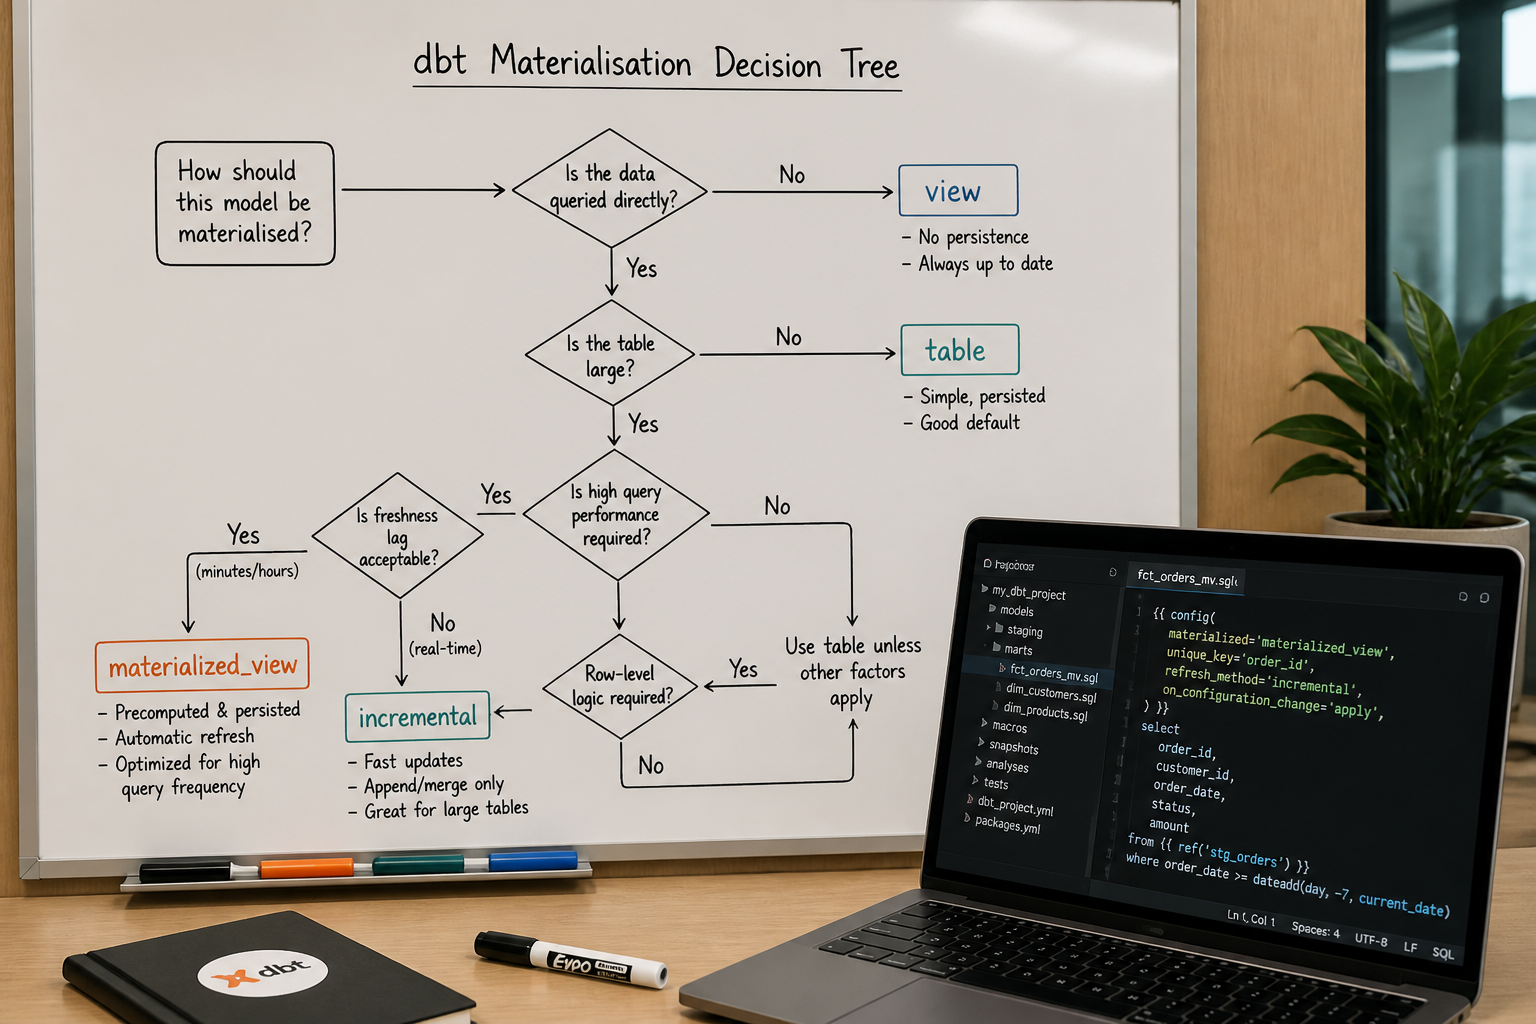
The Decision Framework: When to Use Each Materialisation
After auditing and rebuilding analytics stacks for fintech, payments, and e-commerce businesses, here is the framework we apply when deciding how to materialise a given dbt model on BigQuery.
Use materialized_view when:
- The model is a pure aggregation (SUM, COUNT, AVG, etc.) with no row-level transformation logic
- The same query pattern is executed frequently — by dashboards, scheduled exports, or analyst ad-hoc queries
- The underlying base table is large (hundreds of millions of rows or more)
- A refresh lag of minutes to hours is acceptable for the business use case
- The workload involves heavy aggregation and high-traffic query patterns
Use incremental when:
- You are processing event-stream or append-only data with a clear timestamp watermark
- You need row-level logic (window functions, dense ranking, complex CASE expressions) that cannot be expressed as a pure aggregation
- You need sub-minute data freshness
- The transformation involves joins across multiple large tables where incremental filtering controls scan costs
Use table when:
- The model is a reference or lookup table that is small, rebuilt infrequently, and queried heavily
- The model is the final semantic-layer output that BI tools query, and you want absolute control over its structure and refresh timing
- The downstream tool does not benefit from BigQuery's smart tuning (some third-party connectors bypass the query optimiser)
Use view when:
- The model exists purely for logical transformation or aliasing in the middle of your DAG
- It is queried rarely, or always via a downstream model that is itself materialised as a table
- The logic is in flux and you do not want to manage the overhead of physical storage
One concrete example from delivery: a global payments company we worked with had their entire reporting layer — twelve dbt models feeding four executive dashboards — materialised as standard views on top of a transactions table running at 800 million rows. Dashboard load times were running at 45–90 seconds. Every refresh was scanning the full table. After auditing the query patterns, we converted five of the twelve models to materialized_view materialisations. Dashboard load times dropped to under 4 seconds, and the BigQuery bill for those workloads fell substantially — the scans went from full-table to operating against a pre-aggregated result set a fraction of the size.
Common Mistakes Teams Make With BigQuery Materialized Views
Mistake 1: Materialising views that contain unsupported SQL
BigQuery materialized views have a restricted SQL dialect. You cannot use non-deterministic functions, subqueries in certain positions, certain window functions, or LIMIT clauses. If you attempt to create a materialized view with unsupported SQL, BigQuery will reject it — but the error messages are not always clear. In a dbt project, this surfaces as a model that deploys successfully in CI (where it may be tested with a different materialisation) but fails in production. Always validate against the BigQuery materialized view SQL restrictions before converting a model.
Mistake 2: Setting refresh intervals without understanding the cost
You can adjust the refresh frequency to optimise performance and reduce costs. If the data changes frequently, you may need to increase the refresh frequency to ensure that the materialized views are up-to-date. But each refresh incurs compute cost proportional to the data changed in the base table. Teams that set aggressive refresh intervals on materialized views built over fast-moving large tables can end up spending more on maintenance refreshes than they saved on query scans. Match your refresh frequency to your actual freshness requirement — not to what feels safe.
Mistake 3: Duplicating the materialised view as a dbt table
This is a configuration smell we find in almost every stack we audit. A team creates a BigQuery materialized view manually in the console, then also has a dbt model materialised as a table that computes the same aggregation for "safety." The dbt model overwrites or sits alongside the materialized view, both consume storage, and the refresh logic creates a race condition in downstream dashboards. If you are using dbt, let dbt manage the materialized view via the materialized_view materialisation — do not maintain both in parallel.
Mistake 4: Forgetting to partition the materialized view
By partitioning your materialized views on a column that is frequently accessed in your queries, you can reduce the amount of data that scans when executing the queries. A materialized view without a matching partition strategy to the base table is leaving significant performance gains on the table. We cover partitioning and clustering decisions in detail in our post on BigQuery partitioning and clustering mistakes — the same principles apply when designing materialized view DDL in dbt.
Mistake 5: Using materialized views for near-real-time operational monitoring
This one hurts teams that over-index on cost optimisation without reading the freshness trade-off carefully. A treasury team at a fintech we worked with had a live funding dashboard that needed sub-five-minute data freshness to be operationally useful. A well-intentioned engineer converted the underlying dbt model to a materialized_view materialisation. The dashboard became stale. The team stopped trusting it. Three weeks later, the model was reverted to incremental with a 3-minute schedule, which was the correct solution all along.
How to Implement dbt Materialized Views in BigQuery: The Practical Steps
For teams ready to start converting dbt models to materialized views on BigQuery, here is the approach we follow in delivery:
Step 1: Identify candidate models
Query INFORMATION_SCHEMA.JOBS for your project over the past 30 days. Filter for queries that scan more than 1 GB of data, execute more than ten times per day, and follow a predictable aggregation pattern. These are your candidates. The BigQuery materialized view recommender can also help you improve workload performance and save workload execution cost — these recommendations are based on historical query execution characteristics from the past 30 days.
Step 2: Validate the SQL against BigQuery's restrictions
Before changing the materialisation type in dbt, run the candidate model's compiled SQL through CREATE MATERIALIZED VIEW ... AS SELECT ... in the BigQuery console. Confirm it succeeds. If it fails, note the specific restriction and decide whether the model needs to be refactored or whether a different materialisation is more appropriate.
Step 3: Set the materialisation in dbt
In your dbt_project.yml or model-level config block, set:
{{ config(
    materialized = 'materialized_view',
    partition_by = {
      'field': 'event_date',
      'data_type': 'date'
    },
    cluster_by = ['customer_id'],
    enable_refresh = true,
    refresh_interval_minutes = 60
) }}
Match partition and cluster fields to the base table wherever possible. Set refresh_interval_minutes based on your actual freshness requirement, not the minimum possible.
Step 4: Monitor via INFORMATION_SCHEMA
After deployment, monitor refresh behaviour and query rewrite rates:
SELECT
  table_name,
  last_refresh_time,
  refresh_watermark
FROM
  your_project.your_dataset.INFORMATION_SCHEMA.MATERIALIZED_VIEWS;
Track whether BigQuery is successfully rewriting queries from base tables to the materialized view (visible in query execution plans). If rewrite rates are low, the smart tuning may not be recognising your query patterns — investigate whether the queries are hitting the view through a join or filter that prevents the rewrite.
Step 5: Review costs at the 30-day mark
Pull a before-and-after comparison from INFORMATION_SCHEMA.JOBS_BY_PROJECT. Compare total bytes billed for the affected query patterns. Factor in the storage and refresh compute costs for the materialized views themselves. In well-targeted implementations, the net reduction is significant — but the only way to know is to measure it.
Frequently Asked Questions
Q: What is the difference between a dbt materialized view and a dbt table materialisation in BigQuery?
A: A dbt table materialisation creates a full physical table in BigQuery that is rebuilt completely on every dbt run. A materialized_view materialisation creates a BigQuery materialized view that is maintained incrementally by BigQuery itself — it updates only the changed data when the base tables are modified. The materialized view is generally cheaper to maintain for large aggregation workloads, but it has SQL restrictions and a configurable freshness lag that table materialisations do not.
Q: Do BigQuery materialized views work automatically with dbt without extra configuration?
A: Support for the materialized_view materialisation type was introduced in dbt Core 1.6. As long as your dbt version meets that minimum requirement and your dbt-bigquery adapter is up to date, the configuration is straightforward. The main complexities are in matching partition and cluster settings to the base table and setting an appropriate refresh interval — both of which require deliberate configuration rather than defaults.
Q: Will BigQuery automatically rewrite my queries to use materialized views even if I query the base table directly?
A: Yes — this is BigQuery's smart tuning behaviour. When a user runs a query that BigQuery determines can be answered by the materialized view, BigQuery will automatically rewrite the query to use the precomputed results, even if the user queries the base table directly. This is particularly valuable in BI environments where analysts query tables directly without knowing which materialized views exist.
Q: When should I NOT use a BigQuery materialized view?
A: Avoid materialized views for workloads that require near-real-time freshness (under five minutes), models that contain unsupported SQL syntax (subqueries in certain positions, non-deterministic functions, LIMIT clauses), or transformations that involve complex row-level logic rather than pure aggregations. If your query pattern varies widely — meaning the same base table is queried in many different ways — smart tuning may not trigger reliably and the performance benefit will be inconsistent.
Q: Can BigQuery materialized views cause unexpected cost increases?
A: Yes, in two ways. First, storage costs are incurred for the pre-computed data held by the view. Second, maintenance refresh compute is charged each time BigQuery updates the materialized view from the base table. Storage cost is incurred for the precomputed data stored by the materialized view. Query cost is lower because less data is scanned. Maintenance cost is incurred for the automatic refreshes. Teams that set aggressive refresh intervals on views over rapidly-changing large tables can see refresh costs outpace query savings — always model the full cost before converting a workload.
Growth-stage companies running on BigQuery and dbt routinely leave significant money and performance on the table simply by not applying the right materialisation strategy to the right workloads. If your dashboards are slow, your BigQuery bill is climbing without a clear explanation, or your team is unsure which dbt materialisation to reach for, these are all symptoms of the same underlying gap. At Fintel Analytics, we have helped fintech, payments, and e-commerce businesses audit and rebuild exactly this layer of their data stack — identifying the specific models driving cost, applying the right materialisation strategy, and shipping a stack that performs at scale without unnecessary spend. If that sounds like your situation right now, the fix is more achievable than it looks.