
Accidental cross joins in dbt BigQuery models occur when a join condition is missing, mismatched, or silently collapsed — causing row counts to multiply rather than filter. The result is a Cartesian product: every row from one table combined with every row from another, producing output volumes that can be orders of magnitude larger than the inputs. Left undetected, a single affected model can scan terabytes of unexpected data every scheduled run and send your BigQuery bill into freefall.
This post shows you exactly how to find these joins in your project using query history, how to confirm the damage in seconds, and how to prevent them recurring — without switching on anything new or paying for another tool.
Why Accidental Cross Joins Are So Dangerous in BigQuery
In a traditional database with fixed compute, an accidental Cartesian product is painful but bounded — the query slows to a crawl and someone notices. BigQuery does not work that way. BigQuery will let you run a 100 TB join if you have the quota, and under on-demand pricing, BigQuery charges $6.25 per TiB of data scanned, with the first 1 TiB free each month. A model that accidentally Cartesians a 5M-row transactions table against a 200K-row reference table produces one trillion output rows. That is not a slow query — it is a billing event.
A cross join between two tables produces every possible row combination. Two tables with 1 million rows each produce 1 trillion row combinations. The maths is merciless and it does not care that the model looked correct in development against a sampled dataset.
The reason this pattern is particularly vicious in dbt projects is timing. These accidental cross joins are easy to create — a forgotten ON clause, mismatched data types in join conditions, or implicit joins missing WHERE conditions. They often pass code review because they look syntactically correct. The problems only surface when queries hit production-scale data volumes.
A pattern we see repeatedly in early-stage companies: a new dbt model is built against a 10K-row development dataset, reviewed, merged, and scheduled. Overnight it runs against the full production table with 50M rows. By morning, the BigQuery bill has spiked and nobody knows why — because the model completed without error. BigQuery does not throw an exception for a Cartesian product. It just charges you for it.
Unintentional cross joins are often due to unequal join conditions or missing join predicates on partitioned columns — and they can silently produce billions of costly rows.
📺 Watch: Restore deleted data in BigQuery in 2 Minutes !
How to Detect Accidental Cross Joins Using BigQuery Query History
The fastest diagnostic is to query INFORMATION_SCHEMA.JOBS for models where output rows significantly exceed input rows. BigQuery logs bytes billed and — crucially — total rows processed for every job. A join that multiplies rows will show up as an anomaly in this view.
Run this against your project's job history. Replace your-project-id with your actual GCP project:
SELECT
  job_id,
  user_email,
  statement_type,
  ROUND(total_bytes_billed / POW(1024, 3), 2)          AS gb_billed,
  total_slot_ms,
  creation_time,
  SUBSTR(query, 1, 300)                                 AS query_preview
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND statement_type = 'SELECT'
  AND total_bytes_billed > 10 * POW(1024, 3)  -- flag anything over 10 GB
  AND (
    UPPER(query) LIKE '%CROSS JOIN%'
    OR UPPER(query) LIKE '%JOIN%'
  )
ORDER BY
  total_bytes_billed DESC
LIMIT 50;
This surfaces every SELECT in the past 7 days that billed more than 10 GB and involved a join. Adjust the byte threshold to your project's normal baseline. The query_preview column lets you immediately eyeball whether a CROSS JOIN keyword is present or whether an implicit Cartesian is hiding inside a regular JOIN with a flawed condition.
For dbt-managed models specifically, the job labels are your best friend. When dbt runs a model, it stamps the job with metadata you can filter on:
SELECT
  job_id,
  labels,
  ROUND(total_bytes_billed / POW(1024, 3), 2)  AS gb_billed,
  creation_time,
  SUBSTR(query, 1, 500)                          AS query_preview
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS,
  UNNEST(labels) AS label
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND label.key   = 'dbt_node_id'
  AND total_bytes_billed > 5 * POW(1024, 3)  -- 5 GB
ORDER BY
  total_bytes_billed DESC
LIMIT 30;
The dbt_node_id label maps directly back to your dbt model name. You can take the top result, find the corresponding .sql file in your project, and audit the join logic in under two minutes.
Note on region: swap region-eu for region-us or your specific multi-region depending on where your dataset lives. Using the wrong region will return zero rows without an error, which is a common confusion.
How to Confirm a Row Explosion Without Re-Running the Model
Once you have a suspect model, do not re-run it to confirm — that just bills you again. Instead, use bq dry-run from the CLI to estimate bytes, and separately use a row count check against the materialised table:
-- Compare row count to the largest input source
SELECT
  COUNT(*)                               AS output_rows,
  'fct_transactions_enriched'            AS model_name
FROM
  `your-project.your_dataset.fct_transactions_enriched`;

-- Then check the source table row count
SELECT
  COUNT(*)  AS source_rows
FROM
  `your-project.your_dataset.stg_transactions`;
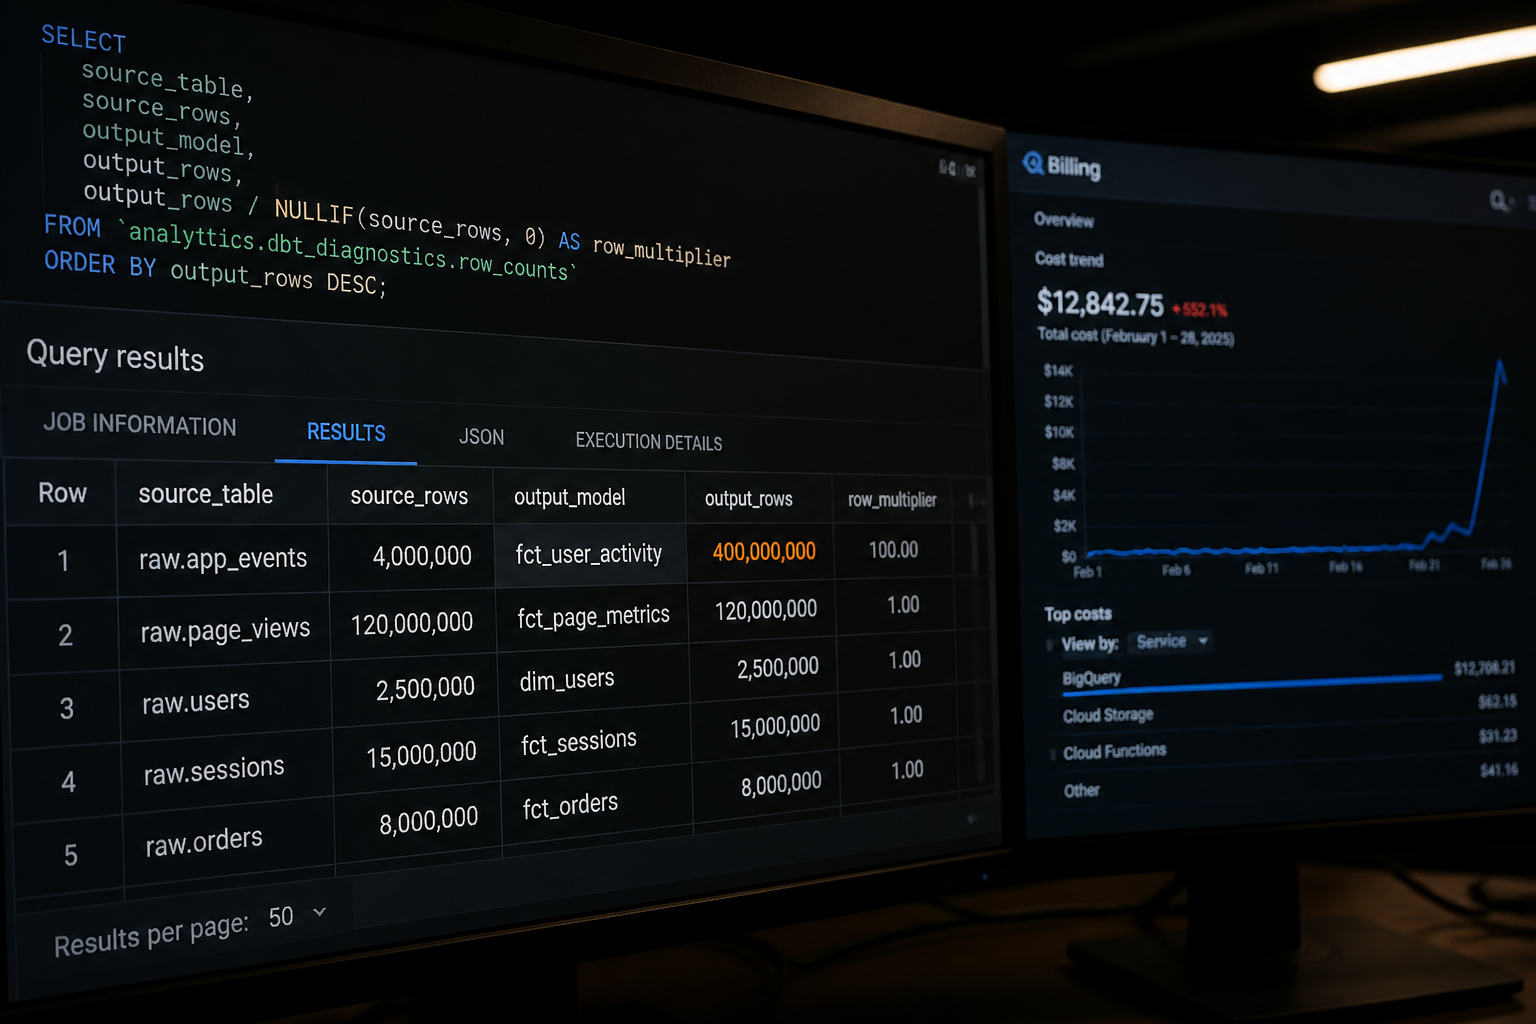
If output_rows is materially larger than source_rows — not a small increase from legitimate fan-out, but an order-of-magnitude difference — you have found your explosion. A transactions staging model with 4M rows producing a fact table with 400M rows is not enrichment; it is a Cartesian.
For a quicker signal, pull the row count from INFORMATION_SCHEMA.TABLE_STORAGE:
SELECT
  table_name,
  row_count,
  ROUND(total_logical_bytes / POW(1024, 3), 2) AS size_gb
FROM
  `your-project.your_dataset`.INFORMATION_SCHEMA.TABLE_STORAGE
WHERE
  table_name IN (
    'fct_transactions_enriched',
    'stg_transactions',
    'stg_reference_rates'
  )
ORDER BY
  row_count DESC;
Seeing the source tables and the output table side by side in one result set makes the multiplication immediately obvious — no re-run required.
Running that pair of queries for one suspect model is fine. Scanning your entire dbt project for models where output row counts are anomalously large compared to their declared sources is not something you want to do manually. fintel-scan is a free open-source CLI (MIT licensed) that automates this check and fourteen others locally, without a warehouse connection: uvx fintel-scan.
How to Fix the Root Cause in Your dbt SQL
Once you have confirmed which model is exploding, the fix is always in the join logic. The three most common causes we encounter in client projects:
1. Missing join key — implicit Cartesian
This is the most common. A developer writes a join between two CTEs but forgets the ON clause, or joins on a constant that matches every row:
-- WRONG: joins on 1=1 — full Cartesian product
LEFT JOIN dim_currency AS c
  ON 1 = 1

-- RIGHT: join on the actual key
LEFT JOIN dim_currency AS c
  ON t.currency_code = c.currency_code
2. Non-unique join key on the right-hand side
This is subtler and harder to spot in review. If your right-hand table is not deduplicated on the join key, every matching row on the left gets duplicated for each match on the right. A transactions table joining to a reference table with five rows per currency code multiplies output rows by five.
-- Always check uniqueness of the join key before joining
WITH deduped_currency AS (
  SELECT
    currency_code,
    exchange_rate,
    ROW_NUMBER() OVER (
      PARTITION BY currency_code
      ORDER BY effective_date DESC
    ) AS rn
  FROM
    `your-project.your_dataset.stg_currency_rates`
)
SELECT *
FROM deduped_currency
WHERE rn = 1
Join to deduped_currency and the fan-out is gone.
3. CROSS JOIN UNNEST used incorrectly
In BigQuery, CROSS JOIN UNNEST() is idiomatic for expanding arrays. Used correctly it is fine. Used on a column that is not an array — or on a subquery that returns multiple rows per parent — it behaves as a full Cartesian. If you see CROSS JOIN UNNEST in a model that is exploding, check what the subquery inside UNNEST actually returns for a sample of rows.
For a related class of problem — where the explosion is caused by skewed keys rather than a missing join condition — see our post on BigQuery join skew in dbt models, which covers how to detect and resolve shuffle skew without rewriting the entire model.
How to Stop This Happening Again
Detection is reactive. The goal is to catch row explosions before they reach production. Three controls that actually work:
Add a maximum_bytes_billed config to high-risk dbt models
You can add cost guardrails directly in your dbt project using maximum_bytes_billed in the model config. This prevents a single misconfigured JOIN from blowing through your daily budget during a scheduled dbt run.
-- In your model's config block
{{ config(
  materialized = 'table',
  maximum_bytes_billed = 53687091200  -- 50 GB hard ceiling
) }}
If the model exceeds this threshold, BigQuery raises an error before the data is written and before the cost is incurred. Set the ceiling at roughly 5–10x the normal scan size for that model.
Add a dbt row count test to your most critical fact tables
dbt's generic tests do not natively test row count ranges, but you can write a singular test that flags when a model's row count exceeds a multiplier of its primary source:
-- tests/assert_fct_transactions_not_exploded.sql
SELECT
  fct.total_rows,
  src.total_rows AS source_rows,
  SAFE_DIVIDE(fct.total_rows, src.total_rows) AS multiplier
FROM (
  SELECT COUNT(*) AS total_rows
  FROM {{ ref('fct_transactions_enriched') }}
) AS fct
CROSS JOIN (
  SELECT COUNT(*) AS total_rows
  FROM {{ ref('stg_transactions') }}
) AS src
WHERE
  SAFE_DIVIDE(fct.total_rows, src.total_rows) > 1.10  -- flag if output > 110% of source
This test will fail the dbt run if the fact table has more than 10% more rows than the staging source — catching any explosion before the model reaches your BI layer. Adjust the multiplier threshold to match legitimate fan-out in your specific model (for example, if a transaction genuinely spawns multiple line items, set it accordingly).
For broader coverage of your test strategy, our post on dbt models with no tests shows how to find every untested model in your project and prioritise where to start.
Set a project-level daily byte quota in GCP
If your team normally scans 2–5 TB per day, set the quota at 10 TB. This catches catastrophic mistakes (accidental Cartesian joins, missing partition filters) without blocking legitimate work. You can set this in the GCP Console under BigQuery → Admin → Quotas, or via the API. It is a blunt instrument but an important backstop for overnight scheduled runs where nobody is watching.
Frequently Asked Questions
Q: How do I know if my dbt model has an accidental cross join?
A: The clearest signal is output row count materially exceeding input row count from the primary source table. Query INFORMATION_SCHEMA.JOBS filtered by dbt_node_id label and sort by total_bytes_billed descending — a Cartesian explosion will stand out immediately as an outlier. Confirm by comparing row counts in INFORMATION_SCHEMA.TABLE_STORAGE for the output model versus its source tables.
Q: Does BigQuery warn you before running an accidental cross join?
A: No. BigQuery will execute a Cartesian product without warning and charge you for every byte scanned. The only native pre-execution guard is maximum_bytes_billed, which you must set explicitly on the query or in the dbt model config. Without it, the query runs to completion regardless of cost.
Q: What is the difference between an accidental cross join and join fan-out in BigQuery?
A: An accidental cross join is caused by a missing or always-true join condition — every row on the left matches every row on the right. Join fan-out (also called a many-to-many join explosion) is caused by a non-unique key on the right-hand side — a valid join condition, but one where the right table has multiple rows per key, causing each left row to duplicate. Both inflate row counts and costs; both are detectable by comparing input and output row counts. The fix differs: cross joins need a corrected ON clause; fan-out needs a deduplication step on the right-hand table before the join.
Q: Can I use CROSS JOIN intentionally in dbt BigQuery models?
A: Yes, intentional cross joins are valid for generating date spines, creating all combinations of dimensions, or populating a skeleton for gap-filling. The issue is unintentional use. If you use CROSS JOIN deliberately, document it in a model comment and add a maximum_bytes_billed cap so that if the reference table grows unexpectedly, it does not silently explode.
Q: How do I prevent accidental cross joins from reaching production in dbt?
A: Three controls in combination work well: (1) set maximum_bytes_billed in the dbt model config for any fact or wide table; (2) add a singular dbt test that compares output row count to primary source row count and fails above a defined multiplier; (3) set a project-level daily byte quota in GCP as a backstop for overnight runs. None of these require additional tooling — they use native BigQuery and dbt capabilities.
Accidental cross joins are one of those problems that feel embarrassing in retrospect but are genuinely easy to miss in code review, especially when the model is developed against sampled data and the explosion only manifests at production scale. At Fintel Analytics, we have found and resolved exactly this pattern for payments companies, e-commerce platforms, and fintech lenders — often buried inside a model that had been silently doubling the BigQuery bill for weeks without triggering a single pipeline error. If your costs are moving in a direction that your data volume does not explain, that is a solvable problem — and the sooner you dig into the query history, the cheaper the answer gets.