
BigQuery Join Skew in dbt Models: Find & Fix It in 2026
BigQuery join skew is what happens when one or more values in your join key appear far more frequently than the rest — causing a single worker slot to receive a disproportionate share of the data shuffle, slowing the entire query to that one slot's pace and burning slot-hours on every other idle worker in the process. In a dbt project, skewed joins rarely throw errors. They show up as mysteriously slow model runs, creeping BigQuery bills, and dashboards that time out under load — and they are almost always invisible until you know exactly where to look.
This is one of the more frustrating problems to debug because the surface symptoms are vague. A dbt model that built in 45 seconds last quarter now takes four minutes. A scheduled query starts missing its SLA window. Finance comes back asking why the BigQuery invoice jumped 40% when data volume only grew 15%. In every one of these scenarios, the answer could be join skew — and the fix is almost always surgical once you find the offending model.
This guide walks through exactly how BigQuery executes joins, why skew emerges in real dbt projects, how to diagnose it using the execution plan and INFORMATION_SCHEMA, and the specific patterns that fix it in production.
Why Does BigQuery Join Skew Happen?
To understand skew, you need to understand how BigQuery actually executes a join. BigQuery is a distributed MPP (massively parallel processing) engine. When it joins two tables, it performs a shuffle — it hashes each row on both sides of the join by the join key, then routes rows with matching keys to the same worker slot so the local join can happen. This is efficient when the join key has high cardinality and even distribution. It breaks badly when it does not.
Consider a fct_transactions table being joined to a dim_merchants table on merchant_id. If 60% of all transactions belong to a single high-volume merchant — say, a platform's own test merchant account, or a "null" catch-all used when merchant attribution fails — then 60% of the entire shuffle lands on one slot. Every other slot finishes its work and sits idle. The query wall time equals the slowest slot, not the average.
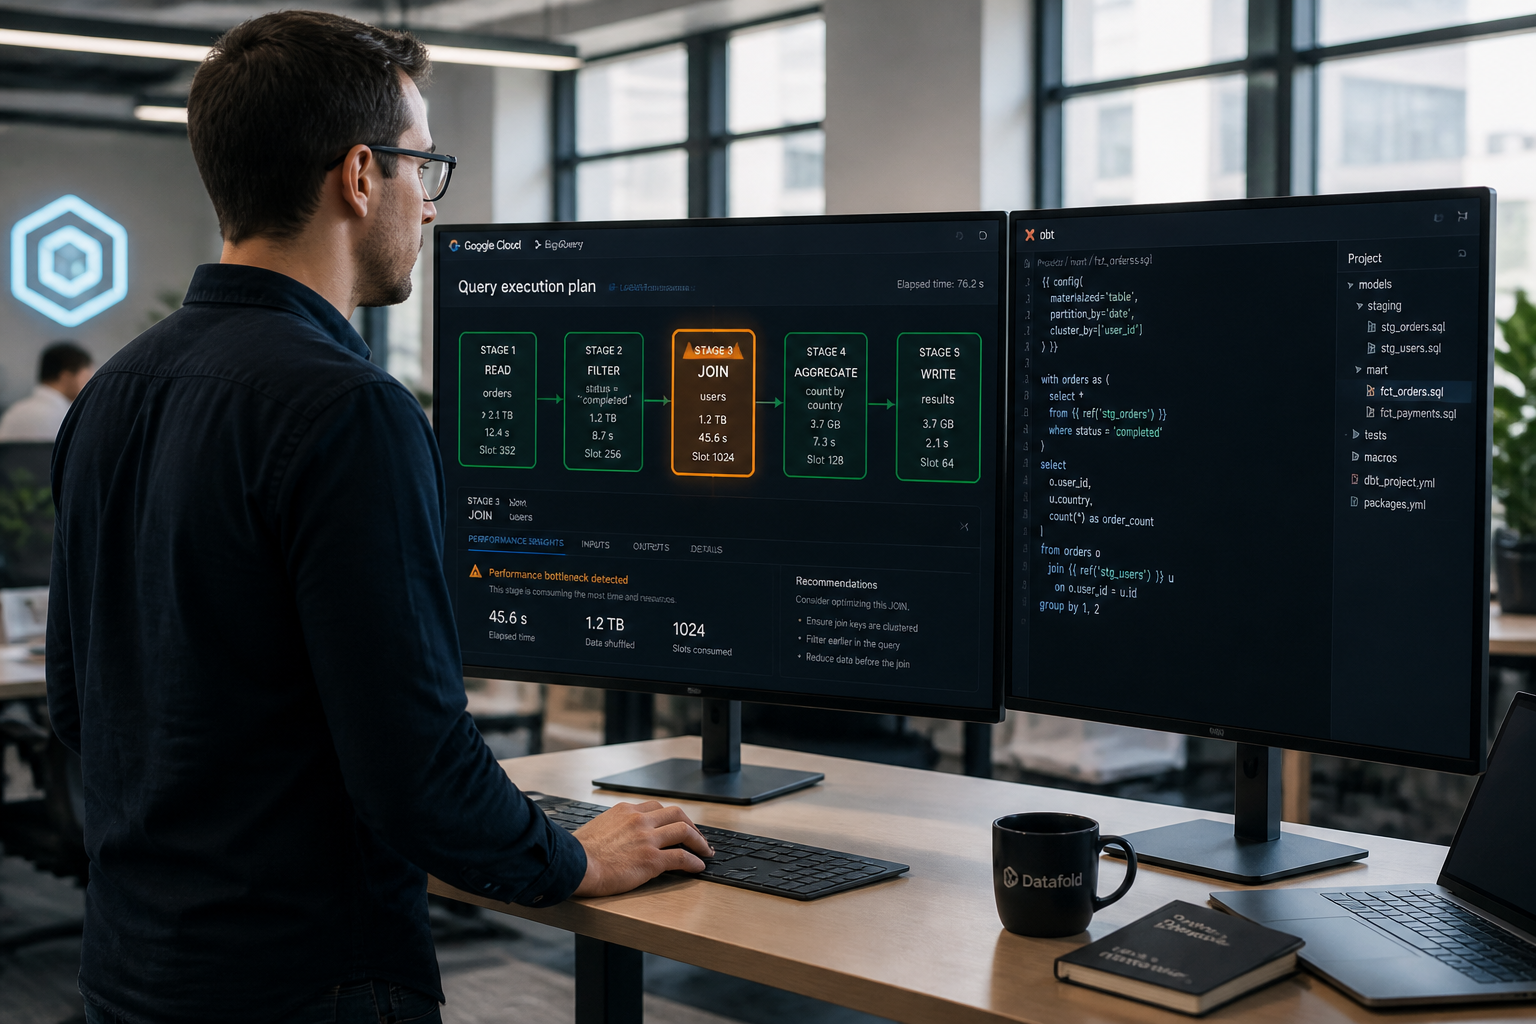
As Google's own BigQuery documentation notes, skewed joins occur when "the data distribution across the join key in one table is very skewed and can lead to performance issues" — and the tell-tale sign in the execution plan is a stage where the maximum compute time is dramatically higher than the average compute time. In practice, a ratio of 10x or more between max and average is a reliable signal that skew is the bottleneck.
In a dbt project, this problem compounds in specific ways:
- Incremental models joining large fact tables to slowly-changing dimensions amplify skew with every run, because the join processes an ever-growing base table.
- Multi-hop joins — where model A joins to model B which joins to model C — can cascade skew across layers, making it hard to pinpoint which model is the root cause.
- Staging models that do not pre-filter pass full, unfiltered tables into joins downstream, maximising shuffle volume.
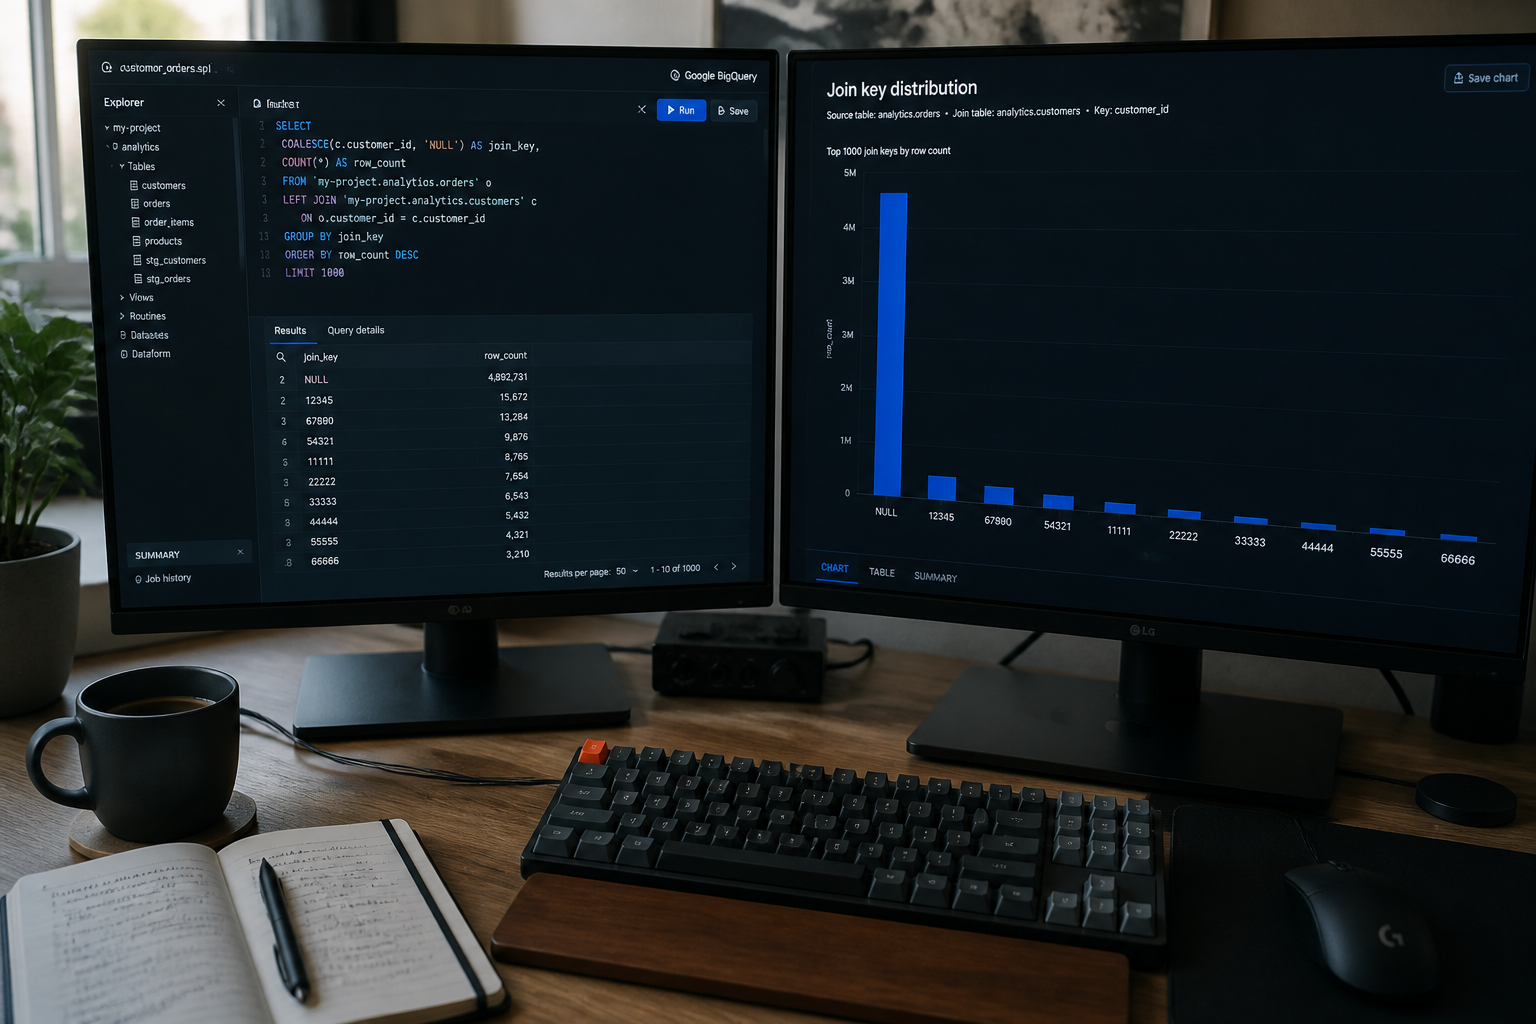
A pattern we see repeatedly when auditing dbt projects at growth-stage companies: a NULL or a sentinel value like 'UNKNOWN' sitting in a join key column, propagated silently from an upstream source, attracting millions of rows into a single shuffle bucket. If you have not audited your join keys for NULL concentration, there is a reasonable chance this is already happening in your project right now.
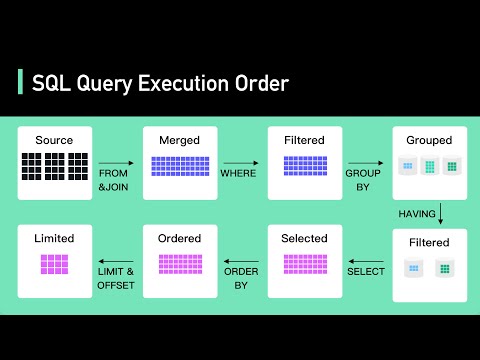
📺 Watch: Secret To Optimizing SQL Queries - Understand The SQL Execution Order
How to Diagnose Skew Using the BigQuery Execution Plan
The first diagnostic tool is the Query Execution Plan in the BigQuery console (the "Execution Details" tab after running a query). You are looking for any stage labelled with a JOIN or SHUFFLE operation where the ratio of maximum-to-average compute time is high.
Here is what the signals mean:
- High
shuffleOutputBytes: data is being redistributed between slots. High shuffle is normal in complex queries, but very high shuffle relative to input bytes suggests a fan-out problem (a related issue — see our post on dbt fan-out joins in BigQuery) or unfiltered tables entering the join. - Max compute >> Average compute in a JOIN stage: the classic skew signal. One slot is overloaded; the rest are idle.
- Slot-time spilling to disk: when a slot's shuffle exceeds the in-memory limit, BigQuery writes to disk, which can add minutes to a query that should take seconds.
For systematic diagnosis across all models — not just the one you happen to be looking at — use INFORMATION_SCHEMA:
SELECT
  job_id,
  query,
  total_slot_ms,
  total_bytes_processed,
  ROUND(total_slot_ms / NULLIF(total_bytes_processed, 0), 4) AS slot_ms_per_byte,
  creation_time
FROM
  `region-eu.INFORMATION_SCHEMA.JOBS_BY_PROJECT`
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND job_type = 'QUERY'
  AND state = 'DONE'
  AND total_bytes_processed > 10000000000  -- 10 GB+
ORDER BY
  total_slot_ms DESC
LIMIT 20;
This query surfaces the 20 most slot-intensive queries in the last seven days. High slot_ms_per_byte — particularly on models you know join large tables — is a strong indicator of inefficient joins, shuffle skew, or both. Once you have a suspect query, open the execution plan for that specific job and look at the JOIN stage.
To find skew in the join key itself, run a distribution check on the column you are joining on:
SELECT
  merchant_id,
  COUNT(*) AS row_count,
  ROUND(
    COUNT(*) * 100.0 / SUM(COUNT(*)) OVER(),
    2
  ) AS pct_of_total
FROM `project.dataset.fct_transactions`
GROUP BY merchant_id
ORDER BY row_count DESC
LIMIT 20;
If the top row contains NULL, 'UNKNOWN', 'TEST', or a single dominant value representing more than 10–15% of all rows, you have your skew source.
The Four Fix Patterns That Actually Work in Production
Once you have located the skew, there are four patterns for fixing it. The right one depends on the structure of your dbt model and the nature of the skewed key.
1. Pre-filter before the join
The single highest-leverage change you can make: filter each side of the join to only the rows you actually need before the join executes. This reduces the data volume entering the shuffle, shrinking both shuffle bytes and the slot-time of the join stage.
In a dbt model, this means using a CTE to pre-filter your fact table rather than filtering after the join:
-- BEFORE: filter happens after full join
SELECT
  t.transaction_id,
  t.amount,
  m.merchant_name
FROM {{ ref('fct_transactions') }} t
LEFT JOIN {{ ref('dim_merchants') }} m
  ON t.merchant_id = m.merchant_id
WHERE t.processed_date >= DATE_SUB(CURRENT_DATE(), INTERVAL 30 DAY)

-- AFTER: filter happens before the join
WITH recent_transactions AS (
  SELECT transaction_id, amount, merchant_id
  FROM {{ ref('fct_transactions') }}
  WHERE processed_date >= DATE_SUB(CURRENT_DATE(), INTERVAL 30 DAY)
)
SELECT
  t.transaction_id,
  t.amount,
  m.merchant_name
FROM recent_transactions t
LEFT JOIN {{ ref('dim_merchants') }} m
  ON t.merchant_id = m.merchant_id
The difference is that in the second version, only the filtered rows enter the shuffle. In a table with three years of transaction history, this can reduce shuffle volume by two orders of magnitude for a 30-day query.
2. Handle NULL and sentinel join keys separately
If your skew source is NULL or a sentinel value (a catch-all like 'UNKNOWN'), the cleanest fix is to route those rows around the join entirely:
WITH non_null_transactions AS (
  SELECT * FROM {{ ref('fct_transactions') }}
  WHERE merchant_id IS NOT NULL
    AND merchant_id != 'UNKNOWN'
),
null_transactions AS (
  SELECT * FROM {{ ref('fct_transactions') }}
  WHERE merchant_id IS NULL
     OR merchant_id = 'UNKNOWN'
),
joined AS (
  SELECT
    t.*,
    m.merchant_name
  FROM non_null_transactions t
  LEFT JOIN {{ ref('dim_merchants') }} m
    ON t.merchant_id = m.merchant_id
)
SELECT * FROM joined
UNION ALL
SELECT *, CAST(NULL AS STRING) AS merchant_name
FROM null_transactions
This pattern separates the hot keys into their own branch that never touches the join, eliminating the shuffle overload entirely for that segment. It reads inelegantly but performs dramatically better in the right circumstances.
3. Add clustering on join keys
When both sides of a join are clustered on the join key, BigQuery can perform block pruning before the join — skipping irrelevant data segments before the shuffle begins. This does not eliminate skew from uneven key distribution, but it significantly reduces the total data volume entering the shuffle, which reduces the absolute slot-time even when skew exists.
In dbt, you add clustering through the model configuration:
{{ config(
  materialized='table',
  cluster_by=['merchant_id']
) }}
Combining clustering with the pre-filter pattern above gives you two independent mechanisms reducing shuffle volume — both beneficial, neither sufficient alone when skew is severe.
If you are still deciding how your models should be materialised, our post on dbt models materialised as table in BigQuery covers when table materialisation is appropriate versus views or incremental models.
4. Break the query into intermediate steps using dbt staging layers
For the most severe cases — typically multi-hop joins where skew compounds across layers — the most reliable fix is to materialise an intermediate model that performs the most expensive join in isolation, persists the result as a table, and lets downstream models join against that pre-computed result instead of executing the full join chain each time.
This is where dbt's layered modelling philosophy pays off directly. A staging or intermediate model that pre-aggregates or pre-joins expensive combinations becomes a performance asset for every downstream model that references it. The join happens once per dbt run, not once per downstream query — and it can be tuned, clustered, and partitioned independently.
This is the pattern we used with a Series A payments company running a reconciliation process that involved joining transaction events, settlement records, and merchant configuration across three fact tables. The naive approach — a single model joining all three — was taking over 40 minutes and regularly timing out. Splitting it into two materialised intermediate models, each with targeted clustering and pre-filtering, brought the end-to-end build time under four minutes.
If you are seeing unexplained slot-time growth or dbt model build times creeping upward without a clear cause, explore how Fintel Analytics approaches BigQuery performance engineering — we work with growth-stage businesses globally to build data stacks that stay performant as data volumes scale.
What Does This Cost You If You Ignore It?
Skew is not a theoretical problem. The financial impact compounds quickly as data volume grows.
Consider a dbt model that joins a 500-million-row fact table to a dimension table, with a join key that has one value representing 20% of all rows. Without skew handling, the join stage processes 500 million rows but one slot carries the load of 100 million of them. In on-demand pricing, you are billed for all bytes processed — but you are also burning slot-time on idle workers doing nothing while the skewed slot catches up.
With slot reservations (Enterprise or Enterprise Plus commitments), the impact is different but equally real: skewed queries hold slots for longer, reducing the effective throughput of your reservation and causing other queries to queue. As noted in Google's own performance documentation, even when static statistics are correct, "queries can still have vastly different behavior due to natural data skew or changes in available compute resources."
In our experience working with growth-stage companies on BigQuery, skew-related inefficiency is consistently one of the top three contributors to unexpected bill growth — alongside unpartitioned full table scans and orphaned scheduled queries. A single skewed dbt model running eight times a day on a 400-million-row table can account for a meaningful fraction of a startup's entire monthly BigQuery spend.
The cost argument for fixing skew is straightforward: the engineering time to diagnose and fix a skewed model is typically two to four hours. The ongoing saving is every day, on every run, indefinitely.
How to Prevent Skew From Returning
Finding and fixing skew once is useful. Preventing it from quietly re-emerging as your data grows is more valuable.
Three practices that work in production:
1. Add a dbt test for NULL concentration in join keys. You can write a custom generic test that fails if more than a configurable threshold of rows have a NULL join key. Adding this to every model that joins on a high-cardinality key means skew caused by NULL propagation is caught in CI before it reaches production.
2. Monitor slot-ms-per-byte ratios over time. Set up a scheduled query or a dbt metric that tracks total_slot_ms / total_bytes_processed for your most expensive models week-over-week. A ratio that is drifting upward is a leading indicator of a join pattern that is degrading as data grows — before it becomes a user-facing performance problem or a billing incident.
3. Keep your dbt source freshness and schema drift checks healthy. Skew sometimes originates upstream — a source system that starts sending a new default value for a previously high-cardinality column, or a schema change that causes joins to fall back on a non-selective key. Our post on dbt sources with no freshness config covers how to systematically identify sources that lack these safeguards.
The broader principle: join skew is a symptom of unvalidated data entering your models. Tightening source-layer data contracts and adding distribution checks to your dbt test suite is the sustainable fix — not just optimising SQL after the fact.
Frequently Asked Questions
Q: What is BigQuery join skew and why does it matter for dbt projects?
A: BigQuery join skew occurs when one or more values in a join key column appear far more frequently than others, causing a single worker slot to receive a disproportionate share of the data shuffle during query execution. In dbt projects it matters because skewed joins cause models to build slowly, inflate BigQuery slot usage, and drive up infrastructure costs — and the problem compounds as data volume grows without any obvious error message alerting you to the root cause.
Q: How do I know if my BigQuery query has join skew?
A: Open the Execution Details tab in the BigQuery console after running your query and look at any stage involving a JOIN or SHUFFLE operation. If the maximum compute time for that stage is significantly higher than the average compute time — a ratio of 10x or more is a strong signal — you almost certainly have join skew. You can also query INFORMATION_SCHEMA.JOBS_BY_PROJECT and filter for high total_slot_ms relative to bytes processed to find the worst-offending queries across your project.
Q: Can BigQuery fix join skew automatically?
A: BigQuery's autonomous query processor includes history-based optimisations and dynamic query planning that can mitigate some forms of skew over repeated executions. However, severe structural skew — particularly from NULL or sentinel values dominating a join key — cannot be fully resolved by the engine alone. The fundamental fix requires restructuring the query or the upstream data to reduce concentration in the join key.
Q: Does clustering fix BigQuery join skew?
A: Clustering on join keys reduces total data volume entering the shuffle through block pruning, which improves overall join performance. However, clustering does not fix the underlying distribution imbalance that causes skew — if one key value accounts for 30% of your rows, clustering still routes 30% of the shuffle to one slot. Clustering is most effective when combined with pre-filtering and NULL/sentinel key separation.
Q: How does join skew affect BigQuery costs on slot reservations versus on-demand pricing?
A: On on-demand pricing, join skew inflates costs by increasing total bytes shuffled and slot-milliseconds consumed. On slot reservations (Enterprise or Enterprise Plus), the cost is different — skewed queries hold your reserved slots for longer, reducing the effective throughput of your reservation and causing other queries and dbt model runs to queue behind them. In both pricing models, resolving skew has a direct, measurable impact on either your invoice or your operational throughput.
BigQuery join skew is one of those problems that grows invisibly — tolerable at seed-stage data volumes, quietly expensive at Series A, and genuinely painful by Series B when your dbt project is running dozens of models against hundreds of millions of rows per day. At Fintel Analytics, we have diagnosed and resolved exactly this class of performance degradation for payments companies, fintech platforms, and e-commerce businesses — finding the two or three skewed models that account for the majority of wasted slot-time, and rebuilding them so they stay efficient as data volumes continue to grow. If your BigQuery bill is climbing faster than your data volume, or your dbt runs are taking longer each quarter without an obvious explanation, that gap is worth investigating before it becomes a budget problem.