
Multi-tenant SaaS analytics architecture determines whether your customers see only their own data — and whether your analytics layer survives beyond 1,000 tenants. Done right, it is invisible: every customer sees a clean, accurate view of their own metrics with zero leakage. Done wrong, it is one of the most expensive failure modes in B2B software.
If you are building a B2B SaaS product and your analytics layer is not explicitly designed for multi-tenancy, you have a problem you probably have not found yet. And the later you find it, the more it costs to fix.
Why Multi-Tenant Analytics Breaks at Scale
Most SaaS teams build their first analytics layer for themselves. An internal dashboard, a Metabase instance pointed at the production database, a few Sheets pulling from a read replica. It works fine at ten customers. It starts to creak at one hundred. At one thousand, it collapses — not because the tools fail, but because the architecture was never designed to serve many tenants safely and independently.
The failure modes are predictable. A pattern we see repeatedly when working with B2B SaaS companies at the Series A stage is the same stack decision made in the first weeks of the product: a shared database, a tenant_id column on most tables, and an application layer that filters on it. That is a reasonable starting point. The problem is that the analytics layer — added later, by a different team, under deadline pressure — does not inherit those same filters. Reporting pipelines run as admin credentials. Dashboards query without tenant context. One misconfigured join, and a customer can see another customer's data.
This is not a theoretical risk. Analytics and reporting surfaces are one of the most common and overlooked isolation failure points in SaaS. Misconfigured analytics tools frequently bypass application-level authorisation unless tenant context is enforced end-to-end through every layer of the stack.
The consequences are severe. According to IBM research cited in 2025 reporting, the average global cost of a data breach reached $4.88 million — and in the United States, that figure hit a record $10.22 million (IBM, 2025). A single leaky analytics query that surfaces one customer's data to another is not just a technical incident. It is a trust event, a contractual liability, and potentially a regulatory breach.
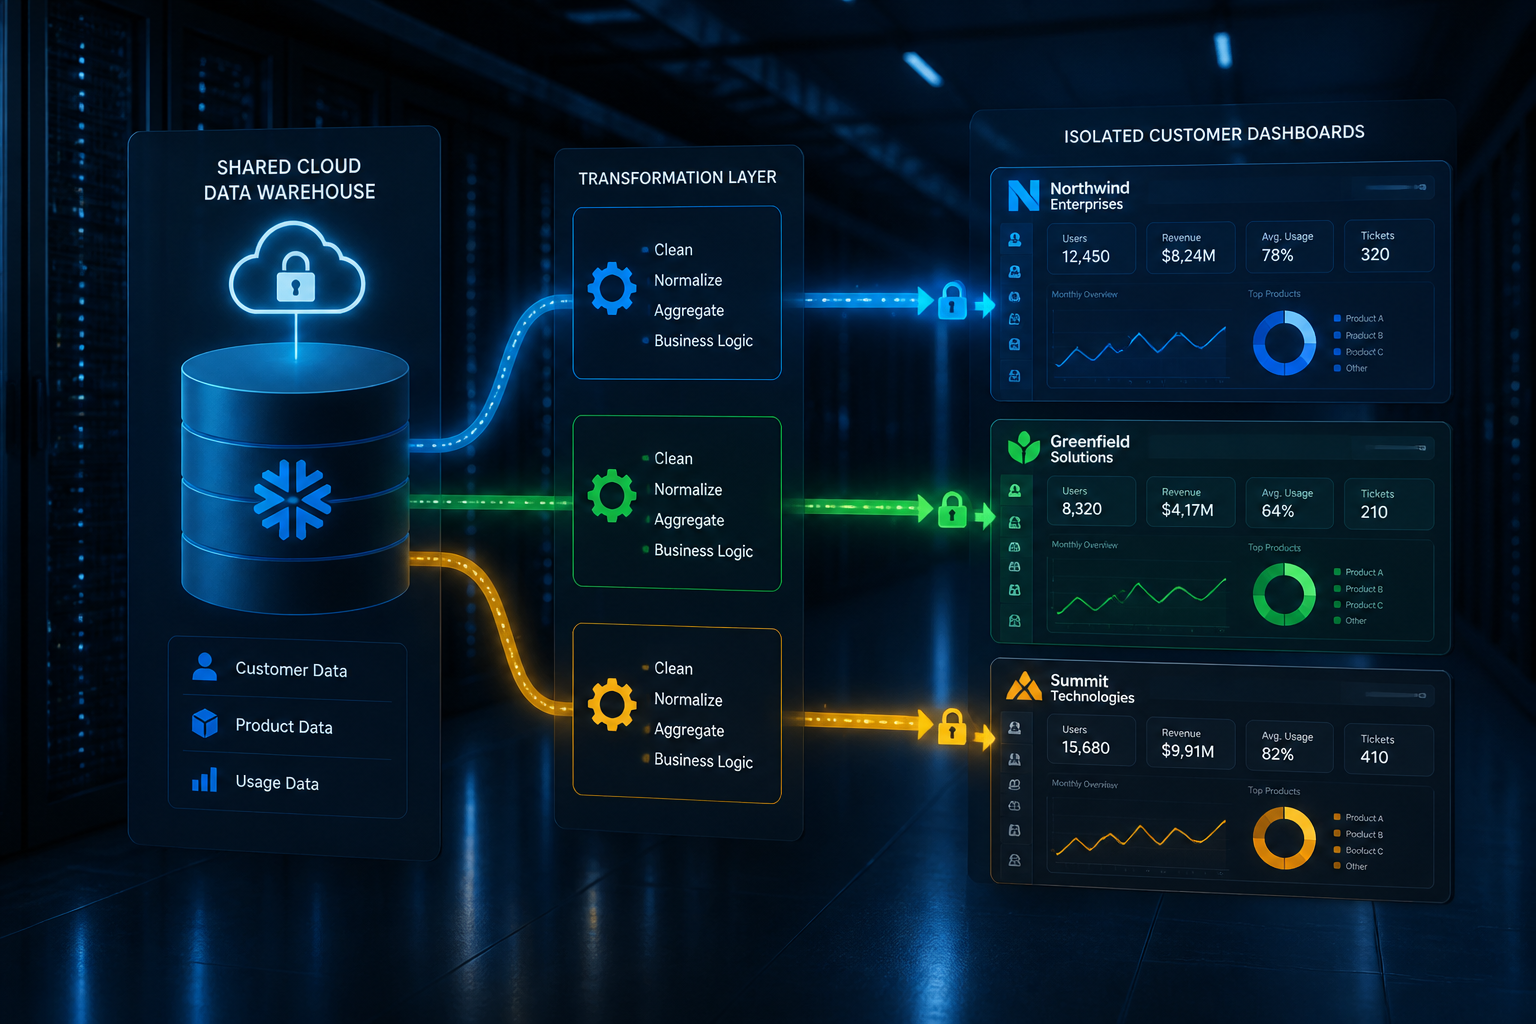
📺 Watch: Why Multi-Tenant Architecture is the Future of SaaS

The Three Isolation Models — and When to Use Each
There is no universally correct multi-tenant analytics architecture. The right model depends on your tenant count, your enterprise sales motion, your compliance obligations, and the size of your engineering team. Here is how to think about the three main patterns:
Shared database with Row-Level Security (RLS)
This is the most common starting point, and for good reason. A single warehouse, tenant_id columns throughout, and RLS policies that enforce query-time filtering. Done well, it is operationally simple and cost-effective. Done badly, it is the source of the most serious data leaks.
The critical failure mode here is not RLS itself — it is the gaps around it. ETL and reporting pipelines that run as superusers bypass RLS entirely. Shared cache layers that do not include tenant_id in the cache key can serve one tenant's dashboard data to another. A query that forgets a filter condition will return rows from every tenant in the table. Every query without explicit tenant scoping is a potential cross-tenant data leak.
If you are using this model, the rule is simple: enforce tenant context at the data layer, not just the application layer. Your dbt models should carry tenant_id through every transformation, and your BI tool should never connect with credentials that bypass row-level policies.
Schema-per-tenant
Stronger logical isolation without the full operational cost of dedicated infrastructure. Each tenant gets their own schema within a shared database — transformations run separately per schema, and there is no risk of a missing WHERE clause exposing cross-tenant data.
The operational trade-off is real: schema-per-tenant architectures become painful as tenant counts grow, because DDL changes and dbt model deployments must be coordinated across every schema simultaneously. A migration that takes five minutes for one schema takes hours across five hundred. This model makes sense for mid-market SaaS products where enterprise clients are in the pipeline but the tenant count is still manageable — typically below a few hundred.
Dedicated infrastructure per tenant (silo model)
The highest isolation, the hardest to operate, and the most expensive. Each tenant gets their own data warehouse, their own pipeline, their own compute. This is the correct model for regulated industries — healthcare, financial services, government — where contractual data residency requirements make shared infrastructure non-negotiable.
Most production SaaS platforms in 2026 run a hybrid model: standard-tier customers on shared infrastructure, enterprise customers with compliance requirements on dedicated environments. This is not always planned from the start — it typically emerges under pressure from the first enterprise deal that requires it.
The Four Analytics-Specific Failure Points Nobody Warns You About
Architecture documentation covers databases and application layers well. The analytics layer gets far less attention — and that is exactly where the failures happen in practice. Here are the four failure points we see most often:
1. Reporting pipelines that bypass tenant context
ETL and transformation jobs typically run with elevated credentials that ignore application-level authorisation. If your dbt models or ELT pipelines do not carry tenant_id through every model, your warehouse contains unsegregated data that any BI query can accidentally surface in full. We have reviewed pipelines at Series A companies where the entire transformation layer had no tenant-level filtering whatsoever — the production database was correctly isolated, but the warehouse was a single flat table accessible to anyone.
2. Analytics built on the production database
This is the fastest way to make your product unreliable for all customers simultaneously. One tenant running a heavy report against a shared production replica can slow query performance for every other tenant on that instance. The analytics layer must be separated from the operational database — a dedicated warehouse, fed by a reliable pipeline, is not optional at scale.
3. Missing tenant_id on event streams
This is an unfixable mistake if you catch it late. Every event your product emits — page views, API calls, transactions, errors — must include tenant_id from day one. There is no retroactive fix. If you have six months of event data with no tenant attribution, that data is analytically useless for per-tenant reporting. In our work with early-stage SaaS companies, we have seen this exact situation: rich behavioural data collected at significant cost that could not be used for customer-facing analytics because tenant context was never added to the schema.
4. Shared caches without tenant scoping
If your analytics layer caches query results — and most BI tools do — the cache key must include tenant_id. A cache key based only on the query string will serve the same cached result to every tenant who runs the same query. The result is not a security failure in the traditional sense: it looks like a stale data problem. The cache returns Tenant A's numbers to Tenant B. Both receive dashboards that appear to load correctly. Neither notices immediately. You discover it during a customer support call three weeks later.
If you are designing or auditing your analytics stack and want an expert view on where your isolation model is holding and where it is not, explore how Fintel Analytics approaches this — we work with B2B SaaS companies globally to design and deliver exactly this kind of multi-tenant analytics infrastructure.
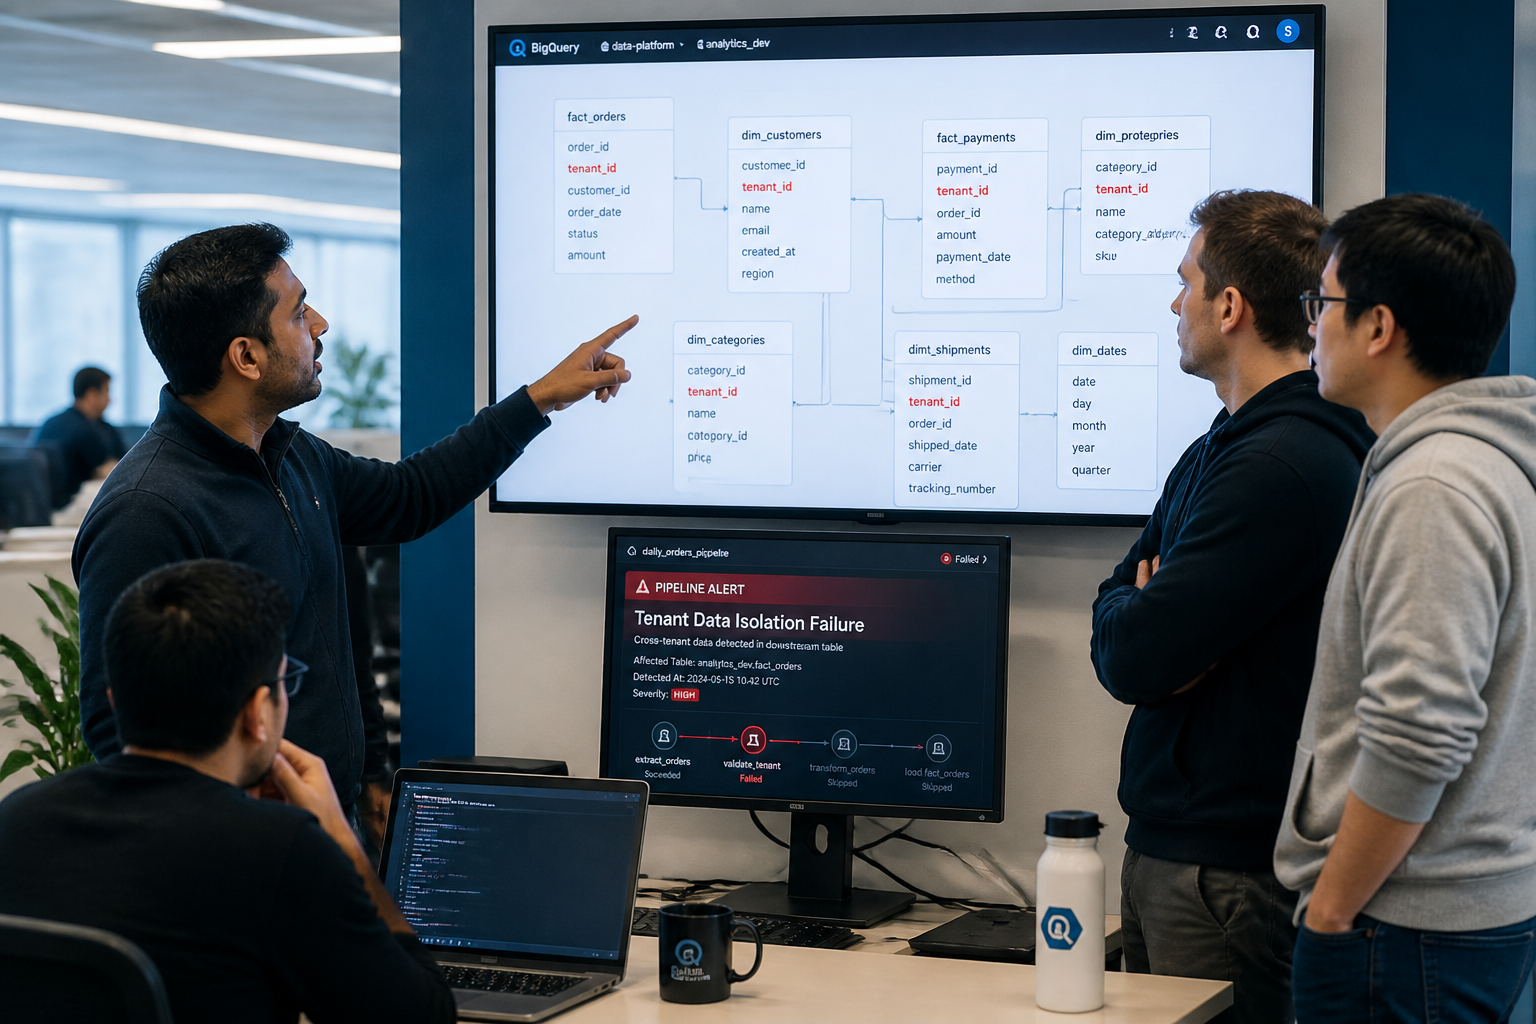
How to Design a Multi-Tenant Analytics Stack That Survives Growth
The following is a reference architecture for a B2B SaaS company in the 100–5,000 tenant range using BigQuery and dbt — the stack we deliver most frequently for companies at this scale.
Layer 1: Source ingestion
All event data lands in BigQuery with tenant_id as a required, non-nullable field on every raw table. This is enforced at the schema level — not at the application level, not as a convention. If the field is absent, the pipeline rejects the record. No exceptions.
For webhook and API event ingestion, structured validation runs before records enter the raw layer. We cover the specific mechanics of this in our post on Webhook Ingestion Analytics: Stop Losing Events in Your Pipeline — the same principles that prevent event loss also enforce tenant attribution.
Layer 2: dbt transformation with tenant-scoped models
Every dbt model carries tenant_id as a first-class dimension. Staging models extract and validate tenant_id from source. Intermediate models join and aggregate within tenant boundaries. Mart models are the layer that BI tools query — and they are tested, via dbt, to ensure tenant_id is present and non-null on every row.
For large deployments, dbt incremental models partitioned on tenant_id and an event timestamp reduce both query cost and build time significantly. The incremental strategy that works at this scale is covered in detail in our post on dbt Incremental Models Strategy: When and How to Use Them.
We also run automated row-count and aggregate-level tests per tenant after each build. If a tenant's row count drops unexpectedly, the pipeline fails and alerts before the BI layer serves stale or incomplete data. This is not optional — silent data loss at the tenant level is the failure mode that damages enterprise relationships most severely.
Layer 3: BI layer with enforced tenant context
The BI tool connects to BigQuery with a service account that has read access to mart tables only. Row-level security is enforced at the BigQuery level using authorised views or column-level policies — never relying on the BI tool's own filtering as the sole control. The BI tool's filtering is an additional layer, not the primary one.
For customer-facing embedded analytics — dashboards surfaced inside your SaaS product — a security token carrying tenant_id and role context is generated at runtime by your application and passed to the analytics layer. The analytics layer never relies on the application to have filtered correctly upstream. It enforces its own context. Defense in depth, applied to the analytics stack.
What This Looks Like in Practice: An Anonymised Example
We worked with a Series A B2B SaaS company serving operational teams across several hundred enterprise clients. Their internal analytics stack had grown organically: a mix of dbt models connected to a production read replica, a Metabase instance with admin credentials, and a handful of customer-facing dashboards built directly on top of raw tables with application-level filtering only.
The immediate problem that brought them to us was not a data leak — it was broken metrics. Finance said one thing, customer success said another, and neither could trust the numbers enough to present them to clients. Classic single-source-of-truth failure, compounded by the fact that the raw tables had no consistent tenant scoping across models.
The rebuild had three phases: first, we moved all transformation into dbt with tenant_id as a required dimension on every model and added automated tests to catch missing tenant attribution before it reached production. Second, we replaced the admin-credential Metabase connection with a BigQuery service account scoped to mart tables only, with BigQuery-level row policies enforced independently of the application. Third, we built customer-facing dashboards in Holistics with runtime tenant token injection — so customers received dashboards that were structurally incapable of returning another tenant's data.
The outcome: metrics matched across every reporting surface for the first time, customer-facing dashboards loaded in consistent sub-second response times, and the engineering team went from spending several hours per week managing bespoke tenant reporting requests to zero — because customers could self-serve from accurate, isolated dashboards.
Frequently Asked Questions
Q: What is multi-tenant SaaS analytics architecture?
A: Multi-tenant SaaS analytics architecture refers to the design of a data pipeline, transformation layer, and BI reporting system that serves multiple customers (tenants) from a shared infrastructure while ensuring each tenant sees only their own data. It requires explicit tenant isolation at every layer — ingestion, transformation, storage, and presentation — not just at the application level.
Q: What is the difference between row-level security and schema-per-tenant in analytics?
A: Row-level security (RLS) enforces tenant data access at query time within a shared database — every query is automatically filtered to the requesting tenant's rows. Schema-per-tenant creates a separate schema for each tenant within the same database, providing stronger logical isolation without RLS dependency. RLS is simpler to operate at scale but carries higher risk if misconfigured; schema-per-tenant is safer but becomes operationally expensive as tenant counts grow into the hundreds.
Q: How do I prevent data leaks in a multi-tenant analytics pipeline?
A: Enforce tenant_id at the data layer — not just the application layer. This means: requiring tenant_id as a non-nullable field on all raw tables, carrying it through every dbt model with automated tests to catch missing attribution, connecting BI tools with scoped credentials that cannot bypass tenant filtering, and implementing row-level policies at the warehouse level (e.g. BigQuery authorised views) as the primary control, with BI-level filtering as a secondary layer only.
Q: When should a SaaS company move from a shared analytics database to dedicated per-tenant infrastructure?
A: The trigger is usually a combination of factors: the first enterprise client with contractual data residency requirements, a compliance audit (SOC 2, GDPR, HIPAA) that flags shared compute risk, or a noisy-neighbour problem where one large tenant's query load degrades analytics performance for all others. Most production SaaS platforms in 2026 run a hybrid model — standard customers on shared infrastructure, enterprise customers on isolated environments — rather than a binary choice.
Q: What happens if I do not add tenant_id to my event schema from day one?
A: You lose the ability to attribute historical event data to individual tenants retroactively. There is no reliable fix — enrichment heuristics rarely achieve complete attribution, and incomplete tenant data is worse than no data because it produces subtly wrong metrics. Every event schema must include tenant_id from the first day data is collected. If you are past that point, triage which data streams can be enriched and accept the loss on those that cannot.
Multi-tenant SaaS analytics is one of the most consequential architectural decisions a B2B software company makes — and one of the most frequently deferred until the failure is already in production. The companies that get this right treat tenant isolation as a data engineering problem, not an application problem, and they build it explicitly rather than relying on convention and hope. At Fintel Analytics, we have helped B2B SaaS companies at every stage — from pre-seed through Series B — audit, redesign, and rebuild their analytics stacks to serve customers safely at scale. If your reporting layer was built before your tenant count made isolation a hard requirement, that is the gap worth closing before it closes you.