
The Short Answer: Ephemeral Models Are CTEs, and BigQuery Re-Evaluates CTEs Every Time
dbt ephemeral models do not create a table or view in your warehouse — they inline their SQL as a Common Table Expression (CTE) into every downstream model that references them. In BigQuery, CTEs are not guaranteed to be materialised at runtime: the query optimiser may re-evaluate the CTE each time it is referenced within a single query, and when the ephemeral model is referenced by multiple separate downstream models, BigQuery executes it as a full independent query for each one. The result is that a single ephemeral staging model scanning a 500 GB raw table can silently execute that scan three, five, or ten times per pipeline run — and your bill reflects every byte.
If you have ever looked at your BigQuery cost dashboard and found your transformation spend climbing faster than your data volume, ephemeral model fan-out is one of the first places to check.
Why Most Teams Don't Catch This Until It's Expensive
The problem starts with a reasonable design decision. Ephemeral models are positioned in the dbt docs as a way to keep intermediate logic DRY without cluttering your warehouse with staging tables. That framing is accurate for lightweight transformations on small tables. The trouble is that most teams apply ephemeral materialisation to their heaviest staging models — the ones joining raw source tables that are large, unpartitioned, or poorly clustered — precisely because they don't want those intermediates visible as tables.
There are two distinct cost failure modes here, and it's worth understanding both.
Failure mode 1: Multi-reference within a single compiled model. When a downstream model references the same ephemeral model twice — directly or via another ephemeral dependency — BigQuery's query optimiser attempts to detect the repeated subquery and execute it once. As Google's own documentation notes, "the query optimizer attempts to detect parts of the query that could be executed only once, but this might not always be possible." When the optimiser cannot inline the result, the CTE gets re-evaluated. The more complex the ephemeral chain, the less reliably the optimiser collapses it.
Failure mode 2: Multiple downstream models referencing the same ephemeral. This is the far more common and expensive pattern. If stg_payments is ephemeral and both fct_transactions and fct_settlement depend on it, dbt compiles each downstream model into its own independent SQL statement — each containing the full stg_payments CTE expanded inline. BigQuery executes them as two completely separate queries. A 200 GB staging scan becomes a 400 GB staging scan. Add a third consumer and you are at 600 GB. This is not a bug in dbt; it is the logical consequence of what ephemeral materialisation is.
A pattern we see repeatedly in our work with early-stage fintech and payments businesses: a stg_raw_events ephemeral model scanning a multi-hundred-gigabyte events table, referenced by four or five mart-layer models, running on a daily schedule. Nobody noticed because the individual model run times looked normal — the cost was distributed silently across multiple job executions.
📺 Watch: dbt: Using The Ref Function
How to Find Your Ephemeral Cost Problem in BigQuery (Runnable Diagnostic)
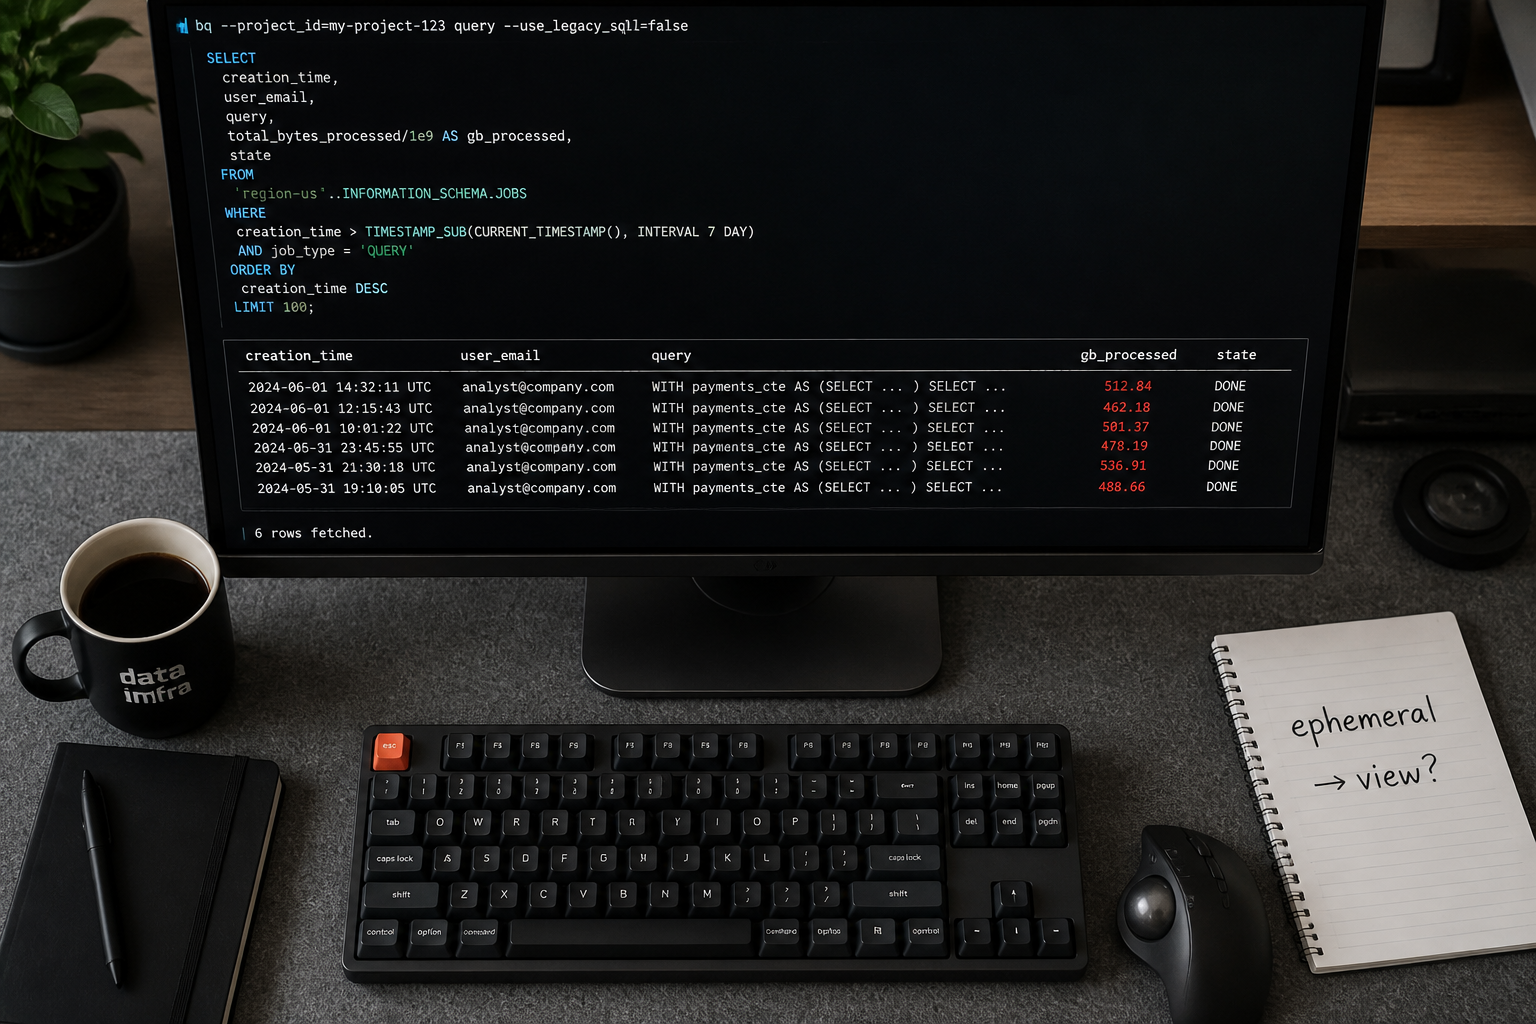
The fastest way to find this is to cross-reference your dbt project's compiled SQL against BigQuery's INFORMATION_SCHEMA.JOBS query history. The goal is to identify queries that contain the same CTE logic appearing across multiple job executions in a short window.
Step one: find all ephemeral models in your dbt project.
dbt ls --select config.materialized:ephemeral --output name
This gives you a list of every ephemeral model. Note the names of any that you know sit on top of large raw tables — these are your candidates.
Step two: pull the top-cost queries from the last 7 days that reference your suspected staging logic. Run this against your BigQuery project:
SELECT
  job_id,
  user_email,
  ROUND(total_bytes_processed / POW(1024, 3), 2)   AS gb_processed,
  ROUND(total_bytes_billed   / POW(1024, 3), 2)   AS gb_billed,
  total_slot_ms,
  creation_time,
  SUBSTR(query, 1, 300)                            AS query_preview
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND job_type   = 'QUERY'
  AND state      = 'DONE'
  AND total_bytes_processed > 10 * POW(1024, 3)  -- models scanning >10 GB
  AND LOWER(query) LIKE '%stg_your_model_name%'  -- replace with your ephemeral model name
ORDER BY
  total_bytes_processed DESC
LIMIT 50;
Replace region-eu with your actual BigQuery region (region-us, us, eu, etc.) and swap stg_your_model_name for the compiled CTE alias from your ephemeral model. If you see the same large-byte scan appearing multiple times per pipeline run — typically in the same 5–30 minute window — you have confirmed the fan-out pattern.
Step three: quantify how many times the scan repeats. Run this aggregation to count how many distinct job executions contain that CTE pattern in a given day:
SELECT
  DATE(creation_time)                              AS run_date,
  COUNT(*)                                         AS job_count,
  ROUND(SUM(total_bytes_processed) / POW(1024, 3), 2) AS total_gb_processed,
  ROUND(SUM(total_bytes_billed)    / POW(1024, 3), 2) AS total_gb_billed
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND job_type   = 'QUERY'
  AND state      = 'DONE'
  AND LOWER(query) LIKE '%stg_your_model_name%'
GROUP BY 1
ORDER BY 1 DESC;
If job_count is consistently 4–6 per day and total_gb_billed is large, each of those jobs is one downstream mart model paying the full staging scan cost independently.
Running that query for one model is manageable. Auditing every ephemeral model across a whole project is not — fintel-scan is a free open-source CLI (MIT licence) that runs this check and fourteen others locally, without a warehouse connection:
uvx fintel-scan.
The Fix: Choose the Right Materialisation for the Fan-Out Pattern
Once you have confirmed which ephemeral models are being scanned multiple times, the fix is straightforward — but the right fix depends on the model's role in your DAG.
Option 1: Materialise as a view (the default dbt fallback). This is the correct fix for most staging models. A view does not store data, but it does give the downstream models a stable reference point that BigQuery can resolve independently. More importantly, if the downstream mart models apply meaningful filters (partition pruning, date filters), BigQuery will push those filters through the view into the underlying base table scan. The staging scan is still executed per consumer query, but now each consumer is filtering properly rather than scanning the full table.
Change the config block in your staging model:
{{ config(materialized='view') }}
Option 2: Materialise as a table (for heavy, frequently-joined staging models). If the staging model is expensive to compute, is referenced by many downstream models, and does not benefit from filter pushdown (for example, because it performs complex joins or aggregations before any mart-level filtering is possible), materialise it as a table. This pays a one-time write cost on each pipeline run and then lets every downstream model read from a pre-computed, properly partitioned and clustered result. As Google's documentation states, "materializing your subquery results improves performance and reduces the overall amount of data that BigQuery reads and writes."
For a staging model on a partitioned events table, you would typically do:
{{ config(
    materialized = 'table',
    partition_by = {
        'field': 'event_date',
        'data_type': 'date'
    },
    cluster_by = ['user_id', 'event_type']
) }}
This gives every downstream consumer a pre-partitioned, clustered base to query — and BigQuery's partition pruning means each mart model can filter to its relevant date window instead of scanning the full history.
Option 3: Use an incremental model for high-volume append-only sources. If the staging model sits on top of a table that grows by appending new records (transactions, events, API logs), consider making the staging model itself incremental. Rather than rebuilding entire tables every time a model runs, incremental models only process new or updated data — saving both time and compute. This is the most impactful change for large, fast-growing datasets.
See our detailed breakdown of when to use each approach in dbt Models Materialised as Table in BigQuery: Fix the Cost Leak and BigQuery Materialized Views With dbt: When to Use Them.
What to Reserve Ephemeral Models For
Ephemeral materialisation is not wrong — it is just frequently misapplied. The correct use cases are narrow:
- Truly lightweight transformations on small reference tables (e.g., a model that renames or casts a few columns on a lookup table with 10,000 rows).
- Single-consumer logic — an ephemeral model that is referenced by exactly one downstream model carries no fan-out risk.
- DRY macros that are not scan-heavy — reusable column aliasing or type-casting logic that doesn't involve a full table scan.
As one practitioner put it in the dbt-bigquery community: "Ephemeral models are powerful, but not free." The moment an ephemeral model sits on top of a large raw table and is referenced by more than one downstream model, it becomes a liability.
A useful rule of thumb from our delivery experience: if the compiled SQL of an ephemeral model would cost more than $0.10 to run on-demand in isolation, it should not be ephemeral.
How to Stop This Recurring
Detection after the fact is useful; prevention is better. Three practical controls:
1. Add a project-level default materialisation policy. In your dbt_project.yml, set staging models to view by default and only override to ephemeral explicitly, with a comment justifying the choice:
models:
  your_project:
    staging:
      +materialized: view
    marts:
      +materialized: table
This means ephemeral only appears where someone has deliberately chosen it — not as the default for models someone forgot to configure.
2. Use dbt model contracts and tags to flag ephemeral models for review. Tag any ephemeral model with ephemeral_approved and add a CI check or dbt test that alerts if a newly added ephemeral model is referenced by more than one downstream model.
3. Set a BigQuery cost alert on your transformation project. Google Cloud's budget alerts can notify you when spend crosses a threshold. Pair this with the INFORMATION_SCHEMA.JOBS query above as a scheduled query that writes to a monitoring table — you will catch fan-out regressions before the end-of-month bill arrives.
The monitoring query to schedule daily:
SELECT
  DATE(creation_time)                              AS run_date,
  REGEXP_EXTRACT(query, r'-- dbt model: (\S+)')   AS dbt_model,
  COUNT(*)                                         AS execution_count,
  ROUND(SUM(total_bytes_billed) / POW(1024, 3), 2) AS gb_billed
FROM
  `region-eu`.INFORMATION_SCHEMA.JOBS
WHERE
  creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 1 DAY)
  AND job_type   = 'QUERY'
  AND state      = 'DONE'
GROUP BY 1, 2
HAVING execution_count > 3
ORDER BY gb_billed DESC;
This surfaces any dbt model that ran more than three times in a single day with significant bytes billed — a reliable proxy for ephemeral fan-out in a typical daily pipeline.
Frequently Asked Questions
Q: Do dbt ephemeral models cost money in BigQuery?
A: Yes — ephemeral models are compiled as CTEs and inlined into every downstream model that references them. Each downstream model is a separate BigQuery job, and BigQuery bills each job for the bytes it scans. If an ephemeral model sits on a large raw table and is referenced by multiple downstream models, that base table scan is executed — and billed — once per consumer per pipeline run.
Q: Are dbt ephemeral models the same as BigQuery CTEs?
A: In effect, yes. When dbt compiles a model that references an ephemeral upstream, it replaces the ref() call with the full SQL of the ephemeral model as an inline CTE. The resulting compiled SQL is a single query with that CTE defined at the top — which means BigQuery's CTE re-evaluation behaviour applies directly.
Q: When should I use ephemeral vs view vs table in dbt with BigQuery?
A: Use ephemeral only for lightweight, single-consumer transformations on small tables. Use view for staging models that are referenced by multiple consumers and where BigQuery can push partition filters through. Use table (or incremental) for heavy staging models with complex joins or aggregations where you want to pay the compute cost once and have all consumers read from the pre-computed result.
Q: How do I find which dbt models are materialised as ephemeral?
A: Run dbt ls --select config.materialized:ephemeral --output name in your dbt project. This lists every ephemeral model. Cross-reference against your INFORMATION_SCHEMA.JOBS query history to see which ones are generating repeated large-byte scans.
Q: Can BigQuery cache ephemeral model results to avoid repeated scans?
A: BigQuery has a query result cache, but it only applies when the query text is identical and the underlying table data has not changed. Because each downstream model compiles to a slightly different SQL statement (different SELECT columns, WHERE clauses, JOINs), the cache rarely fires for ephemeral fan-out. Do not rely on caching as a solution — change the materialisation strategy instead.
If your BigQuery bill is growing faster than your data volume and you have a dbt project with non-trivial use of ephemeral models, this is one of the most commonly overlooked cost drivers we find during an infrastructure review. At Fintel Analytics, we have audited and rebuilt transformation layers for fintech, payments, and e-commerce businesses at every stage from pre-seed through Series B — finding exactly this kind of silent cost pattern and fixing it at the root. If your team is watching cloud costs climb and is not sure where to look next, that is a solvable problem, and the diagnostic work usually pays for itself within the first billing cycle.