
Choosing between BigQuery on-demand and slot reservations is the single highest-leverage pricing decision on your Google Cloud bill — and most early-stage teams get it wrong, often in both directions. On-demand is the right default at low query volume; capacity-based slot pricing unlocks meaningful savings only once your workload is consistent, predictable, and large enough to make idle slots worth paying for. Get the sequencing wrong and you either waste money on reserved capacity you're not using, or you stay on on-demand past the point where it makes sense — and watch your bill compound.
This guide gives you the framework to make that call with actual numbers, not guesswork. If you are a founder, CTO, or engineering lead running BigQuery at pre-seed through Series B scale, this is the decision you will face — probably sooner than you expect.
What Is the Difference Between BigQuery On-Demand and Slot Reservations?
BigQuery separates storage from compute, and you pay for each independently. The pricing model choice only applies to the compute side — how you are charged for running queries.
BigQuery offers two compute pricing models for running queries: on-demand pricing (per TiB), where you are charged for the number of bytes processed by each query, with the first 1 TiB of query data processed per month free.
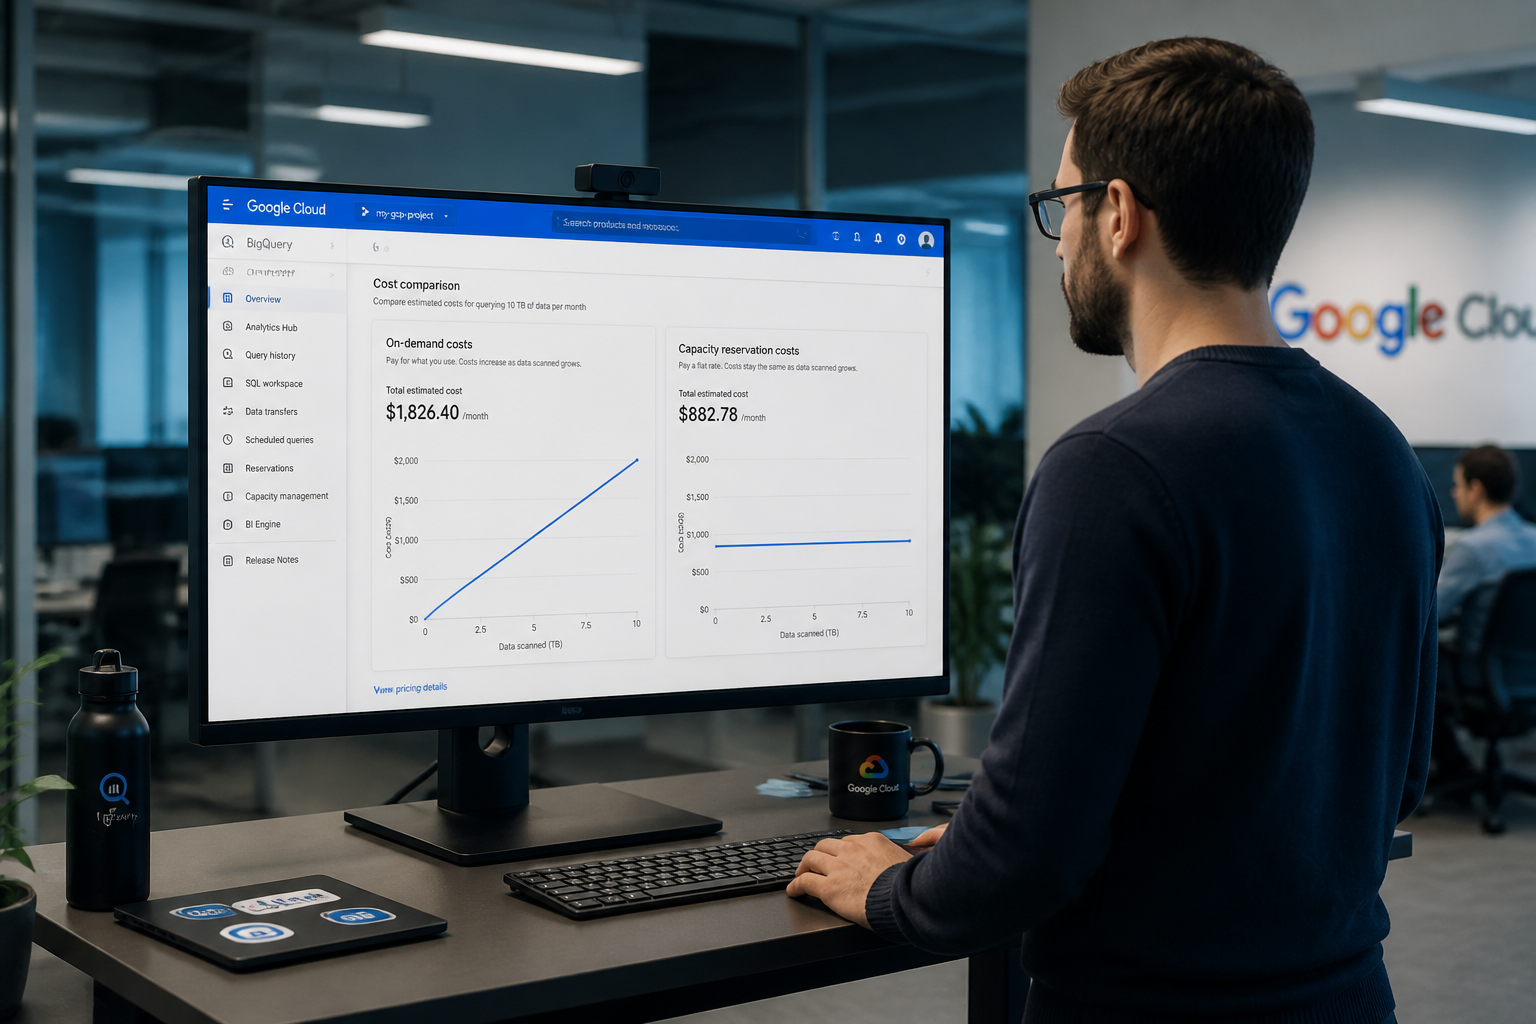
On-demand pricing costs $6.25 per TB scanned, while Standard Edition capacity pricing starts at $0.04 per slot-hour; the lower-cost option depends on how consistent your workload is.
A BigQuery slot is a virtual CPU that Google uses to run your SQL queries. BigQuery automatically decides how many slots your query needs based on its size and complexity — you cannot set this manually.
Under on-demand pricing you get a shared pool of up to 2,000 slots and pay per TB of data scanned. Under capacity pricing you reserve a fixed number of slots and pay by the slot-hour, regardless of how much data you scan.
The third dimension that confuses most people is the BigQuery Editions layer. Capacity pricing is no longer sold as a single flat rate — it comes in three tiers:
- Standard Edition at $0.04 per slot-hour pay-as-you-go is designed for development and ad-hoc workloads.
- Enterprise Edition at $0.06 per slot-hour pay-as-you-go (dropping to $0.038 with a 3-year commitment) is the main production tier and unlocks idle slot sharing, BigQuery ML, and folder-level assignments.
- Enterprise Plus adds compliance controls for regulated industries at $0.10 per slot-hour.
For most growth-stage companies, the relevant comparison is on-demand versus Standard or Enterprise Edition capacity. Enterprise Plus is a compliance story, not a cost story.
📺 Watch: BigQuery Cost Optimization: Compute
Why Do Early-Stage Teams Almost Always Start on On-Demand — and When Does That Become a Problem?
On-demand is the right default. On-demand is the right default for most teams, and it often stays the right choice longer than people expect. If your queries are cheap individually and don't run at high frequency, on-demand is almost always cheaper.
For a team running a few analytical queries per day against well-partitioned tables, on-demand is probably fine. The simplicity is real, and there's no risk of paying for capacity you don't use.
The problem is not choosing on-demand — it is staying on on-demand without noticing that the workload has changed underneath you. A pattern we see repeatedly with Series A and Series B companies is that the data team grows, the number of dbt models increases, scheduled pipelines multiply, and BI dashboards start firing queries on refresh. None of these individually look alarming. Cumulatively, they can push a team from scanning 20 TiB per month to 200 TiB per month inside a single quarter — and the bill follows linearly.
At $6.25 per TiB, a team scanning 10 TiB per day pays roughly $1,900 per month. Scale that to 40 TiB per day — achievable with a moderately active dbt project and a handful of dashboards — and you are at $7,500 per month before you have asked whether the pricing model still makes sense.
The other failure mode we see is the opposite: a team moves to slot reservations early because they want "predictable costs", before their workload is stable enough to size a reservation sensibly. A team moves to BigQuery reservations expecting to cut costs. Three months later, their bill is higher. This happens because baseline slots remain allocated and billed during periods when no jobs are running, and overprovisioned reservations result in wasted capacity.
Both failure modes are avoidable. The fix is a structured decision — not a gut feel about "predictability".
How Do You Actually Calculate the Break-Even Point?
This is where most guides go vague. Here is the actual maths.
The break-even question is: at what monthly query volume does a slot reservation cost less than on-demand?
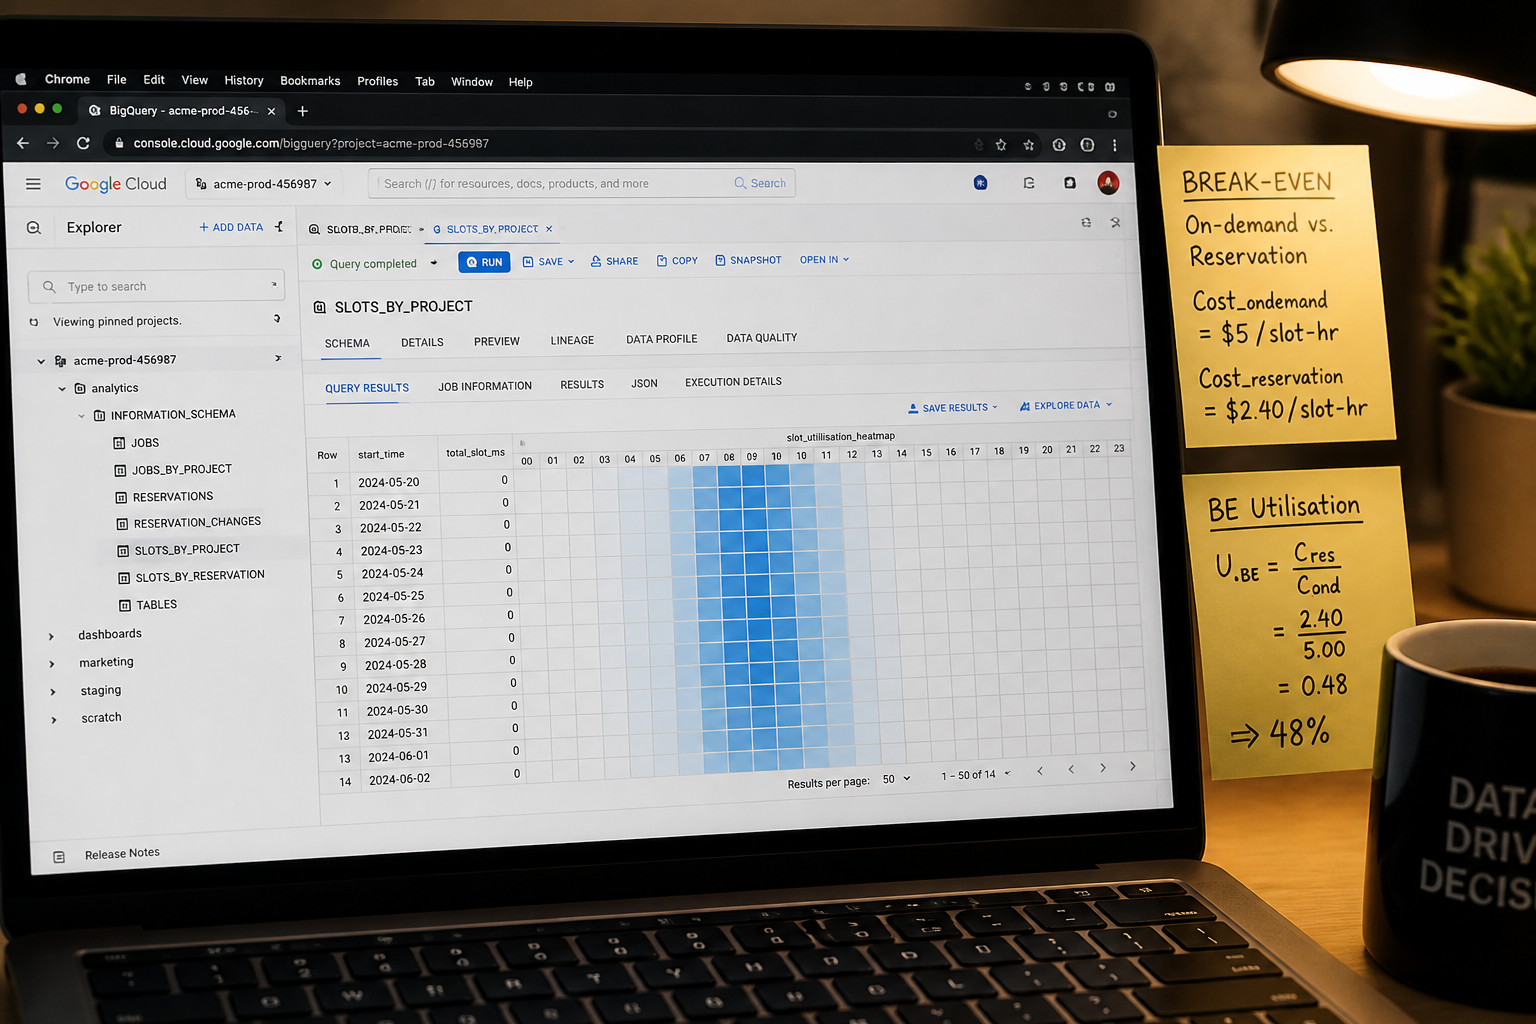
The rule of thumb: if your average slot consumption exceeds 100 slots consistently (not just during peaks), capacity pricing with commitments is likely cheaper than on-demand. At that threshold, Standard edition autoscaling alone costs approximately $0.04 × 100 slots × 730 hours = $2,920/month — equivalent to scanning about 467 TiB on-demand.
But notice the caveat: that is 100 slots consistently, not just during peak windows. Capacity-based pricing requires consistent usage to justify its overhead. Switching too early locks you into active management of a system that isn't saving you money yet.
A more practical framework for growth-stage teams:
Step 1 — Audit your actual slot consumption, not bytes scanned. Run a INFORMATION_SCHEMA.JOBS query over the last 30 days and pull average concurrent slot usage by hour. If you are averaging fewer than 50 slots across most of the day, stay on on-demand. If you are averaging 100+ for 12+ hours per day, the maths starts to move toward capacity.
Step 2 — Separate pipeline slots from ad-hoc slots. Your nightly dbt runs have a predictable slot shape. Your analysts running exploratory queries do not. Reservations work well for the former; on-demand is often fine for the latter. BigQuery lets you run on-demand and capacity pricing simultaneously on a per-project basis, which means you can pilot slots on your heaviest project without touching others.
Step 3 — Start with autoscaling, not a committed baseline. You do not need a commitment to use capacity-based pricing. Starting with autoscaling only (no commitment) is a common way to test whether capacity pricing fits your workload before making a longer-term decision.
Step 4 — Evaluate commitments only once you have 60 days of stable autoscaling data. A 3-year Enterprise commitment saves 37% versus Enterprise pay-as-you-go — but you're locked in for 36 months, and that capacity bill runs whether you use the slots or not. Commitments work best for stable, predictable baseline workloads — think nightly ETL pipelines that run at roughly the same scale every day, or BI dashboards that serve consistent query loads during business hours.
What Are the Hidden Costs Most Teams Miss Before Making the Switch?
The pricing model decision does not exist in isolation. Before you touch reservations, there are upstream problems that will inflate your slot usage and distort any break-even calculation you run.
Unoptimised queries doing full table scans. If your dbt models are materialising as full tables without partitioning or clustering, every downstream query is scanning far more data than it needs to. We have seen teams move to slot reservations and wonder why their slot utilisation is so high — then discover that a handful of unoptimised models are consuming the majority of their compute. Fix the query shape first. Relevant reading: BigQuery Partitioning & Clustering Mistakes Killing Your Bill covers exactly this class of problem.
Models materialised as tables when they should be views or incremental models. Full table materialisation forces BigQuery to recompute an entire model on every run, regardless of how much data actually changed. This is one of the most common cost leaks we fix for clients, and it directly inflates the slot consumption that your break-even analysis will be based on. See dbt Models Materialised as Table in BigQuery: Fix the Cost Leak.
Orphaned scheduled queries still running in the background. Ad-hoc exploration that re-scans large datasets frequently can dominate costs. Legacy scheduled queries that nobody owns, or that were set up by someone who has since left, run silently and accumulate slot usage that makes your workload look busier than it is.
Slot usage spikes masking a low average. Unused reservations, highly concurrent workloads, and complex query structures are the primary culprits behind escalating BigQuery slot cost. If your slot demand is spiky — high for 90 minutes during the morning dbt run, then near-zero for the rest of the day — a baseline reservation will bill you for idle capacity during the low periods. Autoscaling handles this better than a fixed baseline.
In our work with early-stage companies, we consistently find that cleaning up query inefficiencies before switching pricing models reduces the eventual slot reservation size by 30–50%. A team that thought they needed 200 reserved slots discovers they actually need 100 — halving the fixed monthly commitment cost before it ever starts.
If you want to explore whether your current BigQuery setup is cost-optimised before making the pricing model decision, explore how Fintel Analytics approaches this — we run structured BigQuery cost audits for growth-stage businesses as part of our data engineering engagements.
Which Pricing Model Is Right for Your Stage of Growth?
This is the question founders and CTOs actually want answered. Here is a stage-based framework based on patterns we observe in delivery:
Pre-seed and early seed (< $2K/month BigQuery bill): Stay on on-demand. The simplicity is worth it, and the savings available from capacity pricing do not justify the operational overhead of managing reservations. Focus your engineering time on building a clean dbt project structure and partitioning your tables correctly — those decisions will matter enormously later.
Late seed and Series A ($2K–$8K/month BigQuery bill): Run the INFORMATION_SCHEMA audit. If your average hourly slot consumption is consistently above 80–100 slots, it is worth running a 30-day pilot with Standard Edition autoscaling on your heaviest project. If the pilot shows savings, expand it. If it does not, stay on on-demand and focus on query optimisation first.
Series B and beyond ($8K+/month BigQuery bill): Capacity pricing is almost certainly the right model at this scale, but the question shifts to edition selection and whether to take on a 1-year or 3-year commitment. The capacity compute model offers pay-as-you-go pricing (with autoscaling) and optional one year and three year commitments that provide discounted prices. At Series B scale, a 1-year Enterprise commitment is typically the right starting point — it gives you a meaningful discount over pay-as-you-go without the exposure of a 3-year lock-in during a period when your workload is still evolving.
One practical note: to prevent unassigned or newly created projects from defaulting to on-demand pricing, manage your BigQuery reservations using the Google Cloud resource hierarchy — create a reservation assignment at the folder or organisation level rather than project-by-project. This prevents new projects spinning up and quietly accumulating on-demand costs while your reservations sit underutilised on existing projects.
Frequently Asked Questions
Q: When should a startup switch from BigQuery on-demand to slot reservations?
A: The right trigger is consistent average slot consumption above 80–100 slots across most working hours, combined with a predictable workload pattern. Before switching, audit your query efficiency — unoptimised models and full table scans inflate slot consumption and will distort any break-even calculation. Run a 30-day autoscaling pilot before committing to a baseline or long-term contract.
Q: What is the break-even point between BigQuery on-demand and capacity pricing?
A: There is no single universal threshold because it depends on your actual slot consumption rate, not just bytes scanned. As a starting point, if your average concurrent slot usage consistently exceeds 100 slots, capacity pricing with autoscaling is likely cheaper than on-demand at $6.25 per TiB. Run your own INFORMATION_SCHEMA.JOBS analysis to get your actual numbers before switching.
Q: Can you mix on-demand and slot reservations in BigQuery?
A: Yes. BigQuery lets you run both pricing models simultaneously on a per-project basis. This makes it practical to pilot capacity pricing on your heaviest pipeline project while keeping ad-hoc analyst queries on on-demand — which is often the right long-term architecture anyway, since scheduled pipelines and interactive queries have very different slot demand profiles.
Q: What are BigQuery Editions and which one should a growth-stage company use?
A: BigQuery Editions (Standard, Enterprise, Enterprise Plus) are the tiers through which capacity pricing is sold. Standard at $0.04 per slot-hour is suitable for development and testing workloads. Enterprise at $0.06 per slot-hour (or lower with commitments) is the main production tier for most companies and unlocks features like idle slot sharing and folder-level reservation assignments. Enterprise Plus is designed for regulated industries with specific compliance requirements and is rarely the right choice on cost grounds alone.
Q: What should I fix before switching to BigQuery slot reservations?
A: Clean up query inefficiencies first — partition and cluster your tables, convert unnecessary full-table materialisations to incremental or view-based models, and audit your scheduled queries for orphaned jobs. Switching to capacity pricing before doing this means you will oversize your reservation, pay for more slots than you actually need, and never recover that cost. Fix the queries, then size the reservation.
At Fintel Analytics, we help growth-stage companies navigate exactly this decision — not as a theoretical exercise, but as part of hands-on BigQuery cost audits and data engineering engagements where we have personally found and fixed the query patterns that inflate bills and distort break-even calculations. If your BigQuery costs are climbing and you are not sure whether the answer is a pricing model switch or a query optimisation exercise, the answer is almost always both — and the order matters.