
BigQuery row-level and column-level security lets you enforce fine-grained access control across a single table — no data duplication, no shadow datasets, no separate views per team. For growth-stage companies running multiple business functions off a shared data warehouse, getting this right is the difference between a data platform that scales and one that quietly haemorrhages sensitive data.
Most early-stage companies operating on BigQuery reach a predictable breaking point. The first few months, everyone has broad dataset access because the team is small and the risk feels theoretical. Then the company hits 30, 50, 80 people. Finance joins. A third-party data science contractor comes on board. Customer support needs transaction visibility. Suddenly the "everyone reads everything" model is a liability — regulatory, reputational, and operationally. The typical fix is to create separate views or duplicate datasets per team. That approach is expensive, impossible to keep in sync, and creates a governance nightmare that compounds with every new hire.
There is a better way. BigQuery's native fine-grained access controls — row-level security (RLS) and column-level security (CLS) — were built precisely to solve this problem at the storage layer. But used incorrectly, they introduce silent failures, performance regressions, and access gaps that are harder to detect than the problem they were meant to fix. This guide is a practitioner's account of how to implement them correctly.
Why Growth-Stage Companies Get BigQuery Access Control Wrong
The default pattern we see repeatedly at companies between 20 and 150 people: one or two BigQuery datasets, IAM permissions set at the project or dataset level, and a mental model of "analyst role = read everything." It works fine at seed stage. It breaks the moment you have to answer the question: "Can our new data science contractor see customer PII?"
The instinctive fix is to build views. A view per team, a view per region, a view per sensitivity level. We have walked into data stacks where there were 40 views of the same underlying transactions table — each slightly different, each maintained separately, each a potential source of metric drift. One e-commerce client had a orders_for_finance view and an orders_for_ops view that had diverged in their filter logic six months earlier. Finance was seeing cancelled orders included in revenue; operations was not. Neither team knew.
The structural problem is this: views do not solve access control — they just move the complexity. They multiply the maintenance burden, introduce semantic drift, and give you no audit trail of who saw what at the row level.
What BigQuery Actually Offers (and What Most Teams Miss)
BigQuery provides two mechanisms for fine-grained access control: row-level security (RLS) to restrict which rows a user can see, and column-level security (CLS) to restrict which columns are visible. Together, they give you fine-grained access control without duplicating data across multiple tables.
Row-level security extends the principle of least privilege by enabling fine-grained access control to a subset of data in a BigQuery table, by means of row-level access policies. When RLS or CLS is applied, BigQuery rewrites queries under the hood before execution — the user writes a plain SELECT * and BigQuery silently injects the appropriate filters and column masks based on the requesting principal's identity.
This is the key insight most teams miss: the user does not see an error and does not know the filter has been applied. If a user is not a grantee of any policy, they see zero rows — not an error, just an empty result set. That is a significant operational gotcha during setup — we have seen engineers spend hours debugging "empty results" in a new environment when the real issue was a missing row access policy.
📺 Watch: Restricting Access to Rows in BigQuery
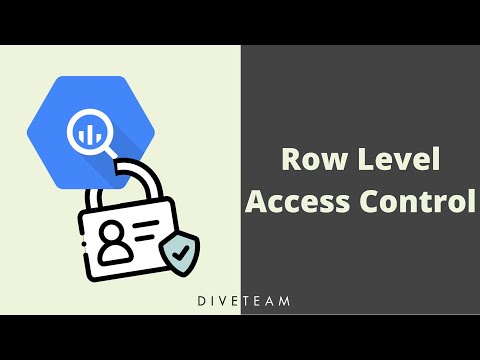
How to Implement Row-Level Security in BigQuery Without Breaking Your Pipelines
Row-level security in BigQuery is built on row access policies — named rules attached directly to a table. A row access policy is a named rule attached directly to a BigQuery table that filters rows based on a filter expression. Each row access policy defines a filter expression (a SQL boolean expression evaluated against each row), a list of grantees (IAM principals — users, groups, service accounts), and a policy name. When a user runs a query against the table, BigQuery identifies all row access policies for which the user is a grantee, then logically ORs those filter expressions together and appends them as a WHERE clause to the query.
Here is what a working policy looks like in practice:
CREATE OR REPLACE ROW ACCESS POLICY eu_transactions
ON `project.dataset.transactions`
GRANT TO ("group:eu-analysts@company.com")
FILTER USING (region = 'EU');

CREATE OR REPLACE ROW ACCESS POLICY full_access
ON `project.dataset.transactions`
GRANT TO ("group:data-engineers@company.com")
FILTER USING (TRUE);
The FILTER USING (TRUE) policy is critical and often forgotten. When you set up row access policies on a table, you need at least two row access policies: a policy that grants access to the table (the first should grant access to users and groups that require full access for data maintenance or support — for example, your BigQuery administrators and service accounts that use DML statements to transform table data).
Service accounts are where this most commonly breaks in dbt environments. Your dbt transformation service account needs FILTER USING (TRUE) access to every table it reads from. Miss one and your dbt run will complete successfully — it will just silently produce models with empty source data. We have had to debug this exact failure mode on client pipelines. The model builds, the tests pass (because an empty table passes a not_null test on zero rows), and the dashboard shows zeroes. It looks like a data freshness issue until you trace it to the RLS layer.
The dbt-Specific Playbook
If you are managing your BigQuery transformations in dbt, the access control question has an additional dimension: your dbt models themselves may need to enforce the same access logic downstream. There are two valid approaches:
Option 1 — Push security to the source tables. Apply RLS directly to your raw or staging source tables. Your dbt models read through the policies and the restricted views propagate automatically. This is the simpler approach and works well when your BI tool queries dbt mart models directly.
Option 2 — Apply RLS to mart-layer models. Leave source tables open to the dbt service account, apply policies only to the final reporting tables or views that your BI users query. This gives you more control but means you are managing policies at a different layer than where data lands.
Option 1 is the right default for most companies up to Series B. Option 2 makes sense if you have complex intermediate models that multiple downstream consumers use differently. The decision is simpler than most teams make it — pick the layer closest to where your BI users actually query.
For column-level security, the implementation uses BigQuery's Data Catalog policy tags. Column-level security uses policy tags from Data Catalog — you create a taxonomy of sensitivity levels, assign tags to columns, and then control who can see columns at each sensitivity level. In practice, we typically see three tiers work well: PUBLIC, SENSITIVE, and PII_RESTRICTED. Engineers and BI tools get SENSITIVE access; only approved data scientists and certain automated pipelines get PII_RESTRICTED. This is the approach we used for a global payments client managing cardholder data across multiple analyst teams — it replaced a manual process of duplicating masking logic in six different views.
If your team hasn't yet assessed whether PII is sitting in accessible columns without column-level policies applied, this diagnostic approach for finding unmasked PII in BigQuery is a good starting point before you build out the access policy layer.
The Performance Traps That Kill RLS Adoption
This is where most implementation guides stop short. Row-level security is not free — and the performance implications, if misunderstood, will cause your engineering team to rip it out after the first slow query complaint.
Avoid making row access policies that filter on clustered and partitioned columns — row-level access policy filters don't participate in query pruning on partitioned and clustered tables. If your row-level access policy names a partitioned column, your query does not receive the performance benefits of query pruning.
This is a significant constraint in practice. Many BigQuery tables are partitioned on created_at or event_date and clustered on region or country_code — exactly the columns teams want to filter on in RLS policies. If you apply RLS on a region column that is also a cluster key, you lose the full benefit of clustering on every query that hits that table.
The workaround: keep your RLS filter predicate on a non-clustered, non-partitioned column where possible (for example, a data_owner_group or tenant_id column that you populate at ingestion time specifically for access control purposes). Then rely on the user's own query predicates on the partitioned columns for performance. The main performance tip is to keep normal query predicates on partitioned or clustered columns when those predicates are part of the user's query — do not rely on the row access policy filter itself to provide partition or clustering pruning.
A second performance consideration: RLS adds overhead on query planning. For dashboards that run high-frequency, low-latency queries (think operational BI refreshing every 30 seconds), the overhead is measurable. In one case, a fintech client running a near-real-time payments dashboard saw p95 query latency increase by 15–20% after naively applying RLS to their main transactions table. The fix was to materialise a pre-filtered mart layer for the high-frequency BI queries and apply RLS to the lower-frequency analytical tables only. Not every table needs the same access control mechanism.
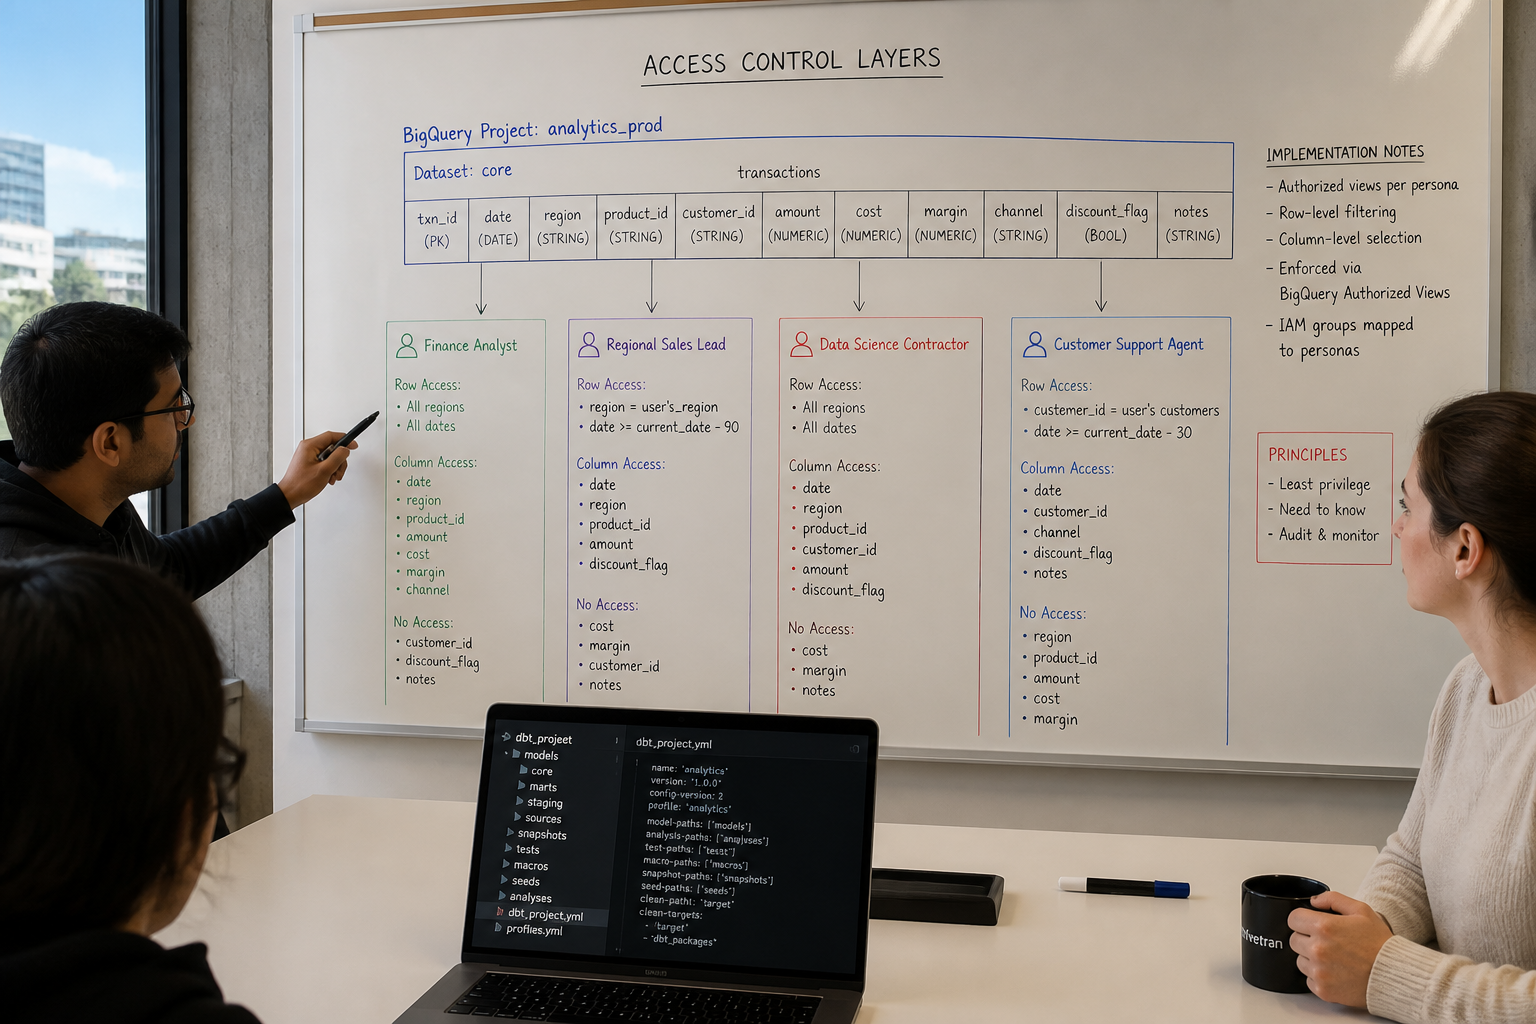
When to Use RLS, CLS, Views, or Dataset-Level IAM — A Decision Framework
The most common question we get from CTOs and data leads at growth-stage companies is not "how do I implement RLS" — it is "which access control mechanism should I be using for this specific case?"
Here is the decision framework we apply in the field:
Use dataset-level IAM when teams operate on entirely distinct data domains with no overlap. Finance gets the finance dataset, marketing gets the marketing dataset. Simple, auditable, no policy management required. Works well when datasets are clean and teams do not need cross-domain access.
Use row-level security when multiple teams query the same table but need different row subsets. Regional sales teams, multi-tenant platforms, partner data sharing, or any scenario where the same schema is shared but the population of rows differs by consumer. The key test: if two different users running the same query should see different rows, you need RLS.
Use column-level security (CLS with policy tags) when all users can see the same rows but some columns must be restricted. PII fields (email, phone, name, card number), salary data, margin data — columns that cut horizontally across every row. CLS is the right tool; views are the wrong one.
Use materialised views or dbt mart models when you need pre-aggregated data products for specific teams — not for access control, but for performance and semantic clarity. Do not conflate data modelling with access control; they are separate concerns that belong at separate layers.
Avoid view proliferation as an access control strategy. Before BigQuery's native fine-grained access controls, the typical solution was to maintain separate views or copies of data per team — an approach that is expensive, hard to keep in sync, and creates a governance nightmare. Row-level security and column-level security eliminate these workarounds at the storage layer itself.
If you are looking to implement a structured access control model across your warehouse, explore how Fintel Analytics approaches data engineering and governance — we work with growth-stage companies globally to design exactly this kind of layered security architecture, from IAM policy design through to dbt model governance.
What Happens When You Get This Wrong — Real Costs, Real Failures
The stakes here are higher than most engineering teams appreciate at the time they are making the access control decision. IBM reports the global average breach cost rose to approximately $4.88M in 2024, then fell to $4.44M in 2025. For a fintech company, the figure is higher: financial services organisations face an average breach cost of USD 6.1 million, with compliance-related penalties increasing 18% year-over-year. Most of these costs are not from sophisticated external attacks — despite record investments in security, human error and misconfiguration remain leading causes of breaches, with 45–50% of breaches now involving cloud or SaaS environments.
Misconfigured BigQuery access is a cloud misconfiguration problem. It does not make headlines the way an external breach does, but the regulatory consequences — particularly under GDPR, PCI DSS, and equivalent frameworks — are identical. A data science contractor who inadvertently has access to production cardholder data because nobody set up column-level security is an audit finding waiting to happen.
Beyond the regulatory dimension, the operational cost is real. We have seen companies running quarterly access reviews that take 3–4 days of engineering time because there is no systematic model — just a spreadsheet of "who has access to what" that nobody fully trusts. A well-implemented RLS and CLS architecture, managed through IAM groups and code-reviewed policy definitions, reduces that quarterly review to a CI/CD check.
The internal access risk is also underappreciated. IBM found that 97% of AI-related breaches involved systems without proper access controls, and most affected organisations lacked governance policies to manage AI or prevent shadow AI — the unauthorised use of AI without employer oversight. As analytics teams at growth-stage companies start routing BigQuery data into LLM pipelines and AI tools, the access control model on the source data becomes the last line of defence.
Frequently Asked Questions
Q: What is the difference between row-level security and column-level security in BigQuery?
A: Row-level security controls which rows a user can see in a table, based on filter expressions attached to row access policies. Column-level security controls which columns are visible, implemented through Data Catalog policy tags. They solve different problems and are typically used together — RLS for "which population of records" and CLS for "which fields within those records."
Q: Does row-level security in BigQuery affect dbt model performance?
A: Yes. RLS filters do not participate in partition pruning or clustering benefits on partitioned and clustered tables. If your dbt source tables use partitioning and clustering for query efficiency, applying RLS filters on those same columns will negate the performance benefits. The recommended pattern is to filter on a dedicated access-control column rather than operational partition columns.
Q: Can I manage BigQuery row-level security policies through dbt?
A: Not natively — dbt does not yet have a first-class resource type for BigQuery row access policies. The common approach is to define and deploy policies via Terraform or a post-hook SQL script, keeping them version-controlled alongside your dbt project. This ensures policy changes go through the same review process as model changes.
Q: What happens if a user is not covered by any row access policy?
A: BigQuery returns an empty result set — not an error. This is one of the most common debugging issues during initial implementation: a developer queries a table, gets zero rows, and assumes it is a data freshness problem. Always verify that every intended user or service account is explicitly covered by at least one row access policy, including a FILTER USING (TRUE) policy for administrators and service accounts that need full access.
Q: How do I audit who has access to what in BigQuery?
A: BigQuery Data Access logs (available in Cloud Audit Logs) record every read and write operation, including the identity of the requester. For access policy auditing specifically, you can query the INFORMATION_SCHEMA.ROW_ACCESS_POLICIES view to list all policies and their grantees across your datasets. Combining these two sources gives you a full picture of what access exists and who has used it.
Getting BigQuery access control right is one of those decisions that looks simple until it is not — and by the time the complexity becomes visible, the damage is usually already done: a contractor with too much access, a view that has silently diverged, a compliance audit that surfaces what engineering assumed was handled. At Fintel Analytics, we have designed and implemented layered access control architectures for fintech, payments, and e-commerce companies — from initial IAM policy design through to RLS and CLS deployment integrated with dbt pipelines. If your team is still relying on broad dataset permissions or a proliferating library of views to manage who sees what, that is a solvable problem — and solving it correctly the first time is materially cheaper than fixing it after an audit.