 Fintel Analytics
Snowflake Query Spilling to Remote Storage: Find & Fix It
Remote spill is the slowest, costliest way a Snowflake query can run. Here is the SQL to find every spilling query and dbt model, and how to fix them.
Snowflake query spilling to remote storage happens when a query's intermediate data overflows both the warehouse's memory and its local SSD, so Snowflake writes it out to cloud object storage. You can find every affected query by filtering SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY for bytes_spilled_to_remote_storage > 0. The fix is either to process less data per query or to run it on a bigger warehouse, and you should try the first one first.
The usual pattern: a nightly dbt run that used to take 20 minutes creeps up to 70. Nobody changed the warehouse and nobody touched the models. The data simply grew past the point where one join or window function fit in memory. Finance gets its numbers later every week, and the Snowflake bill rises because the warehouse stays up longer. This post gives you the queries to find the problem in about five minutes, a framework for deciding between a SQL fix and a bigger warehouse, and the guardrails that stop it coming back.
What Does Snowflake Query Spilling to Remote Storage Actually Mean?
Every Snowflake warehouse node has limited memory. When a sort, join, aggregation or window function needs more than that, Snowflake spills intermediate data first to local disk and then, if that is not enough, to remote cloud storage. The two stages behave very differently:
- Local spill means the working set exceeded memory. It costs you a disk penalty measured in seconds.
- Remote spill means the working set exceeded local disk as well. That is a network penalty measured in minutes.
Because warehouses bill per second while running, the extra runtime a spilling query adds is paid for at the warehouse's full rate. Remote spill is therefore both a performance problem and a cost problem, and it rarely shows up in anyone's dashboard. It is recorded in query history, but almost nobody reads those columns.
One caveat before you start. With Query Acceleration Service enabled, Snowflake writes a small amount to remote storage for each eligible query, so a tiny non-zero value on its own is not a sizing signal. Look for gigabytes, not kilobytes.

📺 Watch: Snowflake COF-C03: Diagnosing Slow Queries with Query Profile
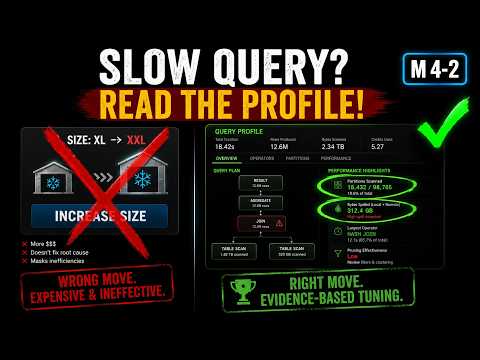
How Do You Find Queries Spilling to Remote Storage in Snowflake?
Start with the raw list. This works on any account where your role can read the SNOWFLAKE database (note that ACCOUNT_USAGE views can lag by up to 45 minutes):
SELECT
  query_id,
  warehouse_name,
  warehouse_size,
  user_name,
  query_tag,
  ROUND(total_elapsed_time / 1000, 1) AS seconds,
  ROUND(bytes_spilled_to_local_storage / POWER(1024, 3), 2) AS gb_local_spill,
  ROUND(bytes_spilled_to_remote_storage / POWER(1024, 3), 2) AS gb_remote_spill,
  partitions_scanned,
  partitions_total,
  LEFT(query_text, 150) AS query_snippet
FROM snowflake.account_usage.query_history
WHERE start_time >= DATEADD('day', -7, CURRENT_TIMESTAMP())
  AND bytes_spilled_to_remote_storage > 0
ORDER BY bytes_spilled_to_remote_storage DESC
LIMIT 25;
That tells you which queries spilled. It does not tell you which dbt model to open. dbt writes a comment into every query it submits, and the default comment includes the model's node ID. Use it to roll spill up by model:
SELECT
  REGEXP_SUBSTR(query_text, '"node_id": "([^"]+)"', 1, 1, 'e', 1) AS dbt_node,
  warehouse_name,
  warehouse_size,
  COUNT(*) AS runs,
  SUM(IFF(bytes_spilled_to_remote_storage > 0, 1, 0)) AS runs_with_remote_spill,
  ROUND(SUM(bytes_spilled_to_remote_storage) / POWER(1024, 3), 1) AS total_gb_remote,
  ROUND(SUM(bytes_spilled_to_local_storage) / POWER(1024, 3), 1) AS total_gb_local,
  ROUND(SUM(total_elapsed_time) / 1000 / 60, 1) AS total_minutes
FROM snowflake.account_usage.query_history
WHERE start_time >= DATEADD('day', -14, CURRENT_TIMESTAMP())
  AND query_text LIKE '%"app": "dbt"%'
  AND (bytes_spilled_to_remote_storage > 0 OR bytes_spilled_to_local_storage > 0)
GROUP BY 1, 2, 3
ORDER BY total_gb_remote DESC, total_gb_local DESC
LIMIT 20;
If you have customised query-comment in dbt_project.yml, adjust the regex to match. In most projects we audit, the result is lopsided. Two or three models account for nearly all the remote spill, usually a wide fact table build or a sessionisation step. You do not have a warehouse-wide sizing problem. You have a handful of models with a shape problem.
Snowflake's own documentation uses a similar query against QUERY_HISTORY and notes that the Query Profile shows which operator nodes are causing the spill. Open the top offender's profile and note whether the spilling node is a Join, Sort, Aggregate or WindowFunction. That single detail drives the next decision.
Is It the Warehouse Size or the SQL? A Decision Framework
Snowflake's documented remedies are a larger warehouse, or processing data in smaller batches. The cheaper option comes first. Running the first query above and the Query Profile together lets you triage each offender:
| What you see | Likely cause | First move |
|---|---|---|
| partitions_scanned close to partitions_total on a big table | Filter not pruning, so you read far more than you need | Filter on the clustering or date column; fix non-sargable predicates |
| Join node spilling, output rows far above input rows | Fan-out from a non-unique join key | Deduplicate or test uniqueness upstream, then re-run |
| Sort or WindowFunction node spilling | Global ORDER BY or a window over one giant partition | Remove the ORDER BY, partition the window, or pre-aggregate |
| Well-pruned, correct joins, still spilling | The dataset is genuinely large | Upsize that one model's warehouse, or batch the build |
On credits: each warehouse size step doubles the hourly rate, from 1 credit for X-Small to 8 for Large and 16 for X-Large. Upsizing is not automatically more expensive, because a query that stops spilling often finishes in far less than half the time. But that only holds when spill is the actual bottleneck. If a fan-out join is producing ten times the rows it should, a bigger warehouse just buys you a faster wrong answer at a higher hourly rate.
A pattern we see repeatedly in early-stage companies is that the first reaction to a slow run is to bump the warehouse to Large and move on. The bill rises, the real defect stays, and six months later the data has doubled and the Large is spilling too. In a reconciliation rebuild we delivered for a global fintech, a process that took 30 to 50 minutes became an automated SQL pipeline completing in under 3 seconds. That came from changing the query's shape, not from buying compute.
Running those queries for a handful of models is fine. Checking every model in a project is not. fintel-scan is a free, open-source (MIT) CLI that runs static checks on your dbt project locally with no warehouse connection: uvx fintel-scan. It cannot read query history, so use the SQL above to find what spilled and the scan to find other models built the same way. Check its README for the current list of checks.
How Do You Fix Snowflake Spilling in dbt Models?
1. Cut the data before the expensive operation. Push filters and column selection into the CTE that feeds the join or window, not after it. Dropping unused wide columns, especially VARIANT and long text, shrinks the working set more than most people expect.
2. Replace global sorts and unpartitioned windows. An ORDER BY inside a dbt model that is materialised as a table does nothing useful downstream. Remove it. For windows, make sure PARTITION BY splits the data into reasonable groups rather than one huge one.
3. Fix the fan-out. If output rows exceed input rows on a join that should be one-to-one, add a uniqueness test on the join key and deduplicate with QUALIFY ROW_NUMBER() OVER (PARTITION BY id ORDER BY updated_at DESC) = 1.
4. Build big incremental models in batches. A full rebuild of a billion-row table in one statement is the classic remote-spill trigger. Switching to an incremental model, or to dbt's microbatch strategy on dbt 1.9 or later, processes bounded slices instead.
5. Upsize only the models that need it. If the data really is that big, give just those models a larger warehouse rather than resizing the whole target:
{{ config(
    materialized='table',
    snowflake_warehouse='TRANSFORM_XL'
) }}
The other 95% of your models keep running on the small warehouse, and you pay the XL rate for minutes rather than hours. If you are also seeing credits burn between runs, see our guide to finding idle Snowflake warehouse costs.
After each change, re-run the model-level query above over the next few days. The model should disappear from the list. If it only drops from remote to local spill, that is usually acceptable for a nightly job.

How Do You Stop Remote Spill Coming Back?
Spill is a drift problem. It does not appear on day one, it appears when data volume crosses a threshold. So you need a tripwire, not a one-off audit.
Tag your queries. Set a query_tag in your dbt profile or model config so spill can be attributed to a team or pipeline, not just a user. Our dbt-comment regex works, but tags survive custom comment changes.
Alert on it. A Snowflake alert can email you when a day produces significant remote spill. A threshold of roughly 1 GiB is a reasonable starting point. At least one monitoring vendor uses a p95 remote spill above 1 GiB over 14 days as its warning rule.
CREATE OR REPLACE ALERT remote_spill_alert
  WAREHOUSE = ops_wh
  SCHEDULE = 'USING CRON 0 7 * * * UTC'
  IF (EXISTS (
    SELECT 1
    FROM snowflake.account_usage.query_history
    WHERE start_time >= DATEADD('hour', -24, CURRENT_TIMESTAMP())
      AND bytes_spilled_to_remote_storage > 1073741824
  ))
  THEN CALL SYSTEM$SEND_EMAIL(
    'my_email_int',
    'data-team@yourcompany.com',
    'Remote spill detected in last 24h',
    'Run the spill-by-model query in the runbook.'
  );

ALTER ALERT remote_spill_alert RESUME;
You will need a notification integration and the EXECUTE ALERT privilege for this to run.
Review it with the code. Add the spill-by-model query to your fortnightly data-team review. Spill belongs next to test failures and freshness breaches as a standard health signal. It is also worth keeping your marts documented, so whoever picks up a slow model knows what it is for. We cover that in finding undocumented dbt models.
This is the kind of fix that explores what you need from your services: find the three models causing the problem, correct them, and put a tripwire in place so the next growth spurt does not surprise you.
Frequently Asked Questions
Q: What is Snowflake query spilling to remote storage?
A: It is when a query's intermediate data exceeds both warehouse memory and local SSD, so Snowflake writes it to cloud object storage. It is the slowest spill tier, and the query keeps consuming credits for the whole extra runtime.
Q: How do I find queries spilling to remote storage in Snowflake?
A: Query SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY and filter for bytes_spilled_to_remote_storage > 0, ordering by that column descending. Include warehouse_size, query_tag and query_text so you can trace the query to a job or dbt model.
Q: Does a bigger warehouse fix remote spill?
A: Often, because each size step doubles memory and local storage, and Snowflake lists a larger warehouse as a remedy. It will not fix a fan-out join or an unpruned scan, though. Test the SQL first, and upsize only the models that still spill afterwards.
Q: Is local spill a problem too?
A: Local spill is slower than in-memory processing but much less severe than remote spill. For a nightly batch job it is often acceptable. For interactive dashboards or tight SLAs, treat it as a warning sign.
Q: Why does a small amount of remote spill show up on fast queries?
A: If Query Acceleration Service is enabled, Snowflake writes a small amount to remote storage for each eligible query even when QAS is not used. A tiny non-zero value alone is not a sizing signal, so focus on queries spilling gigabytes.
Conclusion
Snowflake query spilling to remote storage is a quiet drain. It slows your pipelines, inflates your credit bill and delays the numbers your finance and operations teams rely on, and the evidence is already sitting in query history. At Fintel Analytics, we have helped fast-growing fintech, payments and e-commerce teams trace slow warehouse spend back to a few badly shaped models, fix them in SQL and dbt, and put monitoring in place so the problem stays fixed. If your nightly run keeps getting longer and your first instinct is to buy a bigger warehouse, a short audit will usually find a cheaper answer, and it pays for itself within a billing cycle or two.