 Fintel Analytics
How to Automate Tender Monitoring With AI (Without Missing Bids)
How to automate tender and listing monitoring with an AI agent: what it checks daily, what it costs to run, and where a person still decides.
To automate tender monitoring with AI, you need an agent that checks your sources on a schedule, removes duplicates, researches the buyer, and scores each opportunity against criteria you have written down. It then hands a short, ranked list to a person for a yes or no. The agent does the reading and the person makes the decision. Every step has to be costed, logged and linked back to the original notice.
If you own a bid pipeline, you probably know the routine. Someone opens six or seven portals each morning, scans titles, opens the ones that look promising, and pastes the interesting ones into a spreadsheet. It takes an hour or two, it is the first thing dropped in a busy week, and nobody notices a missed tender until the deadline has passed. This post covers how to replace that routine with a monitoring agent that holds up in production, what it costs to run, what went wrong in our builds before they worked, and when you should build it versus buy it.
Why Does Manual Tender Monitoring Break Down?
Manual monitoring breaks for three reasons, and none of them is that your team is lazy.
The sources multiply and none of them agree. Every portal has its own format, categories, alert settings and quirks. Email alerts from one portal are too broad, and another has no alerts at all. The person doing the checking becomes the integration layer between all of them.
The judgement is unwritten. Ask the person who does the daily scan how they decide something is worth a look. They will say they just know. That knowledge is exactly what an agent needs, and it is rarely written down anywhere. Most of the early work in any monitoring build is getting that judgement into explicit criteria.
The output lives in a spreadsheet nobody owns. A pattern we see repeatedly in growth-stage companies is critical operations running on a shared sheet. One person edits the wrong cell, a filter hides rows, and the pipeline is wrong without anyone knowing. When the tracker is also where the deadline lives, the cost of an error is a lost bid.
There is a wider reason to be careful before you automate. Gartner predicted in June 2025 that over 40% of agentic AI projects will be canceled by the end of 2027, due to escalating costs, unclear business value or inadequate risk controls. Monitoring is a good first agent project because the value is easy to state (hours saved and bids not missed). The costs can be measured, and the risk is low because the agent recommends and a person acts.
📺 Watch: This AI system found £4m in government tenders in 60 days
How Does an AI Agent Automate Tender Monitoring?
The clearest example we can give comes from a job-search assistant we built for education professionals. The domain is different from tenders, but the architecture is the same one you need for any opportunity feed. The problem it solved was a familiar one. A person was spending hours every week across ten job boards, re-reading the same listings and trying to judge employers from memory.
Here is how that system works, translated to tenders.
1. A schedule triggers collection
Most of the sources are checked automatically twice a day. No one has to remember to look. For tenders, this means each portal is polled on a schedule, and new notices are captured with their title, buyer, value, deadline and a link.
2. The awkward sources get a one-click capture
Not every source can be checked automatically. Some sites resist automation, and some sit behind logins or are only reachable through email. In the job tool, those sources are captured with a single click. The listing is sent to the same pipeline, and everything after that is identical. This matters in practice. If you insist on automating 100% of sources, the build stalls on the hardest one. Automate what is easy and give a person a one-click route for the rest.
3. The agent deduplicates before it spends money
The same opportunity often appears on several portals, sometimes reworded. Matching and removing duplicates should happen first and cheaply, with plain code and no model call. Paying a language model to read the same notice three times is the most common avoidable cost in these systems.
4. The agent researches the buyer
For each employer, the job tool researches pay, savings potential, reputation and location. The tender equivalent is buyer research: who the contracting authority is, what it has bought before, how large the contract is relative to your capacity, and whether the location is workable. This is the step that takes a person the longest, and it is where an agent adds the most value.
5. The agent scores against written criteria, and shows its working
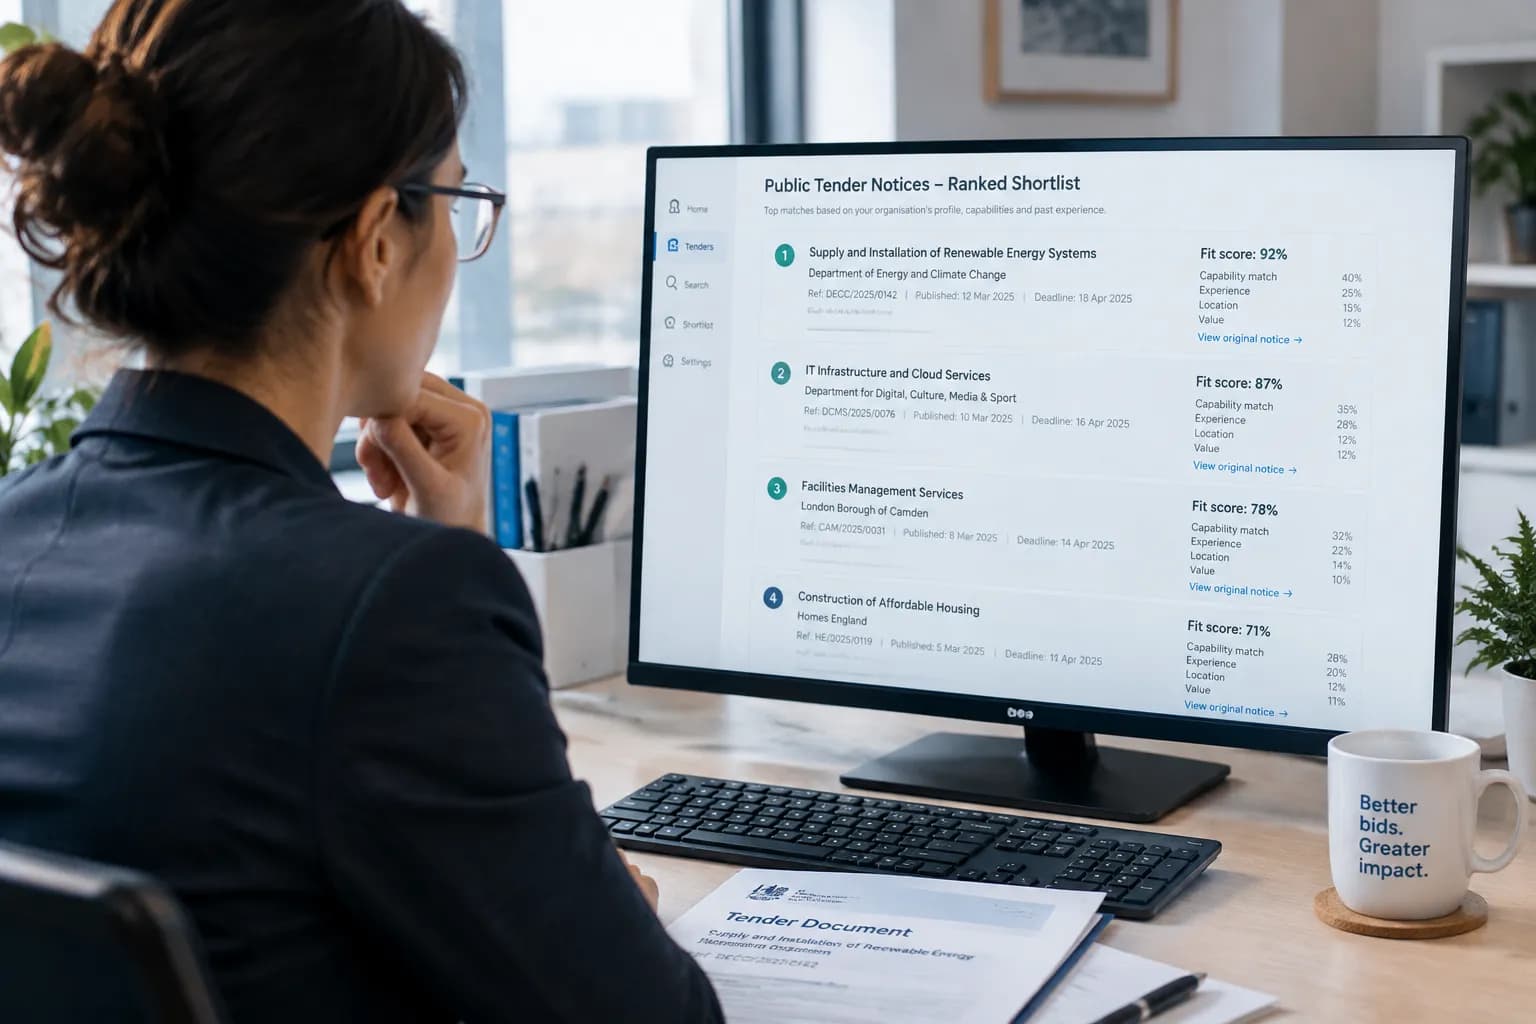
Each match is scored against the candidate's profile, with a visible breakdown. For you, that means a score against your sector, contract value range, geography, certifications and capacity. A bare number is worthless. We have seen teams ignore a score they could not interrogate, and that is reasonable. If the breakdown shows the notice scored high on sector and value but lost points on location, the reviewer can overrule it in seconds.
6. Every item links back to the original
Every result links to the original post. The agent summarises and the source document is the authority. A person should never have to take the agent's reading of a deadline on trust.
7. A person decides
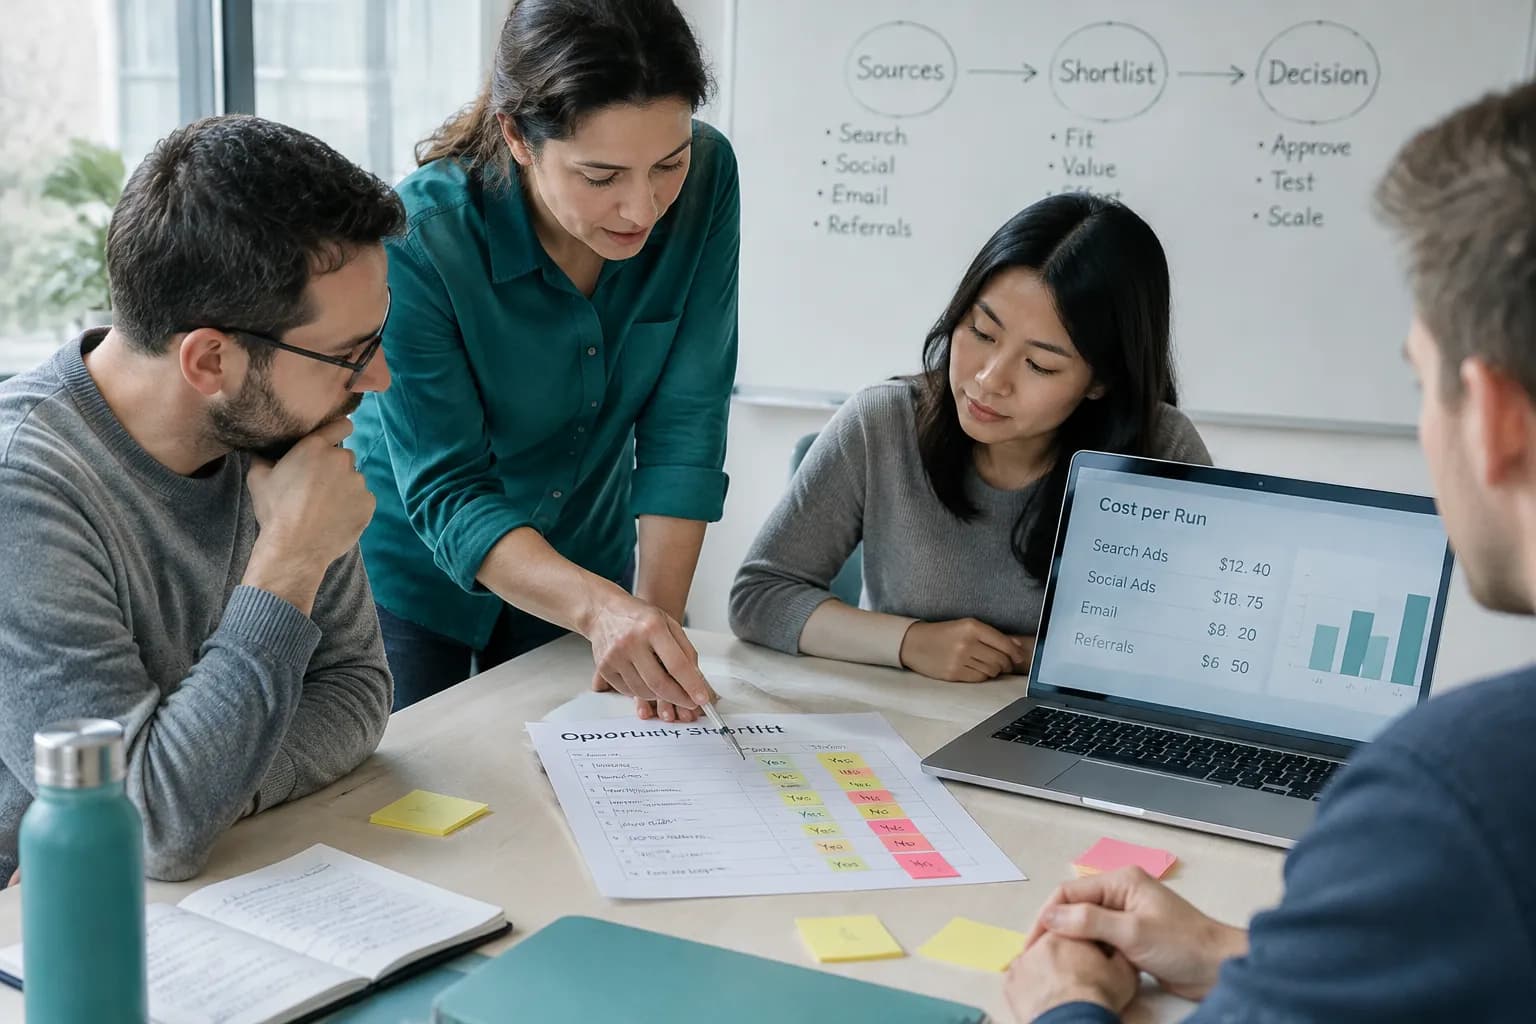
The agent's output is a ranked shortlist, and the human approval step is the bid/no-bid call. The agent does not submit, register interest or contact anyone. For the wider pattern, see our guide to building an AI agent approval workflow with audit trails.
What Does It Cost to Run a Monitoring Agent?
This is the question that separates a useful agent from an expensive toy. In the job tool, every paid model call is shown in the app. That one design decision does more for cost control than any budget alert, because nobody wonders what the system is spending.
I am not going to quote a per-run price for your tender agent. It depends on how many sources you poll, how many notices arrive each day, and how deep your buyer research goes. What you can do is build the cost model before you build the agent.
Cost per useful output, not cost per call. Count the notices that reached a person's shortlist, and divide your total model spend by that number. In a go-to-market system we built for a pre-seed tech company, fixing the prospecting stage took the cost per outreach-ready lead from $1.28 to $0.05. The model did not get cheaper. We stopped paying for runs that failed and for research on leads that were never going to qualify. The share of runs that failed fell from 86% to 14%.
Put the cheap filter first. Plain code removes duplicates and applies hard rules such as a minimum value, an excluded region or a past deadline. A small, inexpensive model does a first-pass relevance check. Only notices that survive both get the full buyer research and scoring. We cover this tiering in our guide to LLM model routing strategy. In an e-commerce operations hub we built, routine questions go to a cheap model and only the marketing analysis goes to a stronger one, so running costs stay small.
Measure against the manual baseline. Time one person doing the daily scan for a week. Multiply by loaded hourly cost. That is the number the agent has to beat, and in most cases it is a very low bar. Our guide on AI agent cost per run covers how to set it up.
If this is a process your team still runs by hand, see how Fintel Analytics builds tools like this. We design and ship AI agents and internal tools that take over exactly this kind of work, with cost tracking, approval steps and audit trails built in.
What Went Wrong Before It Worked, and What Still Needs a Person?
Agent projects get oversold when nobody talks about the failures. These are the ones we hit, and the ones we now plan for.
The weakest stage sets the quality of everything after it. In the go-to-market build, only 5% of leads had a contact found at the start. Every downstream stage looked bad because its input was bad. Fixing that one stage took the figure to 86%. In a tender agent, the equivalent is collection. If your portal polling misses notices, your scoring is meaningless however clever it is. Fix collection first.
Opaque scores get ignored. An early score with no explanation made reviewers distrust the whole list. The visible breakdown fixed it. People will challenge a score, and that is healthy as long as they can see why it was given.
Research on everything wastes money. Researching every incoming item is expensive and mostly pointless, since most items fail a basic fit test. Research comes after the cheap filter, never before.
Agents are wrong sometimes. A deadline gets misread, or a buyer is confused with another organisation of a similar name. This is why every item links to the original and why the agent never acts on its own. If a wrong output can cost you a bid, a person confirms it before anything happens.
What still needs a person:
- The bid/no-bid decision, which depends on relationships, capacity and strategy that are not in any feed.
- Reading the actual tender documents for anything you pursue.
- Maintaining the scoring criteria. Your priorities will change, and the criteria must change with them.
- Reviewing the agent's misses every few weeks. Pull a sample of notices it rejected and check that it was right to reject them.
For teams that want a hard stop, we also add a kill switch that pauses the whole pipeline. We use one in the go-to-market system, and it costs almost nothing to build. It is much more expensive to need one and not have it.
Should You Build or Buy Tender Monitoring Software?
Off-the-shelf alert services are the right answer more often than agent vendors admit. Use this framework to decide.
Buy when:
- Your sources are mainstream, and an existing service already covers them.
- Keyword and category filters are enough to separate good notices from bad.
- You do not need buyer research or custom scoring.
- The subscription is cheaper than the hours it saves, and you are comfortable with how it handles your data.
Build a small custom tool when:
- You monitor niche or fragmented sources that no service covers well.
- Your fit criteria are multi-factor and cannot be expressed as keywords. Examples are value range, buyer history, geography and capacity together.
- The research step is the real time sink.
- The output has to feed your own pipeline, spreadsheet or CRM rather than another dashboard.
- You are paying for several subscriptions that each do one-third of the job.
A useful test is to write the scoring criteria on one page. If the page is easy to write and a keyword filter would capture it, buy something. If it takes real thought and the thought is your competitive edge, build it. We go through this reasoning in more depth in Build vs Buy Internal Tools.
One more practical point: do not start with an agent. Start with the one-page criteria, a week of timed manual scanning, and a list of your sources. Those three things decide whether you need a tool at all, and they make the build much faster if you do.
Frequently Asked Questions
Q: Can AI really automate tender monitoring?
A: Yes, for the repetitive part. An agent can poll sources on a schedule, remove duplicates, research buyers and score notices against your criteria. It should not make the bid/no-bid decision or submit anything. A person reviews a ranked shortlist and decides.
Q: How much does it cost to run an AI monitoring agent?
A: It depends on the number of sources, daily volume and research depth, so be wary of anyone quoting a flat figure without asking. The most reliable way to keep it low is to run plain-code deduplication and a cheap model first, and to save the stronger model for notices that pass. Track cost per shortlisted opportunity, not cost per call.
Q: What is the difference between an alert service and an AI agent for tender monitoring?
A: An alert service matches keywords and categories and sends you notices. An agent also researches the buyer, scores fit across several factors and explains the score. If keyword filters are enough, an alert service is cheaper and simpler.
Q: How do you stop an AI agent from missing or misreading tenders?
A: Link every result to the original notice, and keep a person on the approval step. Check the sources are being collected reliably before you tune scoring, and review a sample of rejected notices every few weeks. Add a kill switch so the pipeline can be paused if output quality drops.
Q: Should a small business build its own tender monitoring tool?
A: Build only if your sources are niche, your fit criteria are multi-factor, or the research step is your real time sink. If mainstream alerts and a keyword filter do the job, buy them. Write the criteria on one page first, because that tells you which route fits.
Conclusion
The challenge is rarely the technology. It is a daily scan that depends on one person's memory, a spreadsheet nobody trusts, and a pipeline where a missed notice only shows up when it is too late. At Fintel Analytics, we have built monitoring and research agents that check sources on a schedule, score opportunities with a visible breakdown, cost every model call, and leave the final decision to a person. If you want to automate tender monitoring with AI and know what it will cost before you commit, that is a fixable problem, and the hours you get back are worth far more than the cost of the build.