 Fintel Analytics
dbt Tests BigQuery Cost: Find Tests Scanning Full Tables
Your dbt tests may be the largest line in your BigQuery bill. Here is the SQL to find the worst offenders and the config to cut their scan cost.
If your dbt tests BigQuery cost has crept up, the cause is almost always the same: generic tests like unique, not_null and relationships run a full scan of the tested columns on every build. To find the worst offenders, query INFORMATION_SCHEMA.JOBS_BY_PROJECT, filter on the dbt query comment that marks test nodes, and rank by bytes billed. Then add a where filter on the partition column so each run tests recent data instead of all history.
Most teams optimise their models and never look at the tests guarding them. The tests are small, they pass quietly, and nobody checks what they cost. On on-demand pricing, a test is a query like any other. BigQuery on-demand queries cost $6.25 per TiB scanned in most regions, and a test that runs hourly against a large fact table bills every time. This post gives you the SQL to find those tests in about five minutes, the config to fix them, and the guardrails to keep them fixed.
Why Do dbt Tests Inflate BigQuery Cost?
A dbt generic test compiles to a SELECT against your model. A unique test groups by the column and counts duplicates. A not_null test filters for nulls. A relationships test joins the child table to the parent. None of these has a time boundary unless you give it one, so every run reads the full history of the columns involved.
BigQuery is columnar, so a test only bills for the columns it touches, not the whole table. That is why the problem hides well: no single test looks alarming. The cost comes from multiplication. Consider a unique test on a key column that holds roughly 100 GiB. A query that scans 100 GiB costs about $0.61. Run hourly, that is around 720 runs a month, or roughly $440 for one test on one column. A project with a few hundred tests, a handful of them on big tables, can quietly outspend the models it is protecting.
A pattern we see repeatedly in early-stage companies is a test suite written when the tables were small, kept as-is while event and ledger tables grew a hundredfold. Nobody revisits it, because a green build looks healthy. The same applies to CI: every pull request that runs dbt build without state selection retests the whole project against production-sized data.
📺 Watch: dbt State: lag_tolerance is now a budget decision
How Do You Find the dbt Tests Costing the Most in BigQuery?
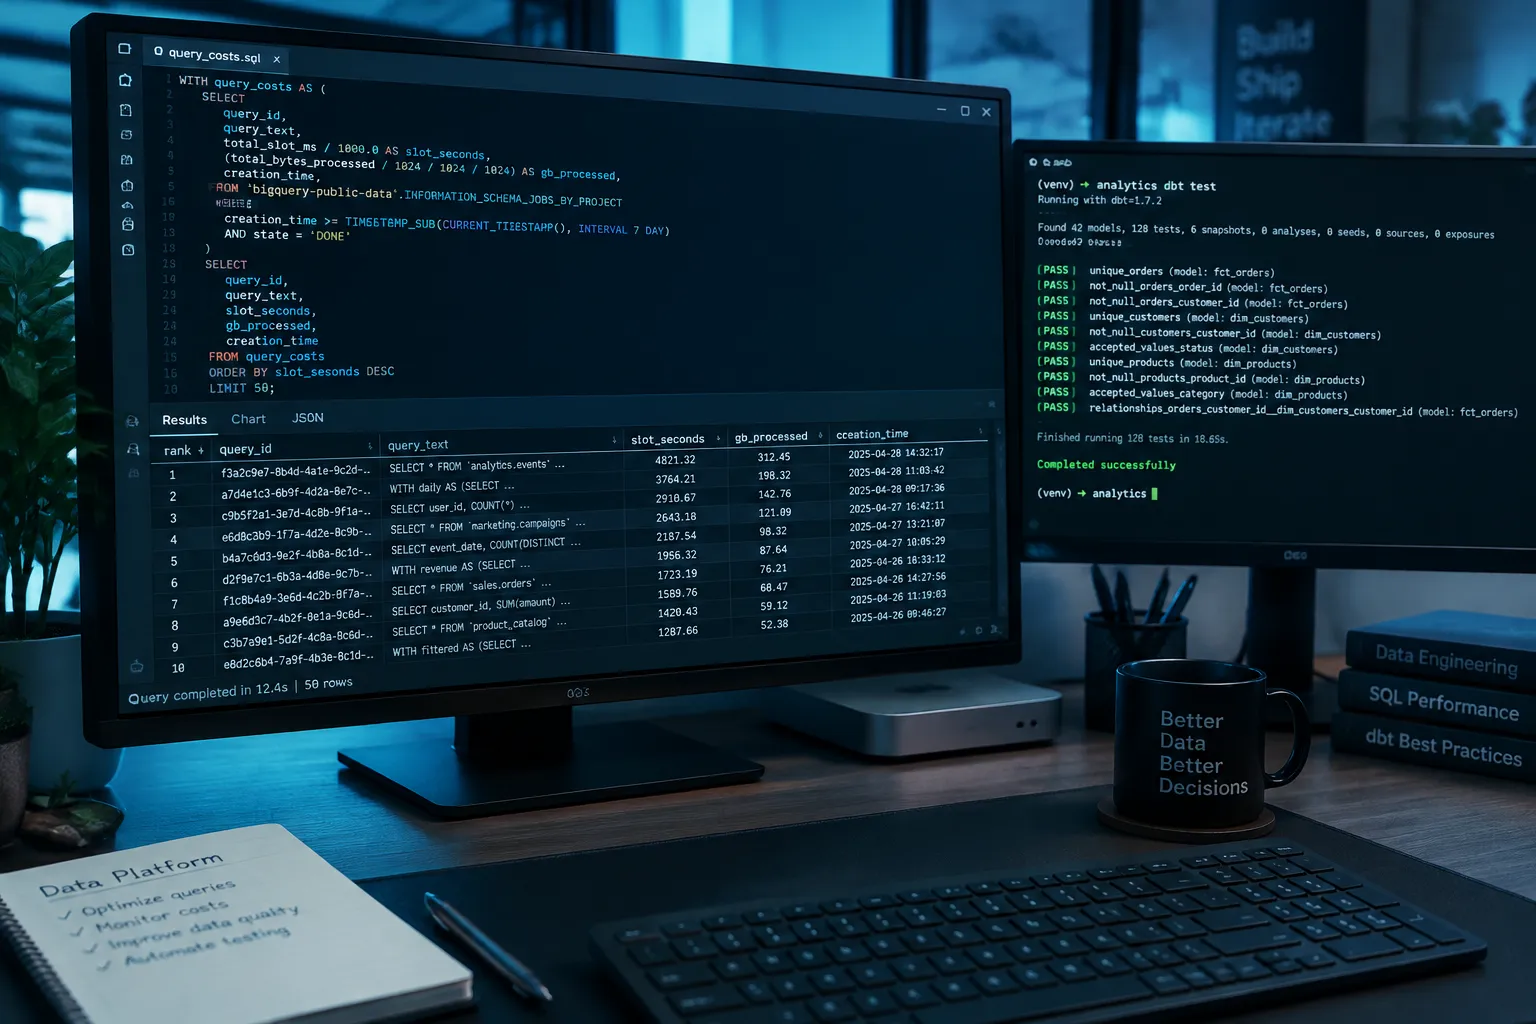
By default, dbt prepends a query comment to every statement it sends to BigQuery. That comment is JSON containing the node's unique_id, and test nodes start with test.. This means you can attribute cost to individual tests using only the jobs view. Run this in the region where your datasets live (swap region-us for yours):
SELECT
  REGEXP_EXTRACT(query, r'"node_id": "(test\.[^"]+)"') AS test_node,
  COUNT(*) AS runs_30d,
  ROUND(SUM(total_bytes_billed) / POW(1024, 4), 3) AS tib_billed,
  ROUND(SUM(total_bytes_billed) / POW(1024, 4) * 6.25, 2) AS est_usd_on_demand,
  ROUND(AVG(TIMESTAMP_DIFF(end_time, start_time, SECOND)), 1) AS avg_seconds
FROM `region-us`.INFORMATION_SCHEMA.JOBS_BY_PROJECT
WHERE creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND job_type = 'QUERY'
  AND state = 'DONE'
  AND error_result IS NULL
  AND REGEXP_CONTAINS(query, r'"node_id": "test\.')
GROUP BY test_node
ORDER BY est_usd_on_demand DESC
LIMIT 25;
The $6.25 multiplier is the US list rate, so adjust it if you are in another region. If you are on capacity pricing, rank by SUM(total_slot_ms) instead of bytes billed.
Before going test by test, check how big the problem is overall. This version splits dbt spend by node type:
SELECT
  CASE
    WHEN REGEXP_CONTAINS(query, r'"node_id": "test\.') THEN 'test'
    WHEN REGEXP_CONTAINS(query, r'"node_id": "model\.') THEN 'model'
    WHEN REGEXP_CONTAINS(query, r'"node_id": "snapshot\.') THEN 'snapshot'
    ELSE 'other'
  END AS dbt_node_type,
  COUNT(*) AS jobs,
  ROUND(SUM(total_bytes_billed) / POW(1024, 4), 2) AS tib_billed
FROM `region-us`.INFORMATION_SCHEMA.JOBS_BY_PROJECT
WHERE creation_time >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND job_type = 'QUERY'
  AND REGEXP_CONTAINS(query, r'"app": "dbt"')
GROUP BY dbt_node_type
ORDER BY tib_billed DESC;
If tests take a larger share than you expected, you have found the leak. In our audits, a handful of tests on the biggest fact or event tables usually account for most of the test spend. If the first query returns nothing, someone has probably customised or disabled your query-comment config. Check dbt_project.yml before assuming there is no cost.
Which dbt Tests Have No Row Filter at All?
The jobs view tells you what has already cost money. To see which tests are exposed before the bill arrives, read the manifest. After any dbt compile or dbt run, this command counts tests with no where config per tested model:
jq -r '.nodes[] | select(.resource_type=="test" and .config.where == null) | .attached_node' target/manifest.json | sort | uniq -c | sort -rn | head -20
Cross-reference the top of that list with the output of your cost query. Models that appear in both are your first targets: large, heavily tested, and unfiltered. Also scan for relationships tests. The where config on a standard relationships test filters the child side only, so the parent table is still read in full. If both sides are big, use dbt_utils.relationships_where, which accepts separate conditions for each side.
Running that query for one project is fine. Checking every model for the structural versions of these problems is not. fintel-scan is a free, open-source (MIT) CLI that runs this kind of static check and fourteen others against your dbt project locally, with no warehouse connection: uvx fintel-scan.
How Do You Cut dbt Tests BigQuery Cost Without Losing Coverage?
The main fix is the where config. The where config limits a test to a subset of rows, which is useful on large tables where you only need to test recent data. The filter must reference the partition column directly, with an expression BigQuery can evaluate as a constant, or partition pruning will not kick in. This is the pattern we use:
models:
  - name: fct_ledger_entries
    columns:
      - name: entry_id
        data_tests:
          - unique:
              config:
                where: "entry_date >= date_sub(current_date(), interval {{ var('test_window_days', 3) }} day)"
          - not_null:
              config:
                where: "entry_date >= date_sub(current_date(), interval {{ var('test_window_days', 3) }} day)"
The daily job tests the last three days. A weekly job then runs the same tests across all history by overriding the variable:
dbt test --vars '{test_window_days: 36500}'
That tiering matters, and it is a trade-off you should make deliberately. A windowed unique test will not catch a duplicate that lands against a row from six months ago. For immutable tables, such as ledger entries, events and payments, new rows rarely collide with old ones, so a short window catches nearly everything that matters. For mutable tables with late-arriving updates, widen the window to match your real late-data horizon.
Two changes people reach for first do not help much:
- The
limitconfig. It caps the number of failing rows a test returns, which helps when you store failures. It does not reduce the bytes scanned to find them. - Setting severity to warn. That changes what happens on failure, not what the test costs. A test that bills hundreds of dollars a month and only ever warns is paying for a signal nobody acts on. We cover that in our post on dbt tests that never fail a build.
In a payments engagement, the windowing change took an afternoon, because the tests were already written and only the config needed to change. The weekly full-history run kept the coverage that auditors and finance cared about, and the daily bill stopped scaling with table size. It also fits a wider principle we apply to every engagement: the cheapest query is the one that reads only the data that could have changed.
How Do You Stop dbt Test Costs Creeping Back?
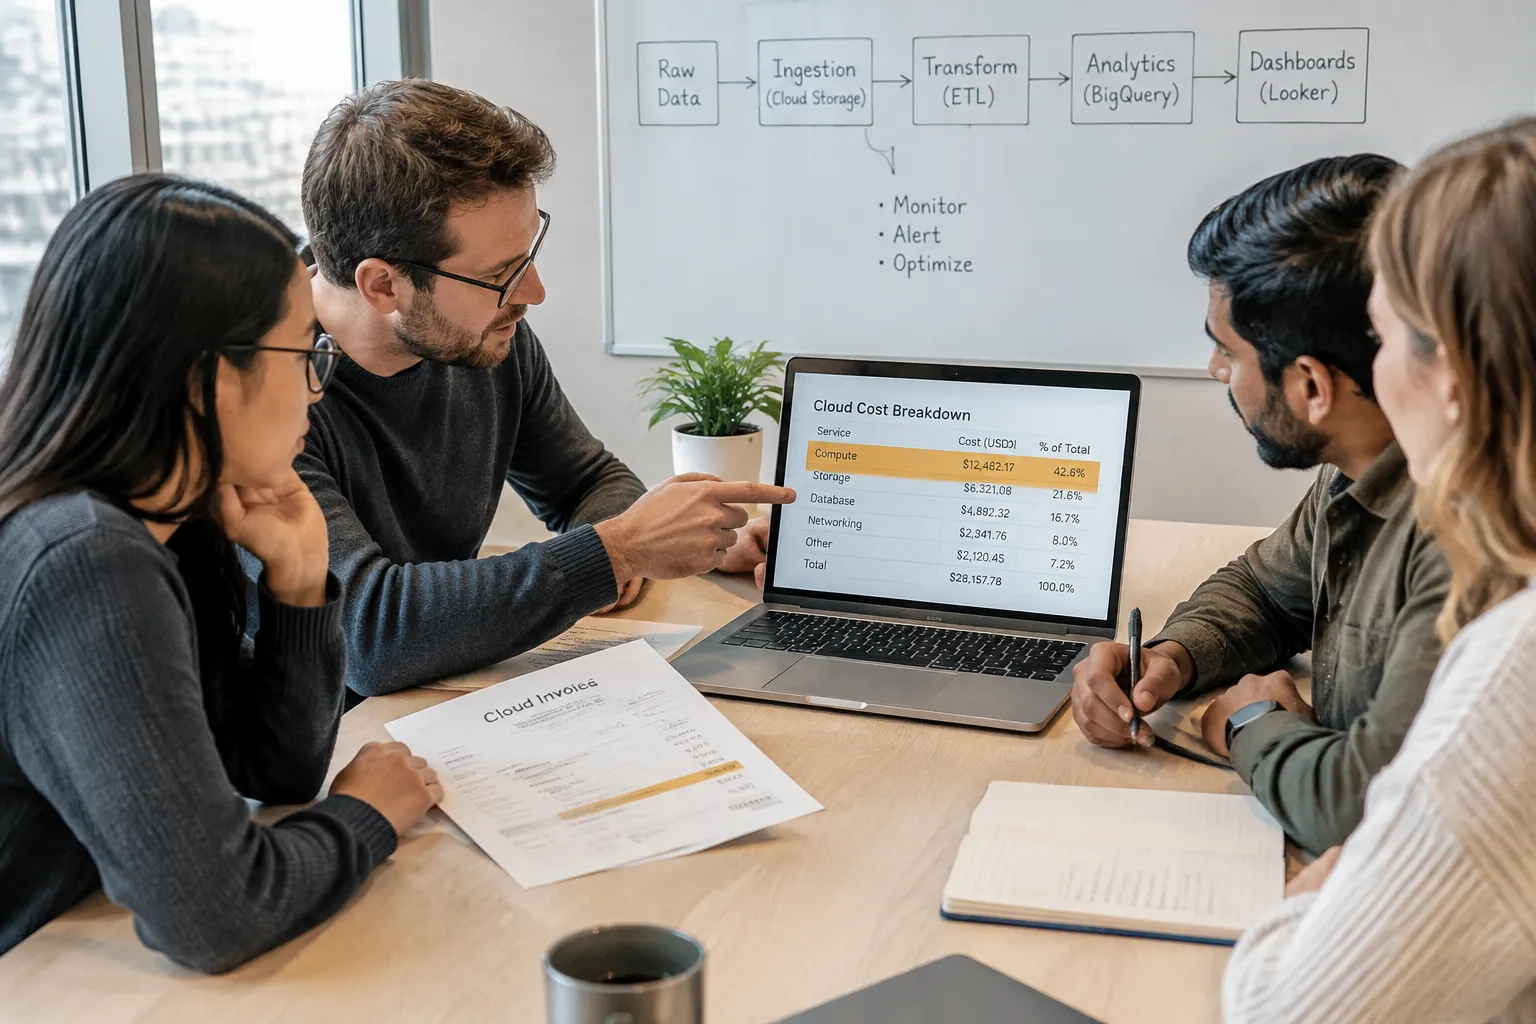
Fixing today's tests does nothing for the ones written next quarter. Three guardrails make it stick.
1. Slim CI. Pull request builds should test only what changed. Store production artifacts and run:
dbt build --select state:modified+ --defer --state ./prod-artifacts
This alone removes the biggest source of redundant test scans for most teams.
2. A hard byte cap on non-production targets. The dbt-bigquery profile accepts maximum_bytes_billed. Set it on your CI and dev targets, and an unfiltered test against a huge table fails with an error instead of quietly billing you. It also forces whoever wrote the test to add the where.
ci:
  type: bigquery
  method: service-account
  maximum_bytes_billed: 20000000000
That is a 20 GB ceiling per query. Pick a number a little above your largest legitimate windowed scan.
3. A weekly cost review. Schedule the first query above and send the top ten to the team channel. A recurring query on a calendar beats a one-off audit, because test cost grows with table size and nobody notices the drift. Pair it with dbt query labels if you also want attribution by team, as the comment-based approach here breaks down if someone overrides the default comment macro.
If you are on Snowflake or Postgres rather than BigQuery, the principle holds but the detection differs: Snowflake uses QUERY_HISTORY with the query tag, and Postgres uses pg_stat_statements.
Frequently Asked Questions
Q: Do dbt tests cost money in BigQuery?
A: Yes. Every dbt test compiles to a SQL query that BigQuery executes, so it consumes billable bytes on on-demand pricing or slots on capacity pricing. A single test is cheap, but tests run on every build, so a few unfiltered tests on large tables can become a meaningful share of your dbt spend.
Q: How do I find which dbt tests are the most expensive?
A: Query INFORMATION_SCHEMA.JOBS_BY_PROJECT, filter for queries whose dbt query comment contains a node_id starting with test., and group by that node ID. Sum total_bytes_billed over the last 30 days and rank descending. The first query in this post does exactly that.
Q: Does the dbt where config reduce BigQuery scan cost?
A: Yes, if the filter is on a partition column and BigQuery can prune partitions with it. A where clause on a non-partitioned column still reads the full column. Always filter on the partition column with a constant expression such as date_sub(current_date(), interval 3 day).
Q: Does the dbt limit config on tests reduce cost?
A: Not meaningfully. The limit config restricts the number of failing records a test returns, which is useful for stored failures. The test query still scans the data needed to find them, so bytes billed barely change.
Q: How can I stop dbt CI from running up my BigQuery bill?
A: Use state-based selection with state:modified+ and --defer so pull requests only test changed models. Add maximum_bytes_billed to the CI profile so any unfiltered scan fails instead of billing. Together they remove most redundant test spend in CI.
Conclusion
Controlling dbt tests BigQuery cost is not about testing less. It is about testing recent data daily, running full history on a schedule, and making expensive tests visible before they reach the invoice. The challenge for most growth-stage teams is that nobody owns the question of what the test suite costs, so it grows with the data until the bill forces a conversation. At Fintel Analytics, we have helped payments, fintech and e-commerce teams audit their BigQuery and dbt projects, cut runaway query costs and put governance in place without weakening data quality. If your warehouse bill is climbing faster than your revenue, that is a diagnosable problem, and the fix usually pays for itself within a billing cycle or two.